Agent-Reflex README

The project's README from github.com/RUC-NLPIR/Agent-Reflex. As one markdown file: README.md.

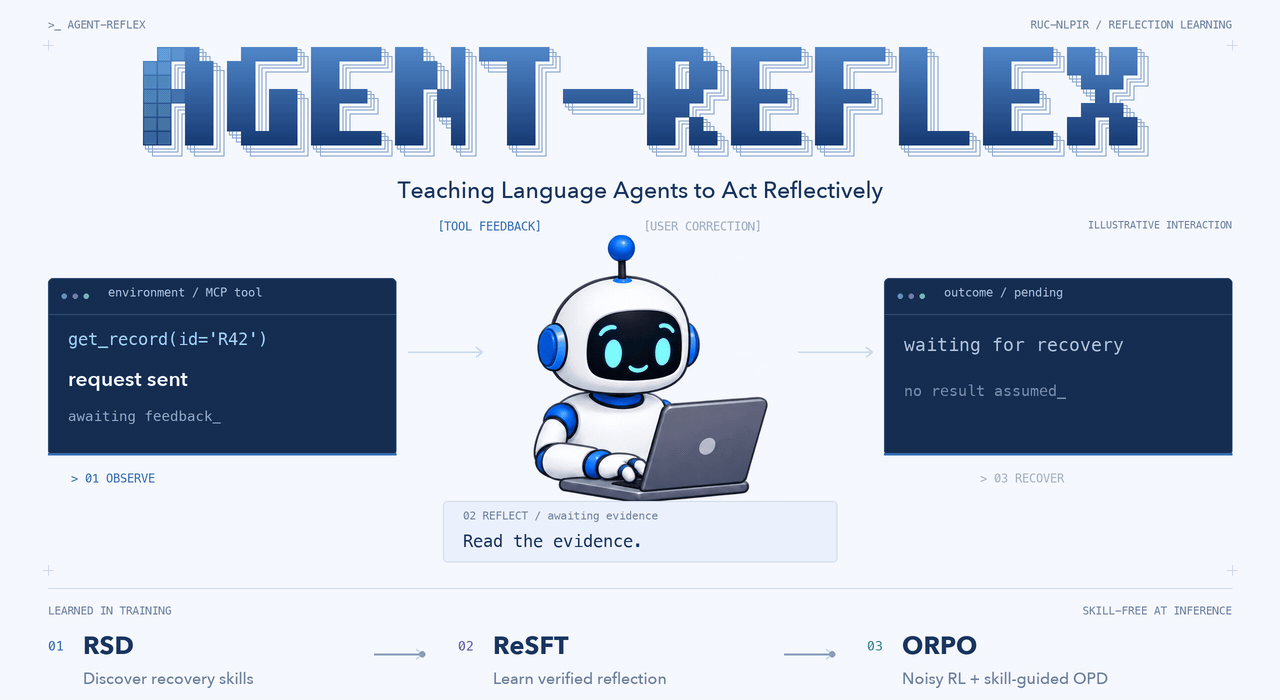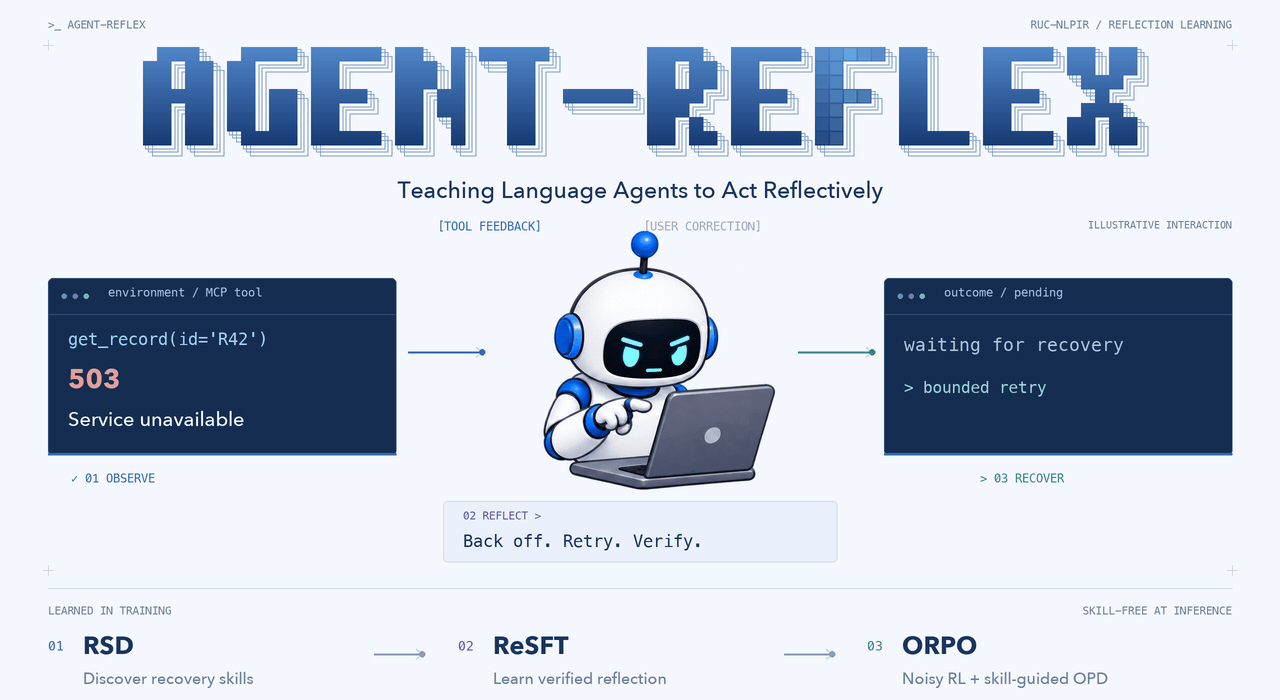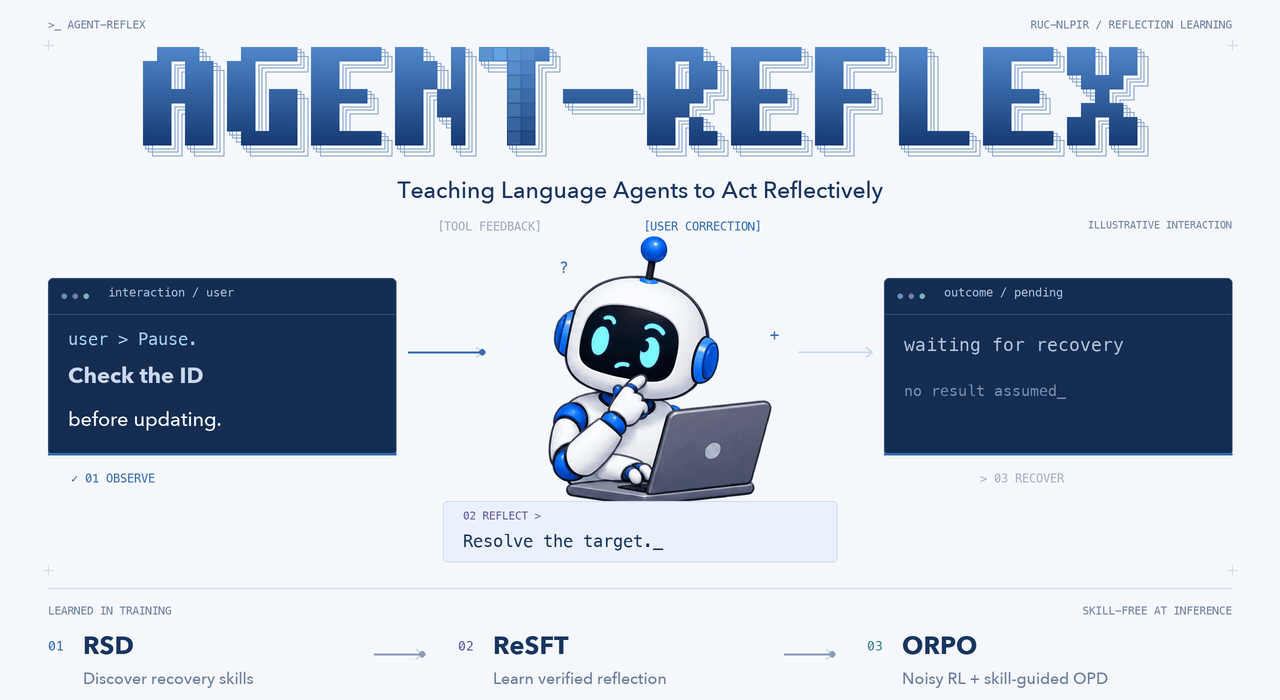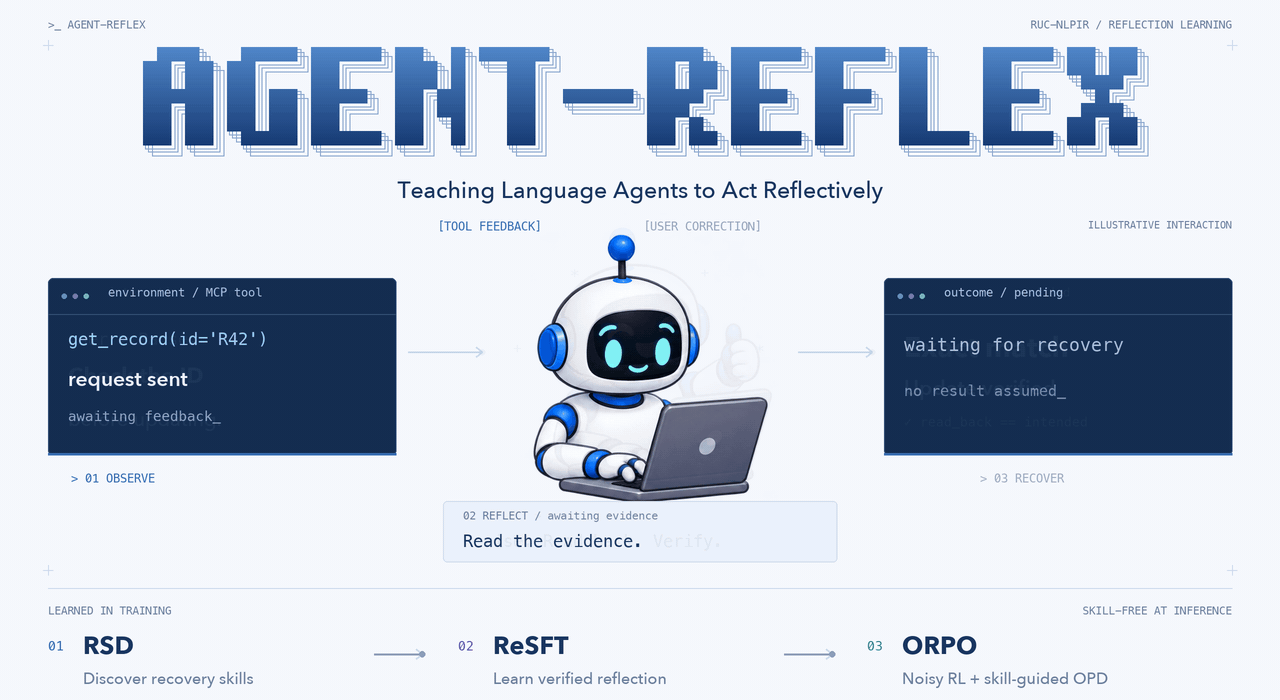
Agent-Reflex learns to observe, reflect, and recover from tool failures and user corrections through RSD, ReSFT, and ORPO training.

 Agent-Reflex: Teaching Language Agents to Act Reflectively

If you like our project, please give us a star ⭐ on GitHub for the latest update.

Paper HF Paper Model SFT Data RL Data Collection Skills License: MIT

A training framework that elicits proactive reflection in tool-using LLM agents: noticing noisy tool feedback and user corrections, and recovering from them.

Demo · Overview · Framework · Results · Installation · Data · Quick Start · Citation

📣 News

🎬 Demo

Agent-Reflex in One Minute

https://github.com/user-attachments/assets/281af1d3-843e-4496-b232-58fee951cefd

🎥 Download the 1080p video (60 seconds) · 💻 original task interactive replay (open locally in a browser)

💡 Overview

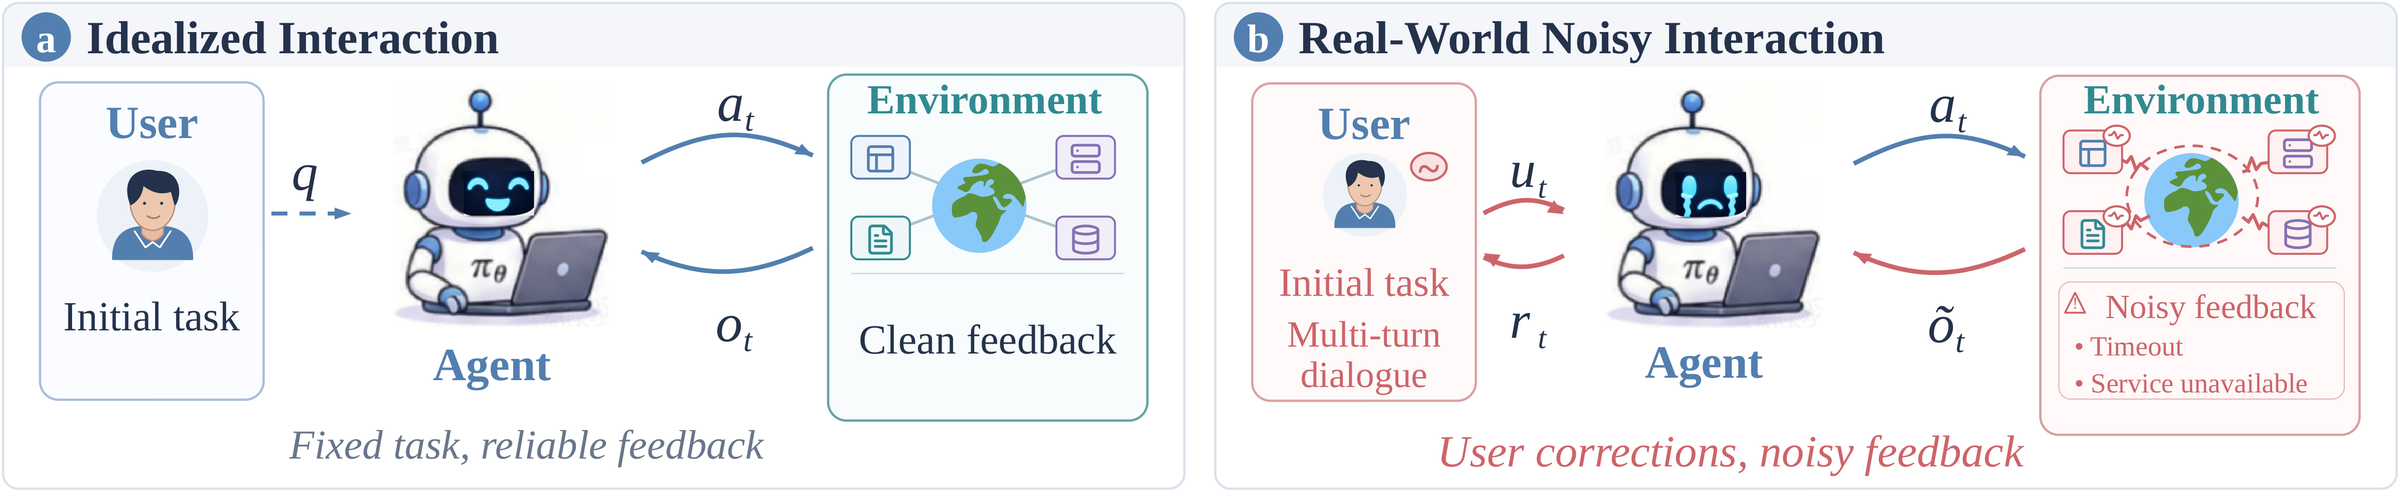
Agents are trained in idealized environments but deployed into noisy ones. Two gaps follow:

Figure 1 (a, b) · The two gaps. Idealized interaction (a) vs. real-world interaction with user corrections and noisy feedback (b).

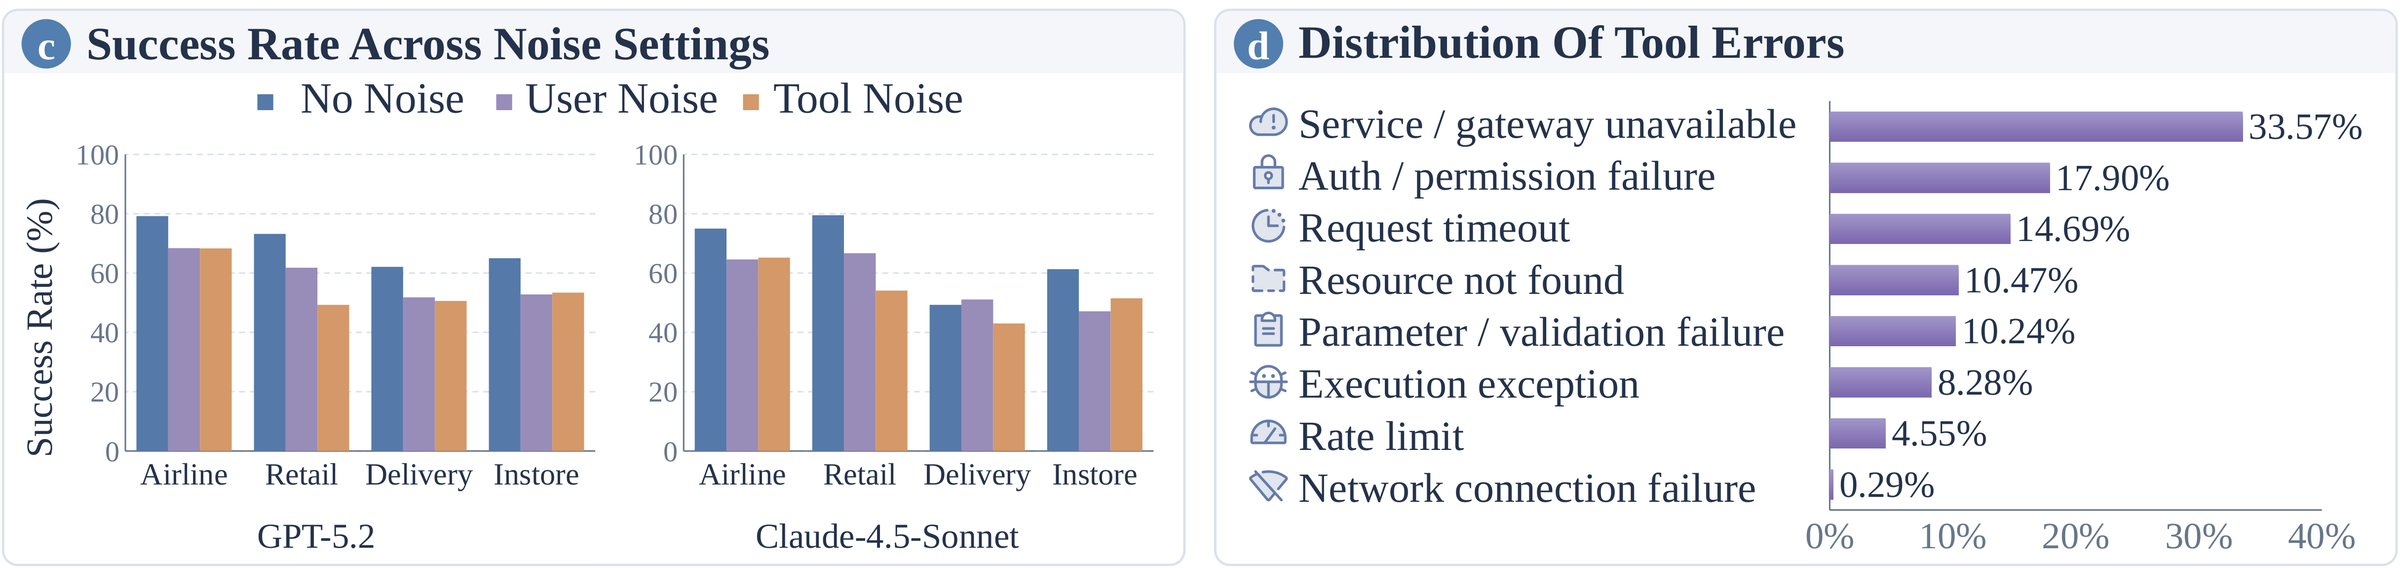
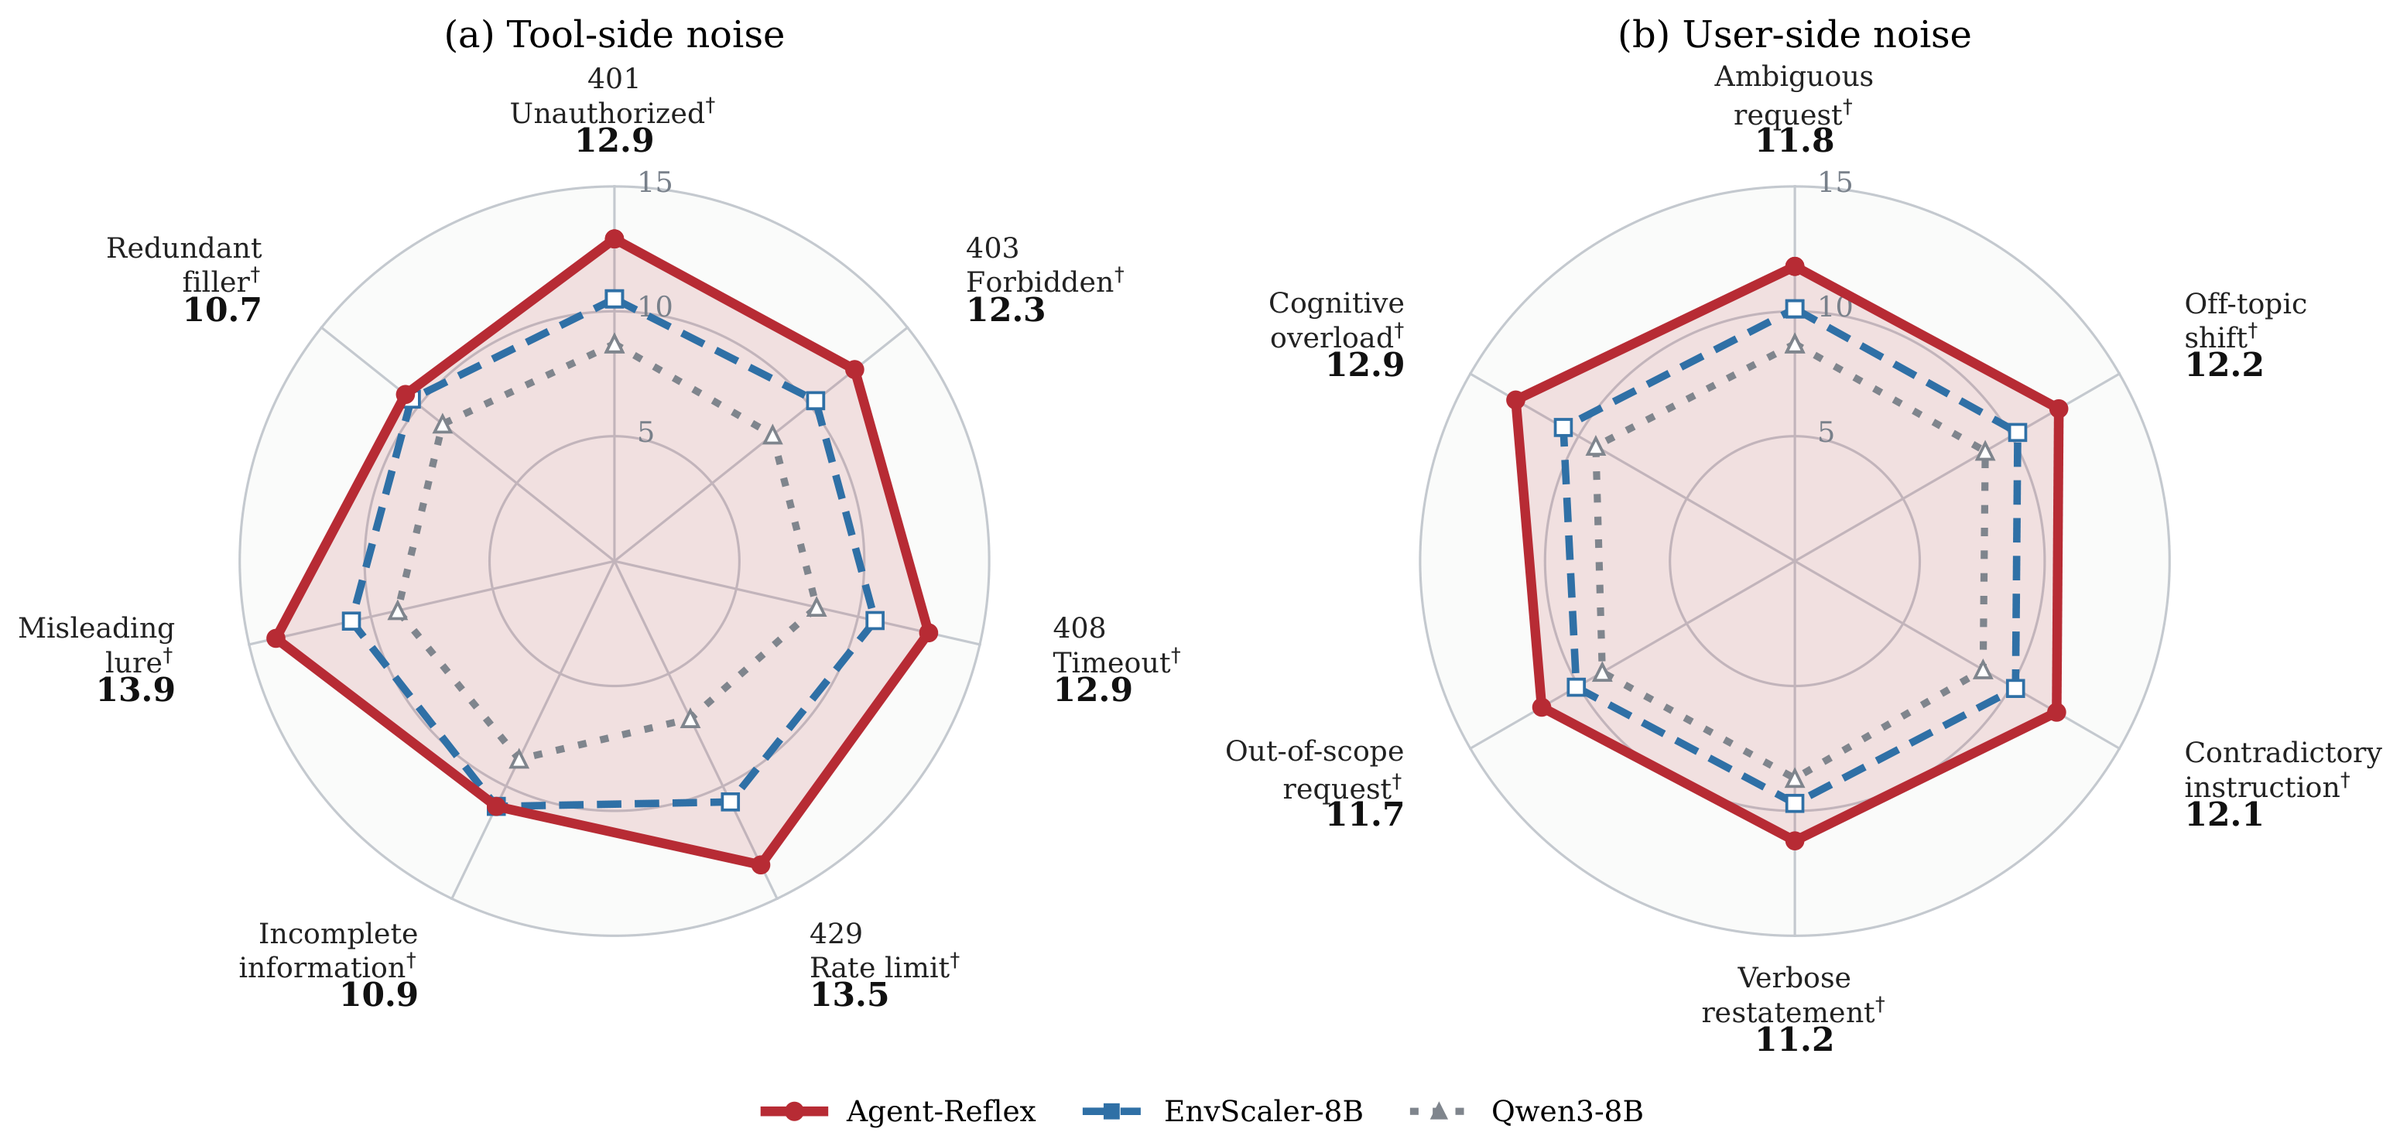
Figure 1 (c, d) · The cost of noise. Strong agents lose success rate under user or tool noise (c); tool errors fall into eight recurring families (d).

Agent-Reflex treats reflection as a learnable meta-skill: it mines skills from failures in noisy environments, distills them into supervised data and reinforces them with noisy agentic RL. On Qwen3-8B it improves six agent benchmarks and stays robust under noise.

✨ Agent-Reflex Framework

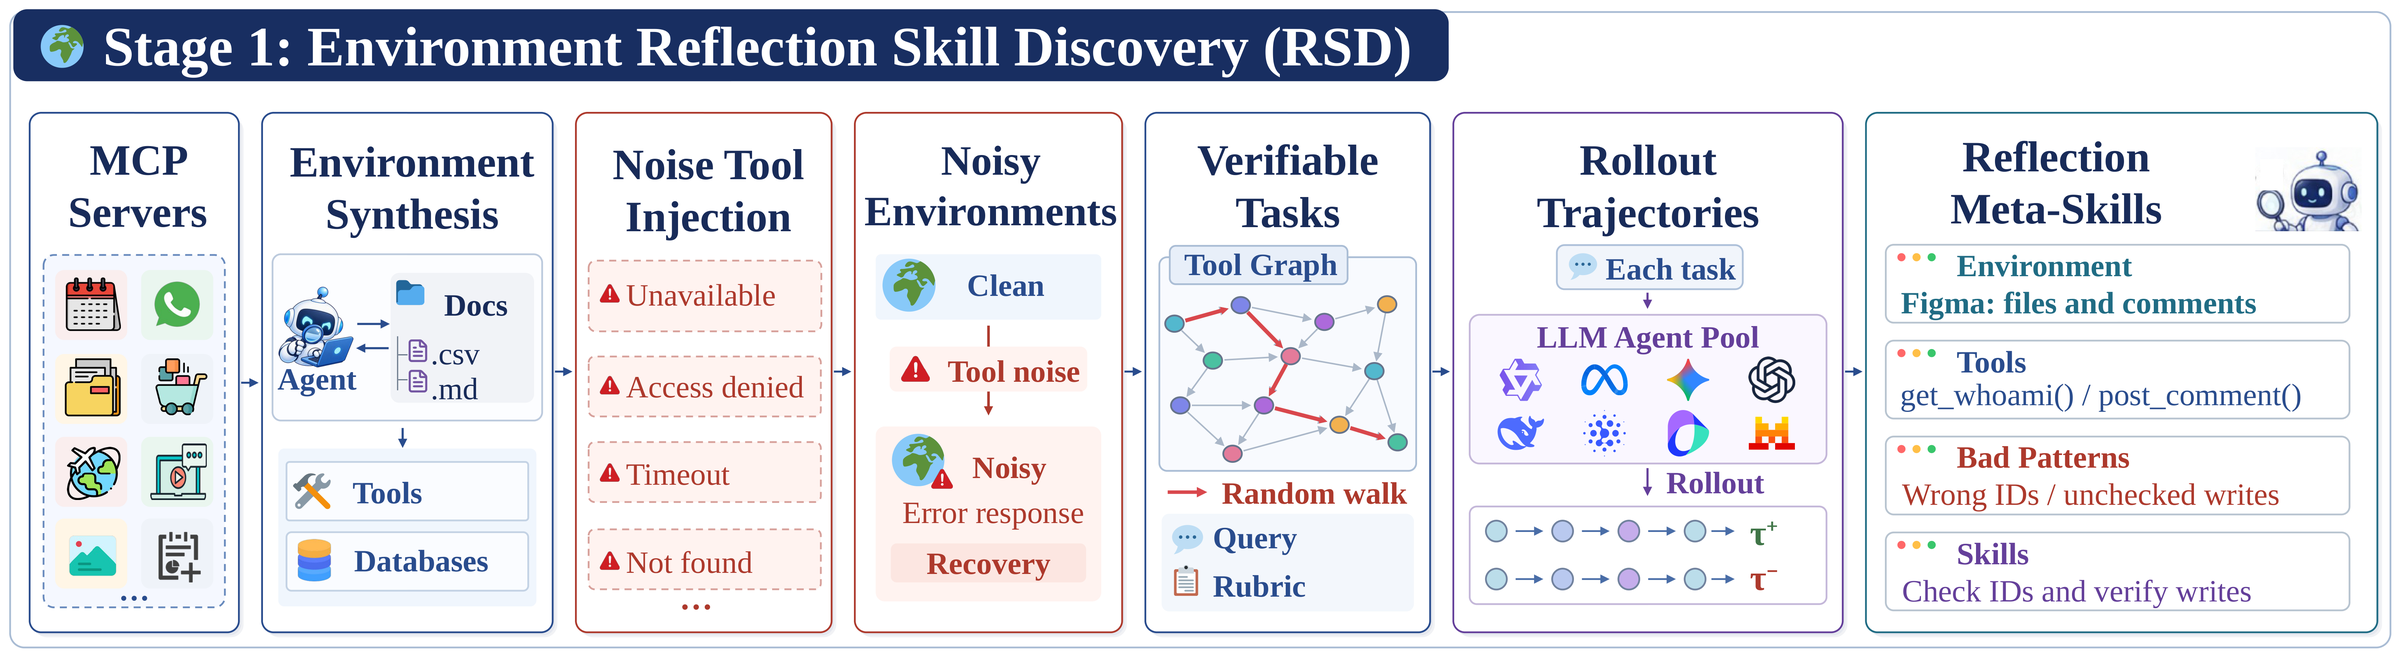
Stage 1 · Environment Reflection Skill Discovery (RSD)

Build failure-aware executable environments by perturbing tool returns with real-world failure families, and mine verifier-matched success / failure pairs into an offline library of 1,170 reflection meta-skills over 557 environments. Environment synthesis and the environment infrastructure follow Agent-World.

Stage 2 · Reflective Supervised Fine-Tuning (ReSFT)

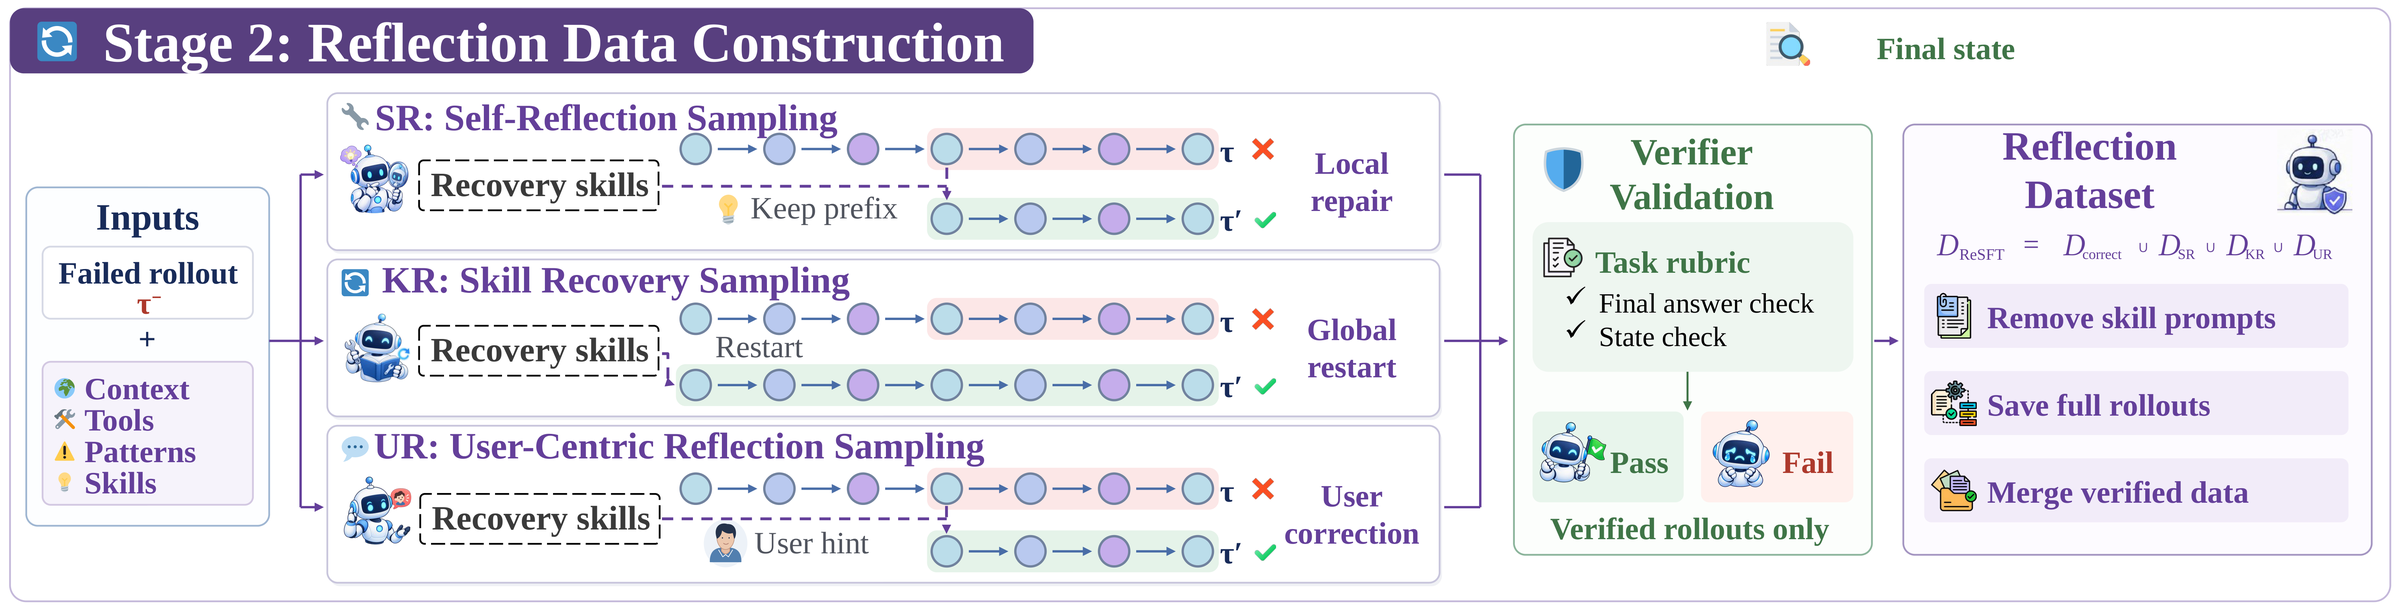
Convert each skill into verifier-validated self-reflection (SR), skill recovery (KR) and user-correction (UR) data, with skill prompts stripped, and internalize them by supervised fine-tuning.

Stage 3 · On-Policy Reflective Policy Optimization (ORPO)

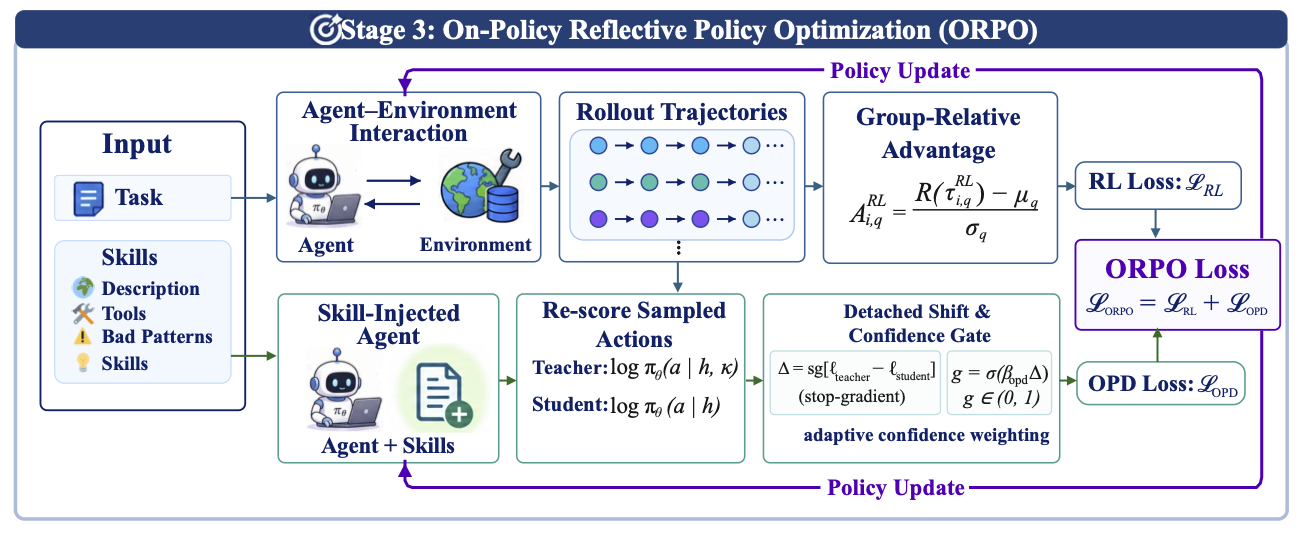
Combine Noisy Agent RL with same-token, skill-guided on-policy distillation (OPD) to provide dense reflection supervision. Skills are used only in training; the deployed agent is skill-free.

📊 Benchmarks & Results

We evaluate on six agent benchmarks under each benchmark's official metric:

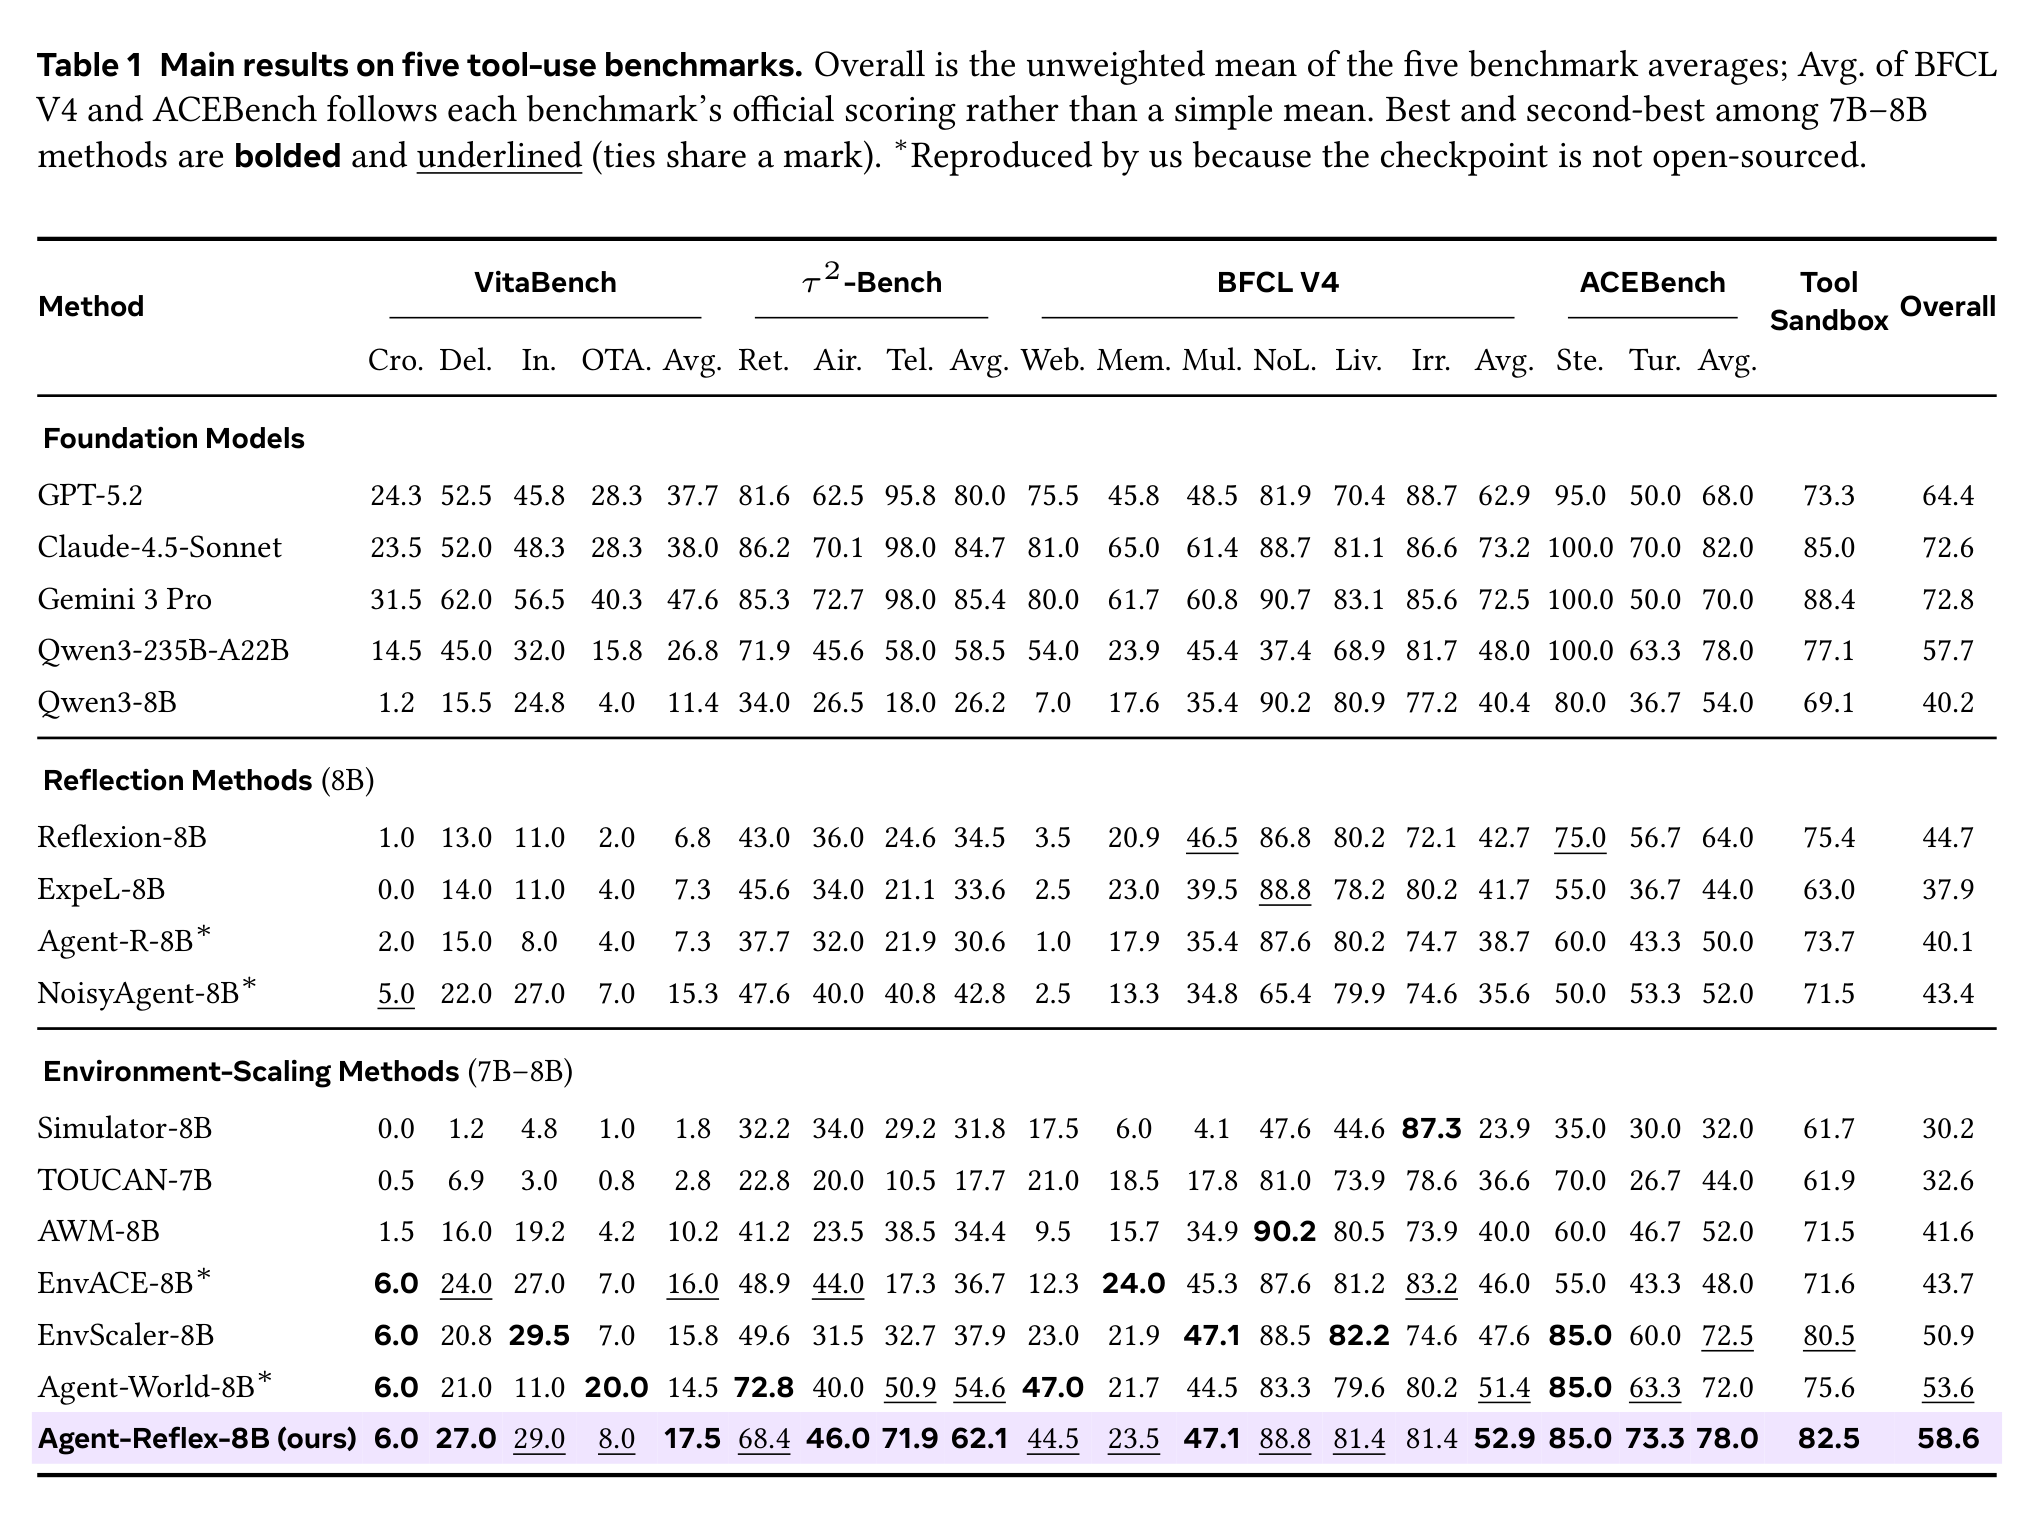
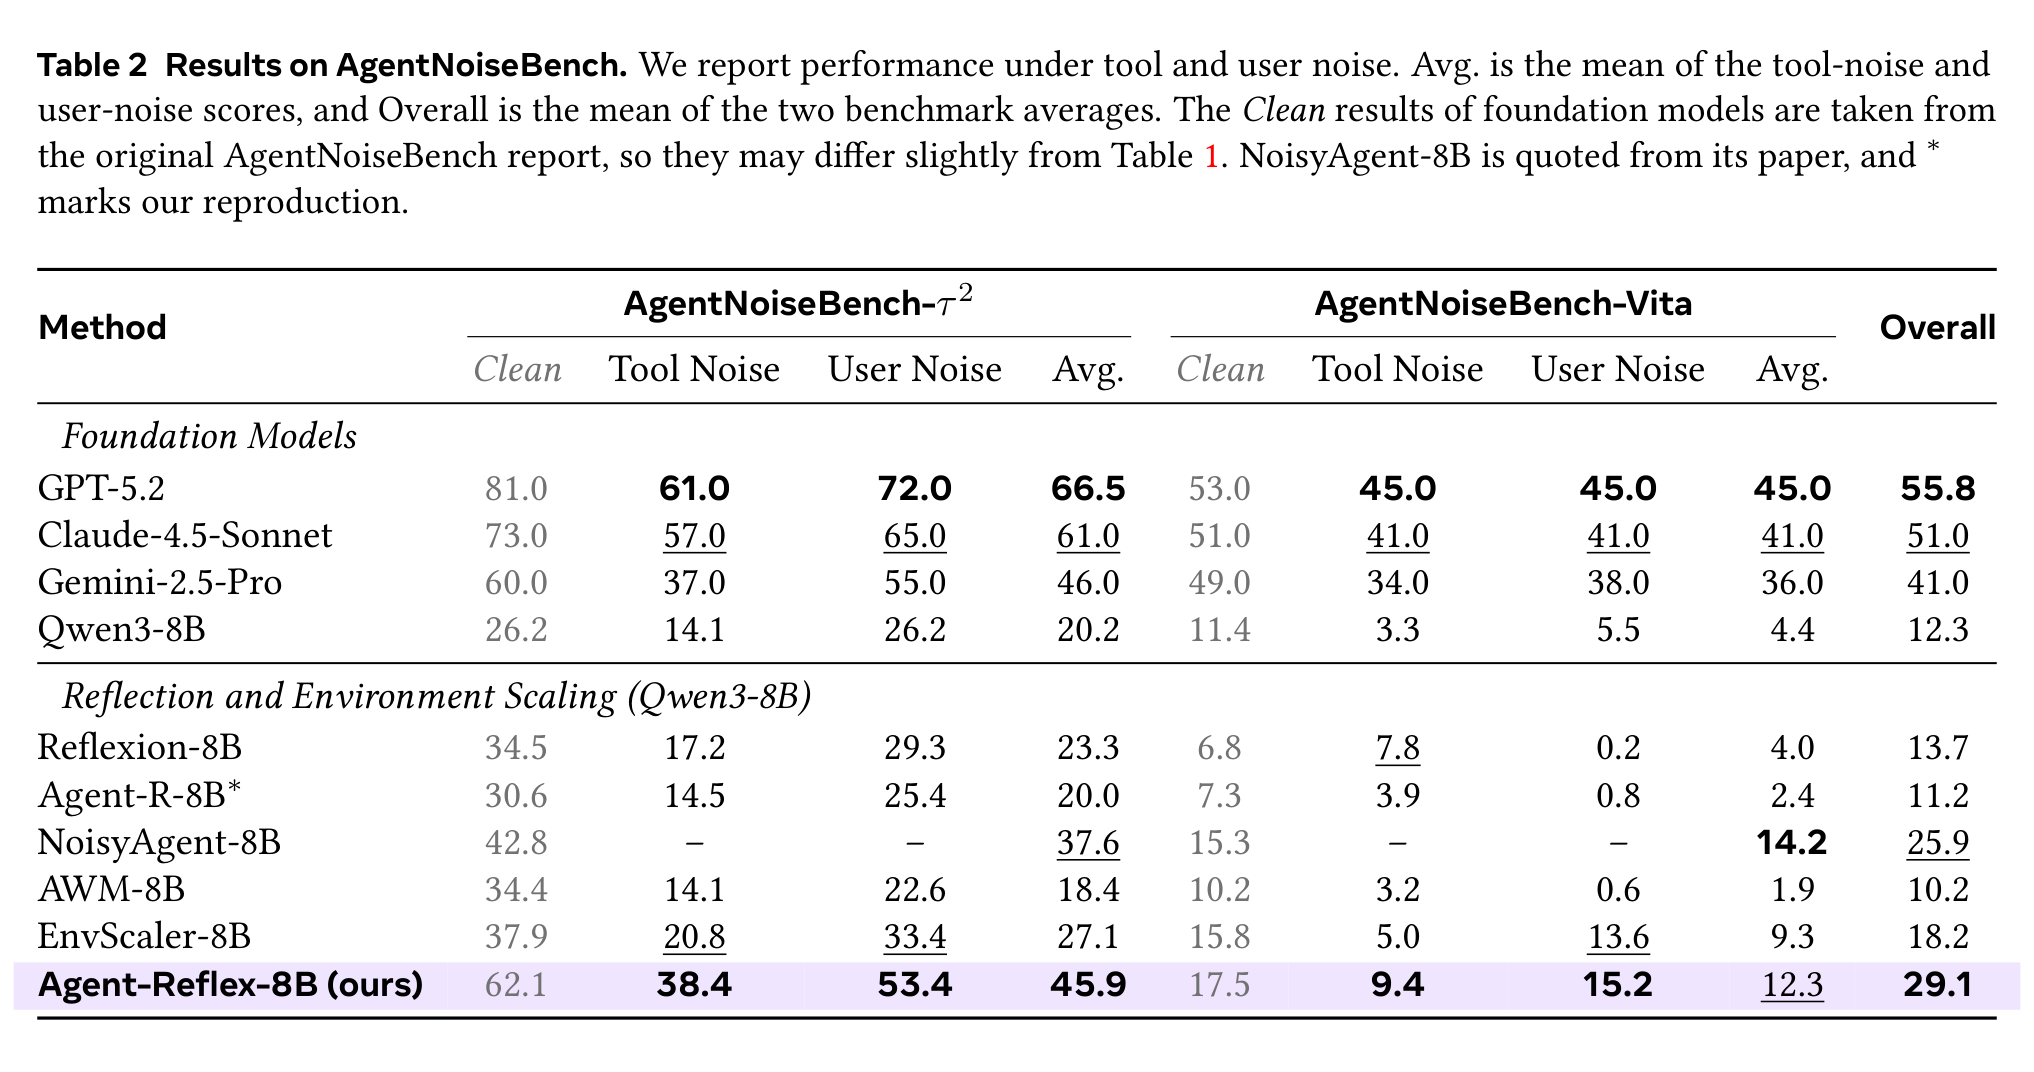
On Qwen3-8B, Agent-Reflex reaches 58.6 Overall on the five long-horizon tool-use benchmarks (+18.4 over the backbone, +7.7 over EnvScaler-8B) and 29.1 on AgentNoiseBench, the best among all 8B methods:

Method VitaBench τ²-Bench BFCL V4 ACEBench ToolSandbox Overall AgentNoiseBench
Qwen3-8B 11.4 26.2 40.4 54.0 69.1 40.2 12.3
Reflexion 6.8 34.5 42.7 64.0 75.4 44.7 13.7
EnvScaler-8B 15.8 37.9 47.6 72.5 80.5 50.9 18.2
Agent-World-8B 14.5 54.6 51.4 72.0 75.6 53.6 –
Agent-Reflex 17.5 62.1 52.9 78.0 82.5 58.6 29.1
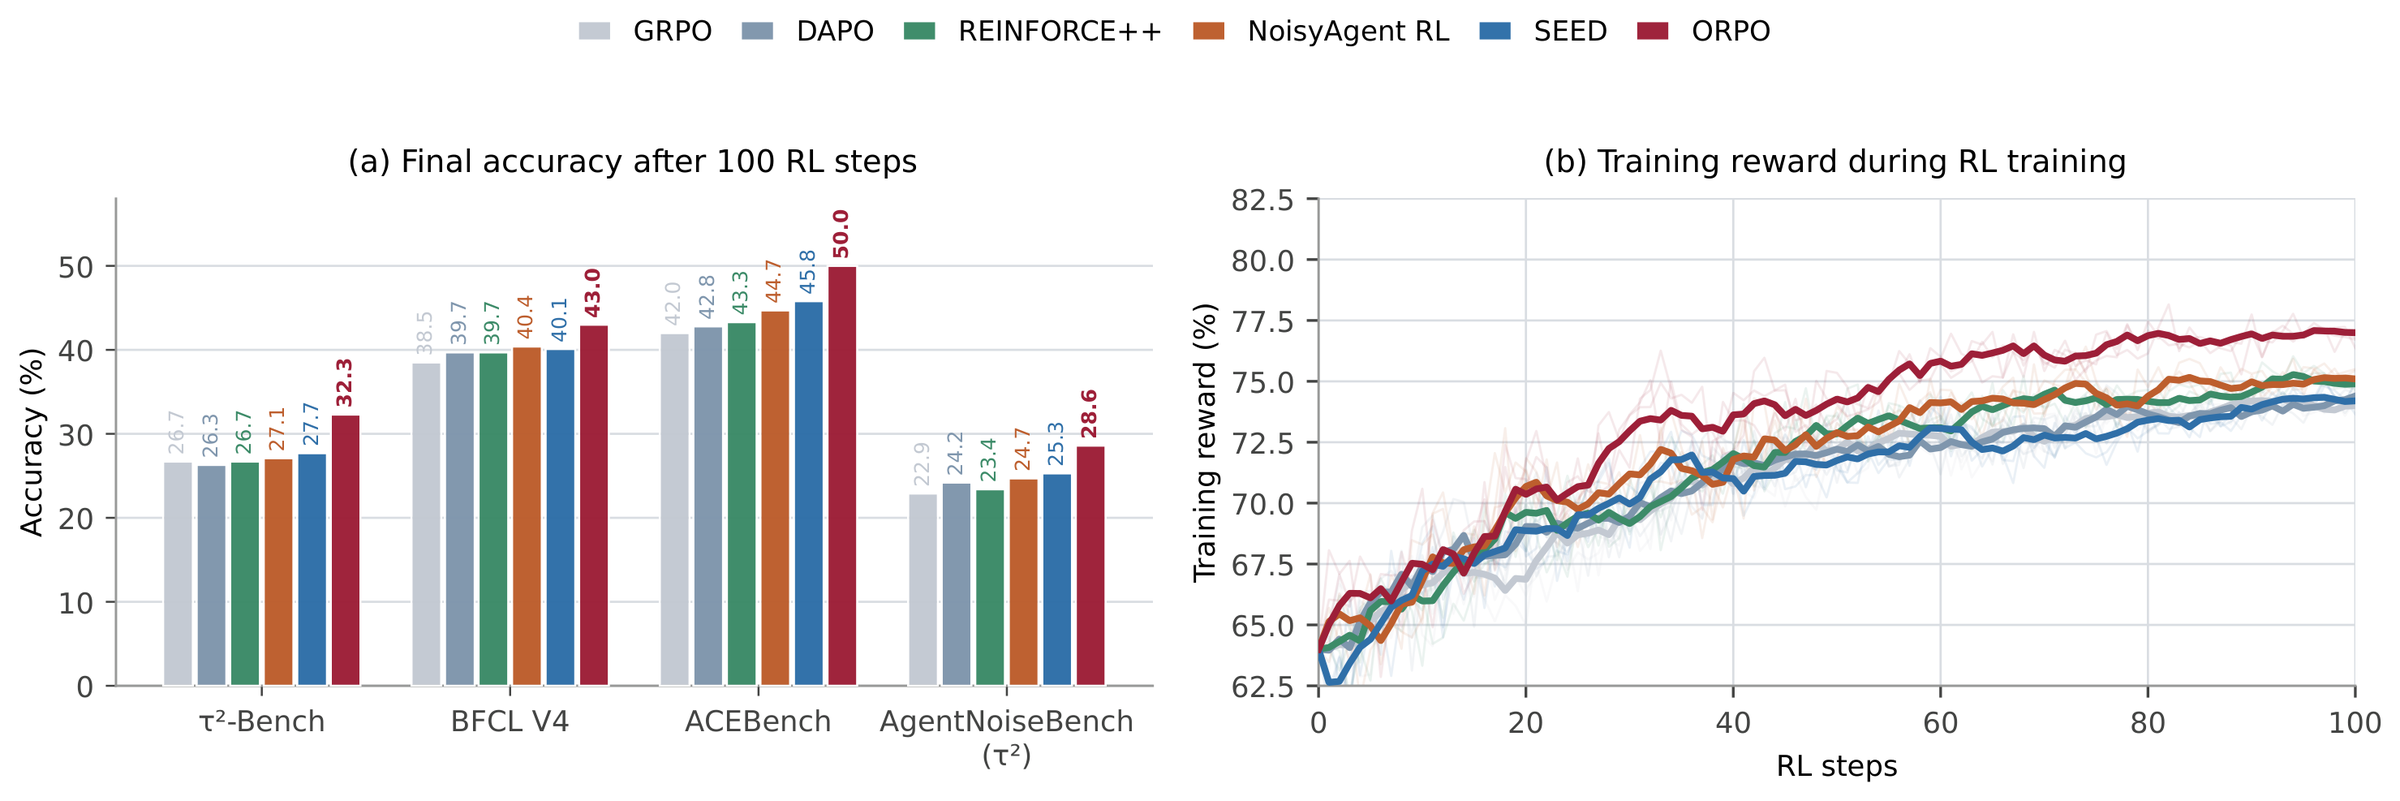
Full tables, noise robustness and the RL algorithm comparison

🔧 Installation

Environment Setup

Each part has its own environment, built by one script with uv (pip install uv) from a pinned requirements.txt:

Part Python Core packages Setup
ReSFT 3.12 torch 2.6.0 (cu124), transformers 5.8, DeepSpeed 0.19, flash-attn 2.7.4, Liger 0.8 bash LLaMA-Factory/setup_env.sh
ORPO 3.10 torch 2.7.1 (cu128), verl 0.5, SGLang 0.4.10.post2, transformers 4.54.1, Ray 2.57, flash-attn 2.8.3 bash ORPO/setup_env.sh
Model serving 3.12 vLLM 0.27.1 bash evaluation/shared/setup_vllm.sh
Benchmarks 3.10 / 3.12 one venv per benchmark; upstream code cloned at pinned commits bash evaluation/<Bench>/setup.sh

API Configuration

Training needs no API keys. Evaluation reads them from evaluation/.env (git-ignored):

cp evaluation/.env.example evaluation/.env
# then edit evaluation/.env:
BOYUE_API_KEY=sk-xxxxxxxx
BOYUE_API_BASE_URL=http://35.220.164.252:3888/v1   # outside CN/HK: https://api.boyuerichdata.opensphereai.com/v1
SERPER_API_KEY=xxxxxxxx

[!NOTE] By default our evaluation calls these models through Boyue, a third-party OpenAI-compatible API service. Any OpenAI-compatible endpoint works: to use the official OpenAI / Anthropic APIs or your own gateway, point the base URL and key in evaluation/.env (and the client setup in each benchmark's run.sh / config) to your provider. A coding agent can make this change in a few minutes.

🗂️ Repository

Agent-Reflex/
├── RSD/             🪞 Stage 1 · the reflection meta-skill library (1,170 skills)
├── LLaMA-Factory/   📘 Stage 2 · ReSFT recipe and launch scripts
├── ORPO/            🎯 Stage 3 · verl-based ORPO: noisy rollouts + skill-guided OPD
├── evaluation/      📊 τ²-Bench, BFCL V4, ACEBench, VitaBench, AgentNoiseBench, ToolSandbox
└── assets/          🖼️ figures used in this README; demo/ holds the demo video and replay page
Folder What you get Start here
RSD/ 557 MCP-anchored environments with tools, bad patterns and 1,170 reflection meta-skills, in English and Chinese README
LLaMA-Factory/ ReSFT on Qwen3-8B: full fine-tuning, ZeRO-3, 3 epochs, 5,127 steps README · reproduce
ORPO/ ORPO from the ReSFT checkpoint on 1 × 8 GPUs README · reproduce
evaluation/ one folder per benchmark, official settings, vLLM serving README · reproduce

📦 Data

Resource Size Download Put it at
Agent-Reflex-8B (Qwen3-8B, ReSFT + ORPO) 16 GB 🤗 HuggingFace any path, pass as MODEL_PATH
ReSFT data, 54,663 trajectories 2.6 GB 🤗 HuggingFace LLaMA-Factory/data/agent_reflex_resft/train/
ORPO tasks, 2,550 with skills 152 MB 🤗 HuggingFace ORPO/data/
RSD skill library, 1,170 skills (English / Chinese) 22 MB this repo RSD/environment_skills.jsonl · RSD/environment_skills_zh.jsonl
Evaluation data 115 MB this repo evaluation/<Bench>/data/
pip install -U huggingface_hub
hf download dongguanting/Agent-Reflex-SFT-54K --repo-type dataset --include "train/*" \
  --local-dir LLaMA-Factory/data/agent_reflex_resft
hf download dongguanting/Agent-Reflex-RL-2K train_envscaler_2550_with_skills.jsonl \
  --repo-type dataset --local-dir ORPO/data
hf download dongguanting/Agent-Reflex-8B --local-dir /path/to/Agent-Reflex-8B

🚀 Quick Start

1. ReSFT

cd LLaMA-Factory
NNODES=2 NODE_RANK=<0|1> MASTER_ADDR=<node0> MODEL_PATH=/path/to/Qwen3-8B \
  bash scripts/run_resft_qwen3_8b.sh

2. ORPO

Start from the ReSFT model checkpoint:

cd ORPO
python scripts/prepare_init_checkpoint.py /path/to/resft_checkpoint --apply
MODEL_PATH=/path/to/resft_checkpoint bash scripts/run_orpo_qwen3_8b.sh

3. Evaluation

Full task sets under the official settings (fill in evaluation/.env first):

cd evaluation
MODEL_PATH=/path/to/Agent-Reflex-8B RUN_NAME=agent-reflex bash run_all.sh

run_all.sh serves the model with vLLM and runs all six benchmarks; set BENCHES="Tau2 BFCL-v4" to run a subset. Per-benchmark details are in evaluation/README.md.

🙏 Acknowledgements

Agent-Reflex builds on verl, LLaMA-Factory, EnvScaler, Agent-World, tau2-bench, BFCL, VitaBench, ToolSandbox and AgentNoiseBench. Thanks to their authors.

📄 License

Agent-Reflex code and the RSD skill library are released under the MIT License. Vendored components keep their own licenses:

Component License
ORPO/ (verl), LLaMA-Factory/ Apache-2.0
evaluation/BFCL-v4/ (BFCL data, from gorilla) Apache-2.0
evaluation/Tau2/data/, evaluation/AgentNoiseBench/repo/tau2-bench-main/ (tau2-bench) MIT
evaluation/VitaBench/data/, evaluation/AgentNoiseBench/repo/vitabench/ (VitaBench) MIT
evaluation/ACEBench/interact_with_env/ (EnvScaler, tau-bench) MIT

ToolSandbox is cloned from apple/ToolSandbox at setup time and is not redistributed here. The AgentNoiseBench noise injection and data follow AgentNoiseBench; please refer to its authors for terms of use.

📚 Citation

@misc{dong2026agentreflex,
  title={Agent-Reflex: Teaching Language Agents to Act Reflectively},
  author={Guanting Dong and Xinyu Yang and Jiajie Jin and Yuyang Hu and Xiaoshuai Song and Yifei Chen and Xiaoxi Li and Jiejun Tan and Yutao Zhu and Tat-Seng Chua and Ji-Rong Wen and Zhicheng Dou},
  year={2026},
  eprint={2610.17953},
  archivePrefix={arXiv},
  primaryClass={cs.CL},
  url={https://arxiv.org/abs/2610.17953},
}

Agent-Reflex (RUC-NLPIR/Agent-Reflex)

sglang
Searching Database…

What is this?Agent-Reflex is a training framework that teaches tool-using LLM agents to reflect: noticing noisy tool feedback and user corrections, and recovering from them instead of failing silently.
Is this a ready-to-use agent or a training pipeline I run myself?It is a full three-stage training pipeline (skill mining, supervised fine-tuning, then RL), not a plug-and-play agent; the final deployed model is skill-free, the skills are only used during training.
How do I get it running?Each stage has its own pinned environment set up via uv: run bash LLaMA-Factory/setupenv.sh for ReSFT, bash ORPO/setupenv.sh for ORPO, bash evaluation/shared/setupvllm.sh for serving, then follow the Quick Start scripts for ReSFT, ORPO and evaluation in order.
What hardware and API keys do I need?You need NVIDIA 80GB GPUs with CUDA 12.8 driver support (ReSFT uses 2x8 GPUs, ORPO/evaluation use 1x8); training itself needs no API keys, but evaluation needs a Boyue API key for the judge/user-simulator and a Serper API key for BFCL's web-search tasks.
What's the catch with running this?Reproducing the results requires a serious GPU cluster (16 GPUs for ReSFT) and strict, version-pinned environments per stage; ToolSandbox is not redistributed and must be cloned separately from Apple's repo during setup.
What is the RSD skill library?It is 1,170 reflection meta-skills mined from verifier-matched success/failure trajectory pairs across 557 MCP-anchored environments where tool returns are perturbed with real-world failure patterns, used to generate the ReSFT and ORPO training data.
Does the project release a trained model?Yes, an Agent-Reflex-8B checkpoint (Qwen3-8B trained with ReSFT + ORPO, 16GB) is published on Hugging Face alongside the SFT and RL datasets.
How much does reflection training actually help?On Qwen3-8B it raises the average score across five long-horizon tool-use benchmarks from 40.2 to 58.6, and scores 29.1 on the noisy AgentNoiseBench, the best result among 8B-scale methods.
Why does an agent need to be trained to reflect?Real tools time out or return malformed results and real users interrupt mid-task, but standard agent training environments give clean feedback with no corrections, so agents never learn to detect and recover from these failures.
What are similar projects?verl, open-r1, NeoHorse, minimind, halo, jeeves, Meshy, Model-Optimizer
Creator
RUC-NLPIR
Size
50.7 MB
Stars
234
Updated
CommitOct 14
Age
13d
Commits · 90 Days