


308 ·GitHub
Что это?
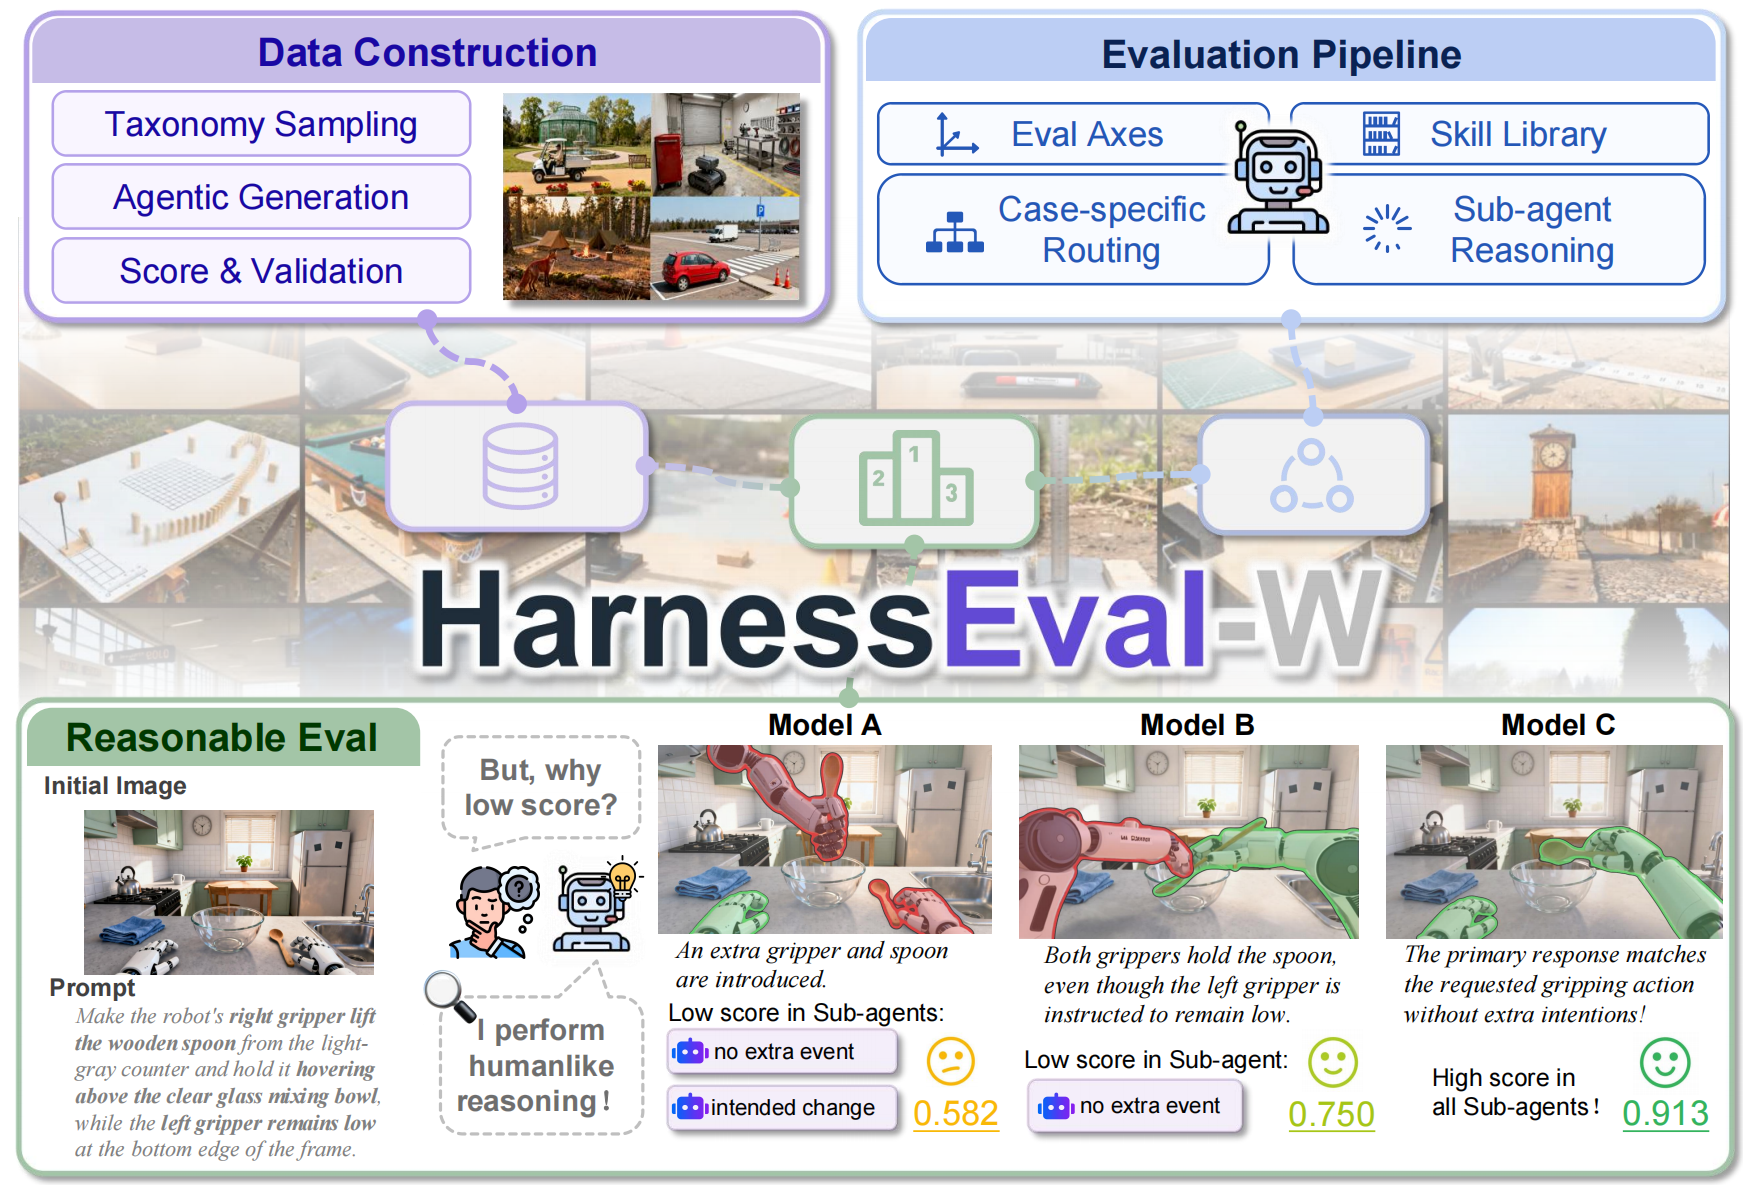
 HarnessEval-W — это агентный конвейер оценки для бенчмаркинга моделей мира и генерации видео: вместо грубой скалярной оценки он раскладывает каждый оценочный кейс на подвопросы, на которые отвечают специализированные субагенты, а затем сводит доказательства в прозрачный и проверяемый вердикт.
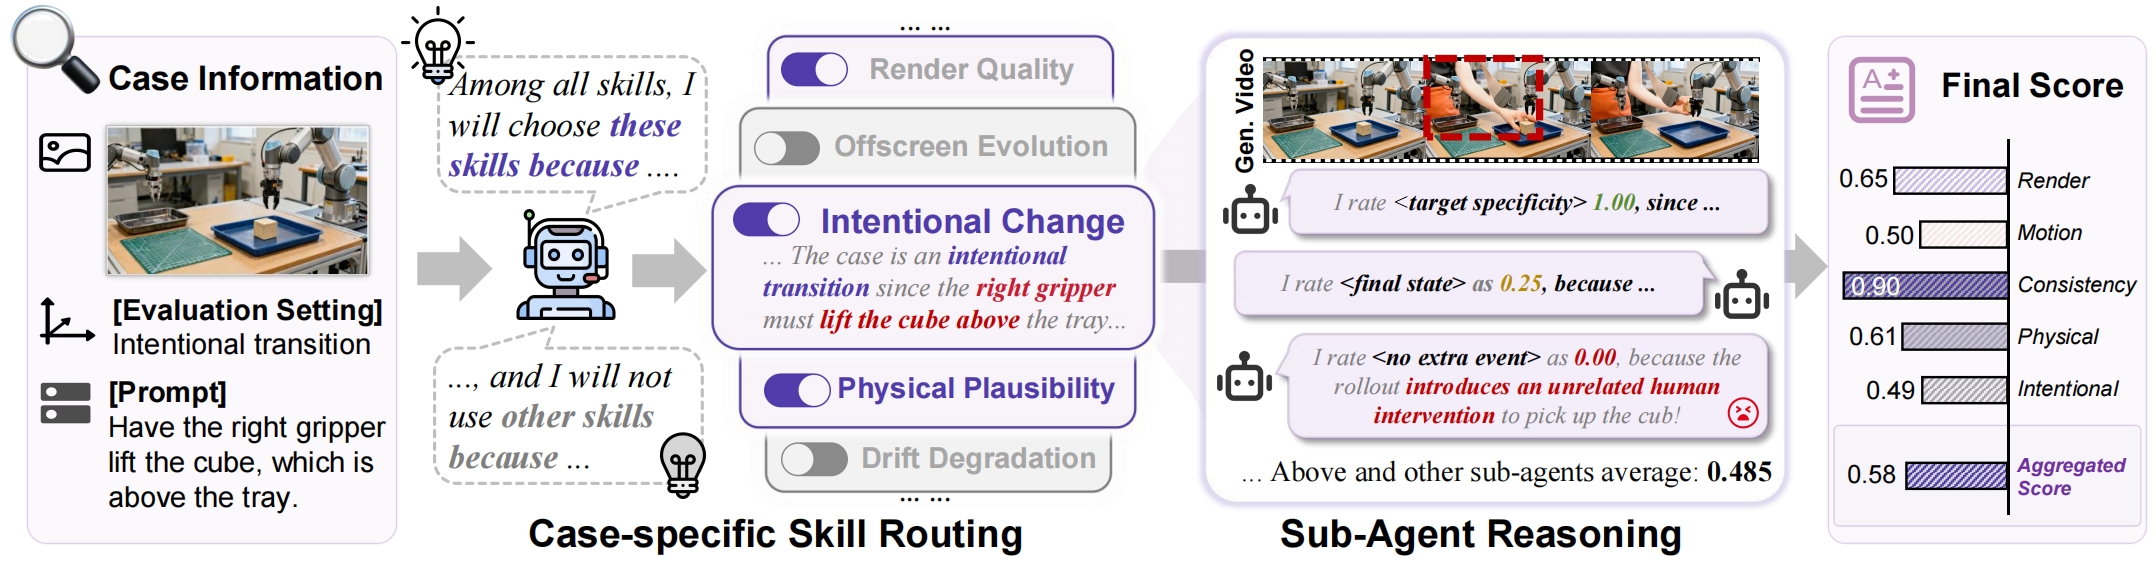
Это один инструмент с метрикой или полноценный агентный конвейер?Это мультиагентный конвейер: планировщик направляет каждый кейс тем скиллам, которые вправе его оценивать, выделенные субагенты отвечают на измеримые подвопросы, опираясь на доказательства из прогонов, а родительский агент проверяет и агрегирует эти доказательства в итоговую оценку кейса.
Это мультиагентный конвейер: планировщик направляет каждый кейс тем скиллам, которые вправе его оценивать, выделенные субагенты отвечают на измеримые подвопросы, опираясь на доказательства из прогонов, а родительский агент проверяет и агрегирует эти доказательства в итоговую оценку кейса.Как его запустить?Создайте три отдельных окружения - harnesseval-main (лаунчер/CLI), harnesseval-metrics (бэкенды метрик) и harnesseval-pavrm (бэкенд физической правдоподобности) - настройте учётные данные и пути, затем запустите входящий в комплект демо-пример в runs/example/resultsexample.
Создайте три отдельных окружения - harnesseval-main (лаунчер/CLI), harnesseval-metrics (бэкенды метрик) и harnesseval-pavrm (бэкенд физической правдоподобности) - настройте учётные данные и пути, затем запустите входящий в комплект демо-пример в runs/example/resultsexample.Что нужно перед запуском?Python плюс три отдельно управляемых окружения - для CLI-лаунчера, бэкендов метрик и бэкенда физической правдоподобности - в каждом из которых сначала настраиваются свои учётные данные и пути.
Python плюс три отдельно управляемых окружения - для CLI-лаунчера, бэкендов метрик и бэкенда физической правдоподобности - в каждом из которых сначала настраиваются свои учётные данные и пути.Каких подводных камней при установке ждать?Установка требует возни с тремя отдельными окружениями вместо одного, а хостинг-сервиса ещё нет - опция «отправить видео, получить оценки» всё ещё числится незаконченным TODO, так что пока всё работает локально.
Установка требует возни с тремя отдельными окружениями вместо одного, а хостинг-сервиса ещё нет - опция «отправить видео, получить оценки» всё ещё числится незаконченным TODO, так что пока всё работает локально.Что такое карточка кейса?Это проверяемый артефакт, который HarnessEval сохраняет по каждой оценке: каждый подвопрос, ответ субагента, оценка и подкрепляющий кадр, на которых основан итоговый вердикт.
Это проверяемый артефакт, который HarnessEval сохраняет по каждой оценке: каждый подвопрос, ответ субагента, оценка и подкрепляющий кадр, на которых основан итоговый вердикт.Какие модели мира он умеет оценивать?Он поддерживает модели мира, обусловленные текстом, изображением, действиями и камерой, включая Kling, MiniMax H3, Seedance, WAN и Cosmos, - через адаптеры генерации моделей.
Он поддерживает модели мира, обусловленные текстом, изображением, действиями и камерой, включая Kling, MiniMax H3, Seedance, WAN и Cosmos, - через адаптеры генерации моделей.Есть ли публичный лидерборд?Да, публичный набор из 100 кейсов с лидербордом был выпущен вместе с полным бенчмарком и кодом метрик в сентябре 2026 года.
Да, публичный набор из 100 кейсов с лидербордом был выпущен вместе с полным бенчмарком и кодом метрик в сентябре 2026 года.Почему бы просто не использовать фиксированную шкалу оценки?Фиксированные метрики считаются в лоб, без прослеживаемой цепочки рассуждений, поэтому HarnessEval вместо этого направляет кейсы специализированным субагентам, которые рассуждают над доказательствами и выдают обоснованную и прослеживаемую оценку.
Фиксированные метрики считаются в лоб, без прослеживаемой цепочки рассуждений, поэтому HarnessEval вместо этого направляет кейсы специализированным субагентам, которые рассуждают над доказательствами и выдают обоснованную и прослеживаемую оценку.What are similar projects?CodeVideoModel, object-permanence, RSIGame, context-language-models, Proteus, ParseBench, WanGP, Zero-WAM
CodeVideoModel, object-permanence, RSIGame, context-language-models, Proteus, ParseBench, WanGP, Zero-WAMWhich topics is it in?seedance, world-model, wan, minimax-h3, harness-engineering, arxiv, dataset, harness, evaluation, video-generation, generative-ai, huggingface
seedance, world-model, wan, minimax-h3, harness-engineering, arxiv, dataset, harness, evaluation, video-generation, generative-ai, huggingface