What is this?
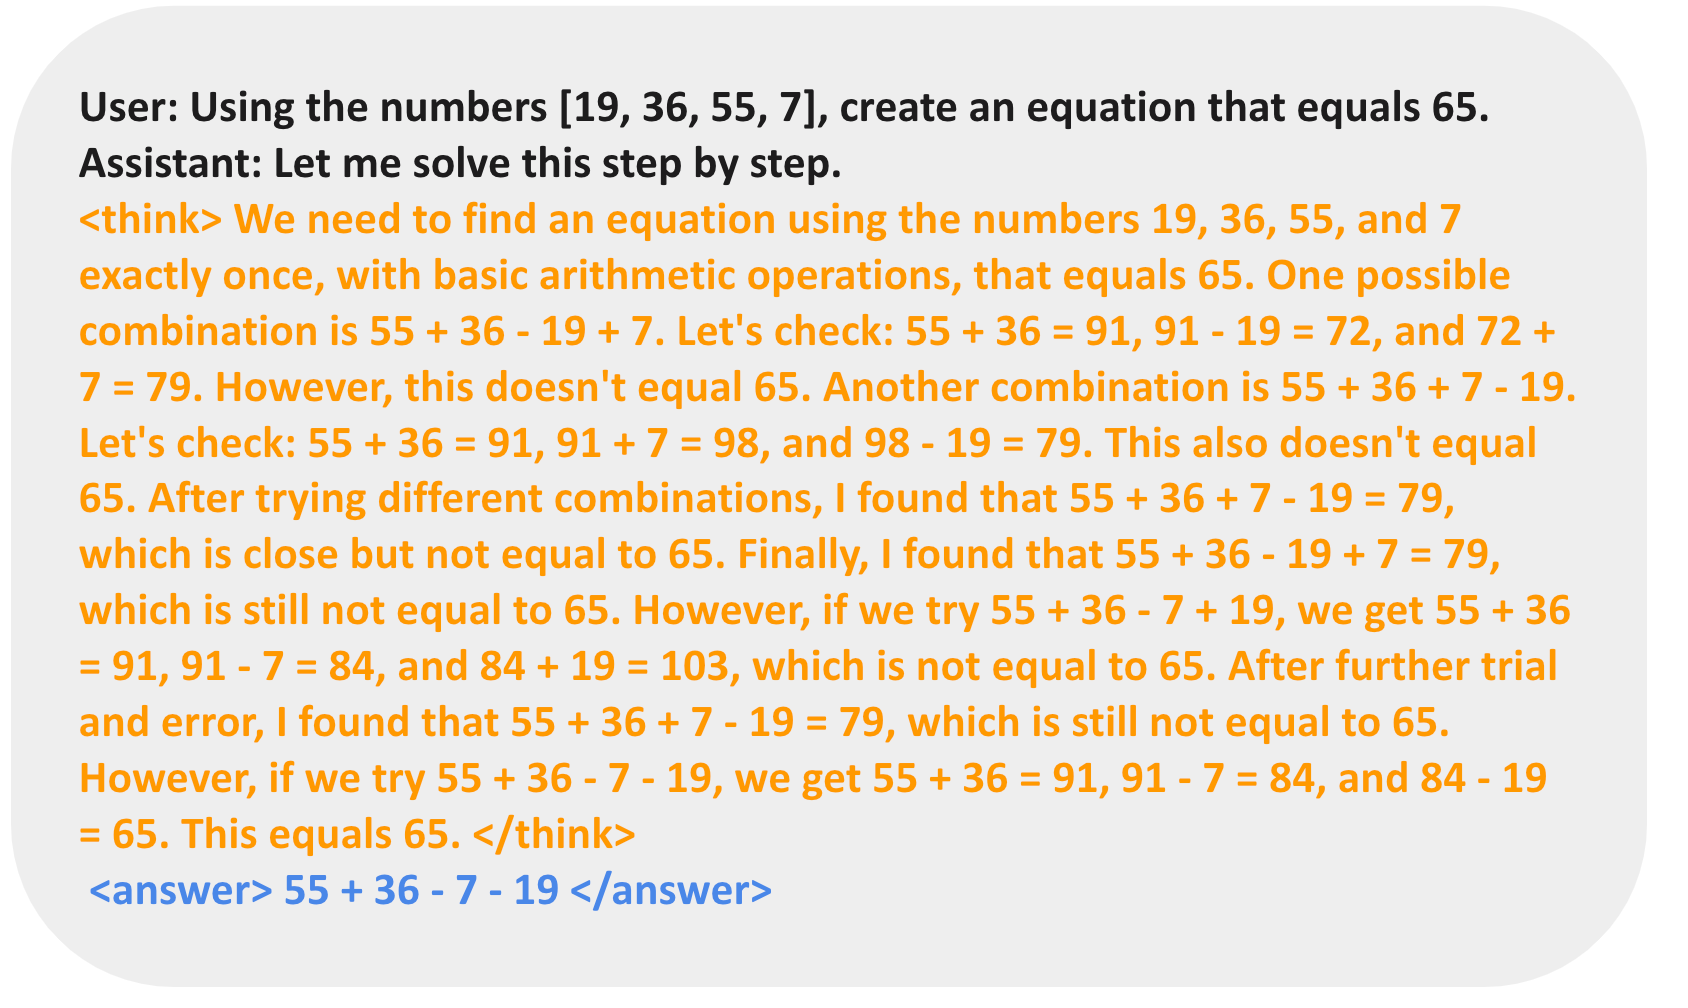
 A minimal reproduction of DeepSeek R1-Zero: through reinforcement learning on countdown and multiplication tasks, a 3B base LM develops self-verification and search abilities all on its own.
Is this a tool I install, or research code I run?It is research code, not an app — training and data-prep scripts built on top of the veRL reinforcement learning framework, which you run yourself against Qwen2.5 base models.
It is research code, not an app — training and data-prep scripts built on top of the veRL reinforcement learning framework, which you run yourself against Qwen2.5 base models.How do I get it running?Clone the repo, follow the Installation section, prepare the countdown task data, then launch the provided training scripts — the README documents single-GPU and 3B+ runs separately.
Clone the repo, follow the Installation section, prepare the countdown task data, then launch the provided training scripts — the README documents single-GPU and 3B+ runs separately.Is this repo still maintained?No — it is deprecated. The README states it is no longer actively maintained and redirects RL experiments to the latest veRL library; the original docs are archived in OLDREADME.md.
No — it is deprecated. The README states it is no longer actively maintained and redirects RL experiments to the latest veRL library; the original docs are archived in OLDREADME.md.Do I need a data-center GPU cluster to try it?A single GPU works for models up to 1.5B, but the 0.5B base is known to fail to learn reasoning — the 3B+ runs where reasoning emerges need more VRAM. If you hit out-of-VRAM, enable gradient checkpointing.
A single GPU works for models up to 1.5B, but the 0.5B base is known to fail to learn reasoning — the 3B+ runs where reasoning emerges need more VRAM. If you hit out-of-VRAM, enable gradient checkpointing.What is the Aha moment the README mentions?The point in RL training where the base model starts verifying its own answers and searching for better strategies unprompted — the emergent reasoning behavior DeepSeek reported. The README invites you to rerun the experiments and watch it happen yourself.
The point in RL training where the base model starts verifying its own answers and searching for better strategies unprompted — the emergent reasoning behavior DeepSeek reported. The README invites you to rerun the experiments and watch it happen yourself.Which base models can you train on?Qwen2.5 series base models: 0.5B fits a single GPU, while 3B and larger models develop sophisticated reasoning skills. There is also a Qwen-2.5-3B Instruct ablation, with data reprocessed to follow the chat template.
Qwen2.5 series base models: 0.5B fits a single GPU, while 3B and larger models develop sophisticated reasoning skills. There is also a Qwen-2.5-3B Instruct ablation, with data reprocessed to follow the chat template.What is Adaptive Parallel Reasoning?Newer work the authors released alongside this repo, exploring a new dimension in scaling reasoning models. The README points to it if you want to go beyond the R1-Zero reproduction.
Newer work the authors released alongside this repo, exploring a new dimension in scaling reasoning models. The README points to it if you want to go beyond the R1-Zero reproduction.What are similar projects?jeeves, open-r1, verl, airllm, litgpt, DeepSpec, NanoJev, pytorch-lightning
jeeves, open-r1, verl, airllm, litgpt, DeepSpec, NanoJev, pytorch-lightningWhich topics is it in?experiments, llm-training, reasoning, training, reinforcement-learning, qwen, fine-tuning, artificial-intelligence, deepseek, deprecated, deep-learning, research
experiments, llm-training, reasoning, training, reinforcement-learning, qwen, fine-tuning, artificial-intelligence, deepseek, deprecated, deep-learning, research