ncm README

项目的 README,来自 github.com/HazyResearch/ncm。合并为一个 markdown 文件:README.md。

NCM logo Next-Concept Modeling

Fast, Parallel Coarse-to-Fine Text Generation

Paper Hugging Face collection Blog post Scaling Intelligence blog post X thread MIT license

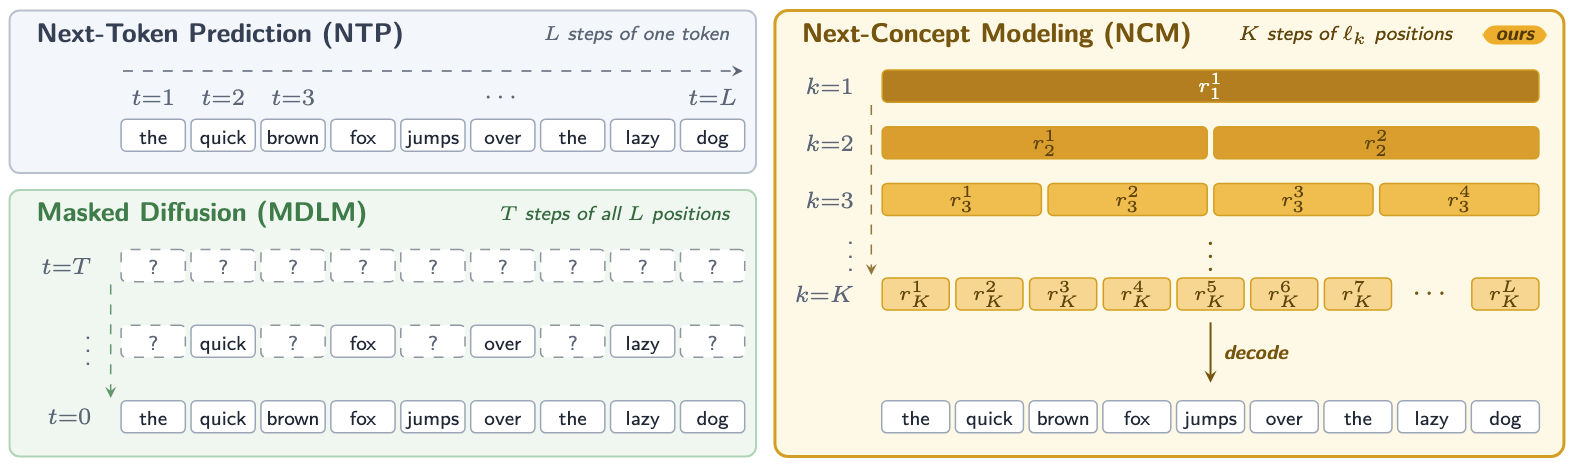
Next-Concept Modeling (NCM) is a two-stage framework for parallel text generation. A multiscale residual VQ tokenizer represents a sequence as a hierarchy of discrete codes, and a transformer predicts that hierarchy from coarse to fine. Positions within a level are generated in parallel, so generation requires one forward evaluation per level.

Comparison of autoregressive, diffusion, and next-concept generation

Highlights

Coarse-to-fine generation

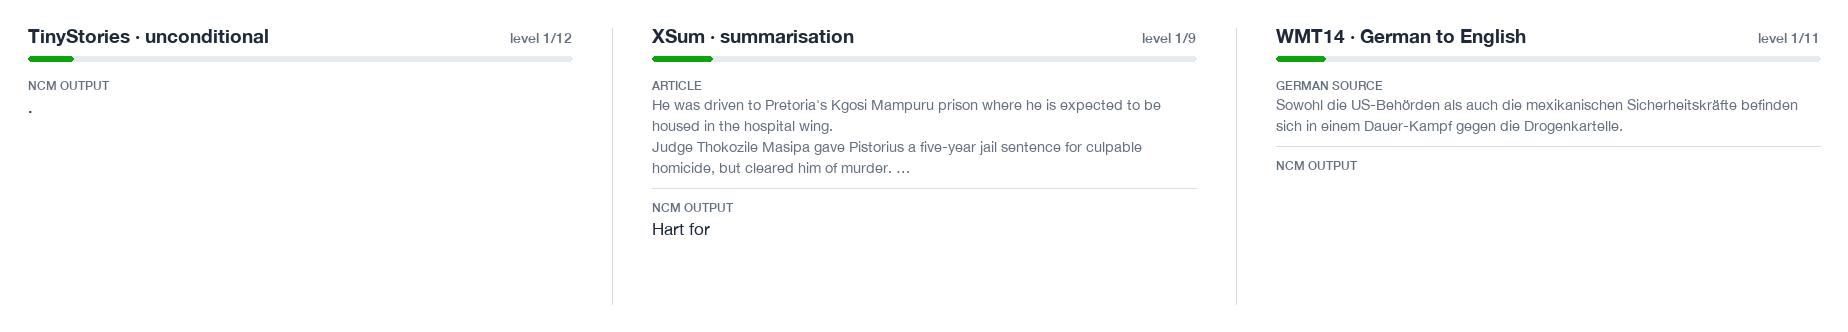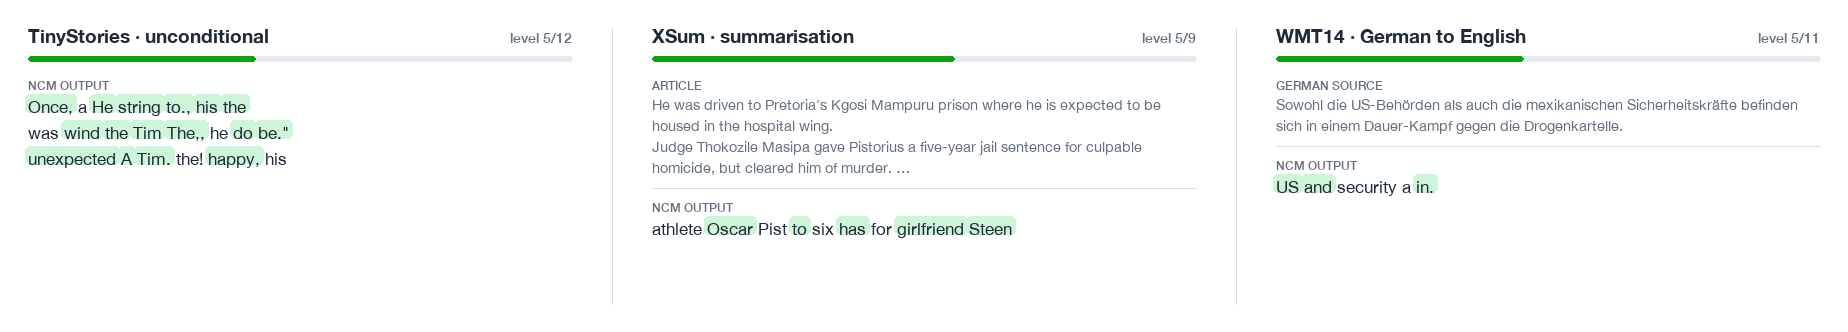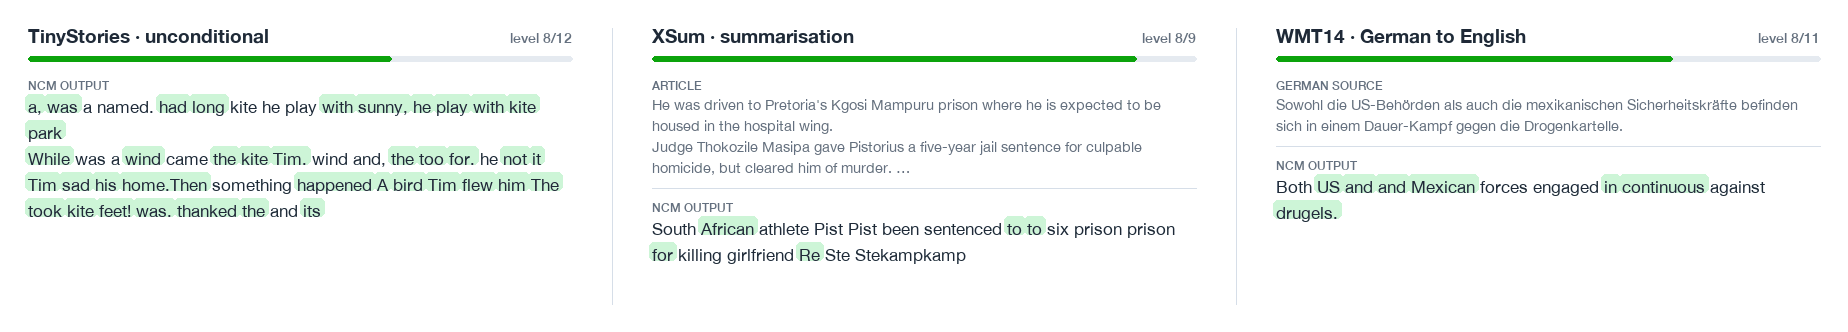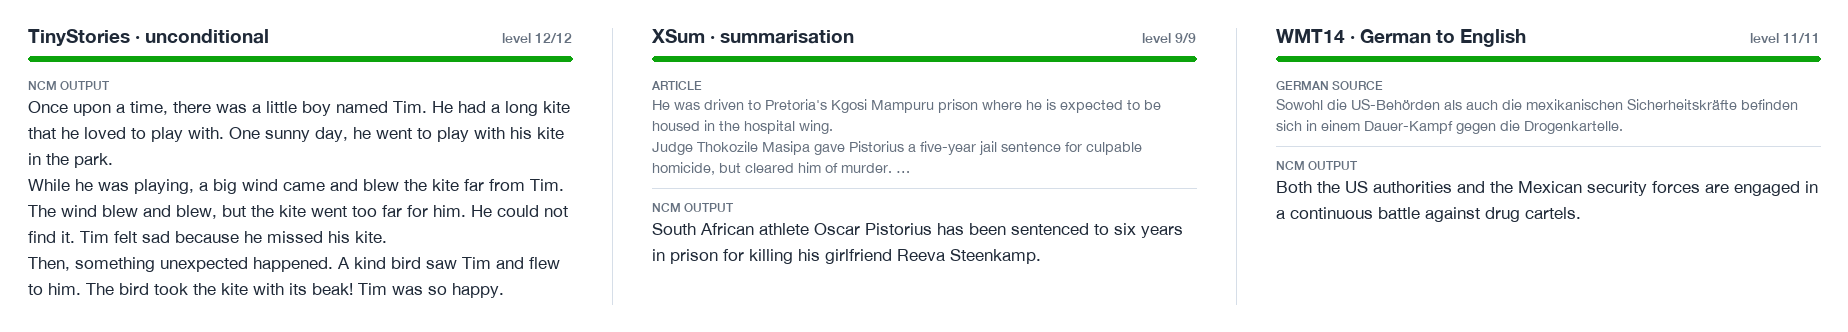
NCM generates coarse to fine: each level predicts a longer sequence in parallel, and decoding every level shows a sample being refined from a rough sketch to the full output in a few steps.

TinyStories, XSum and WMT14 samples refined level by level

Quality at a fraction of the cost

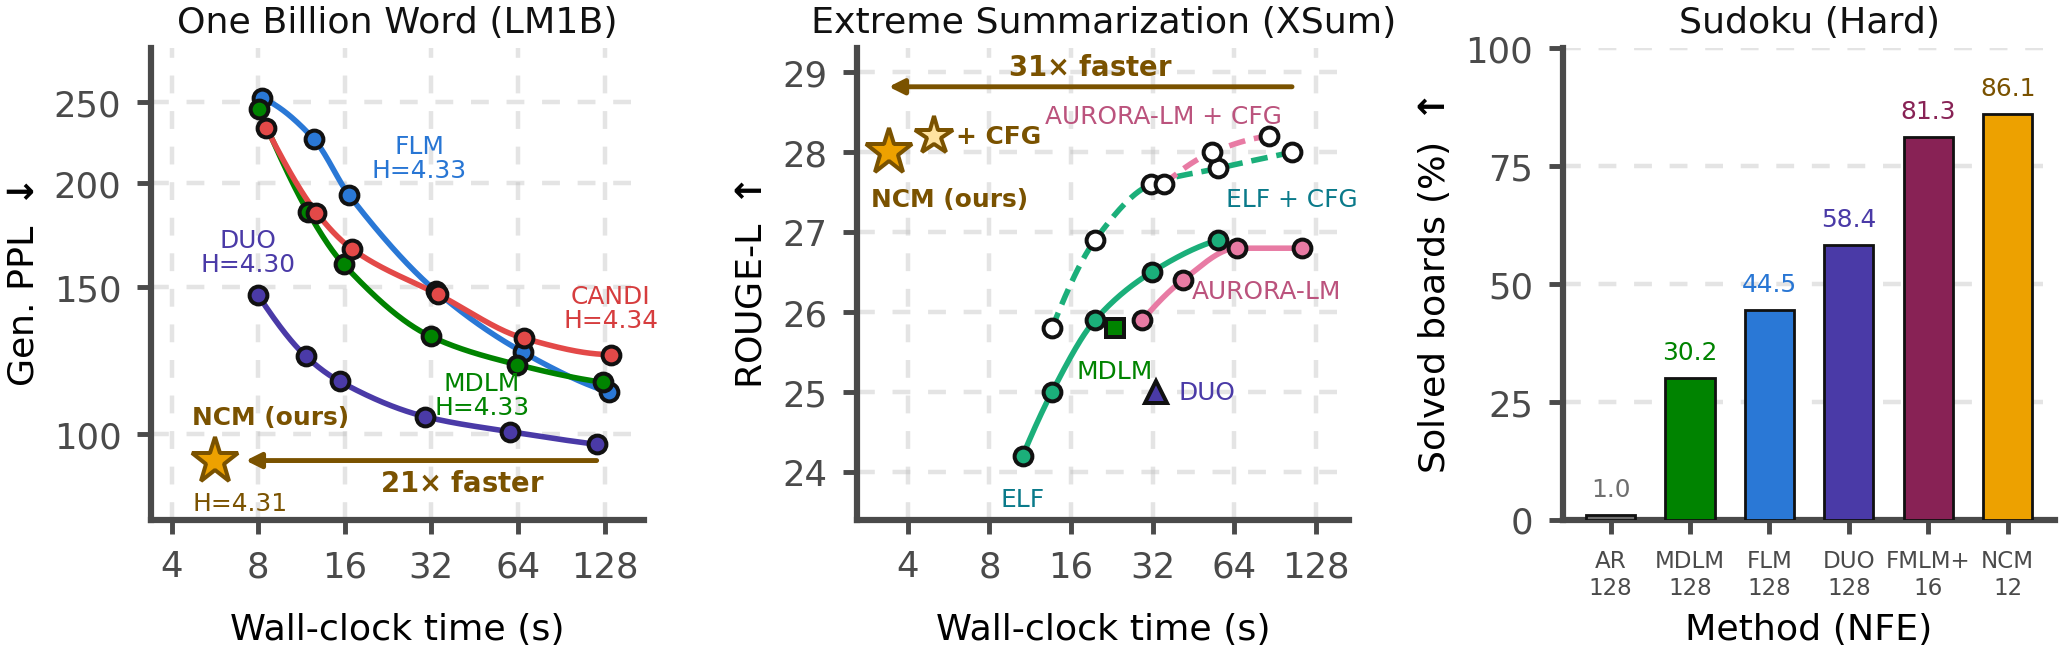
NCM beats or matches strong diffusion baselines on different tasks & datasets while generating 9-31× faster.

Generation quality against wall-clock time on LM1B and XSum, and hard Sudoku accuracy by method

Released models

Weights and tokenized datasets are hosted in the NCM Hugging Face collection. Each released model consists of a frozen tokenizer and a next-concept generator.

TaskModelTokenizerGeneratorConfigData
XSum–tokenizer.ptgenerator.ptconfig.yamltest set
WMT14 De–En–tokenizer.ptgenerator.ptconfig.yamltest set
Sudokueasytokenizer.ptgenerator.ptconfig.yamltest boards
mediumtokenizer.ptgenerator.ptconfig.yaml
hardtokenizer.ptgenerator.ptconfig.yaml
LM1Bsmalltokenizer.ptgenerator.ptconfig.yamltokenized text
mediumgenerator.ptconfig.yaml
largegenerator.ptconfig.yaml
TinyStories–tokenizer.ptgenerator.ptconfig.yamltokenized text
OpenWebText–tokenizer.ptgenerator.ptconfig.yamltokenized text

Installation

git clone https://github.com/HazyResearch/ncm.git
cd ncm
pip install -r requirements.txt

Python 3.10 or newer and a CUDA-capable PyTorch installation are recommended.

Evaluation

Download the checkpoints and evaluation inputs:

hf download hazyresearch/ncm-checkpoints --local-dir artifacts
hf download hazyresearch/ncm-datasets --repo-type dataset --local-dir data

Then run:

python evaluate.py --config config/eval/<task>.yaml --checkpoint-dir artifacts/<task> --data-dir data/<task>
# <task> is one of xsum, wmt14, sudoku-easy, sudoku-medium or sudoku-hard

python evaluate.py --config config/eval/<dataset>.yaml --checkpoint-dir artifacts/<dataset>
# <dataset> is tinystories, owt or lm1b-<size> with <size> one of small, medium or large

This runs one generation shard per visible GPU, merges them, and prints ROUGE-1/2/L and generative perplexity for XSum; cased and lowercased sacreBLEU, chrF and length ratio for WMT14; solved, cell and valid-grid rates for Sudoku; and generative perplexity under GPT-2 large with unigram entropy, over 5 seeds of 256 unconditional samples, for TinyStories, OpenWebText and LM1B, the latter under the FLM scoring protocol. Add --cfg <scale> for classifier-free guidance on XSum and WMT14; the guided WMT14 row uses --cfg 1.0.

Repository layout

Citation

@misc{kumbong2026nextconcept,
      title={Next-Concept Modeling: Fast, Parallel Coarse-to-Fine Text Generation},
      author={Hermann Kumbong and Ishan S. Khare and Iddah Mlauzi and Andrew Woen and Charles Ding and E. Kelly Buchanan and Simran Arora and Azalia Mirhoseini and Christopher Ré},
      year={2026},
      eprint={2610.14162},
      archivePrefix={arXiv},
      primaryClass={cs.CL},
      url={https://arxiv.org/abs/2610.14162},
}

Released under the MIT license.

ncm (HazyResearch/ncm)

正在搜索数据库…

1.9K ·GitHub
这是什么?NCM(Next-Concept Modeling)是一个两阶段的快速并行文本生成框架:残差 VQ 分词器将序列转换为由离散编码组成的层级结构,Transformer 则从粗到细预测这一层级结构,而不是逐个 token 生成。
这是可以直接使用的应用,还是附带已发布模型权重的研究代码库?这是一个研究代码库,包含分词器和生成器模型的代码以及评估框架;预训练检查点和分词后的数据集则单独托管在 Hugging Face 上。
如何对已发布的模型运行评估?下载你所需任务对应的检查点和评估输入数据,然后使用 config/eval/ 中对应的配置文件运行 evaluate.py。
运行 NCM 之前需要安装什么?需要 Python 3.10 或更高版本,以及支持 CUDA 的 PyTorch 版本;由于评估工作会分配到可见的各个 GPU 上,因此需要 GPU。
这个项目自带训练好的模型吗,还是我必须从头训练?仓库中只包含代码;要实际生成内容,你需要从 Hugging Face 下载某个已发布的冻结分词器加生成器检查点,且需针对特定任务,例如 XSum、WMT14 或 Sudoku。
NCM 开箱即用支持哪些任务和数据集?已发布的模型涵盖 XSum 摘要、WMT14 德英翻译、数独求解,以及 LM1B、TinyStories 和 OpenWebText 语言建模。
NCM 比基于扩散的文本生成快多少?NCM 的效果与强大的扩散基线相当或更优,同时生成速度快 9–31 倍,因为每个从粗到细的层级只需一次并行前向传播。
从粗到细的生成过程究竟是什么样的?层级结构中的每一层都会并行预测比上一层更长的序列,因此解码只需几步,就能逐步将粗略的草图细化为最终的全分辨率输出。
--cfg 参数有什么用?它在 XSum 和 WMT14 的评估中启用无分类器引导(classifier-free guidance),README 中引导后的 WMT14 结果使用的是 --cfg 1.0。
大小
0.7 MB
星标
1.9K
更新
提交Oct 14
时长
1个月
提交 · 90 天