Recursive Experiential–Working Memory Evolution for Long-Horizon Agent Harnesses
National University of Singapore · Stanford University · University of Oxford · Princeton University
💡 Introduction
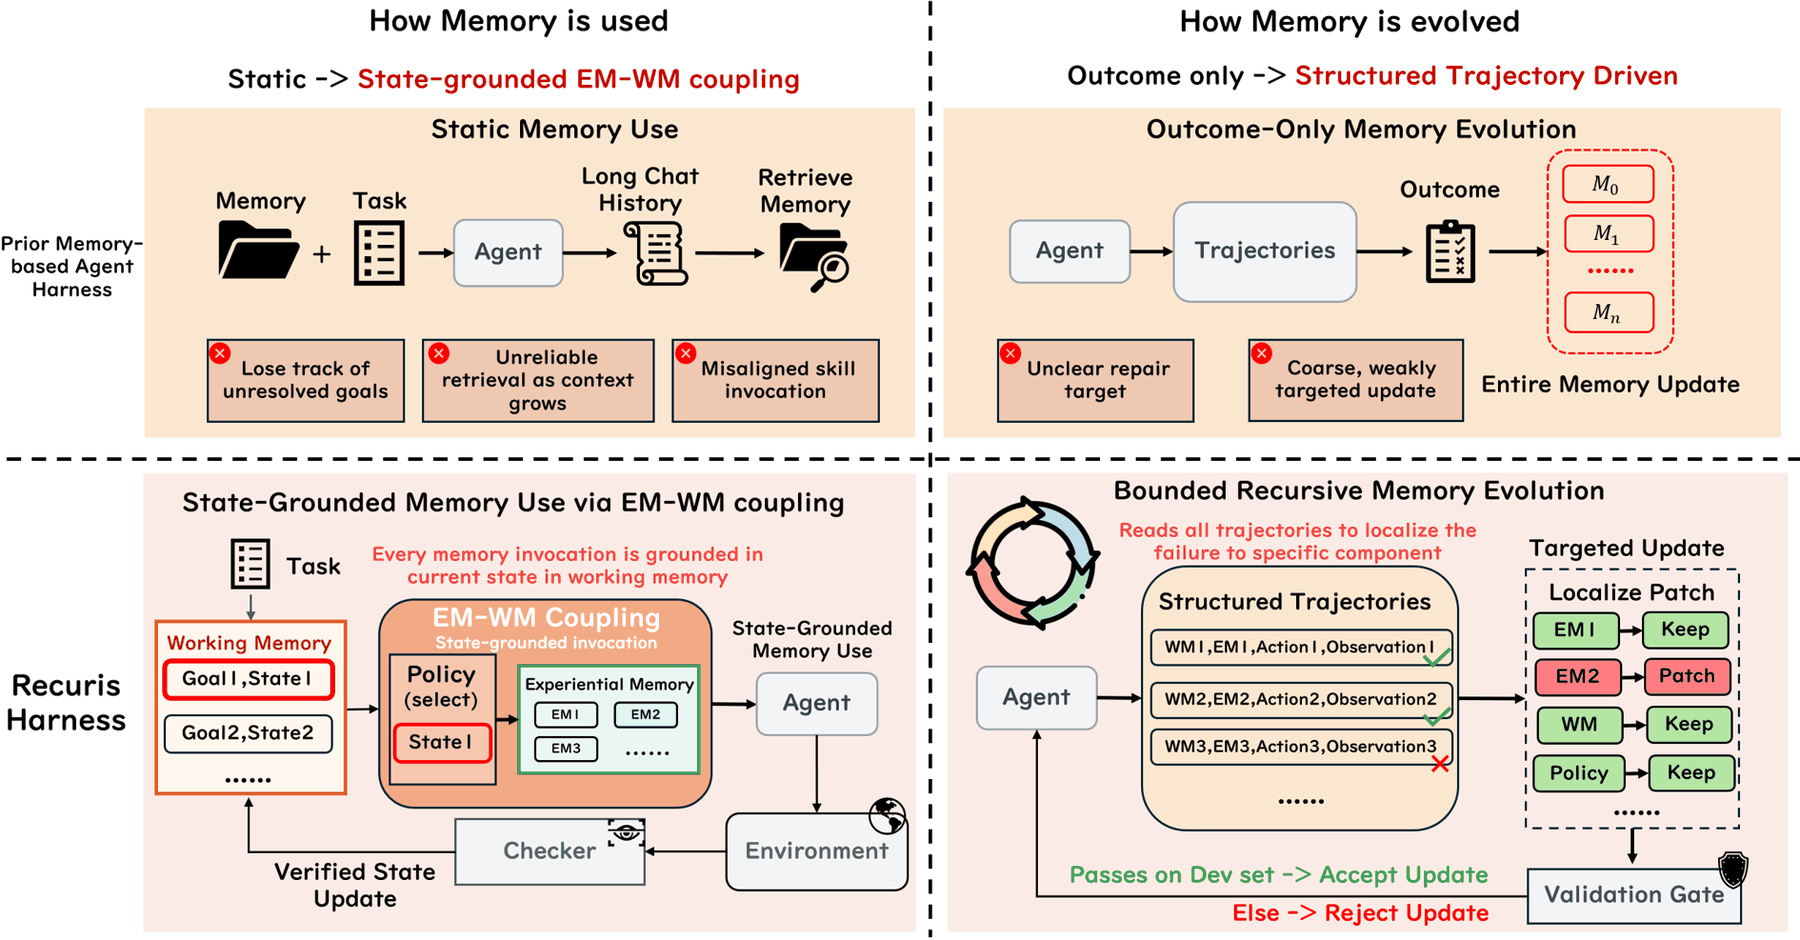
Recuris is a recursive self-improvement framework that improves a
long-horizon agent by evolving its memory instead of its weights or its
prompt. A frozen agent is paired with a Skill MemoryM = (E, W, ρ, C).
A meta-agent reads structured execution traces, locates each failure in one
component of that memory, and patches only that component. A deterministic
validation gate then decides, on paired held-out evidence, whether the patch
survives. Recuris has the following key features:
State-grounded memory use. Working memory drives skill invocation, so
retrieval is conditioned on verified task state rather than on a chat history
that grows until the state is buried.
Targeted memory evolution. Structured trajectories (w_t, E_t, a_t, o_t)
locate a failure in a specific component, instead of nudging a monolithic
prompt from outcomes alone.
Bounded by a validation gate. Candidates are admitted by paired held-out
arithmetic and nothing else. No model votes on its own patch.
Training-free and model-agnostic. The downstream agent stays frozen, and a
memory evolved on one model transfers to others unchanged.
Overall, Recuris achieves higher task success, larger gains on longer
horizons, and substantially fewer long-horizon failures, on both frontier
and open-source agents.
🔔 News
[2026-08] 🎉 Initial release: evaluation and evolution code, the evolved
Skill Memory packages, and the frozen evaluation splits.
📊 Results
Task success (avg@4, %), each model run with the benchmark's own reference
agent alone and with that same agent plus Recuris. Bold marks the better of
each pair, the subscript is Δ, † marks a paired task-clustered bootstrap 95% CI
excluding zero, and n/a means the model was not run on that benchmark.
Model
Cross-task evolution
Within-task adaptation
τ²-Retail
τ²-Airline
SkillFlow
Terminal-Bench 2.1
Open-source models
Granite-4.1-3B
9.7
34.3
0.3
0.6
+ Recuris
23.0+13.4†
39.8+5.5
0.0 −0.3
3.1+2.5
Qwen3.5-4B
68.0
75.3
6.0
10.1
+ Recuris
68.3+0.3
79.0+3.8
7.1+1.1
13.0+2.9
Qwen3.5-9B
77.6
75.5
15.1
17.4
+ Recuris
79.6+2.0
78.4+2.9
18.4+3.4
20.5+3.1
GPT-OSS-20B
50.6
54.8
7.8
3.9
+ Recuris
60.8+10.2†
59.3+4.5†
10.4+2.6†
6.7+2.8
Qwen3.6-27B
62.8
79.0
42.2
38.8
+ Recuris
71.2+8.3†
80.0+1.0
58.7+16.6†
42.1+3.3
Qwen3.6-35B
78.2
80.3
35.3
33.1
+ Recuris
78.5+0.3
81.5+1.3
48.8+13.5†
36.4+3.3
Frontier models
Gemini 3.7 Flash
73.5
86.5
n/a
79.8
+ Recuris
78.3+4.8
85.0 −1.5
n/a
82.4+2.6
GPT-5.6 Sol
58.3
79.0
n/a
83.2
+ Recuris
76.1+17.8†
86.0+7.0†
n/a
86.4+3.2
Claude Opus 5
72.4
89.5
n/a
84.6
+ Recuris
87.9+15.6†
90.5+1.0
n/a
88.4+3.8
Doubao-2.0-Pro (deployment)
58.1
75.5
34.6
46.1
+ Recuris
81.4+23.3†
80.5+5.0
51.4+16.8†
48.9+2.9
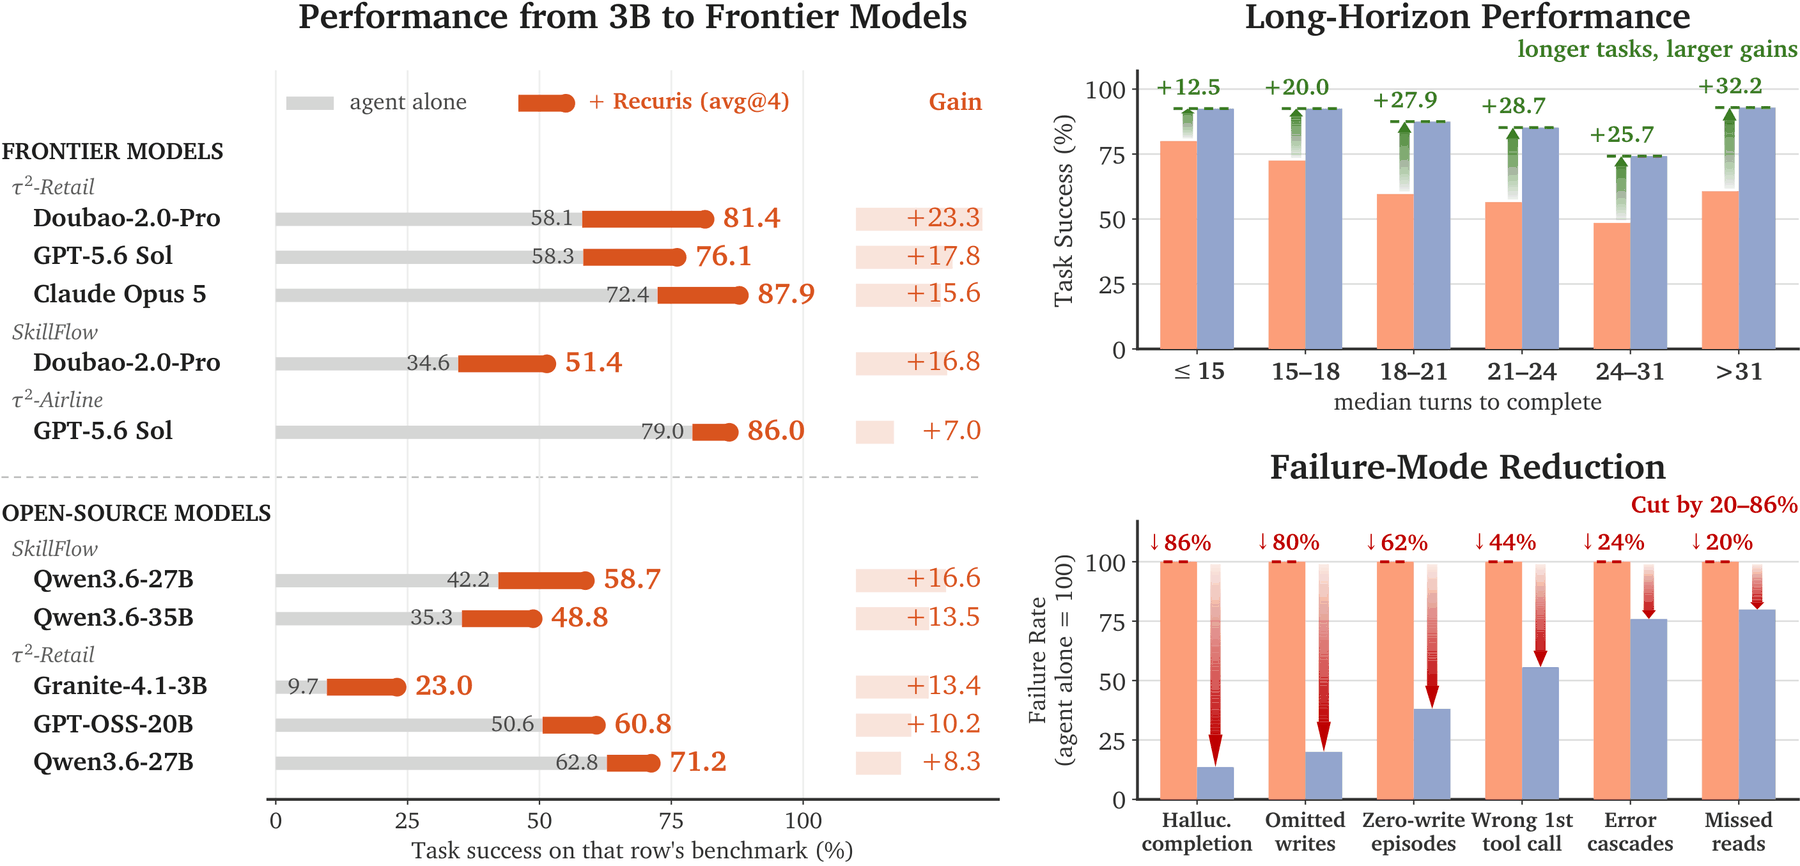
Recuris improves task success in 35 of the 37 completed model and benchmark
pairs, from a 3B open-source agent up to the strongest frontier models. The
largest gains reach +23.3 on τ²-Retail and +16.8 on SkillFlow. Gains
grow with the interaction horizon, reaching +32.2 on the longest tasks, and
common long-horizon failure modes drop by up to 80%.
🛠️ Getting Started
This repository provides the code for running Recuris on τ²-Bench, SkillFlow and
Terminal-Bench 2.1, the Skill Memory packages produced by the evolution loop,
and the frozen evaluation splits.
📦 Install Packages
Python 3.12 and git. SkillFlow and Terminal-Bench 2.1 also need Docker
with the Compose V2 plugin (docker compose version must work; harbor
shells out to it for every task).
git clone https://github.com/Gen-Verse/Recuris.git recuris
cd recuris

uv sync --extra all          # or: pip install -e ".[all]"
⚙️ Setup Environment Variables
Put your endpoint in a .env file at the repository root, or export it:
OPENAI_API_KEY=...
OPENAI_BASE_URL=...
Any OpenAI-compatible endpoint works. This is needed even when the agent itself
is an open-source model, because τ²-Bench scores every episode with an LLM user
simulator and an LLM assertion judge, and both stay pinned to a reference model.
🚀 Quick Start
Each benchmark is run twice, once with a Skill Memory loaded and once without.
The two runs differ only in the flags shown below. Both are needed, because the
number that matters is the difference between them.
Install tau2 after uv sync, not before: uv sync resolves the environment to
exactly what pyproject.toml declares, so running it again removes anything
added with uv pip install.
Serve an open-source model locally. τ²-Bench drives the agent through tool
calls, so the two tool-calling flags are required, not optional: without them
vLLM rejects every request and every episode ends ungraded.
--domain is retail or airline. For airline, use
--skill-memory tau2_airline.
--agent-llm-args must be identical in both runs. It is validated rather
than merged, so an unknown key raises an error instead of being dropped
silently.
Switching models means changing $MODEL and $ARGS. Nothing else changes.
Some servers need extras, for example
"extra_body":{"chat_template_kwargs":{"enable_thinking":false}} for Qwen.
🔹 SkillFlow
Set up the benchmark and build the task images once:
Generate the configs for both runs, then execute them:
export MODEL=openai/qwen3.6-27b
export BASE=http://127.0.0.1:8000/v1

recuris skillflow render-configs --arm bare \
    --model "$MODEL" --base-url "$BASE" --out configs/skillflow/generated
recuris skillflow render-configs --arm skill --routing default \
    --model "$MODEL" --base-url "$BASE" \
    --skill-memory skillflow --out configs/skillflow/generated

for cfg in configs/skillflow/generated/bare_*.yaml;  do harbor run -c "$cfg" --yes; done
for cfg in configs/skillflow/generated/skill_*.yaml; do harbor run -c "$cfg" --yes; done

recuris skillflow score --bare jobs/bare --skill jobs/skill
Notes:
Run the jobs one at a time. Concurrent harbor jobs exhaust the Docker IPv4
address pool, and the resulting failure looks like something else entirely.
Configs are generated rather than committed, so the two runs cannot drift
apart and no credential is ever written to disk.
--routing default is model-agnostic and is the right choice for new
work. --routing frozen_insample reproduces our reported numbers and applies
six per-family overrides that were chosen in-sample.
On this benchmark a task may be attempted several times in a row, and it stops
as soon as one attempt succeeds. --rounds sets how many attempts each task
gets. There are three configurations:
Configuration
What the agent carries
After a failed attempt
bare
nothing, the stock agent
nothing changes, the next attempt starts over
m0
a fixed Skill Memory, the seed package
nothing changes, the next attempt gets the same package
tta
the same package, as a per-task copy
the meta-agent reads the failed trajectory and writes a new card into that copy, which the next attempt carries
# smoke test: one task, one attempt
recuris tta run --taskset splits/tb21/tta_taskset_v3.json \
    --run-id smoke --arm m0 --limit 1 --rounds 1

# all three configurations, four attempts each
for cfg in bare m0 tta; do
    recuris tta run --taskset splits/tb21/tta_taskset_v3.json \
        --run-id demo --arm "$cfg" --rounds 4 --concurrency 3
done
Notes:
Give all three configurations the same --rounds. Comparing tta at four
attempts against bare at one mostly measures the extra attempts rather than
adaptation.
m0 against bare isolates the value of having a Skill Memory at all. tta
against m0 isolates the value of updating it between attempts, since both
carry a package and both get the same number of attempts.
At four attempts, that second comparison is worth +2.3 points, 60.9%
against 58.6%, which is not significant at this sample size. We report it
that way rather than as a headline number.
🔹 Evolving a Skill Memory
This is the recursive loop. A meta-agent, the upstream model, reads failed
trajectories from the agent being improved, the downstream model. It patches
one component of the memory, and a gate admits the patch only on paired held-out
evidence.
npm install -g @anthropic-ai/claude-code
RECURIS_META_MODEL=...        # the upstream meta-agent's model
RECURIS_META_BASE_URL=...
RECURIS_META_API_KEY=...
--meta-model is the upstream meta-agent and --worker-model is the
downstream agent being improved. Both default to Doubao.
--base neutral starts from a deterministic seed package, so no
hand-written domain profile enters the loop.
Start with qualify and then a single round. Each round writes a full record:
the evidence the session was given, the plan it produced, the gate arithmetic,
and the ledger entry. A round that admits nothing is a valid outcome.
Evolving a package for a specific model beats reusing one evolved elsewhere.
On GPT-OSS-20B a rebuilt package gained +10.2, while the general-purpose
package transferred negatively.
📖 Citation
@article{yu2026recuris,
  title   = {Recursive Experiential--Working Memory Evolution for Long-Horizon Agent Harnesses},
  author  = {Yu, Zhaochen and Wu, Yingcheng and Yin, Zhenfei and Chen, Kaiyuan and Zhao, Zhe and Wang, Mengdi and Yan, Shuicheng and Yang, Ling},
  journal = {arXiv preprint arXiv:2608.24876},
  year    = {2026}
}
What is this?Recuris is a recursive self-improvement framework that boosts long-horizon LLM agents by evolving their memory instead of their weights or prompt. A frozen agent is paired with a structured Skill Memory, and a meta-agent patches it based on execution traces, only keeping changes that pass a validation gate.
Does it fine-tune the agent, or just change what it remembers?It is training-free and model-agnostic: the downstream agent's weights stay completely frozen, and only the Skill Memory object is edited by a separate meta-agent. A memory package evolved on one model can transfer unchanged to other models.
How do I run the benchmarks?Install Python 3.12 and git, point an OpenAI-compatible endpoint from a .env file, then run each benchmark twice (once with a Skill Memory loaded, once without) using the flags provided for τ2-Bench, SkillFlow or Terminal-Bench 2.1 and compare the two runs.
Do I need Docker for every benchmark?τ2-Bench only needs Python 3.12 and git, but SkillFlow and Terminal-Bench 2.1 also require Docker with the Compose V2 plugin, since the harness shells out to 'docker compose' for every task.
Does Recuris always improve the agent?Not guaranteed for every pair — it improved results in 35 of 37 completed model/benchmark combinations, but a generic memory can transfer negatively to a new model: GPT-OSS-20B needed its own rebuilt package to gain +10.2 points instead of regressing with the general-purpose one.
What does a Skill Memory actually contain?It is a structured object M = (E, W, ρ, C) combining execution traces, working-memory state and skill cards, which the meta-agent patches component by component instead of editing one monolithic prompt.
Why does it need an LLM endpoint even when the agent itself is open-source?τ2-Bench scores every episode with an LLM user simulator and an LLM assertion judge that stay pinned to a reference model, so an OpenAI-compatible endpoint is required no matter which model you evaluate.
Which benchmarks does Recuris ship evaluation code for?τ2-Bench (retail and airline domains), SkillFlow, and Terminal-Bench 2.1, each with its own evolution/evaluation scripts and frozen evaluation splits.




 Recuris is a recursive self-improvement framework that boosts long-horizon LLM agents by evolving their memory instead of their weights or prompt. A frozen agent is paired with a structured Skill Memory, and a meta-agent patches it based on execution traces, only keeping changes that pass a validation gate.