SOLO in 75 seconds
https://github.com/user-attachments/assets/52b05335-46a2-4bf0-bf8f-a7a45033a8eb
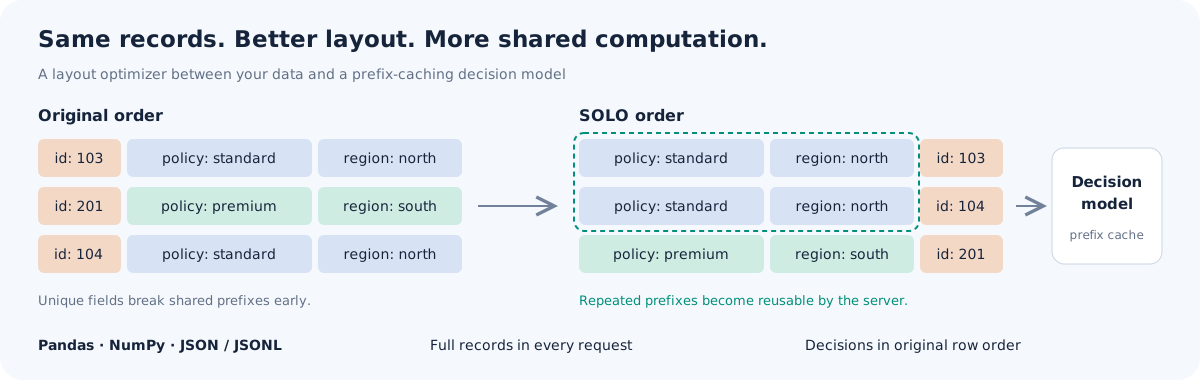
SOLO runs a natural-language decision over every record in your dataset.
It arranges rows and fields so a prefix-caching backend can reuse more input
computation, then returns decisions in your original row order. The backend
receives the complete record on every request.
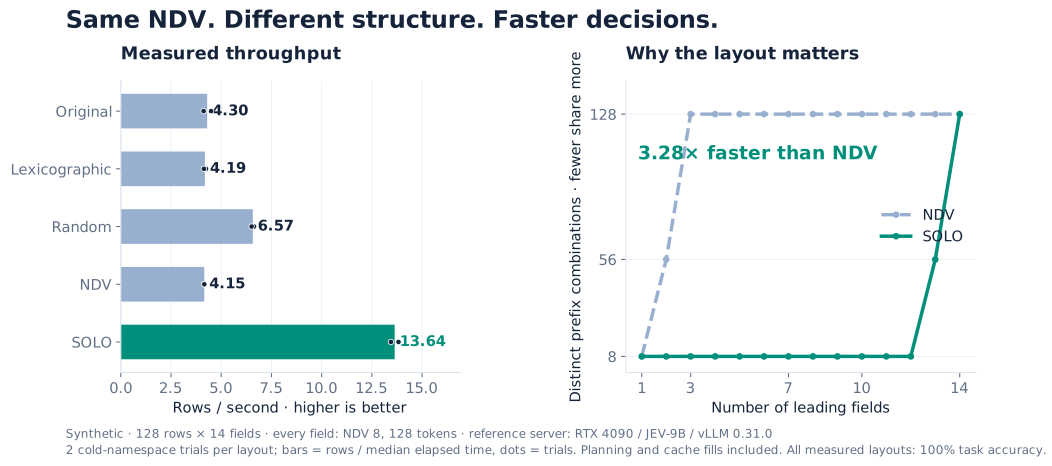
Measured on one RTX 4090: up to 11.7× throughput over original order
with long shared context, and 3.28× over NDV sorting with correlated fields.
Both are reproducible synthetic workloads; see the full conditions below.
Use it for structured workloads with repeated policies, account context, catalog
attributes, or correlated fields. The included backend serves AutoTrust JEV-9B,
an open decision model built on Qwen3.5-9B, through vLLM. It returns binary,
categorical or scored decisions with probabilities. The layout optimizer also
works independently with your own backend.
Quickstart
Install from this source checkout (Python 3.10+):
python -m pip install ".[pandas,hub]"
This installs the client. For inference, connect to a running JEV-9B service or
deploy one on your GPU. With the default local service:
import pandas as pd
from solo_layout import DecisionEngine

tickets = pd.DataFrame([
    {"id": "T-104", "policy": "Refunds within 30 days", "request": "Please refund my order."},
    {"id": "T-201", "policy": "Refunds within 30 days", "request": "Can I exchange the size?"},
])
with DecisionEngine() as engine:
    result = engine.scan(tickets, "Does the request ask for a monetary refund?")
print(result.to_pandas())  # Decisions + probabilities, aligned with tickets.index
The client downloads only the pinned model's two small decision-head metadata
files on first inference. Set model_dir="/path/to/JEV-9B" to use local metadata.
Model weights, vLLM and Torch stay on the server.
Try the optimizer with no GPU or network:
python examples/offline_layout.py
JSON is an input, too:
from pathlib import Path
from solo_layout import DecisionEngine

with DecisionEngine() as engine:
    result = engine.scan(Path("tickets.jsonl"), "Does this customer request a refund?")
JSON text, JSON/JSONL files, nested objects, DataFrames, and NumPy arrays share the
same engine. See the input contract for schema and type rules.
Why can a one-token decision still be slow?
A decision model may return only one label, but it must first process the full
contract, policy, user context or candidate. On JEV-9B, median request latency
rose from 0.280 seconds at roughly 1K input tokens to 0.897 seconds at 6.5K,
even though every request produced exactly one token.
SOLO keeps every field and leaves the model unchanged. It reorganizes repeated
content inside an already-ready batch so the inference server can reuse more of
the input. Across all 1,088 decisions from 64 selected ContractNLI contracts,
original-order accuracy was 66.18%; SOLO reached 73.90%. Completing the same
17 batches of 64 took 293.64 seconds with the original layout and 115.73 seconds
with SOLO—a 2.54× speedup.
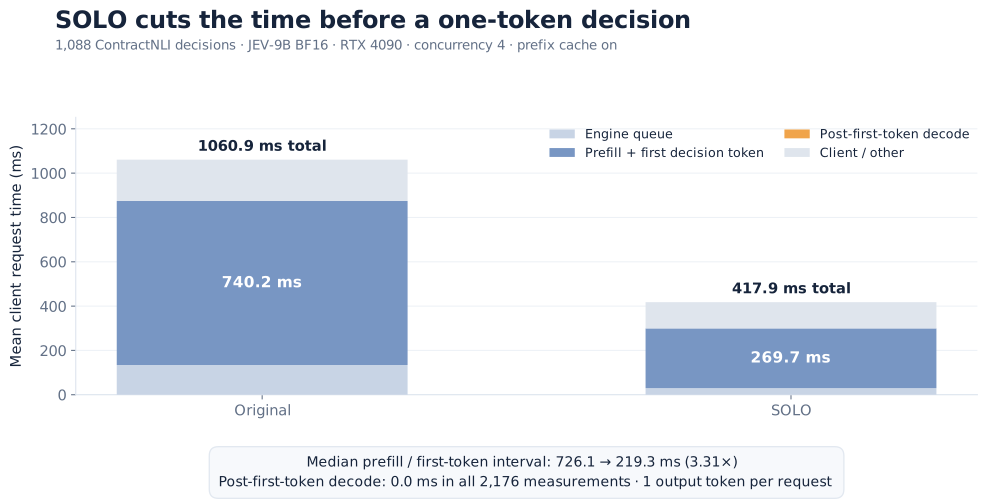
The server timings show where that reduction happens. The median interval from
scheduling to the first decision token fell from 726.1 ms to 219.3 ms
(3.31×). Every request emits one decision token, so the subsequent decode
interval was 0.0 ms in all 2,176 original/SOLO request measurements.
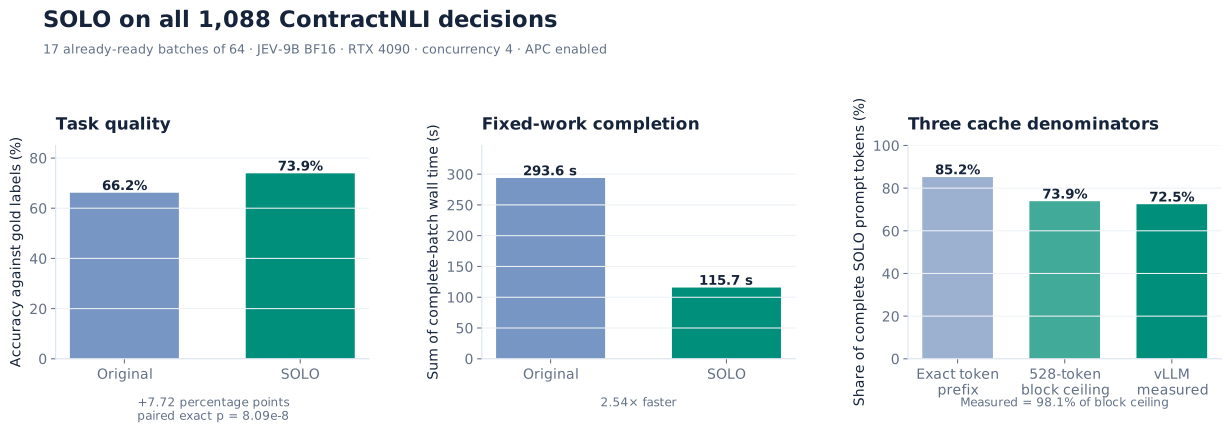
The speedup disappears when APC is disabled. With APC enabled, 85.19% of SOLO
prompt tokens had an earlier exact prefix, 73.89% remained reusable after
528-token block quantization, and vLLM reported 72.48% actually cached—98.1% of
the block-level ceiling.
Full protocol, cache controls and statistics ·
Timing aggregate ·
Full-coverage aggregate
Two reproducible demos
These are controlled synthetic workloads measured on a real RTX 4090 with
JEV-9B BF16, vLLM 0.31.0, prefix caching enabled and concurrency 4. The model,
complete input records, and concurrency are held constant across layouts. Each
method starts in a fresh cache namespace; reported time includes planning,
serialization, HTTP and the first cache fills. Figures show two trials per method.
1. Repeated context: move the unique ID out of the way
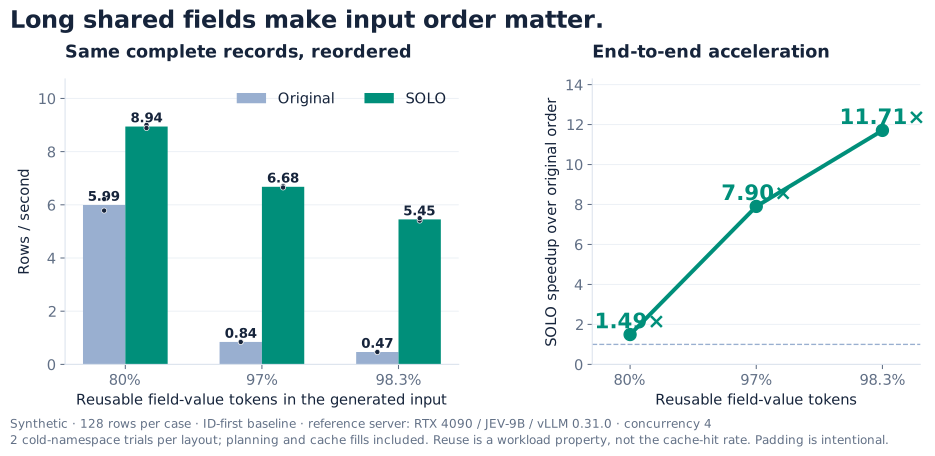
Many records share policies or account context, but an ID-first serialization
breaks the reusable prefix. This demo deliberately varies the length of repeated
fields to measure that effect. The reuse percentage describes field-value tokens,
not the server's cache-hit rate.
| Reusable field-value tokens |
Max prompt tokens |
Original rows/s |
SOLO rows/s |
Speedup |
| 80.0% |
1,401 |
5.99 |
8.94 |
1.49× |
| 97.0% |
8,881 |
0.84 |
6.68 |
7.90× |
| 98.3% |
15,611 |
0.47 |
5.45 |
11.71× |
In the longest-context case, the same 128 records finish in 23.5 seconds
instead of 274.9 seconds. All measured layouts reach 100% accuracy on this
synthetic refund task. Raw trials ·
Figure PDF
All 14 fields have the same NDV (8) and the same length (128 tokens).
Twelve fields encode correlated information. Sorting columns by marginal NDV
leaves their original order unchanged; SOLO groups fields using their joint
prefix structure.
| Layout |
Rows/s |
Cached input |
SOLO speedup over layout |
| Original |
4.30 |
0.0% |
3.17× |
| Lexicographic |
4.19 |
0.0% |
3.26× |
| Random |
6.57 |
45.3% |
2.07× |
| NDV |
4.15 |
0.0% |
3.28× |
| SOLO |
13.64 |
77.8% |
1.00× |
All methods send 244,352 input tokens per scan and reach 100% accuracy on
this synthetic refund task. Random uses seed 42; NDV breaks ties by input order.
These examples isolate useful mechanisms, rather than establish a universal
speedup. Raw trials · Protocol and reproduction
python -m pip install ".[demo]"
# Repeated-context sweep, matching the figure:
python demo.py --model-dir /path/to/JEV-9B --workload shared \
  --rows 128 --repeat-ratios .80 .97 .983 --methods original solo --repeats 2
# Equal-NDV correlated fields, all five baselines:
python demo.py --model-dir /path/to/JEV-9B --workload correlated \
  --rows 128 --cardinality 8 --correlated-columns 12 --field-tokens 128 --repeats 2
Understand your own data
Inspect layouts locally before running inference:
from solo_layout import LayoutOptimizer

report = LayoutOptimizer().explain(tickets)
print(report.to_pandas())
The report exposes column NDVs, distinct prefix combinations and adjacent shared
prefix bytes. It diagnoses reusable structure; tokenization, cache block size,
GPU scheduling and task quality still need measurement.
Compare full scans using the same engine:
with DecisionEngine() as engine:
    comparison = engine.compare(
        tickets, "Does the request ask for a monetary refund?",
        methods=["original", "lexicographic", "random", "cardinality", "solo"],
        repeats=2, seed=42,
    )
print(comparison.to_pandas())
Binary decisions, categorical choices and scores from 0 to 5 are supported.
API reference · Runnable examples
How it works
- Normalize the input. Keep every field and retain original row identity.
- Plan the layout. Choose columns that keep distinct prefix combinations
small, then stably group rows under that column order.
- Run decisions. Send complete records through a bounded, concurrent client.
vLLM reuses matching prefix computation between requests.
- Restore outputs. Decisions and probabilities return in original row order,
including the original DataFrame index.
The planner is backend-independent:
plan = LayoutOptimizer("solo").plan(tickets)
ordered = plan.apply(tickets)
# predictions = your_backend(ordered)
# original_order_predictions = plan.restore(predictions)
The optimized integer-stamp kernel is retained unchanged from SOLO's
“Optimize SOLO planning with reusable integer stamps” PR #1. After encoding,
exact greedy grouping costs O(NM²) time and O(N + M) auxiliary space,
besides the compact O(NM) encoded table. Fixed-order row grouping is O(NM).
Implementation and provenance
Decision backends and deployment
SOLO now has two prefix-cache-aware clients: the measured AutoTrust JEV-9B
backend below, and VllmJevBackend for the open-source
vllm-jev framework. The first vllm-jev
target is Open-Jev-2B:
from solo_layout import DecisionEngine, VllmJevBackend

backend = VllmJevBackend("http://127.0.0.1:8795")
with DecisionEngine(backend=backend) as engine:
    result = engine.scan(rows, question, cache_salt="arrived-batch-42")
The adapter calls vllm-jev's Choice plugin with one shared cache namespace for
the batch, while preserving SOLO's serialized field order. See the
setup and selection notes.
On the 64-row shared-policy microbenchmark, SOLO raised reported cached input
from 45.78% to 91.59% and reduced median batch time from 5.448 s to
3.254 s (1.67×). With prefix reads disabled, the two layouts were within
2.6%. Configuration and raw results
AutoTrust JEV-9B
Our experiments use autotrust/JEV-9B,
AutoTrust's independent open reproduction of TypeSafe Jev's decision behavior.
AutoTrust provides the Qwen3.5-9B backbone, trained decision adapter and
calibration metadata; SOLO provides the input-layout optimizer and
table/JSON execution interface.
We load the upstream adapter_vllm adapter into vLLM as jev-decision and enable
prefix caching. The client sends a complete record to /v1/completions, obtains
one-token option log probabilities, and applies the upstream head bias and
calibration to return the decision distribution. See the
deployment guide for the exact
revision and request path.
On a compatible Linux NVIDIA GPU host, the deployment helper installs the server
in an isolated environment, downloads pinned weights, and starts a local API:
bash deploy/jev9b.sh up
The measured configuration fits JEV-9B BF16 on one RTX 4090 24 GB with a 16K
context limit and concurrency 4. See deployment requirements, reuse of existing
weights, and health checks.
SOLO is useful when complete records contain reusable prefixes after reordering
and prefill is a meaningful part of execution time.
Development and research credit
python -m pip install -e ".[dev,demo,plot]"
python -m pytest
python -m build
python scripts/render_benchmarks.py
The wheel contains the client and planner. Demos, figures, raw measurements and
GPU deployment tools remain in the source distribution. See
CONTRIBUTING.md for contribution and benchmark guidance.
Citation
SOLO builds on our ICML 2026 paper. If you find this project useful
in your research, please consider citing our work:
Prefix-Cache-Aware Data Reordering for LLM-Augmented Database Analytics
Yingze Li, Dong Wang, Yiming Guo, Yao Chen, Hongzhi Wang, and Bingsheng He.
@InProceedings{pmlr-v306-li26gn,
  title     = {Prefix-Cache-Aware Data Reordering for {LLM}-Augmented Database Analytics},
  author    = {Li, Yingze and Wang, Dong and Guo, Yiming and Chen, Yao and Wang, Hongzhi and He, Bingsheng},
  booktitle = {Proceedings of the 43rd International Conference on Machine Learning},
  year      = {2026},
  volume    = {306},
  pages     = {70693--70723},
  series    = {Proceedings of Machine Learning Research},
  publisher = {PMLR},
  url       = {https://proceedings.mlr.press/v306/li26gn.html},
  pdf       = {https://raw.githubusercontent.com/mlresearch/v306/main/assets/li26gn/li26gn.pdf}
}
Thank you for supporting our research! Please also report the SOLO
version used in your experiments to help others reproduce your results.
Citation metadata · Planner provenance ·
Original research implementation ·
MIT license

 SOLO 会对数据集的行和字段进行重排,让带前缀缓存的 LLM 决策后端能够跨请求复用计算,对每一行执行自然语言决策,同时按原始行顺序返回结果。