Harness Self-Evolution: Theory,
Algorithms, Evaluation, Applications, and Impact
📄 Full version · 66 pages
Self-Evolving Agent Harness · arXiv · Project Page · Reading List · Citation · 中文版 · 
Chuyang Wei1,3, Haoxiang Guan1,3, Minghang Zhu1, Kexin Zhou1,3, Jiyan He1,2, Xiren Zhou3, Huanhuan Chen3, Yifei Shen1,2,†
1 Zhongguancun Academy · 2 Zhongguancun Institute of Artificial Intelligence
3 University of Science and Technology of China · † Corresponding author
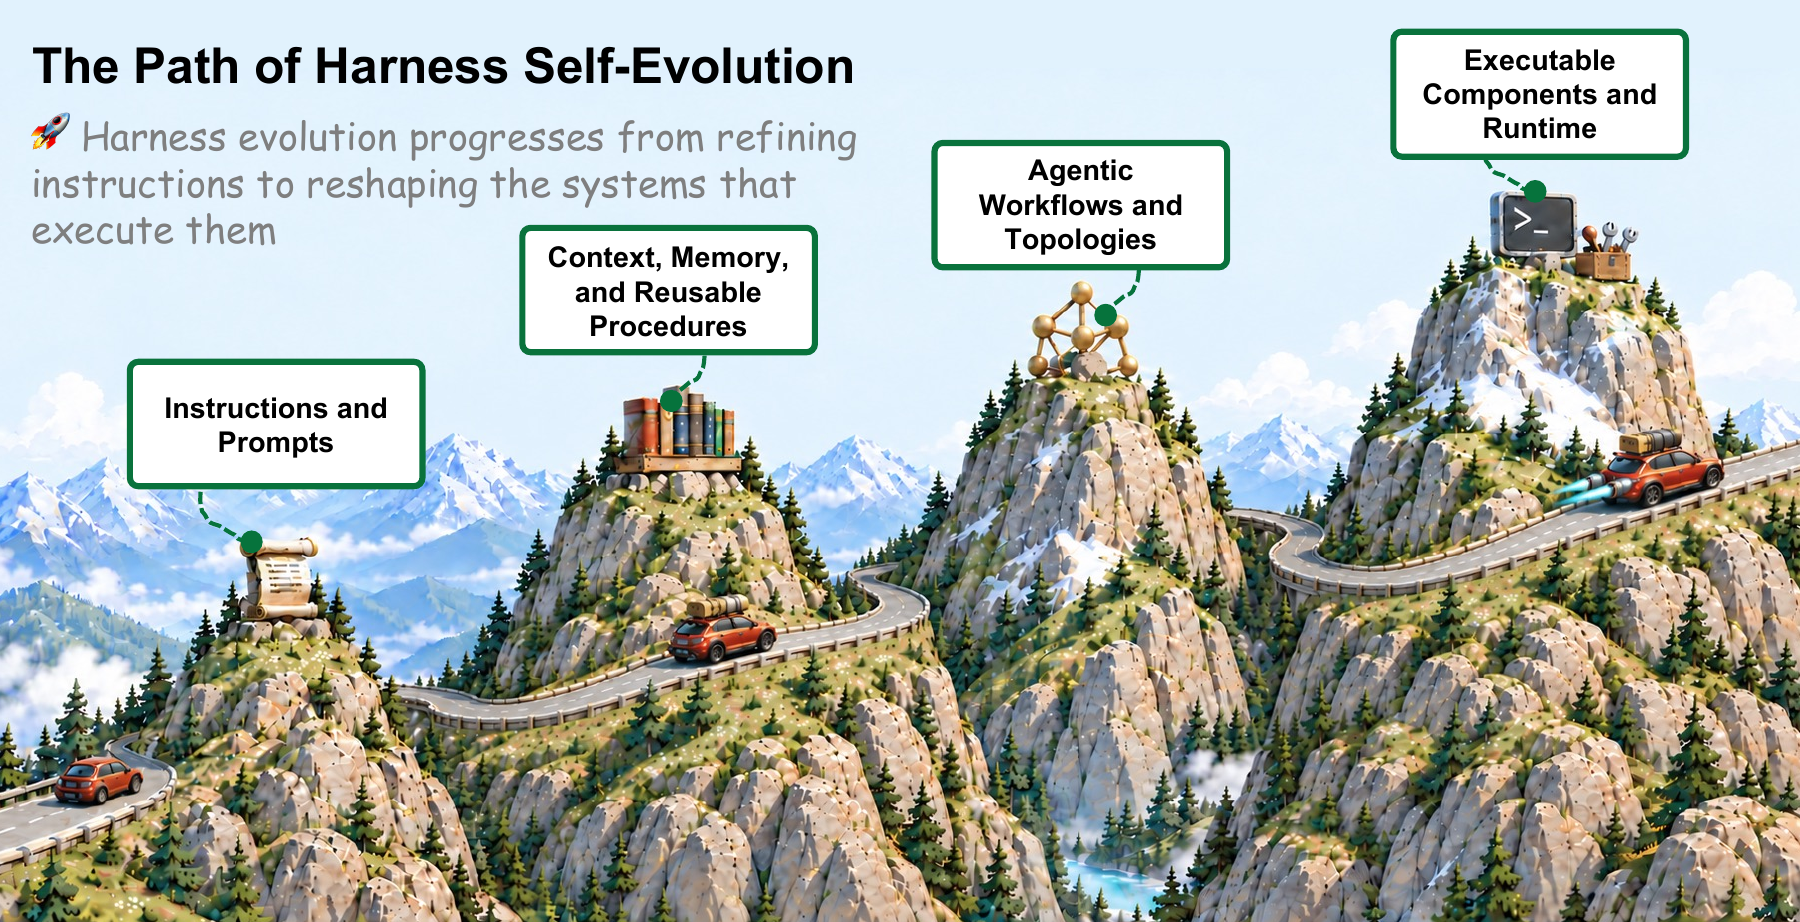
Companion materials for our survey of how execution experience becomes persistent harness state under a fixed base model. The survey covers update mechanisms, evolutionary search, continual PAC learning, evaluation, applications, and societal impact.
PDF downloads: Full report · 66 pages · Short paper · 18 pages.
Reading Guide
Background Related Surveys · Definition · Taxonomy · Precursors
Literature Interpreted · Executable · Theory · Evaluation
Resources Applications & Outlook · Reported Evidence · Contributing · Citation
- A Survey of Self-Evolving Agents
TMLR'26 — organizes self-evolution by what, when, how, and where to evolve. [paper]
- A Comprehensive Survey of Self-Evolving AI Agents
arXiv'25 — organizes methods by optimizer feedback. [paper] [list]
- Externalization in LLM Agents
arXiv'26 — unified review of memory, skills, protocols, and harness engineering. [paper]
- Code as Agent Harness
arXiv'26 — organizes by the role of code in the agent loop. [paper] [list]
- Recursive Self-Improvement in AI
arXiv'26 — from bounded self-refinement to autonomous research loops, organized by loop closure. [paper]
- Self-Improvements in Modern Agentic Systems
arXiv'26 — separates model and scaffold updates under frozen parameters and discusses independent evaluation and component controls. [paper] [list]
- Self-Evolving Coding Agents
arXiv'26 — distinguishes proposal eligibility, runtime activation, and admission, and discusses component controls under a common budget. [paper]
Definition
A harness $H$ is the software and configuration that governs how a model $M$ operates in an environment $E$. It includes tools, context construction, memory, and execution control. The final evaluator $J$ scores a trajectory and stays outside the candidate’s editable surface; internal critics and provisional verifiers may belong to the mutable harness.
$$
\tau \sim \mathrm{Run}(M,H,E), \qquad y=J(\tau)
$$
Harness self-evolution uses a batch of trajectories $\mathcal{B}_k$ to revise the state used by later runs:
$$
H_{k+1}=\mathrm{Update}(H_k,\mathcal{B}_k)
$$
The update mechanism remains available for further revisions, and an accepted state is saved and loaded by a later run. Rejected candidates leave the harness unchanged. The analysis holds $M$ fixed; systems that also train weights are read here for their harness-side changes. Offline optimizers and mechanisms with limited persistence are marked in the entries.
Self-evolution is the process of updating persistent harness state; self-improvement is a beneficial change established through evaluation. Harness RSI is the conventional short name used throughout this resource.
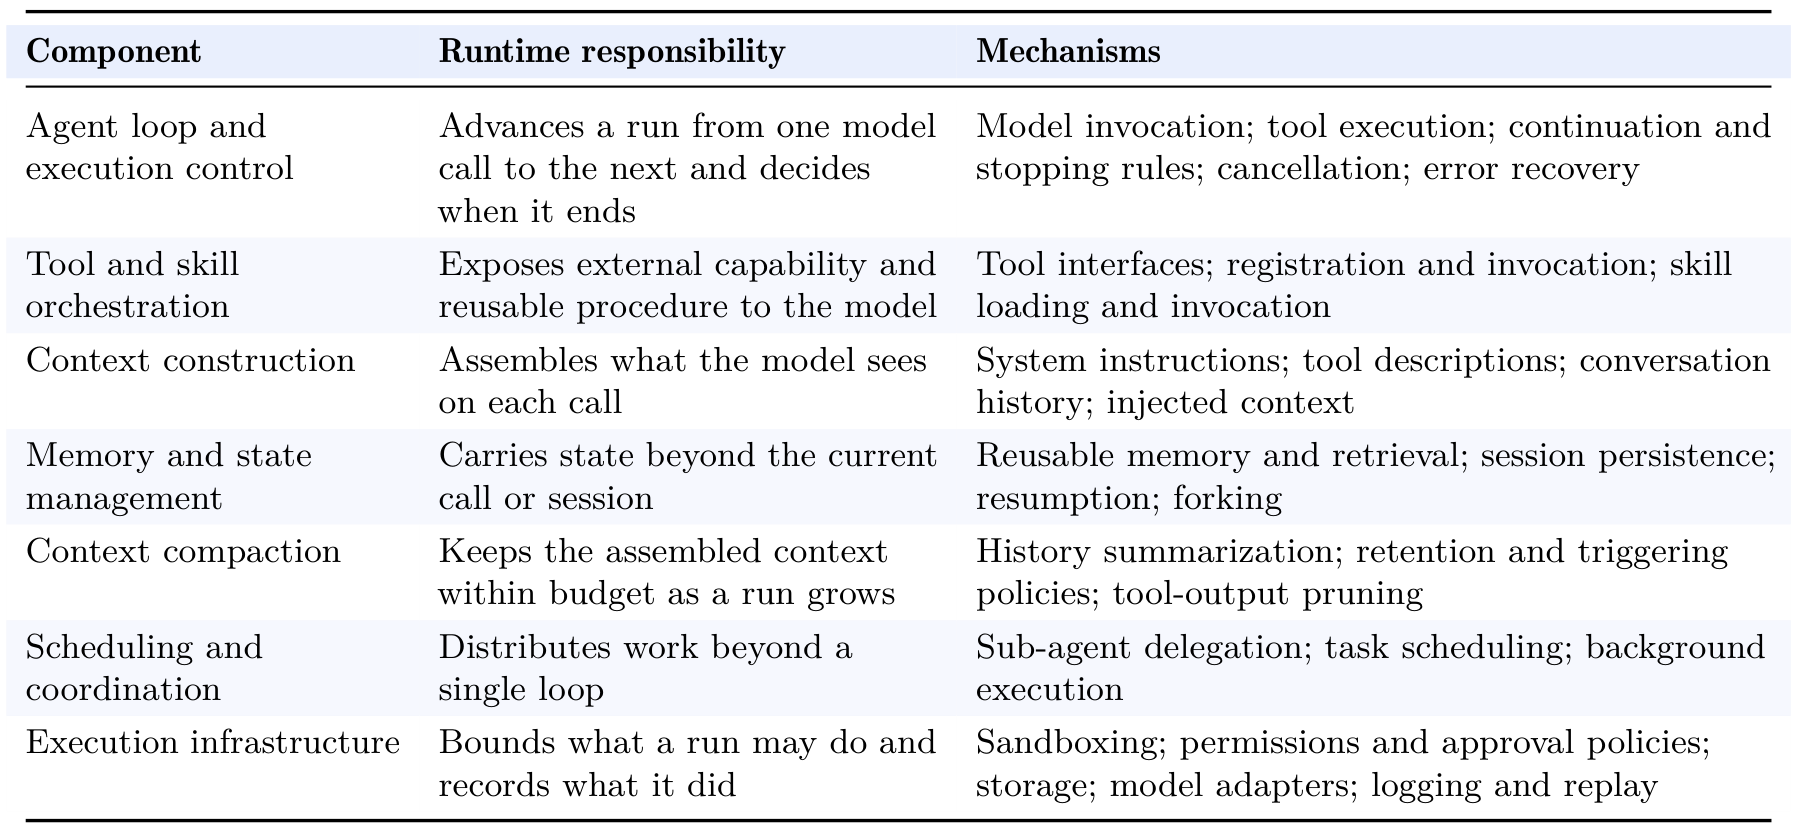
Harness components (paper §2)
Runtime responsibilities and mechanisms. An implementation may combine or omit components.
Taxonomy
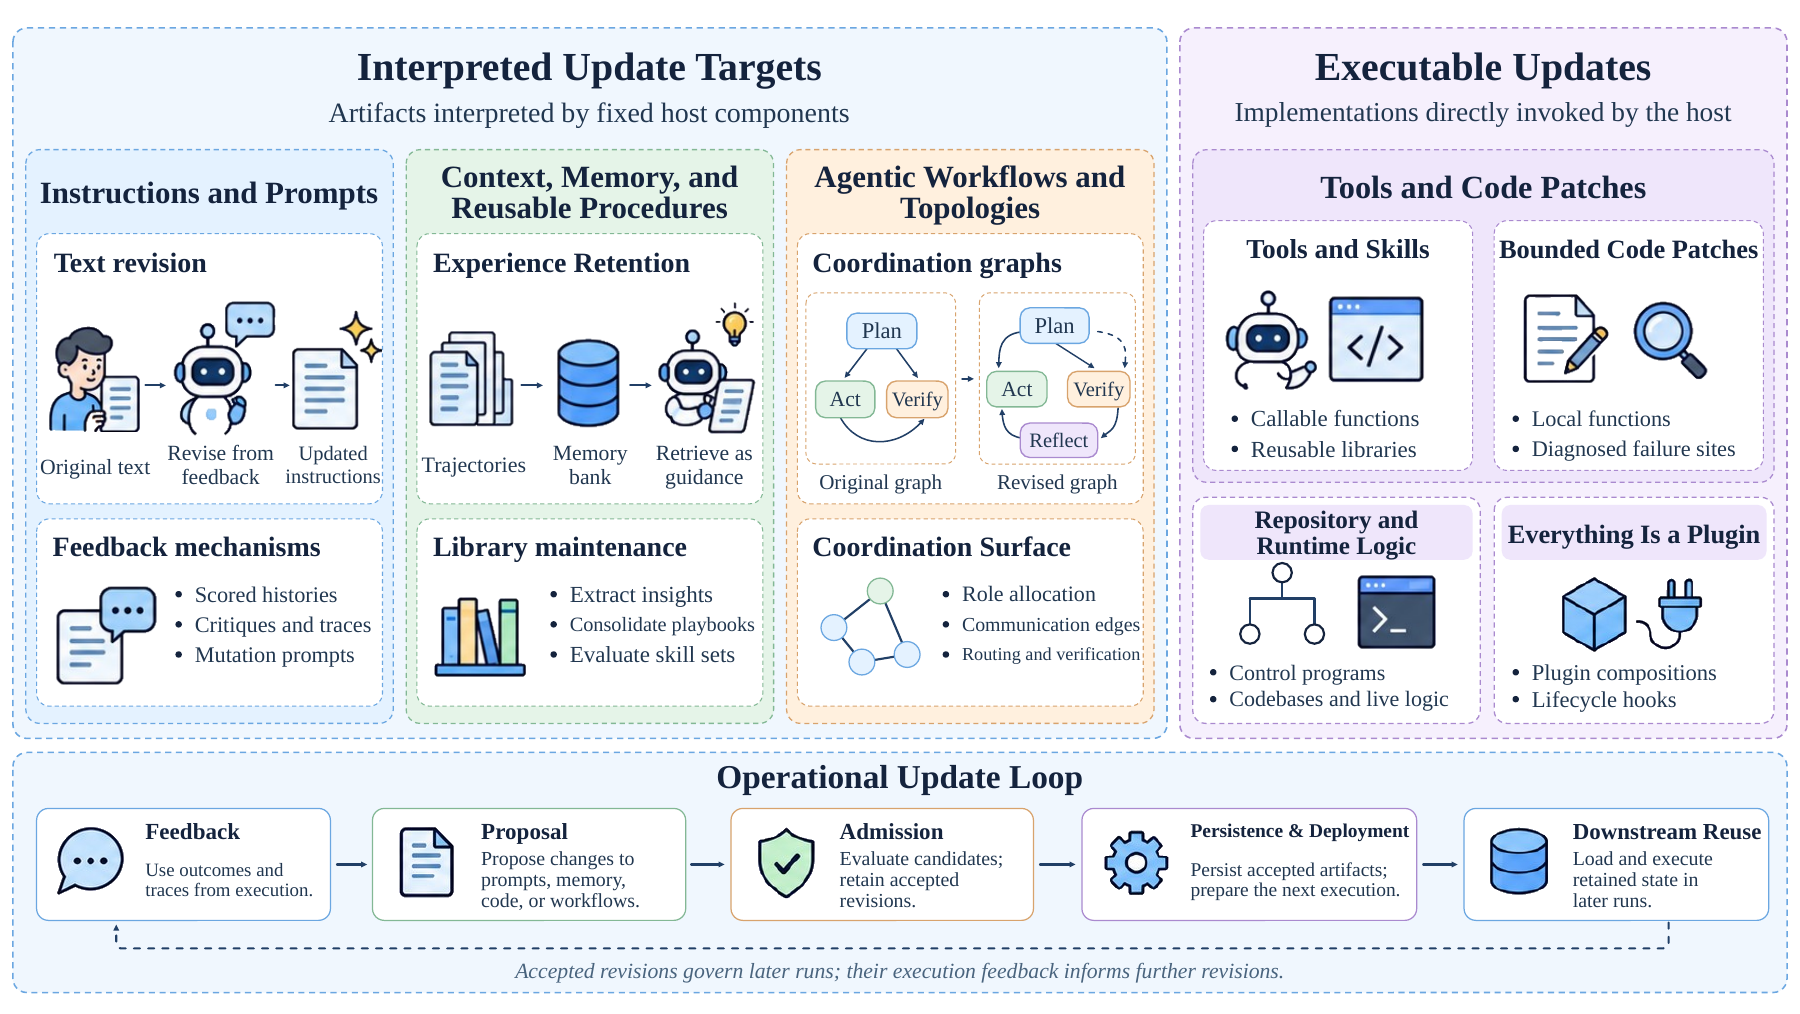
Interpreted updates revise content read by a fixed host; executable updates revise the implementations it invokes. Evaluation forms a separate branch, while theory cuts across update targets.
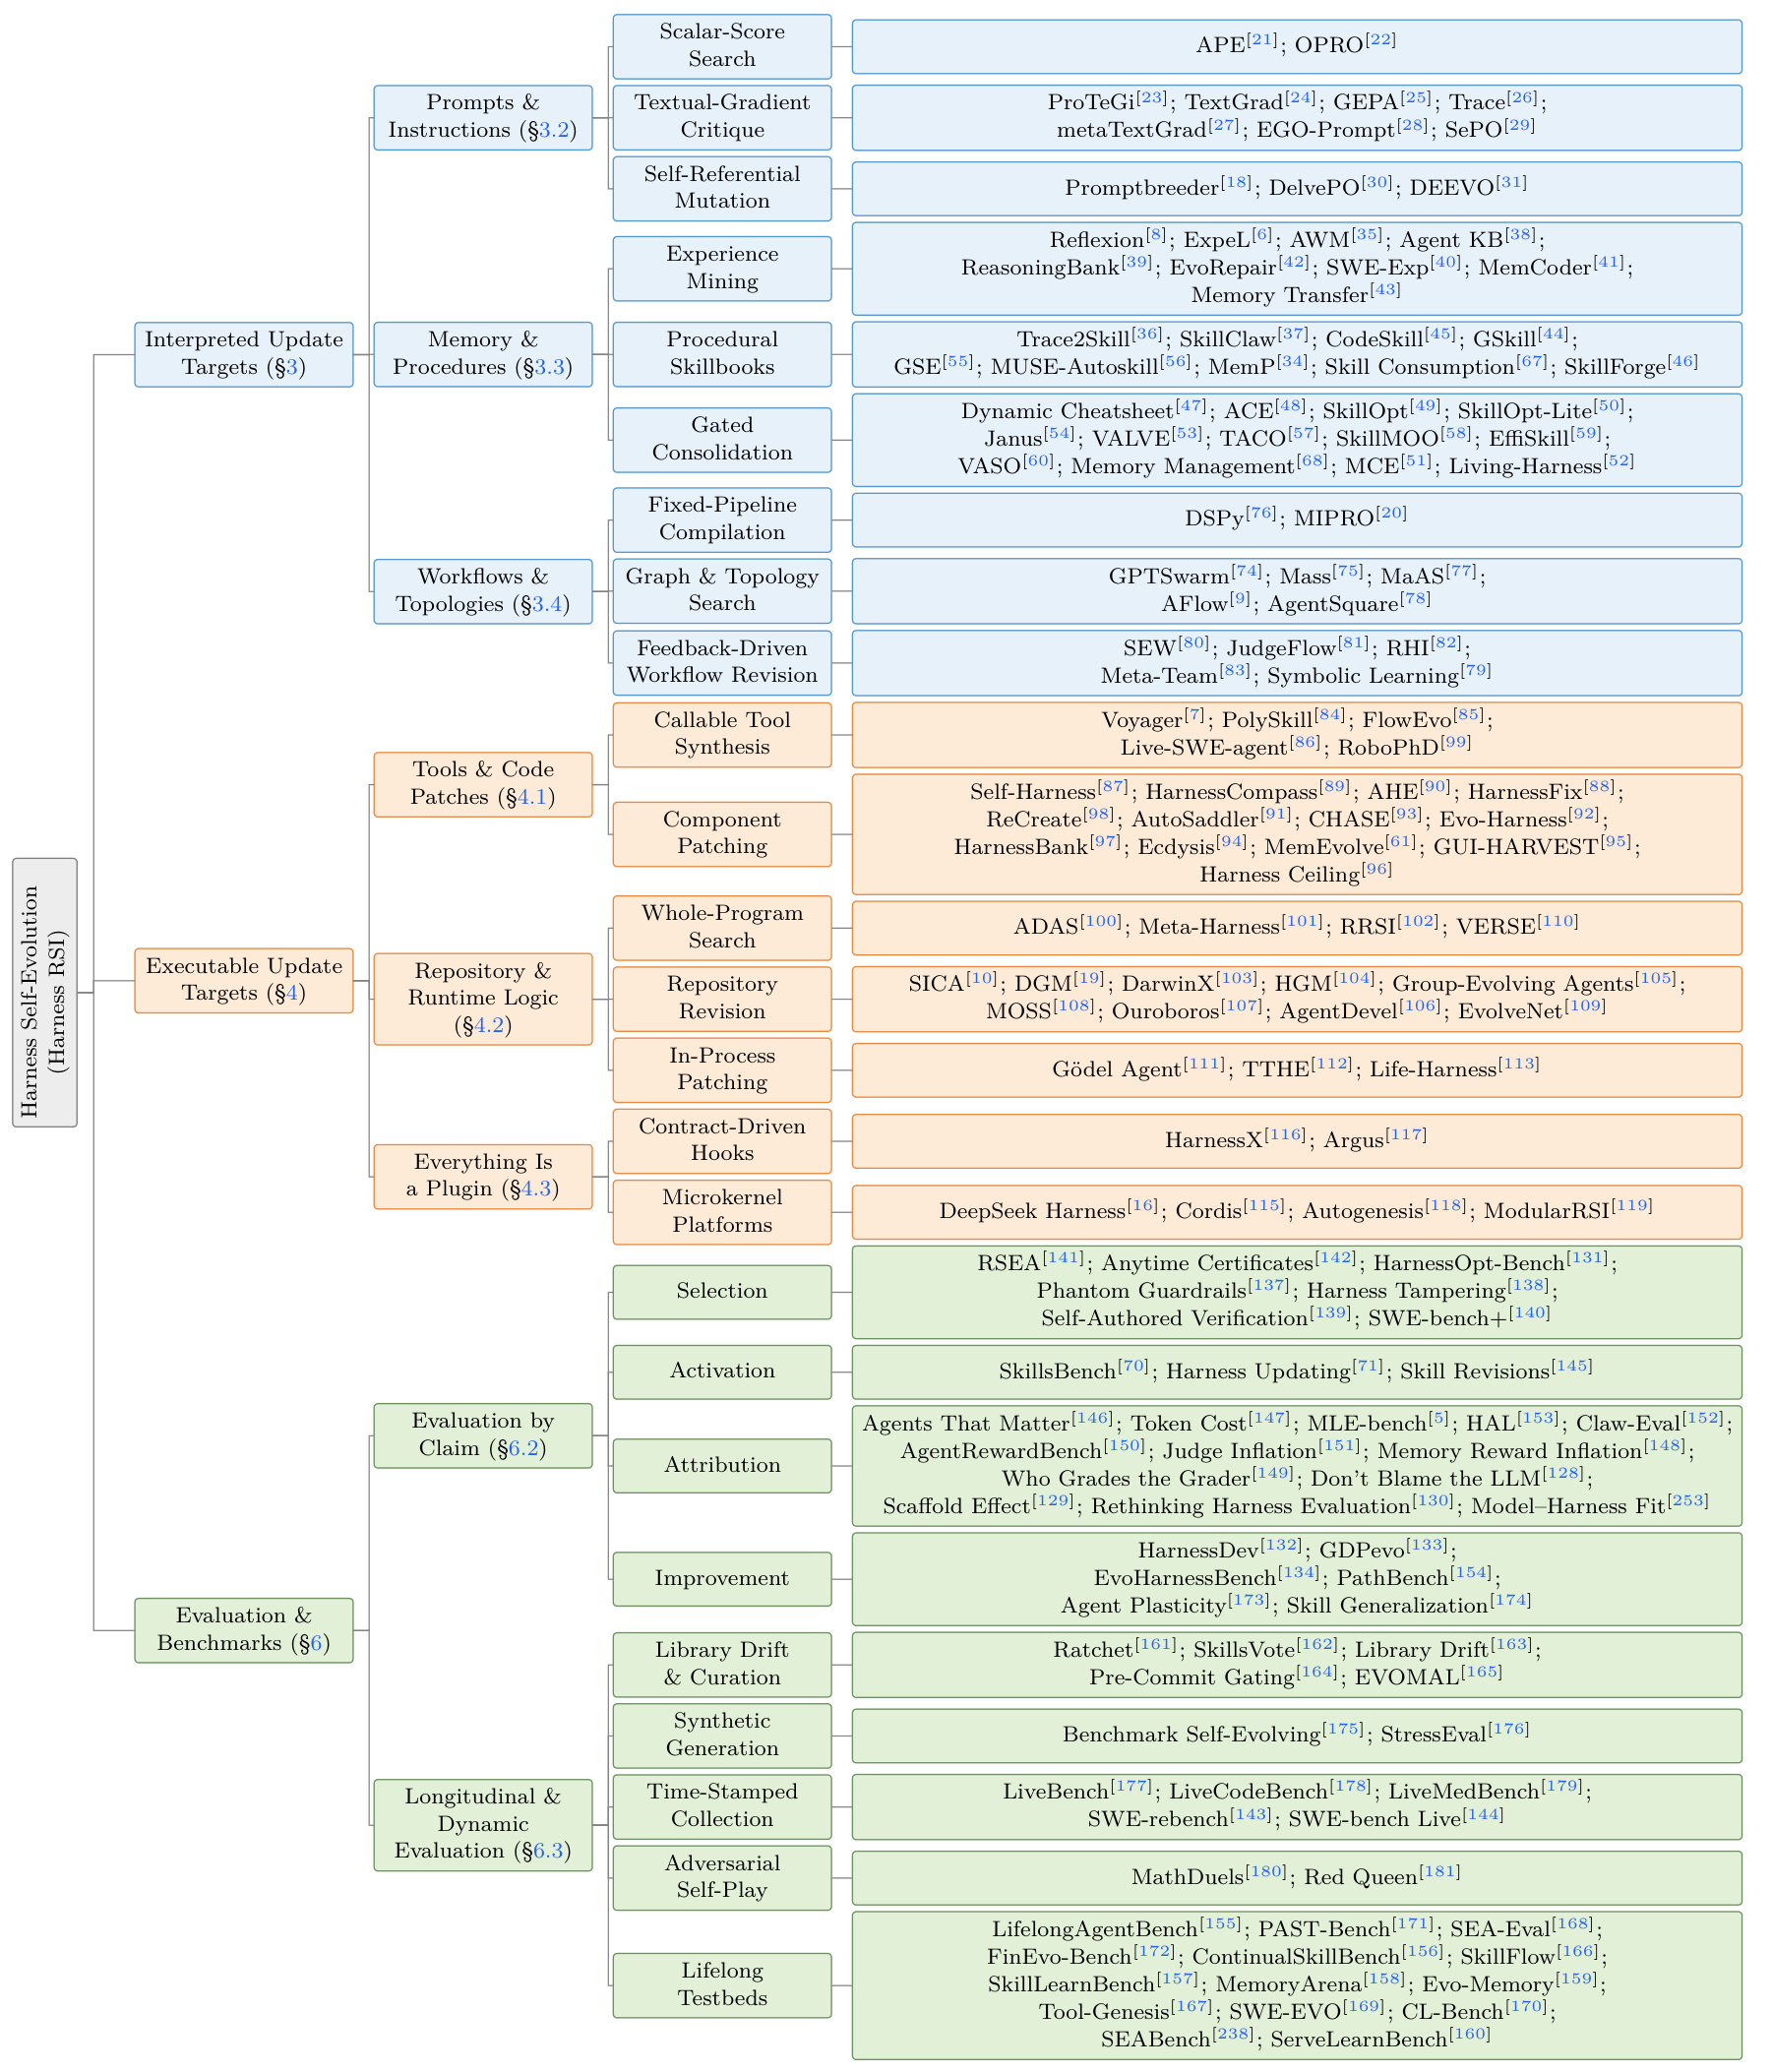
Reference numbers follow the manuscript; source links appear in the reading list below. See also the taxonomy data.
Precursors
- Speculations Concerning the First Ultraintelligent Machine
Adv. Computers'65 — frames recursive improvement as a machine designing a better successor to itself. [paper]
- EURISKO
Artif. Intell.'83 — learned heuristics, including heuristics that modify other heuristics, shape later search. [paper]
- Gödel Machines
arXiv'03 — a self-rewrite executes only after the system proves the rewrite improves expected utility. [paper]
1. Interpreted Update Targets
These methods revise instructions, memory, or coordination specifications read by fixed components. Entries note offline optimization and task-local adaptation where applicable.
1.1 Prompts & Instructions
Scalar-Score Search
Use candidate scores to propose and select prompt revisions.
- APE
ICLR'23 — proposes instructions from input–output demonstrations and keeps the highest-scoring candidate. [paper] [project]
- OPRO
ICLR'24 — feeds earlier instructions and scores to an optimizer model that proposes the next candidate. [paper] [code]
Textual-Gradient Critique
Translate errors, critiques, or execution traces into edits to text parameters.
- ProTeGi
EMNLP'23 — converts task errors into natural-language "gradients" and beam-searches over the edited prompts. [paper]
- TextGrad
Nature'25 — backpropagates textual critiques through a graph of LLM calls to edit any text variable in the system. [paper]
- GEPA
ICLR'26 Oral — uses execution-trace reflection to revise prompts and Pareto selection to retain candidates. [paper]
- Trace
NeurIPS'24 — treats the execution trace as a computation graph and generates edits from rich feedback through a generative optimizer. [paper] [project]
- metaTextGrad
arXiv'25 — optimizes the optimizer's own prompts, accepting an update only when a validation split improves. [paper]
- EGO-Prompt
arXiv'25 — co-adapts the prompt and a semantic causal graph for domain deployments. [paper]
- SePO
arXiv'26 — rewrites persistent system prompts using accumulated task feedback. [paper] [code]
Self-Referential Mutation
Search over the instructions that generate later mutations.
- Promptbreeder
ICML'24 — co-evolves task prompts and the mutation prompts that generate them. [paper]
- DelvePO
arXiv'25 — decouples prompt components and steers mutation along identified directions. [paper]
- DEEVO
arXiv'25 — evolves instructions through structured debates, ranking candidates by Elo tournament. [paper]
1.2 Memory & Reusable Procedures
Experience Mining
Distill execution trajectories into knowledge retrieved by later runs.
- Reflexion
NeurIPS'23 — stores verbal self-reflection on a failure and reloads it for another attempt at the same task. [paper]
- ExpeL
AAAI'24 — extracts cross-task insights from a training pool of trajectories, with add/edit/upvote/downvote curation. [paper]
- AWM
ICML'25 — induces recurring sub-goal workflows from trajectories, offline from a training split or online from the task stream. [paper]
- Agent KB
arXiv'25 — a cross-domain experience base whose top-k retrieved items are injected into later runs. [paper]
- ReasoningBank
ICLR'26 — consolidates reasoning strategies from successes and failures into a bank injected into the system instruction. [paper]
- EvoRepair
arXiv'26 — accumulates, scores, and reuses vulnerability-repair experience across long-horizon repairs. [paper]
- SWE-Exp
arXiv'25 — distills issue-resolution experience from prior search trajectories into a bank queried on new issues. [paper] [code]
- MemCoder
arXiv'26 — structured memory of repository knowledge and repair outcomes that grows alongside the codebase. [paper]
- Memory Transfer
arXiv'26 — measures how memories formed in one domain transfer to another, across four memory formats. [paper]
Procedural Skillbooks
Store an explicit procedure that can guide later tasks.
- Trace2Skill
arXiv'26 — distills execution lessons into skill patches and aggregates them into reusable skill documents; validation-based patch selection is a separate experiment. [paper]
- SkillClaw
arXiv'26 — an agentic evolver whose validator admits a candidate skill only if it beats the deployed pool on validation tasks. [paper]
- CodeSkill
arXiv'26 — learns self-evolving coding skills through preparatory passes that build the bank before deployment. [paper]
- GSkill
ACM AIAS'26 — automatically learns SKILL.md files for coding agents from prior runs. [paper]
- GSE
arXiv'26 — learns globally reusable skills gated by local and replay-driven validation under one-project-held-out splits. [paper]
- MUSE-Autoskill
arXiv'26 — couples skill creation, memory, and management, registering a skill only once it passes its own generated tests. [paper]
- MemP
ACL'26 Findings — distills procedural memory from trajectories and compares update strategies and abstraction granularities. [paper]
- Skill Consumption
arXiv'26 — examines how generated skills affect downstream behavior, including changes to default strategies and explicit use. [paper]
- SkillForge
SIGIR'26 Industry — learns reusable skill documents from execution experience and reserves a later temporal partition for reporting. [paper]
Gated Consolidation
Revise, compress, or replace stored content through a validation or maintenance rule.
- Dynamic Cheatsheet
EACL'26 — maintains an adaptive memo of strategies curated at test time. [paper]
- ACE
ICLR'26 — grows and consolidates an evolving context playbook through incremental delta updates instead of rewrites. [paper]
- SkillOpt
arXiv'26 — evaluates a revised skill set on validation before it replaces the active library. [paper]
- SkillOpt-Lite
arXiv'26 — combines a validation deadband with compilation and smoke tests to admit skill edits at lower cost. [paper] [code]
- Janus
arXiv'26 — wraps an updater and compares old and candidate memories on coverage, boundary, and fresh tasks when a proposal deviates from the recent update direction. [paper]
- VALVE
arXiv'26 — admits skill revisions through paired comparisons on a validation panel and tracks drawdown over a long task stream. [paper]
- TACO
arXiv'26 — compresses observations for terminal agents through a write-back gate and a reward-free retention stopping rule. [paper] [code]
- SkillMOO
arXiv'26 — uses NSGA-II ranking to select skill combinations under competing objectives. [paper]
- EffiSkill
arXiv'26 — mines efficiency skills from verified code pairs, ranking candidates on a public split and reporting on a private one. [paper]
- VASO
arXiv'26 — formally verifiable skills: each plan is model-checked against the skill's specification before it may run. [paper]
- Memory Management
ACL'26 — empirical study of how retention, deletion, and retrieval rules change task outcomes, with a similarity-based adherence measure. [paper]
- MCE
ICML'26 — applies history-informed (1+1) evolution to skills with agentic crossover and a validation archive. [paper]
- Living-Harness
arXiv'26 — an interactive-agent evolver that consolidates retrieved memory into a reusable graph across cycles. [paper] [code]
1.3 Workflows & Topologies
Fixed-Pipeline Compilation
Optimize prompts and demonstrations while keeping the pipeline structure fixed.
- DSPy
ICLR'24 — compiles declarative LM pipelines, optimizing prompts and demonstrations while control flow stays fixed. [paper] [code]
- MIPRO
EMNLP'24 — jointly optimizes instructions and demonstrations across the stages of a multi-stage LM program. [paper] [project]
Graph & Topology Search
Search over connections and coordination among fixed operators.
- GPTSwarm
ICML'24 — makes edges between fixed operations learnable and optimizes the resulting communication graph. [paper] [code]
- Mass
ICLR'26 — jointly searches agent prompts and communication topologies over predefined multi-agent blocks. [paper]
- MaAS
ICML'25 — samples query-dependent architectures from an agentic supernet over predefined operators. [paper]
- AFlow
ICLR'25 — serializes workflows as operator-composing code and searches structure and prompts over it; the operators themselves stay fixed. [paper] [code]
- AgentSquare
ICLR'25 — searches module compositions in a modular design space while also generating new module implementations. [paper] [code]
Feedback-Driven Workflow Revision
Use execution feedback to revise the workflow specification.
- SEW
arXiv'25 — jointly mutates prompts and topology while comparing alternative workflow representations. [paper]
- JudgeFlow
arXiv'26 — uses block-level judge diagnoses to revise sequence, loop, and conditional blocks. [paper]
- RHI
arXiv'26 — applies pairwise feedback to roles, instructions, communication contracts, and interaction hops within one task episode. [paper]
- Meta-Team
arXiv'26 — carries experience across tasks to update a reusable scaffold of agent prompts, teammate profiles, collaboration notes, and shared coordination rules. [paper]
- Symbolic Learning
AI Open'25 — jointly revises pipeline structure, prompts, and tools through back-propagated language loss. [paper]
2. Executable Update Targets
These methods revise tools, component implementations, control programs, or plugins invoked by the host.
Generate reusable programs exposed through a tool interface.
- Voyager
TMLR'24 — turns self-verified programs into a growing skill library retrieved and composed in later tasks. [paper] [project]
- PolySkill
arXiv'25 — induces polymorphic skill abstractions so a learned skill generalizes past its originating site. [paper] [code]
- FlowEvo
arXiv'26 — compiles a successful workflow into a validated callable artifact in a persistent skill bank, then either executes it or describes it to workflow generation. [paper] [code]
- Live-SWE-agent
arXiv'25 — synthesizes Bash and Python tools during a task; the tools are discarded with its container. [paper]
- RoboPhD
arXiv'26 — co-evolves a deterministic Python analysis tool with model-readable SQL instructions, then ships the pair without its evolutionary infrastructure. [paper]
Evidence-Grounded Component Patching
Modify a declared executable component while the enclosing executor stays fixed.
- Self-Harness
arXiv'26 — proposes edits from the incumbent and admits candidates that do not regress on either split and improve on at least one. [paper] [code]
- HarnessCompass
arXiv'26 — optimizes harness components separately and combines them into candidate configurations. [paper]
- AHE
arXiv'26 — uses submit-guard and shell traces to diagnose component edits and supports file-level rollback. [paper]
- HarnessFix
arXiv'26 — diagnoses harness faults from failed trajectories and admits a repair only through a validation-set assessment. [paper]
- ReCreate
ACL'26 — edits role, process, tool, and memory components at text and code level using a small development set. [paper]
- AutoSaddler
arXiv'26 — retains patches that improve a minibatch, selects on development data, and reports on a group-disjoint test split. [paper]
- CHASE
arXiv'26 — tests proposed patches against protocol transformations designed to invalidate their apparent gains. [paper]
- Evo-Harness
arXiv'26 — compiles accumulated context into harness-level skills along an online stream, matching fail→pass traces to skill content. [paper] [code]
- HarnessBank
arXiv'26 — archives component patches by semantic descriptor, checks activation beacons during screening, and keeps evaluation code in an immutable kernel. [paper]
- Ecdysis
arXiv'26 — trains runtime harnesses with promotion on a training objective, then scores the frozen harness on a held-out split. [paper]
- MemEvolve
arXiv'25 — rewrites the encode, store, retrieve, and manage implementations behind a fixed memory-provider interface. [paper]
- GUI-HARVEST
arXiv'26 — turns recurring failures from repeated GUI executions into bounded source edits with stated behavioral predictions. [paper]
- Harness Ceiling
arXiv'26 — compares harness edits on long-horizon planning tasks to identify failures that remain for weight training. [paper]
2.2 Repository & Runtime Logic
Whole-Control-Program Search
Search over the control program; VERSE also revises the optimizer that proposes it.
- ADAS
ICLR'25 — a fixed meta-agent writes new agent forward implementations and keeps evaluated candidates in an archive. [paper] [project]
- Meta-Harness
COLM'26 — uses an external coding agent to generate complete harness programs from earlier candidates’ source, scores, and traces. [paper]
- RRSI
arXiv'26 — regularizes program search using edit budgets, leakage checks, and noise-adjusted admission thresholds. [paper] [code]
- VERSE
arXiv'26 — revises both the executor harness and the optimizer’s prompts, tools, hooks, and notes under execution checks. [paper]
Repository Revision
Edit a versioned harness implementation and retain candidates for further evolution.
- SICA
arXiv'25 — lets the best archived agent revise its own multi-file Python codebase, including tools, subagents, and control flow. [paper]
- DGM
ICLR'26 — branches repository variants into an open-ended archive, with parent selection over performance and novelty. [paper]
- DarwinX
arXiv'26 — evolves repository-level harness candidates through selection, mutation, and recombination. [paper]
- HGM
arXiv'25 — approximates clade-level productivity and allocates lineage-expansion and evaluation budgets by Thompson sampling. [paper] [code]
- Group-Evolving Agents
arXiv'26 — lets selected parents share code patches, tools, and execution experience before producing framework-level patches. [paper]
- MOSS
arXiv'26 — rewrites routing, hooks, state management, and dispatch code, then swaps the container behind a health check plus human authorization. [paper] [code]
- Ouroboros
arXiv'26 — evolves its own core through reviewed commits, with run manifests, seed attestation, and public per-task traces. [paper]
- AgentDevel
arXiv'26 — uses versioned diffs and release-candidate regression tests, recording which tasks each update fixes or breaks. [paper]
- EvolveNet
arXiv'26 — combines harness edits across clients and validates merged patches before broadcasting shared state. [paper]
In-Process Patching
Apply changes to a running process; persistence depends on the system’s save and reload mechanism.
- Gödel Agent
ACL'25 — monkey-patches decision methods, action spaces, and modification routines in Python memory; edits last for the process lifetime. [paper]
- TTHE
arXiv'26 — evolves executable harness programs from traces at test time and carries the selected program into subsequent inputs. [paper]
- Life-Harness
arXiv'26 — adapts environment contracts, action realization, and trajectory regulation together, then freezes the runtime interface for evaluation. [paper] [code]
2.3 Everything Is a Plugin
Additional reading outside the fixed evidence audit: PluginRSI alternates single-plugin mutation with workflow recomposition in an offline search, retaining useful variants in a shared library. Its updates span role and skill instructions as well as tool and memory implementations. [code]
Contract-Driven Hooks
Bind updates to hooks with explicit interfaces and admission checks.
- HarnessX
arXiv'26 — checks hook types, singleton constraints, and smoke tests before acceptance; each edit declares an expected trace feature. Replay, novelty, and structural checks do not guarantee non-decreasing task scores. [paper]
- Argus
arXiv'26 — exposes skills through a general agent runtime and evolves them along long task streams. [paper]
Keep a small host fixed and expose replaceable components through plugin interfaces.
- DeepSeek Harness
Product'26 — provides a Cordis-based runtime with declared dependencies, checkpointing, and replay; the product page reports no empirical self-evolution evaluation. [page]
- Autogenesis
arXiv'26 — a self-evolving agent protocol with an explicit propose–evaluate–commit cycle over lineage and versioning. [paper] [code]
- ModularRSI
arXiv'26 — evolves modules behind a composer and admits updates through a reward-blind gate on externally curated tasks. [paper]
- Cordis / Spatiotemporal Composability
arXiv'26 — the formal calculus behind that kernel; self-evolving harnesses are stated as future work. [paper]
3. Theory
The paper develops two perspectives: optimization and generalization. Many reviewed methods search discrete harness state without gradients; scores support selection while traces and critiques guide proposals. Evolutionary paradigms describe shared search structures, and continual PAC analysis studies generalization, retention, and candidate admission.
3.1 Evolutionary Paradigms
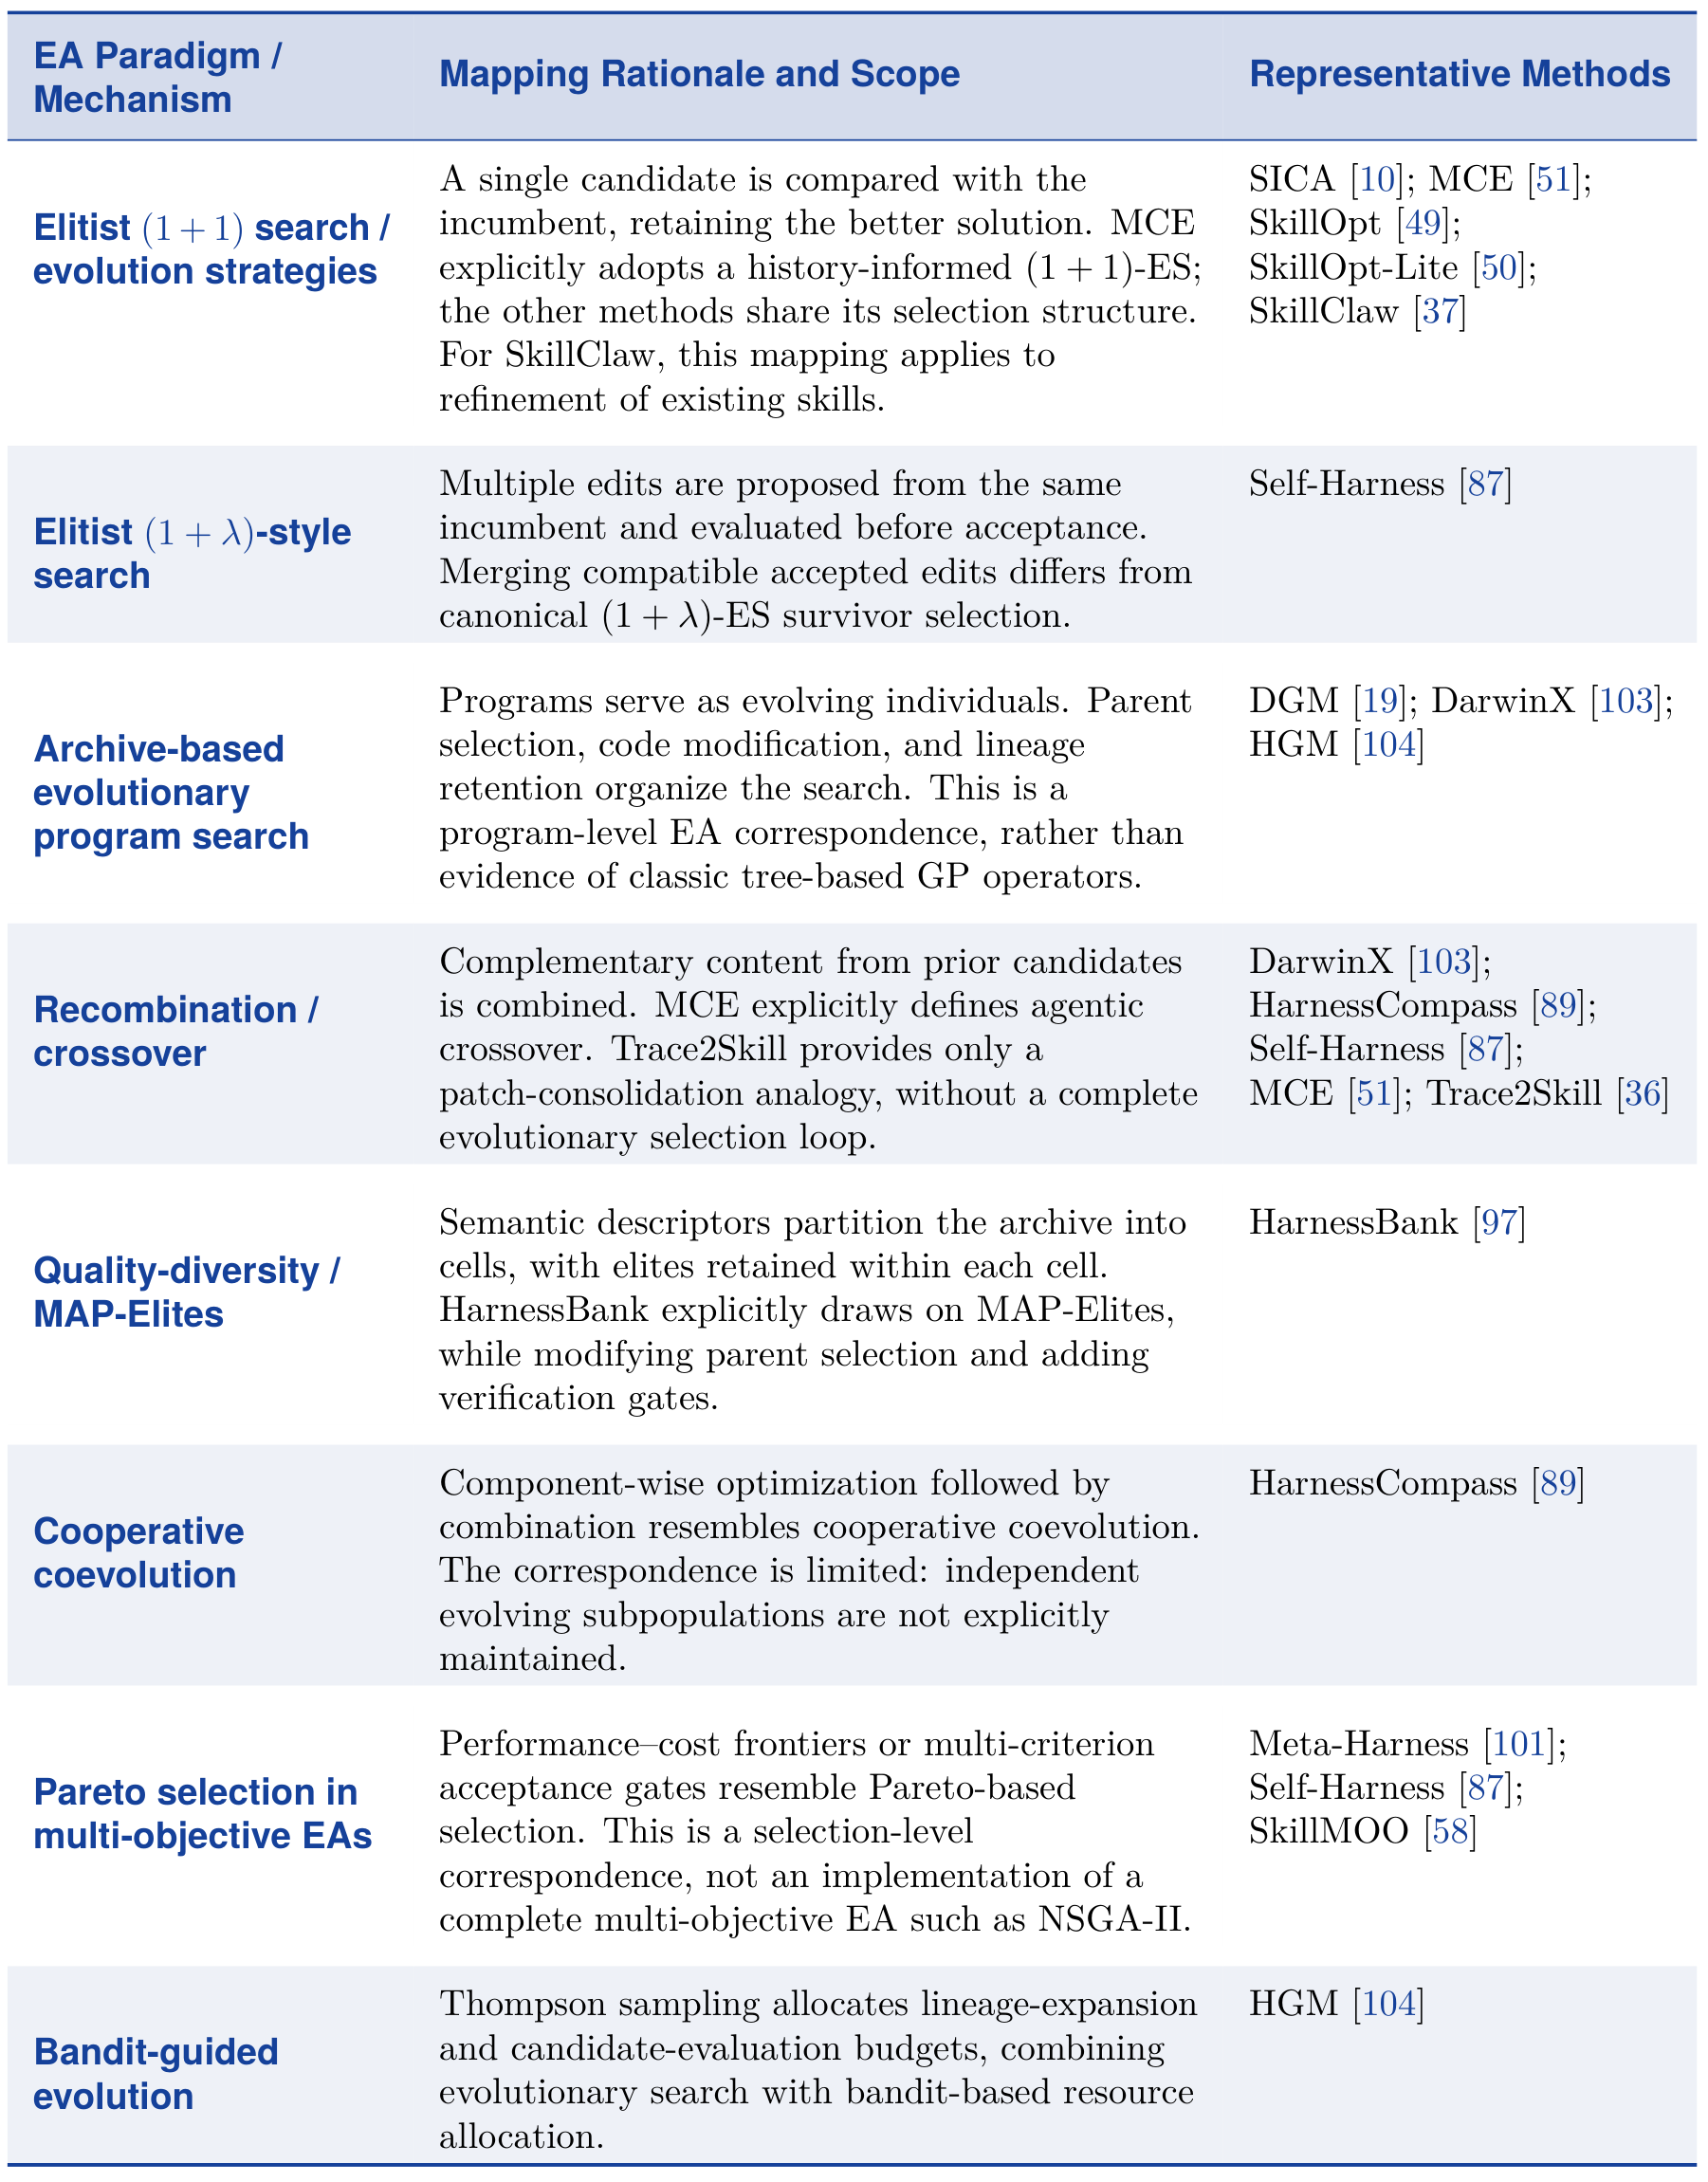
The paper maps variation, selection, archive retention, and budget allocation onto EA paradigms. A method may appear in several rows; each mapping states its scope.
3.2 PAC Learning & Stability
The continual PAC analysis separates sensitivity to training samples, retention of earlier capabilities, and admission of new candidates. It assumes independent exogenous task draws, task losses in $[0,1]$, and a fixed model and evaluator.
For at most $K$ candidates in each of $T$ rounds, compare each candidate with the incumbent on $m$ fresh tasks independent of its construction:
$$
\widehat{\Delta}_k(H') + \sqrt{\frac{2\ln(KT/\delta)}{m}} < 0
$$
Here $\widehat{\Delta}$ is candidate loss minus incumbent loss. Under the stated assumptions, this gate gives joint confidence $1-\delta$ for accepted candidates on their round’s task mixture. It applies to the candidate actually tested, including any merged edits. Repeated rollouts reduce execution noise but do not add independent tasks.
Stability & Retention
- Learnability, Stability and Uniform Convergence
JMLR'10 — relates an algorithm's sensitivity to individual observations to its generalization gap. [paper]
- Memory Bounds for Continual Learning
FOCS'22 — lower bounds on the memory a continual learner needs, motivating generalization and retention as one joint question. [paper]
Confidence-Gated Admission
- Hoeffding Bounds
JASA'63 — bounds deviations of bounded empirical losses for paired candidate admission. [paper]
- Selection Overfitting
JMLR'10 — analyzes overfitting in model selection and its bias in reported performance. [paper]
- The Reusable Holdout
Science'15 — preserves validity of a holdout reused across adaptive, data-dependent decisions. [paper] · [companion]
- SkillForge
SIGIR'26 Industry — learns reusable skill documents from execution experience and reserves a later temporal partition for reporting. [paper]
Self-Improvement Limits
- Harness Evolution as Learning
arXiv'26 — approximation, generalization, and optimization limits of self-improving personal agents. [paper]
- A Theory of Reliable Self-Evolution
arXiv'26 — derives adoption conditions whose ceiling depends on verification and evaluation cost. [paper]
- The Ladder
ICML'15 — a leaderboard mechanism that stays reliable under repeated adaptive submissions. [paper]
- Train Faster, Generalize Better
ICML'16 — stability of SGD as a route to generalization bounds. [paper]
- PAC-Bayes for Prompts
arXiv'23 — prompt engineering may not require rethinking generalization. [paper]
- ZOPO
arXiv'24 — localized zeroth-order prompt optimization. [paper]
- Statistical Limits
TMLR'26 — statistical limits of self-improving agents. [paper]
- AdaEvolve
arXiv'26 — adaptive LLM-driven zeroth-order optimization. [paper]
- GAMBLe
arXiv'26 — an analytical framework for AI-driven research systems. [paper]
- Mutation Without Variation
GECCO'26 — convergence dynamics in LLM-driven program evolution. [paper] [code]
- What Fits Doesn't Overfit
arXiv'26 — compression and generalization in ML research agents. [paper]
- IMABO
arXiv'26 — bandit hyperparameter optimization at inference time. [paper] [code]
4. Evaluation & Benchmarks
The evaluation framework connects Selection, Activation, Attribution, and Improvement to the evidence supporting each reported comparison.
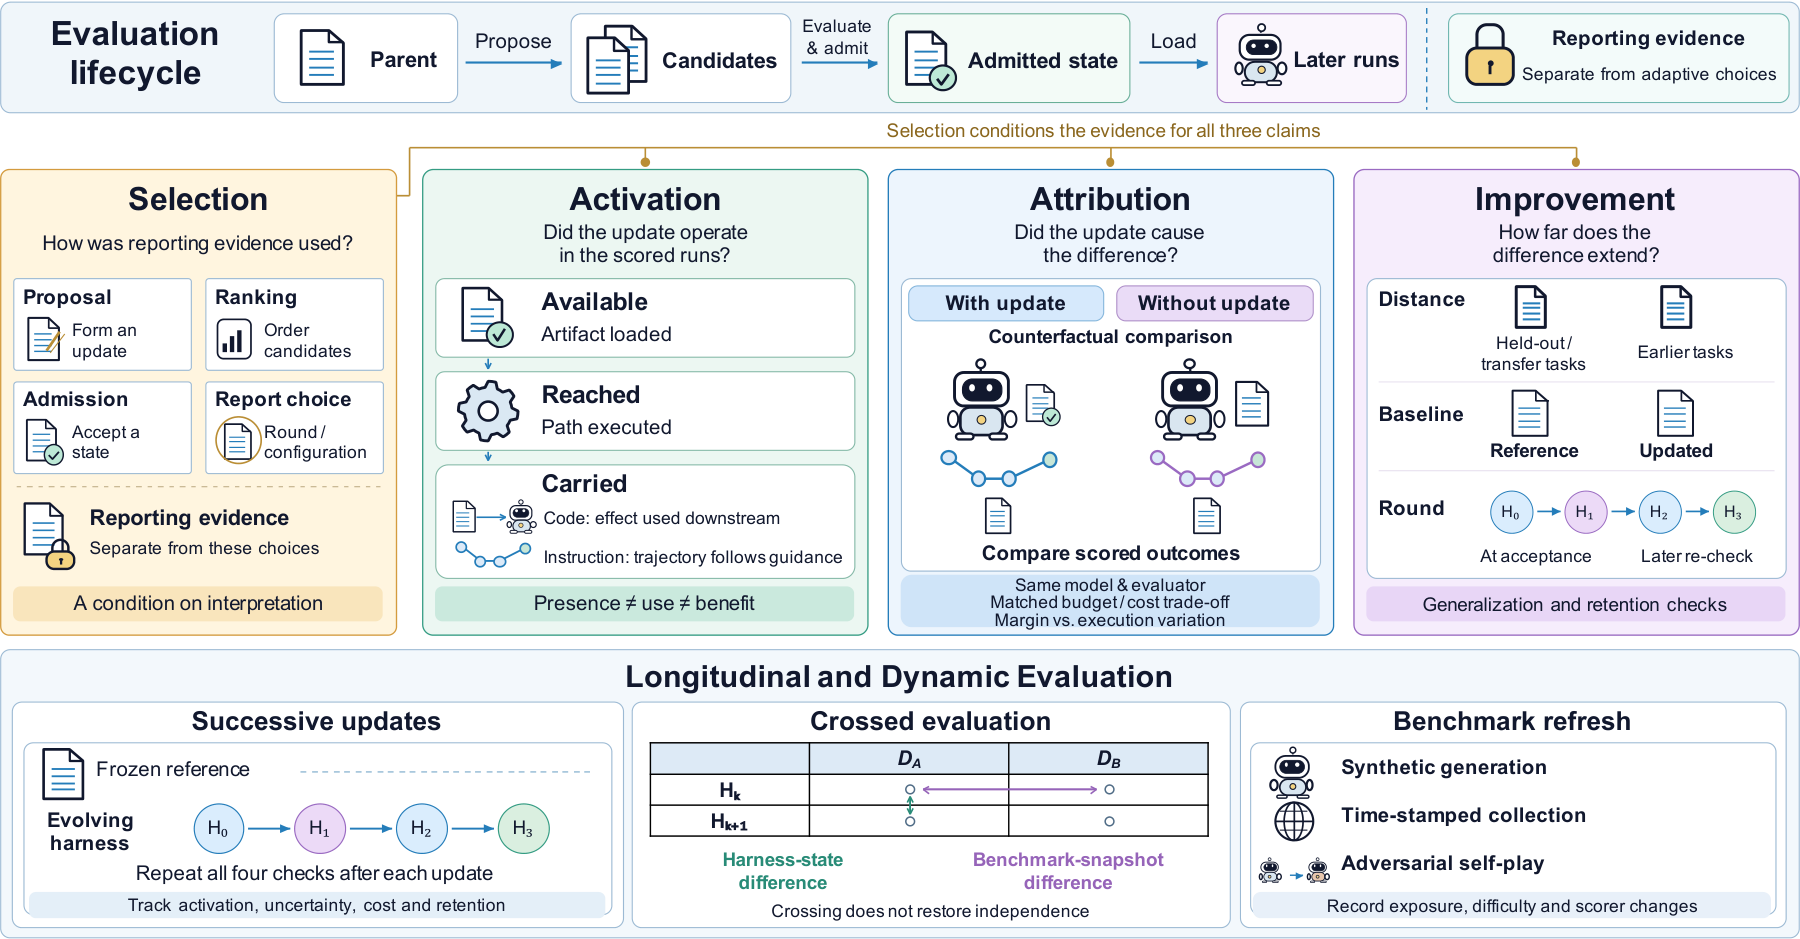
Activation distinguishes an artifact being available, its changed path being reached, and its effect being carried into subsequent execution. See the criteria for evidentiary requirements and coverage.
The Improvement criterion records how reporting tasks relate to those that formed the update. Selection and Attribution assess the reliability and source of the observed gain.
4.1 Claim-Specific Evidence
Selection & Oracle Integrity
Separate reporting evidence from the update process and protect the scorer from candidate edits.
- RSEA
arXiv'26 — assigns separate data to proposal, admission, and reporting. [paper]
- Anytime Certificates
arXiv'26 — anytime-valid certificates for repeated, data-dependent admission decisions. [paper]
- HarnessOpt-Bench
arXiv'26 — keeps its test partition out of reach for the whole search, with the boundary enforced by the runtime, and meters the resources the target agent spends. [paper]
- Phantom Guardrails
arXiv'26 — documents self-improving harnesses that fix failures which never occurred, the patch grounded in no observed execution. [paper]
- Harness Tampering
arXiv'26 — examines candidates that modify verification logic rather than the behavior under test. [paper]
- Self-Authored Verification
arXiv'26 — finds self-written checks unreliable as admission evidence in heuristic self-improving agents. [paper]
- SWE-bench+
arXiv'24 — documents solution leakage and weak assertions that corrupt promotion and reporting together. [paper]
Runtime Activation
Record whether the accepted artifact operated in the runs that produced the result.
- SkillsBench
arXiv'26 — records whether task-provided skills are read or referenced, across diverse tasks. [paper]
- Harness Updating ≠ Harness Benefit
arXiv'26 — measures skill loading separately from trajectory adherence to identify updates that are available but not followed. [paper] [code]
- Skill Revisions
arXiv'26 — tests whether revisions to a skill change coding-agent behavior when the skill is loaded on demand. [paper]
Attribution Controls
Separate the effect of the update from execution variation, inference compute, and evaluator changes.
- Agents That Matter
TMLR'25 — shows agent comparisons confound capability with cost, and asks for cost-controlled evaluation. [paper]
- Token Cost
arXiv'26 — analyzes and predicts token consumption in agent runs. [paper]
- MLE-bench
ICLR'25 — ML-engineering tasks with repeated runs and an explicit compute envelope. [paper]
- HAL
ICLR'26 — standardized run records, model snapshots, and cost accounting as shared evaluation infrastructure. [paper]
- Claw-Eval
arXiv'26 — scores trajectories and repeats trials to estimate execution variation. [paper]
- AgentRewardBench
COLM'25 — meta-evaluates automatic judges of web-agent trajectories against expert annotation. [paper] [project]
- Judge Inflation
arXiv'24 — documents spontaneous reward hacking in iterative self-refinement. [paper]
- Memory Reward Inflation
arXiv'26 — shows stored memory can inflate the reported reward rather than improve the behavior. [paper]
- Who Grades the Grader
arXiv'26 — examines evaluator drift when metrics and skills evolve together. [paper] [code]
- Don't Blame the LLM
arXiv'26 — attributes measured coding-agent differences to harness evolution rather than to the model. [paper]
- Scaffold Effect
arXiv'26 — treats harness choice as a hidden variable in coding-agent comparisons. [paper]
- Rethinking Harness Evaluation
arXiv'26 — examines protocol confounds in reported harness-evolution gains. [paper]
- Model–Harness Fit
arXiv'26 — compares model–harness combinations across agent tasks to identify interaction effects. [paper]
- Compositional Safety Failures
arXiv'26 — compares individual and combined component updates to identify safety failures, with hypergraph-guided runtime monitoring. [paper]
Generalization & Retention
Test on held-out tasks, new settings, or earlier distributions.
- HarnessDev
arXiv'26 — separates harness creation from iterative evolution, reporting capability, cost, and held-out transfer. [paper]
- GDPevo
arXiv'26 — evaluates evolved harnesses on held-out business tasks constructed by recombining rules from training tasks. [paper] [code]
- EvoHarnessBench
arXiv'26 — grows the harness an agent is given and measures whether earlier competence is retained as capabilities are added. [paper]
- PATH-Bench
arXiv'26 — path-dependent evaluation: deliberately varied task order and retained frozen reference histories. [paper]
- Agent Plasticity
arXiv'26 — measures how execution experience translates into held-out gains and examines failures to reuse artifacts. [paper]
- Skill Generalization
arXiv'26 — compares evolved skills on training and held-out tasks to measure how much improvement transfers. [paper]
4.2 Longitudinal & Dynamic Evidence
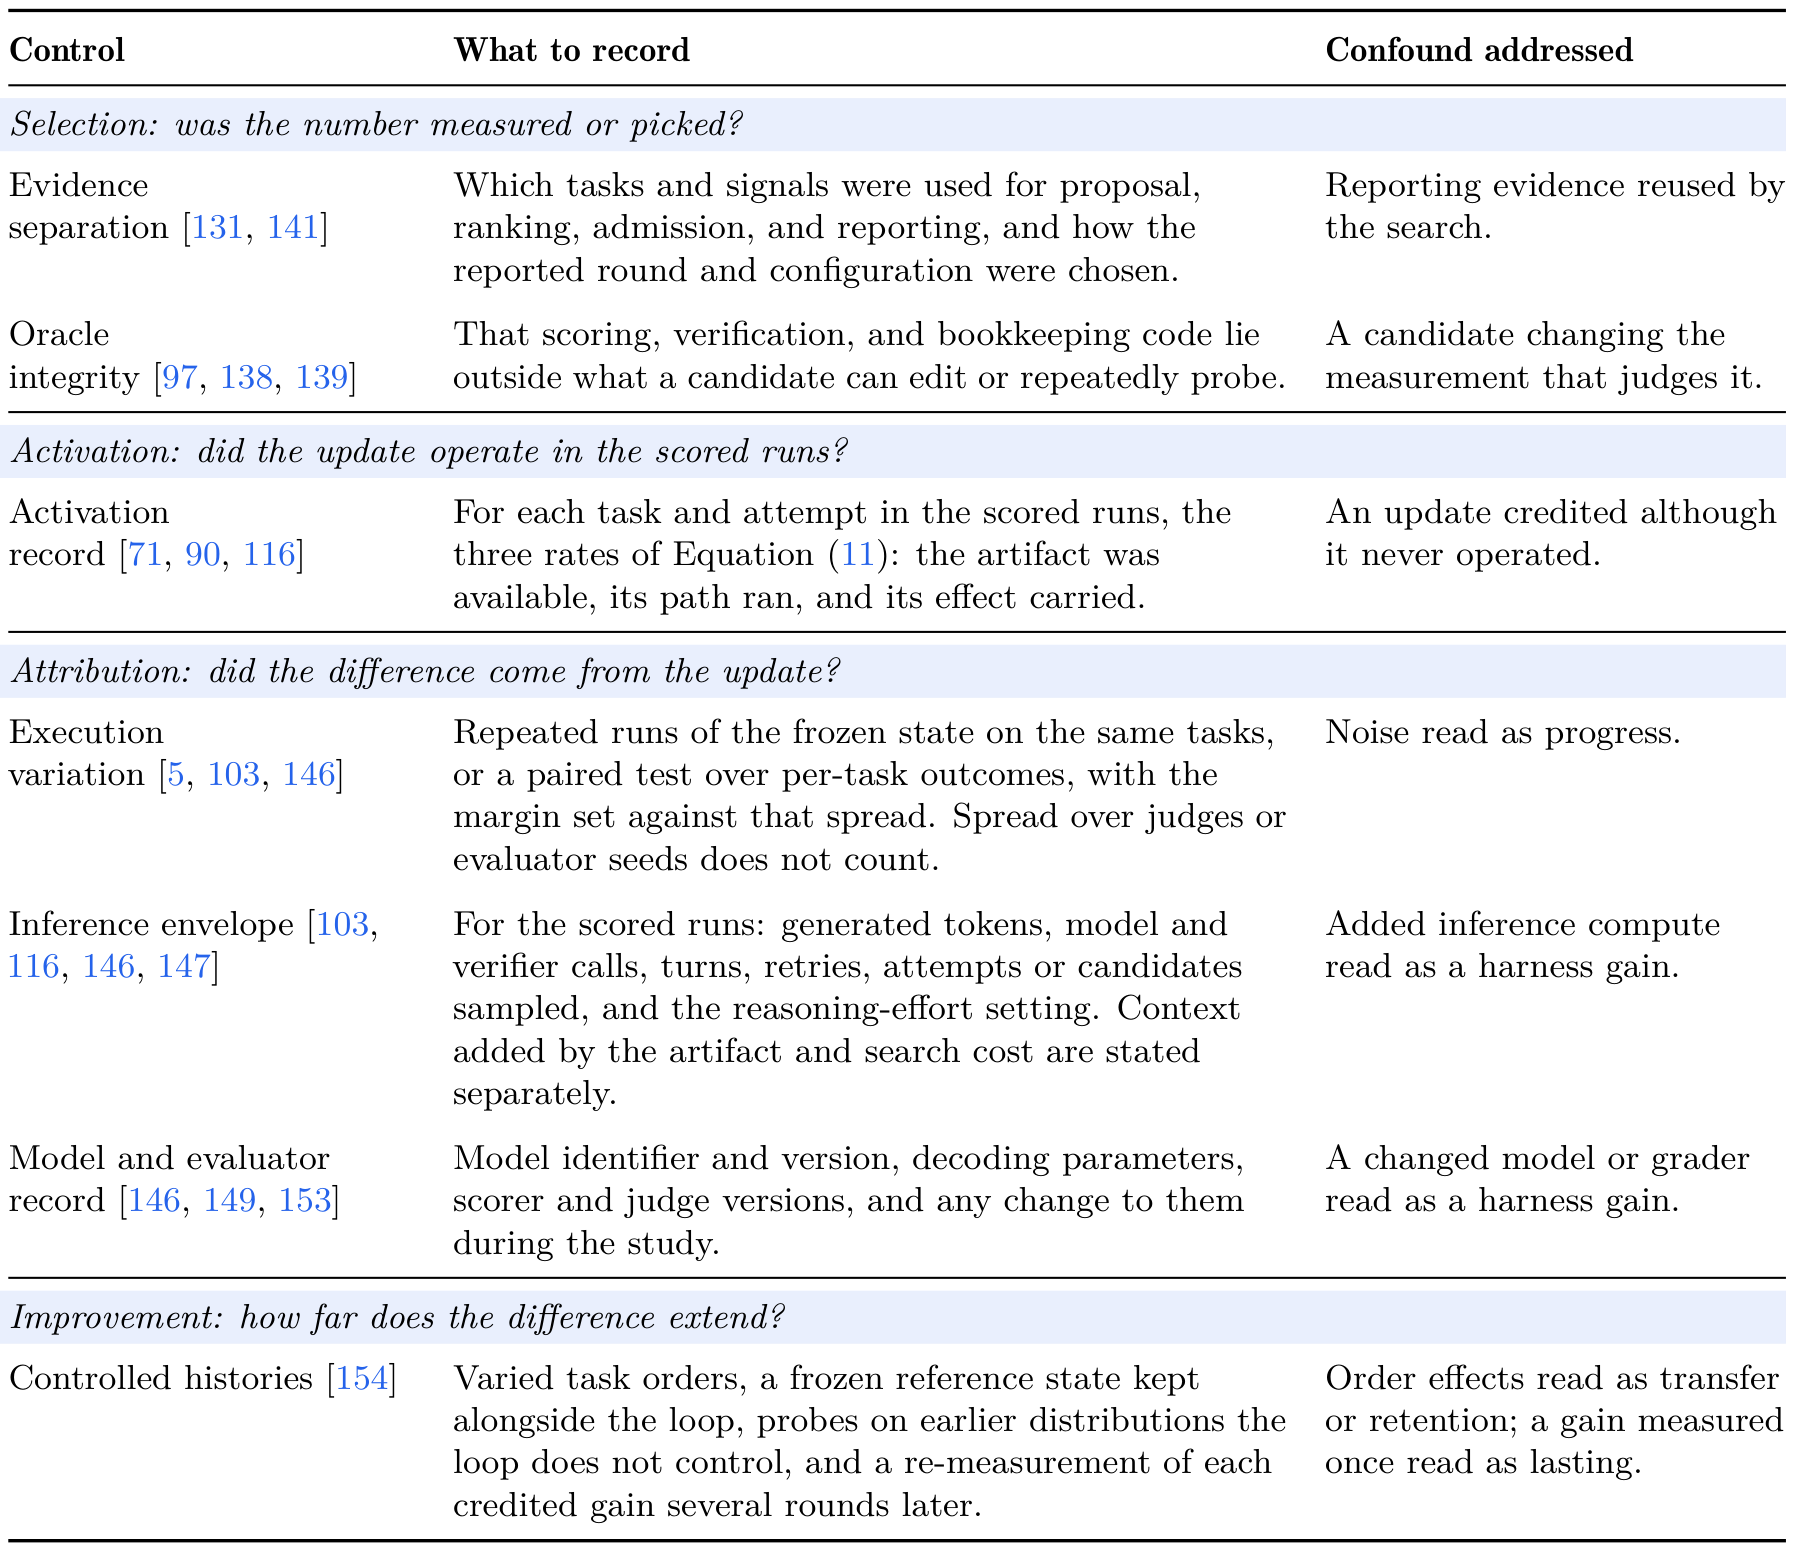
Controls for successive updates (paper §6.3)
Successive updates require state and evaluator records, execution variation, inference budgets, and historical task performance. The table connects each control with its confound.
Active-Set Integrity
Track which stored artifacts remain reachable and used after later updates.
- Ratchet
arXiv'26 — asks how reliable an LLM judge must be before a skill may be retired. [paper] [code]
- SkillsVote
arXiv'26 — lifecycle governance of skills across collection, recommendation, and voting-based curation. [paper]
- Library Drift
arXiv'26 — diagnoses and fixes silent drift in a growing self-evolving skill library. [paper] [code]
- Pre-Commit Gating
arXiv'26 — checks proposed skill changes before commit to prevent contamination. [paper]
- EVOMAL
arXiv'26 — documents self-poisoning in self-evolving coding agents. [paper]
Synthesized Boundary Tasks
Construct new tasks while recording overlap with the feedback used to form updates.
- Benchmark Self-Evolving
arXiv'24 — a multi-agent framework that derives new instances from existing ones for dynamic evaluation. [paper] [code]
- StressEval
arXiv'26 — failure-driven dynamic benchmarking that generates instances from diagnosed failures. [paper]
Temporal Streams
Use tasks released after a cutoff and account for changes in difficulty and content.
- LiveBench
ICLR'25 Spotlight — contamination-limited benchmark refreshed from post-cutoff sources with objective ground truth. [paper]
- LiveCodeBench
arXiv'24 — time-stamped competitive-programming problems collected after a cutoff. [paper] [project]
- LiveMedBench
arXiv'26 — contamination-free medical benchmark with automated refresh. [paper]
- SWE-rebench
arXiv'25 — automated pipeline for task collection and decontaminated evaluation. [paper] [project]
- SWE-bench Live
arXiv'25 — continuously refreshed SWE-bench built from freshly merged issues. [paper] [project]
Adversarial Play
Report changes to the agent, task generator, and evaluator separately.
- MathDuels
COLM'26 — a self-play benchmark that grows with the participant pool. [paper]
- Red Queen Gödel Machine
arXiv'26 — co-evolves agents and their evaluators in one loop. [paper]
Lifelong Testbeds
Evaluate sequential tasks together with the state carried between them.
- LifelongAgentBench
arXiv'25 — evaluates agents as lifelong learners over skill-dependent task sequences. [paper] [project]
- PAST-Bench
arXiv'26 — benchmarks RSI foundations in personal agents, comparing persistence enabled against disabled. [paper] [code]
- SEA-Eval
arXiv'26 — evaluates self-evolving agents beyond isolated episodes. [paper]
- FinEvo-Bench
arXiv'26 — longitudinal professional-finance benchmark with matched persistence-on/off conditions. [paper]
- ContinualSkillBench
arXiv'26 — measures skill development over a continual task stream. [paper]
- SkillFlow
arXiv'26 — benchmarks lifelong skill discovery and evolution. [paper]
- SkillLearnBench
arXiv'26 — benchmarks continual-learning methods for agent skill generation. [paper] [code]
- MemoryArena
arXiv'26 — interdependent multi-session tasks in which earlier writes affect later work. [paper]
- Evo-Memory
arXiv'25 — benchmarks test-time learning with self-evolving memory. [paper]
- Tool-Genesis
arXiv'26 — task-driven tool-creation benchmark for self-evolving agents. [paper]
- SWE-EVO
arXiv'25 — long-horizon software-evolution scenarios for coding agents. [paper]
- CL-Bench
arXiv'26 — frontier systems in real-world stateful continual-learning settings. [paper]
- SEABench
arXiv'26 — benchmarks endogenous misalignment in self-evolving agents. [paper]
- ServeLearnBench
arXiv'26 — streams environments with changing undisclosed rules to evaluate learning from serving experience. [paper]
5. Reported Evidence
Evidence for the four claims across 93 primary reported comparisons; 2 methods without empirical evaluation are excluded.
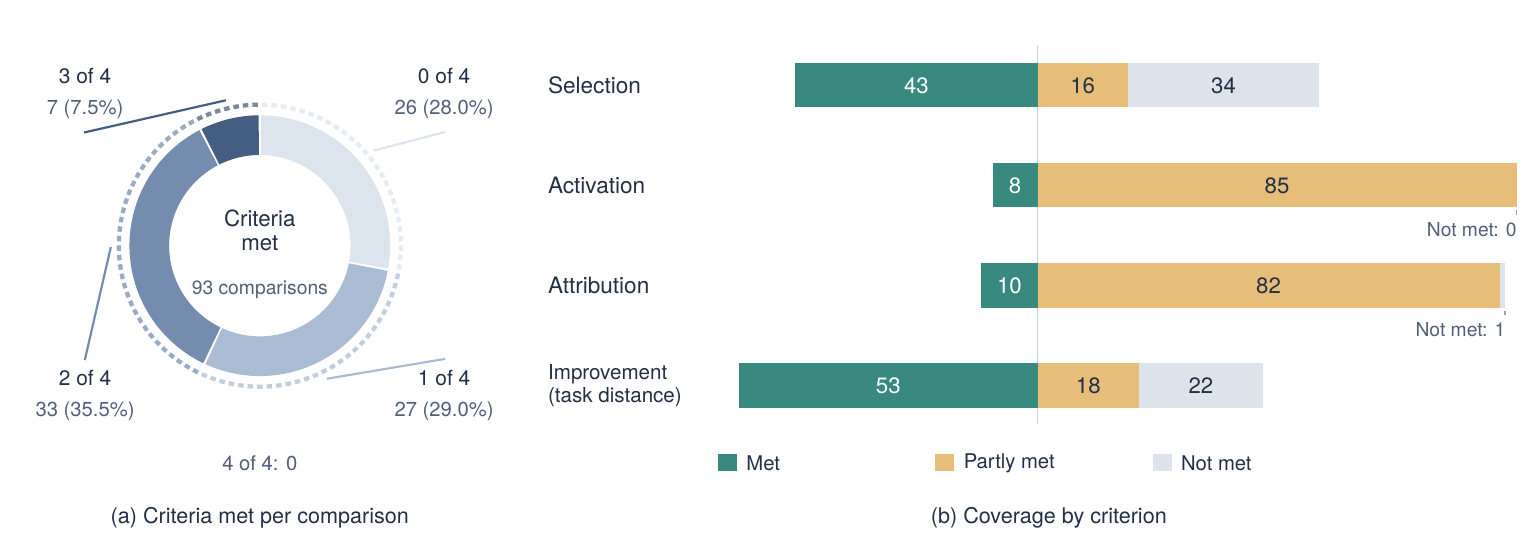
The most common evidence profile meets Selection and task distance, with partial Activation and Attribution: reports often evaluate on held-out tasks, but less often confirm that accepted updates execute in scored runs or separate their effects from run variation and extra inference compute.
See the full results for comparisons, judgments, and sources, and the criteria for their definitions.
6. Applications and Outlook
The survey examines personal assistance and developer workspaces, enterprise automation, scientific discovery, robotics, and public or clinical services. Harness state can preserve preferences, shared procedures, research know-how, and executable skills. These settings differ in what an update changes, how far it travels, and how its effects can be checked.
Persistent and shareable artifacts also affect work and learning, control over accumulated knowledge, privacy, security, and institutional accountability. Open questions include model–harness–environment co-evolution, optimization over heterogeneous artifacts, compositional program contracts, reusable state, dynamic evaluation, and authorization boundaries. See the application map and societal-impact map, with the full discussion in Sections 7–9 of the paper.
Examples include runtime capability bindings in DSH Everything, clinically prioritized tool admission in MedRSI, and practice-environment design in EnvHarness.
The short paper presents cases on model–harness pairing, plugin reuse, and distributed execution.
Contributing
See CONTRIBUTING.md for adding papers, correcting evidence, and rebuilding the site. Keep English and Chinese entries synchronized.
Bibliographies: full report · short paper.
Citation
Please cite the version you use:
@misc{wei2026harnessrsi,
  title  = {{Harness Self-Evolution: Theory, Algorithms, Evaluation,
             Applications, and Impact}},
  author = {Wei, Chuyang and Guan, Haoxiang and Zhu, Minghang and
            Zhou, Kexin and He, Jiyan and Zhou, Xiren and
            Chen, Huanhuan and Shen, Yifei},
  year   = {2026},
  url    = {https://github.com/zgcagi/Harness-RSI/blob/main/paper/harness-self-evolution.pdf}
}

@misc{wei2026selfevolvingagentharness,
  title         = {{Self-Evolving Agent Harness}},
  author        = {Wei, Chuyang and Guan, Haoxiang and Zhu, Minghang and
                   Zhou, Kexin and He, Jiyan and Zhou, Xiren and
                   Chen, Huanhuan and Shen, Yifei},
  year          = {2026},
  eprint        = {2610.18813},
  archivePrefix = {arXiv},
  primaryClass  = {cs.AI},
  url           = {https://arxiv.org/pdf/2610.18813}
}
Released under CC BY 4.0. Listed works retain their respective licenses.


 这是综述《Harness Self-Evolution》的配套阅读列表和资源网站。该综述探讨 LLM 智能体的 harness(提示词、记忆、工作流)如何在底层模型权重保持不变的情况下,根据执行经验进行更新。