# Install uv first (if you haven't)
curl -LsSf https://astral.sh/uv/install.sh | sh

# Install Hyper-Extract CLI
uv tool install hyperextract
# or: pipx install hyperextract
2. Configure your provider (pick one):
# OpenAI (LLM + embeddings in one key)
he config init -p openai -k YOUR_OPENAI_API_KEY

# DeepSeek (LLM only — pair with an OpenAI embedder, most cost-effective)
he config llm -p deepseek -k YOUR_DEEPSEEK_API_KEY
he config embedder -p openai -k YOUR_OPENAI_API_KEY

# Local vLLM (free, on-premise)
he config llm -p vllm -u http://localhost:8000/v1 -k dummy -m Qwen/Qwen3.5-9B
he config embedder -p vllm -u http://localhost:8001/v1 -k dummy -m BAAI/bge-m3
More providers — Anthropic (Claude), Alibaba Bailian, OrcaRouter…
# Anthropic (Claude) — LLM only
he config llm -p anthropic -k YOUR_ANTHROPIC_API_KEY
he config embedder -p openai -k YOUR_OPENAI_API_KEY

# Alibaba Bailian (Qwen, LLM + embeddings in one key)
he config init -p bailian -k YOUR_BAILIAN_API_KEY
OpenAI and Bailian provide both LLM and embedding models in one API. Anthropic and DeepSeek are LLM-only (pair them with an OpenAI-compatible embedder). DeepSeek is the most cost-effective option (~$0.001-0.005/page).
3. Extract, query & visualize:
# Extract knowledge from a document
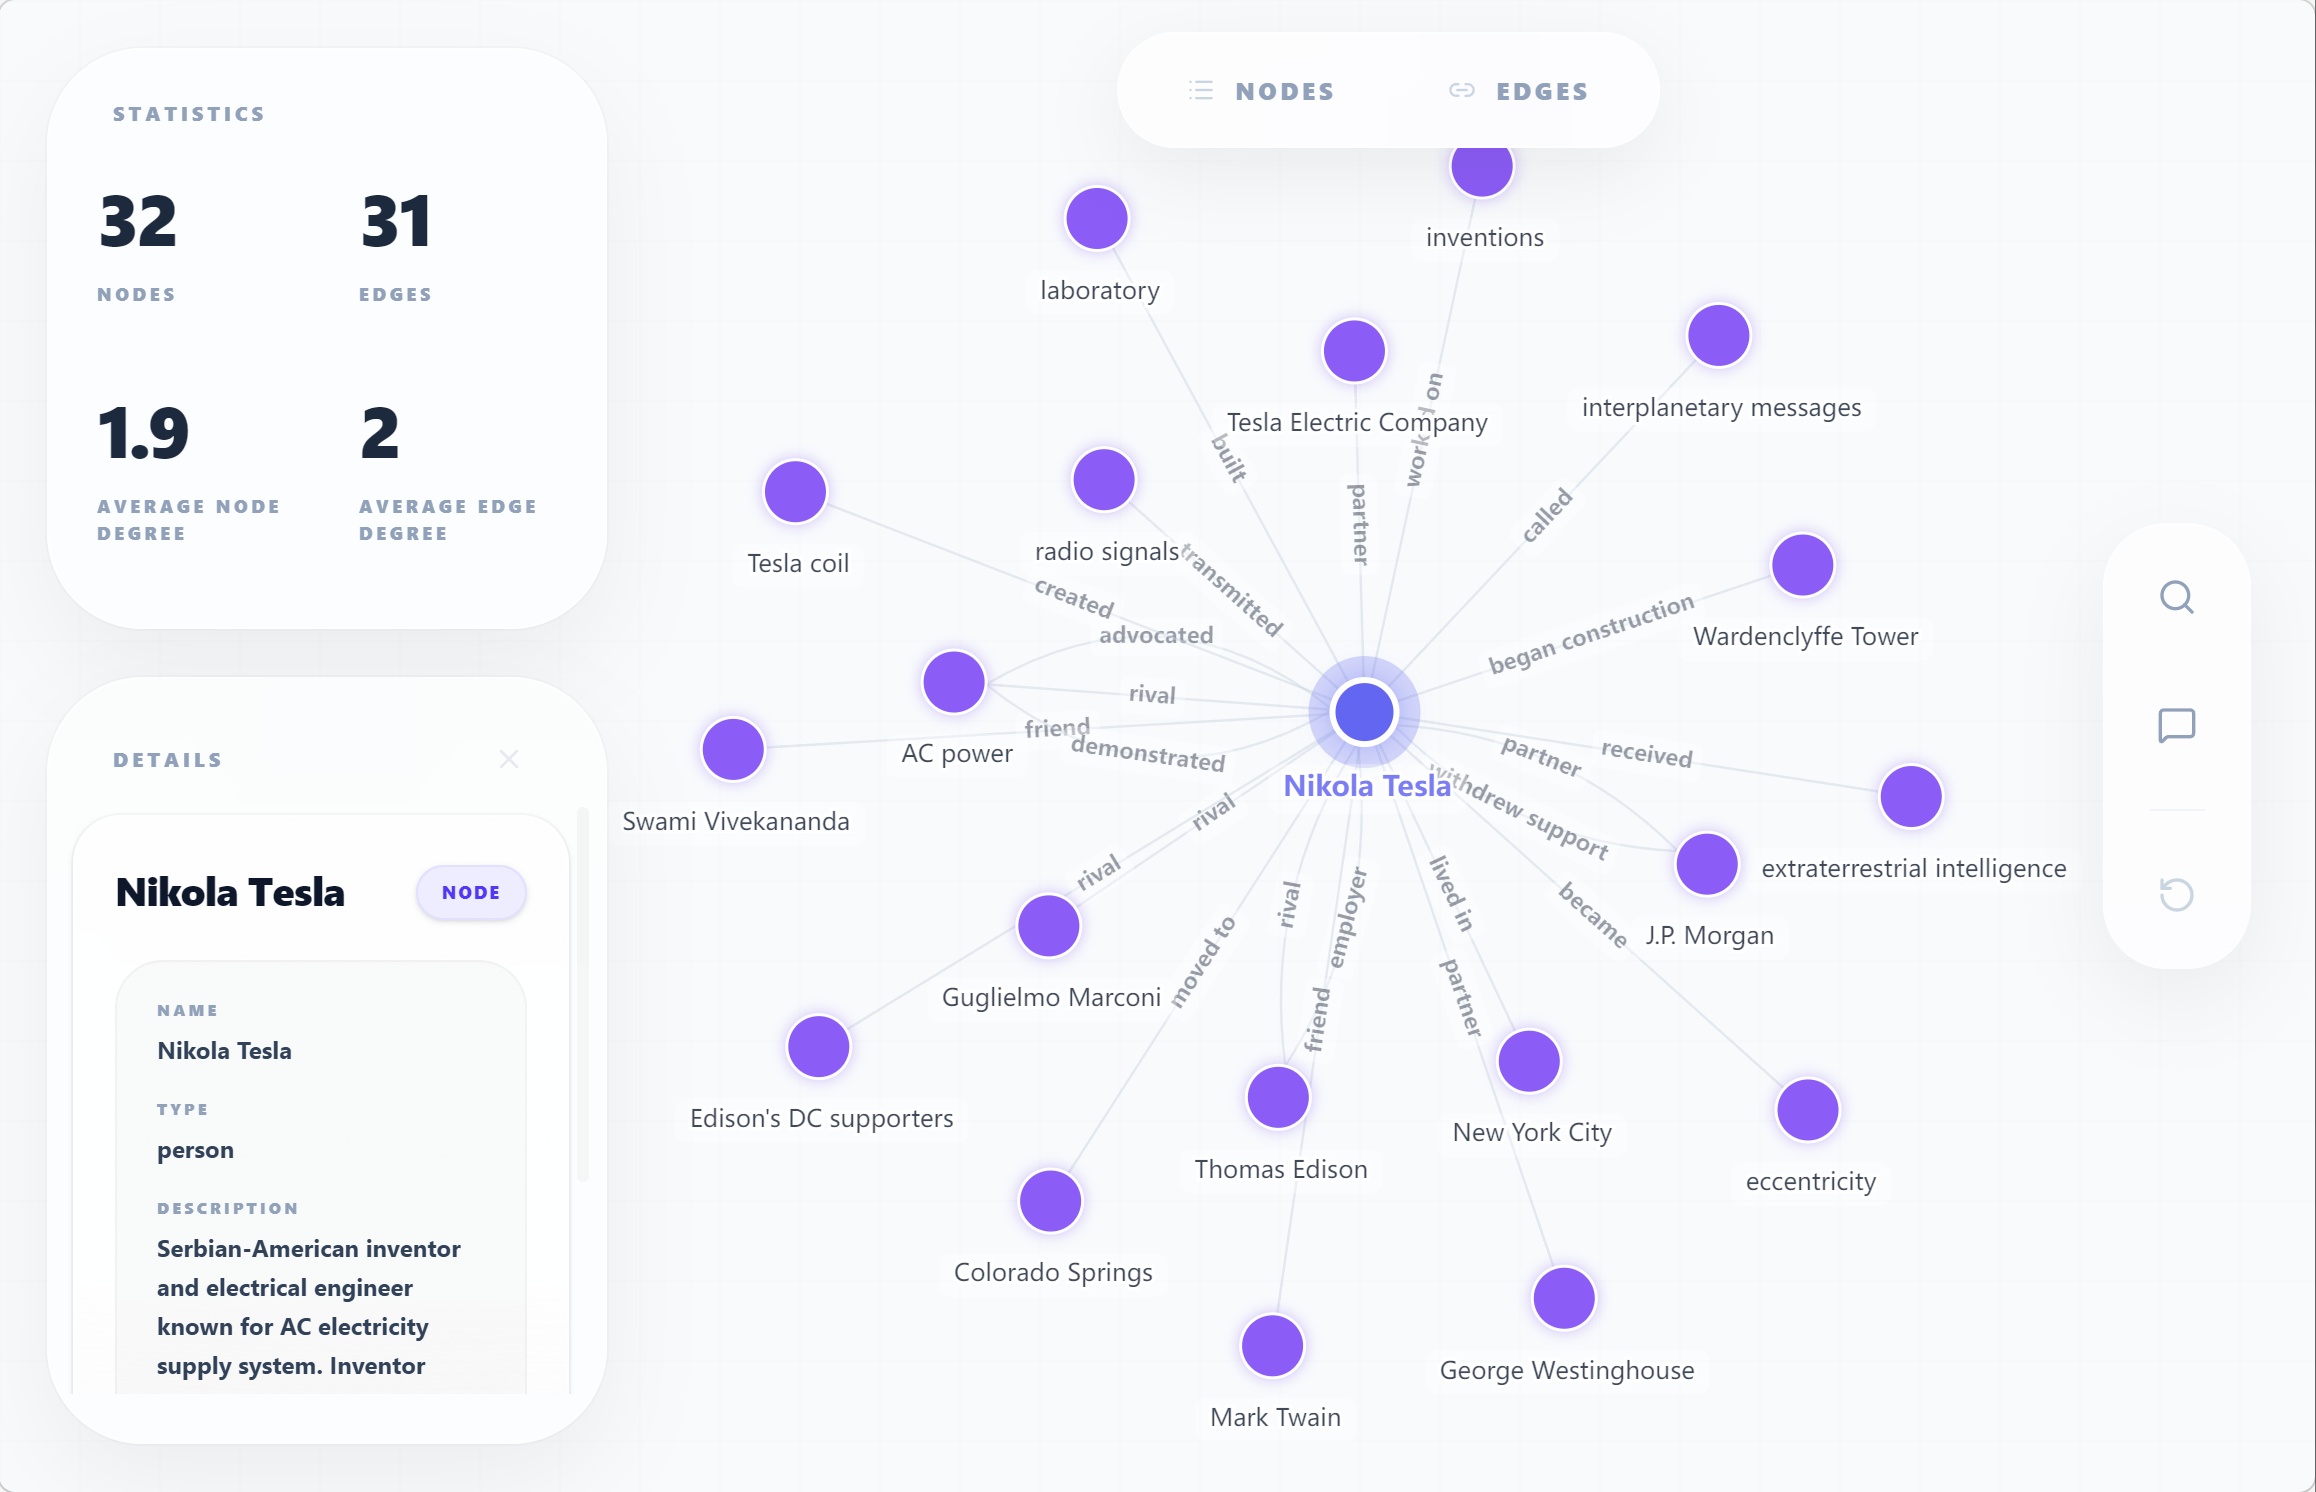
he parse examples/en/tesla.md -t general/biography_graph -o ./output/ -l en

# Query it
he search ./output/ "What are Tesla's major achievements?"

# Visualize
he show ./output/

# Export to an Obsidian vault (Markdown notes + [[wikilinks]])
he export obsidian ./output/ -o ./vault/

# Your sources change? Feed updates under the same source — old facts roll back automatically
he feed ./output/ updated-tesla.md --source tesla.md

# Tag and scope your searches
he tag ./output/ --source tesla.md --add biography
he search ./output/ "inventions" --tag biography

# Audit: which documents contributed what?
he info ./output/ --sources
Which provider should I use? OpenAI and Bailian provide both LLM and embedding models in one API; Anthropic and DeepSeek are LLM-only (pair with an OpenAI embedder); local vLLM is free but needs a GPU. Full guide: Provider System.
🐍 Python API (click to expand)
uv pip install hyperextract
from hyperextract import Template

ka = Template.create("general/biography_graph")

with open("examples/en/tesla.md") as f:
    result = ka.parse(f.read())

result.show()
Feed PDF, Word, PowerPoint, Excel, HTML, EPUB and more — not just .txt/.md (pip install "hyperextract[ingest]")
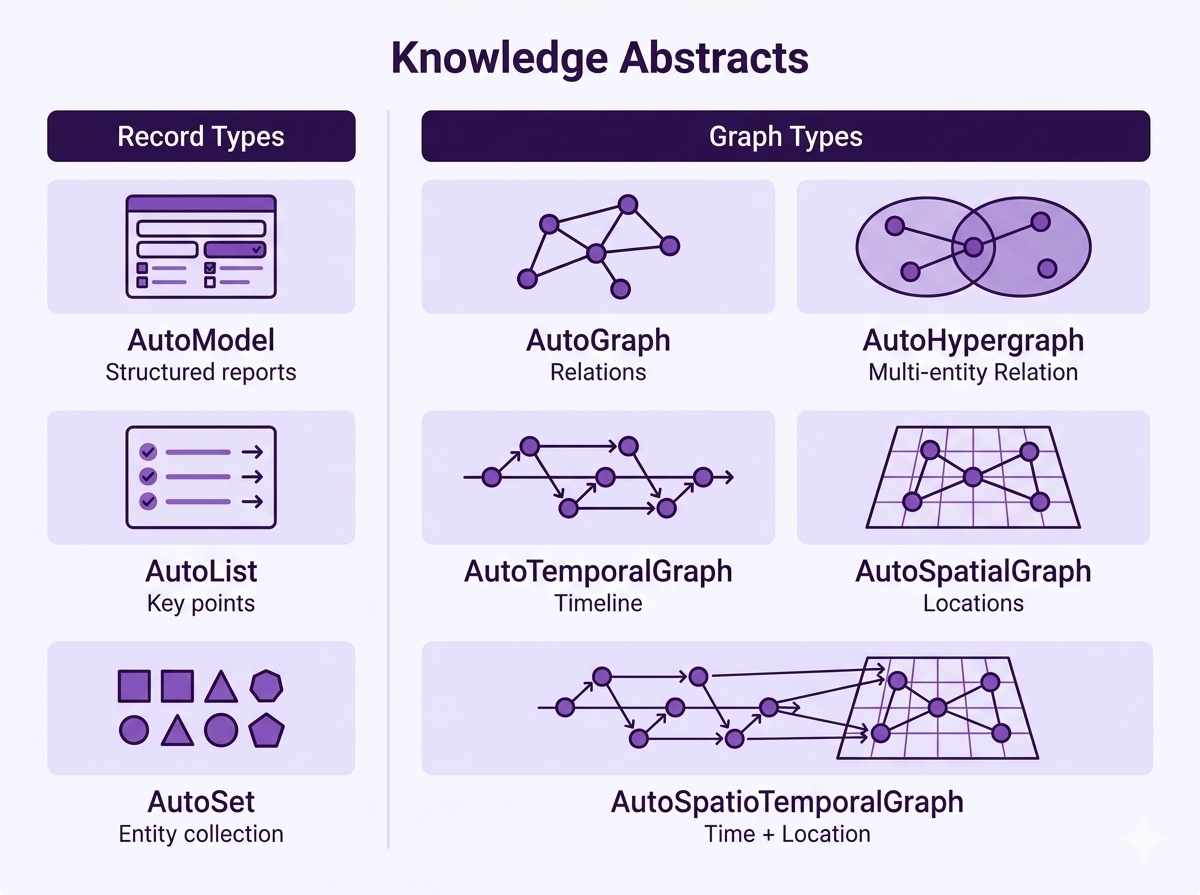
🔷 9 Knowledge Structures
From raw chunk corpora and simple Lists to advanced Graphs, Hypergraphs, and Spatio-Temporal Graphs
🧠 11+ Extraction Engines
chunk_rag (zero-cost baseline), GraphRAG, LightRAG, Hyper-RAG, KG-Gen, and more — ready to use
📝 80+ YAML Templates
Zero-code extraction across Finance, Legal, Medical, TCM, Industry, and General domains
🔄 Incremental Evolution & Provenance
Feed new documents anytime — every source is attributed and the index updates incrementally; audit (he info --sources), roll back (he remove --document), or upsert updated versions as your sources change
📤 Obsidian Export
Turn any extracted graph into an Obsidian vault — Markdown notes linked by [[wikilinks]]
🎯 What Can You Do With It?
📄 Researcher — Turn papers into knowledge graphs
Feed a 20-page academic paper, get an interactive graph of key concepts, authors, and citations.
he parse paper.pdf -t general/academic_graph -o ./paper_kb/
he show ./paper_kb/
🏦 Financial Analyst — Extract entities from earnings reports
Automatically identify companies, executives, financial metrics, and their relationships from unstructured reports.
he parse earnings.md -t finance/earnings_graph -o ./finance_kb/
he search ./finance_kb/ "What are the key risk factors?"
🔒 Local Deployment — Keep data on-premise with vLLM
Run Qwen3.5-9B + bge-m3 locally via vLLM. No data leaves your machine.
📜 Knowledge Base Manager — Keep your KB in sync with reality
Documents change. Hyper-Extract tracks every source so you can update, roll back, or audit without starting over.
# Ingest with attribution — every fact is traceable to its source
he feed ./ka/ contract-v1.md --source contract-v1
he tag ./ka/ --source contract-v1 --add legal --add acme

# Document updated? Re-feed under the same source — old facts roll back automatically
he feed ./ka/ contract-v2.md --source contract-v1

# Document is obsolete? Roll back everything it contributed
he remove ./ka/ --document contract-v1

# Remove a single wrong fact (LLM-assisted, with dry-run preview)
he remove ./ka/ --edit-node Apple --fact "founded by Steve Jobs" --dry-run

# Search only within legal-tagged documents
he search ./ka/ "termination clause" --tag legal

# Audit: which documents contributed what?
he info ./ka/ --sources
🚀 Supported Platforms & Models
Hyper-Extract uses LangChain structured output with function calling. The model must support tool/function calling.
Embedding models (semantic search) work with any OpenAI-compatible endpoint: text-embedding-3-small, text-embedding-v4 (Bailian), bge-m3 (local vLLM).
Provider notes — DeepSeek & Anthropic pairing
DeepSeek: V4 models default to "thinking" mode, which Hyper-Extract auto-disables so structured extraction works. Set DEEPSEEK_API_KEY. DeepSeek has no embeddings API:
from hyperextract import create_client
llm, emb = create_client(llm="deepseek", embedder="openai:text-embedding-3-small")
Anthropic: Claude is used for the LLM (set ANTHROPIC_API_KEY, extra: pip install 'hyperextract[anthropic]'). No embeddings API:
from hyperextract import create_client
llm, emb = create_client(llm="anthropic", embedder="openai:text-embedding-3-small")
v0.9.0 — 📄 Rich document ingestion: he parse / he feed now take PDF, Word, PowerPoint, Excel, HTML, EPUB and more (pip install "hyperextract[ingest]") · 🧱 New chunk_rag method: zero-extraction chunk baseline with full provenance · 🐛 he tag and method-KA command fixes.




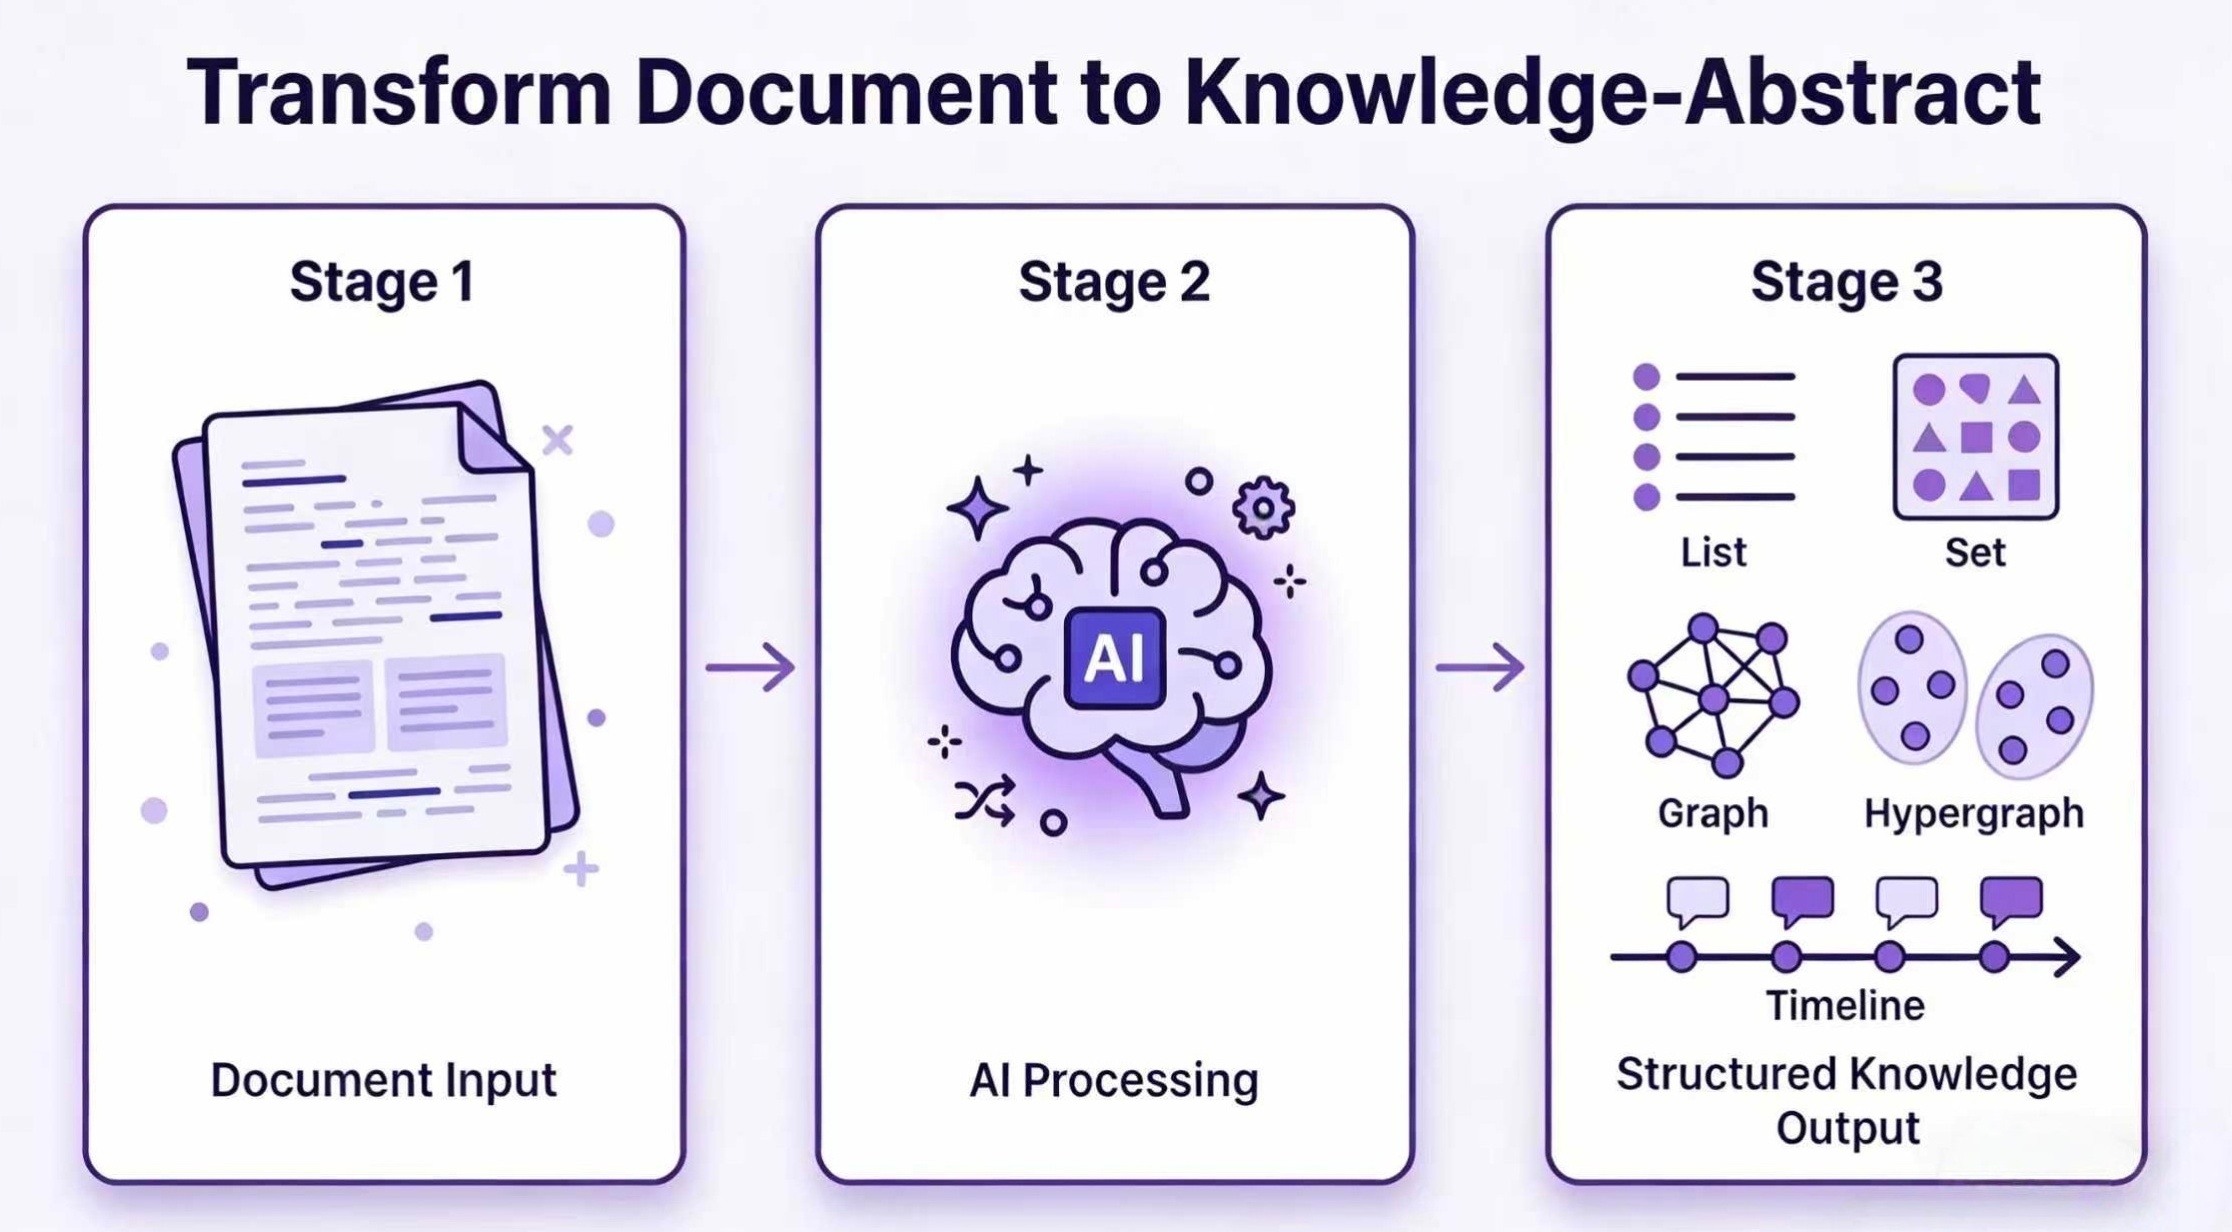
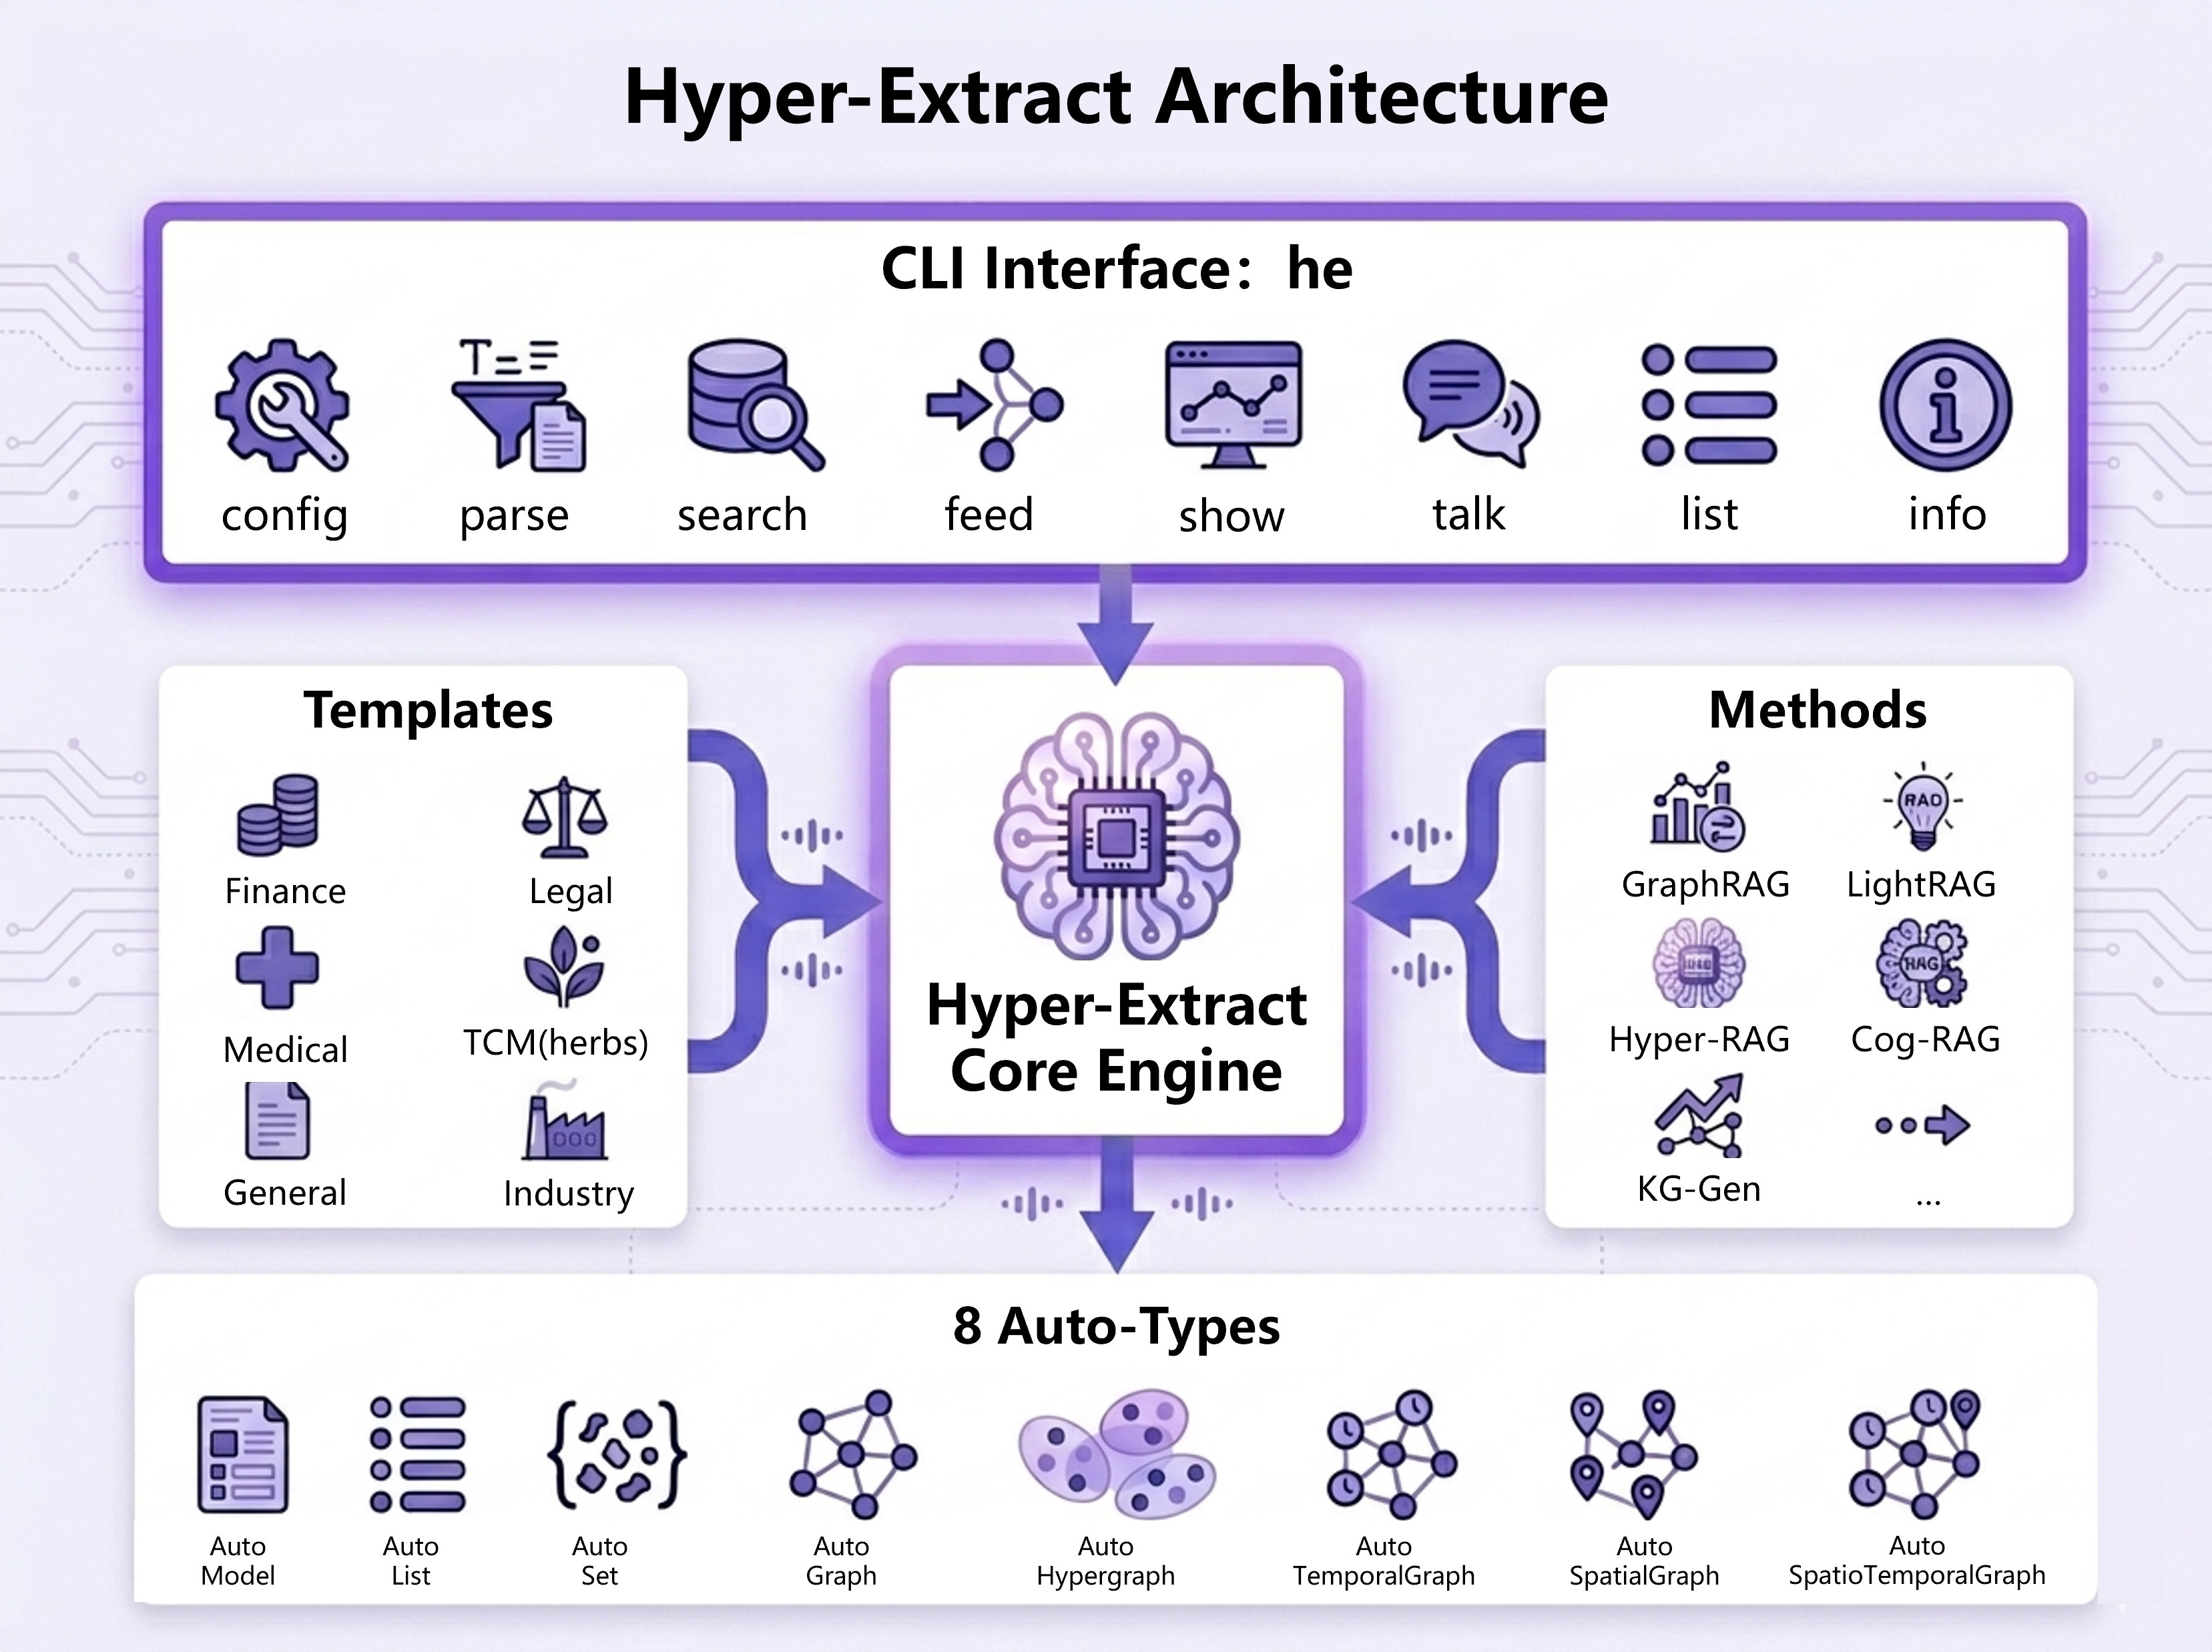

 Hyper-Extract 是一个命令行工具,利用 LLM 把非结构化文档(PDF、Word、文本等)转化为结构化知识——包括分块语料、列表、图、超图和时空图——只需一条命令即可完成。