What is this?
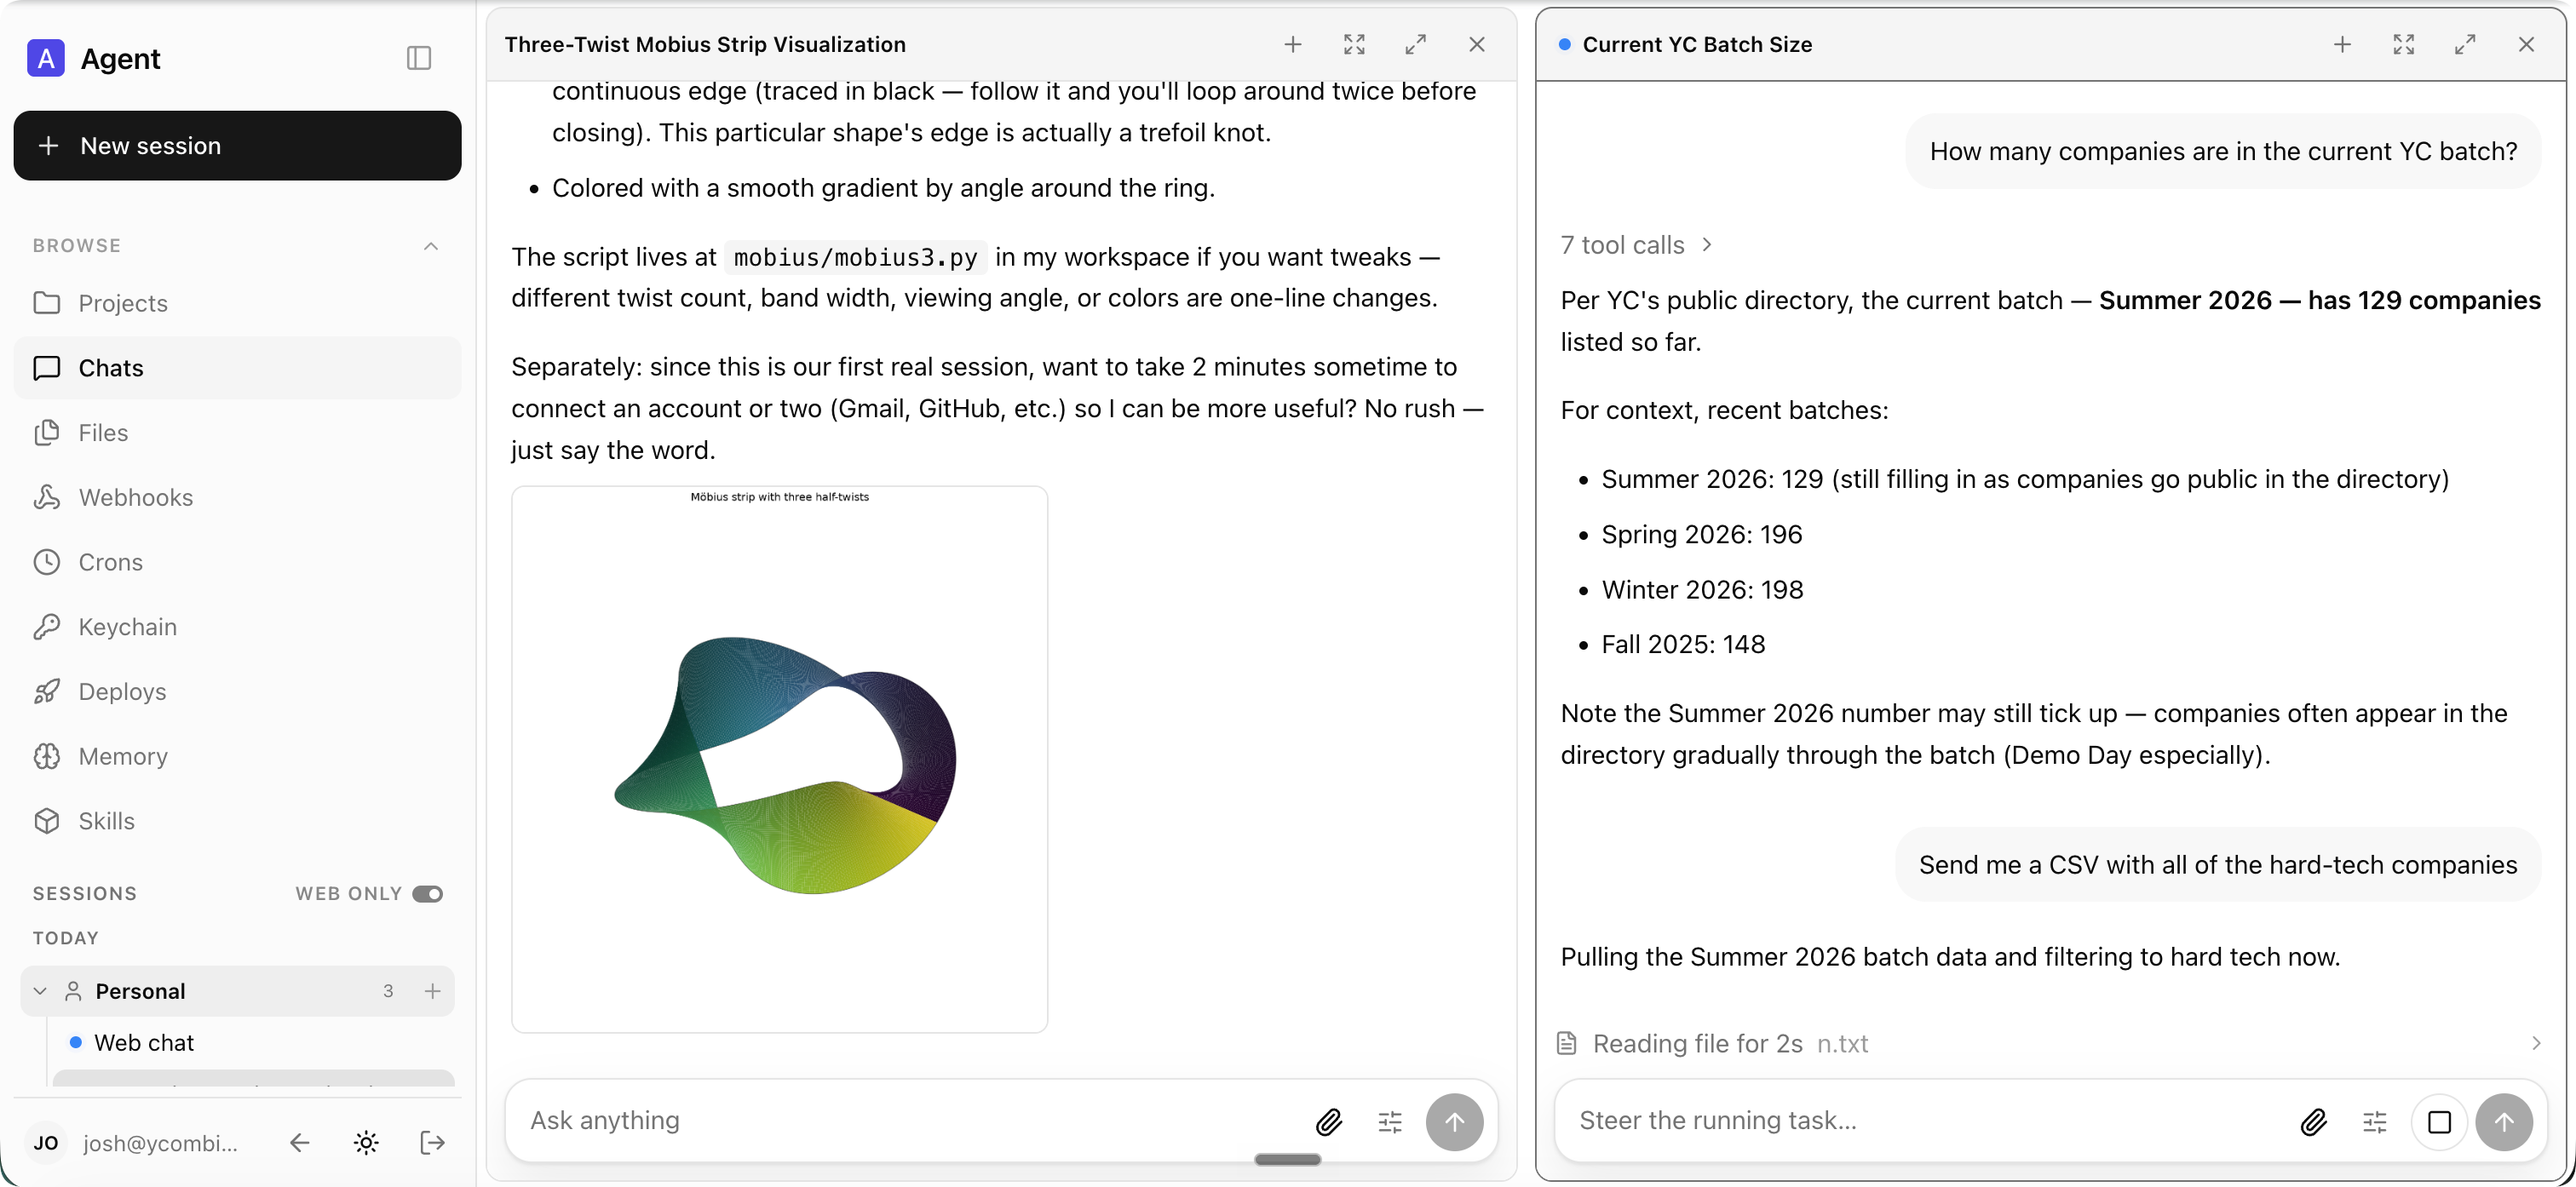
 An open-source multiplayer agent harness for work: one AI agent that a whole company shares, reachable from Slack and a web app. It is built for teams of people working with the agent together, not for a single person.
Do we run it ourselves, or is there a hosted option?You self-host it: your organization creates a deployment repository depending on the @yc-software/qm package, and each deployment runs in your own cloud account. A 3rd-party hosted version exists for trying it out.
You self-host it: your organization creates a deployment repository depending on the @yc-software/qm package, and each deployment runs in your own cloud account. A 3rd-party hosted version exists for trying it out.How do we actually get it deployed?Tell your coding agent of choice 'Let's deploy' and it follows the deployment guide. Initialization walks you through infrastructure, web sign-in, connector credentials, optional Slack access, and live verification — no source checkout required.
Tell your coding agent of choice 'Let's deploy' and it follows the deployment guide. Initialization walks you through infrastructure, web sign-in, connector credentials, optional Slack access, and live verification — no source checkout required.Are we locked into one AI model or coding agent?No — you pick your own harness and model and can switch between them. Pi, OpenCode, Codex, and Claude Code all drive the same core, so a deployment is not tied to any single vendor.
No — you pick your own harness and model and can switch between them. Pi, OpenCode, Codex, and Claude Code all drive the same core, so a deployment is not tied to any single vendor.What will bite us if we skip a setup step?Without DATABASEURL and SESSIONSTORE=postgres, sessions live in process memory and vanish on restart, so set them for durability. The core also runs directly on Node, which must be version 24.15 or newer.
Without DATABASEURL and SESSIONSTORE=postgres, sessions live in process memory and vanish on restart, so set them for durability. The core also runs directly on Node, which must be version 24.15 or newer.Is it one person's assistant, or does a whole team use it?It is designed for startups: every employee gets their own isolated workspace and works independently, and people can also collaborate with the agent together in Slack channels, group messages, and projects.
It is designed for startups: every employee gets their own isolated workspace and works independently, and people can also collaborate with the agent together in Slack channels, group messages, and projects.Does the agent and our company data stay on our own infrastructure?Yes — each deployment runs in the operator's own cloud account, with user data, session history, and other durable state held in a Postgres persistence layer. Memory can additionally be routed per scope to external providers if you choose.
Yes — each deployment runs in the operator's own cloud account, with user data, session history, and other durable state held in a Postgres persistence layer. Memory can additionally be routed per scope to external providers if you choose.What can the agent actually do for a team day to day?It can search internal notes, email, documents, databases, and the web together; build and publish internal web apps; triage your inbox on a schedule with labels and reply drafts; work in an existing repository — run tests, open PRs, monitor CI, check logs — and track a project in a shared channel.
It can search internal notes, email, documents, databases, and the web together; build and publish internal web apps; triage your inbox on a schedule with labels and reply drafts; work in an existing repository — run tests, open PRs, monitor CI, check logs — and track a project in a shared channel.What is this sandbox the agent works in?Each person and each room gets its own isolated, durable sandbox — the agent's own computer. The agent's execute tool runs commands there, and installed tools stay installed across sessions.
Each person and each room gets its own isolated, durable sandbox — the agent's own computer. The agent's execute tool runs commands there, and installed tools stay installed across sessions.The agent acts with our credentials — what stops it from running something destructive?Your org picks one security posture: Strict pauses every harness tool call for human approval, Auto (the default) screens external content with a classifier before it reaches the model, and Dangerous turns screening off. Hard denials for things like recursive deletes and destructive SQL apply in every posture.
Your org picks one security posture: Strict pauses every harness tool call for human approval, Auto (the default) screens external content with a classifier before it reaches the model, and Dangerous turns screening off. Hard denials for things like recursive deletes and destructive SQL apply in every posture.Can it keep working on things when nobody is online?Yes — crons, watches, and inbound webhooks run background work while nobody is watching, such as scheduled inbox triage that applies labels and drafts replies.
Yes — crons, watches, and inbound webhooks run background work while nobody is watching, such as scheduled inbox triage that applies labels and drafts replies.Which topics is it in?assistant, cron, webhooks, slack, collaboration, harness, opencode, agent-memory, sandbox, agent-orchestration, skills, postgresql
assistant, cron, webhooks, slack, collaboration, harness, opencode, agent-memory, sandbox, agent-orchestration, skills, postgresql