





Auto-claude-code-research-in-sleep README

The project's README from github.com/wanshuiyin/Auto-claude-code-research-in-sleep. As one markdown file: README.md.

Auto-claude-code-research-in-sleep (ARIS ⚔️🌙)

Hugging Face Daily Paper · #1 Paper of the Day

Technical Report · ARIS Intro (HTML) · ARIS Intro Slides — VALSE 2026 · AI Agents · Featured on PaperWeekly · Featured in awesome-agent-skills · AI Digital Crew - Project of the Day · GitHub stars · 💬 Join Community · Cite

💡 Use ARIS as a skill-based workflow in Claude Code / Codex CLI / Cursor / Trae / Antigravity / GitHub Copilot CLI / OpenClaw / DeepSeek Harness, or get the full experience with the standalone ARIS-Code CLI — enjoy any way you like!

🐋 On DeepSeek Harness it installs as one plugin: dsh plugin --profile web add dsh-aris (fetches from npm by itself — no separate install step, but pnpm must be on PATH) — all 82 skills unchanged, Codex still the independent reviewer. Setup and limits on the dsh-aris branch.

🌱 ARIS is a methodology, not a platform. What matters is the research workflow — take it wherever you go.

🤖 AI agents: Read AGENT_GUIDE.md instead — structured for LLM consumption, not human browsing.

🛡️ ARIS audits its own output → now Anti-Autoresearch audits everyone's. 61 signals — 46 integrity hack-patterns in 8 families, 13 AI-style impressions, 2 advisory — checked end-to-end into a deterministic, reviewer-ready report. Self-consistency + fabrication forensics, not an AI-text detector.

The field has put up with unreliable autoresearch long enough —
Anti-Autoresearch is the read that finally catches it.

🧱 ARIS's reviewer is good — and it also proposed hashes nobody reads → HERO is the contract that stops that. Hashing, Edge cases, Rubrics, Overbuild — the four shapes agents over-defend in, as a ~550-token block for CLAUDE.md / AGENTS.md. It bounds what the agent proposes, never what it looks for.

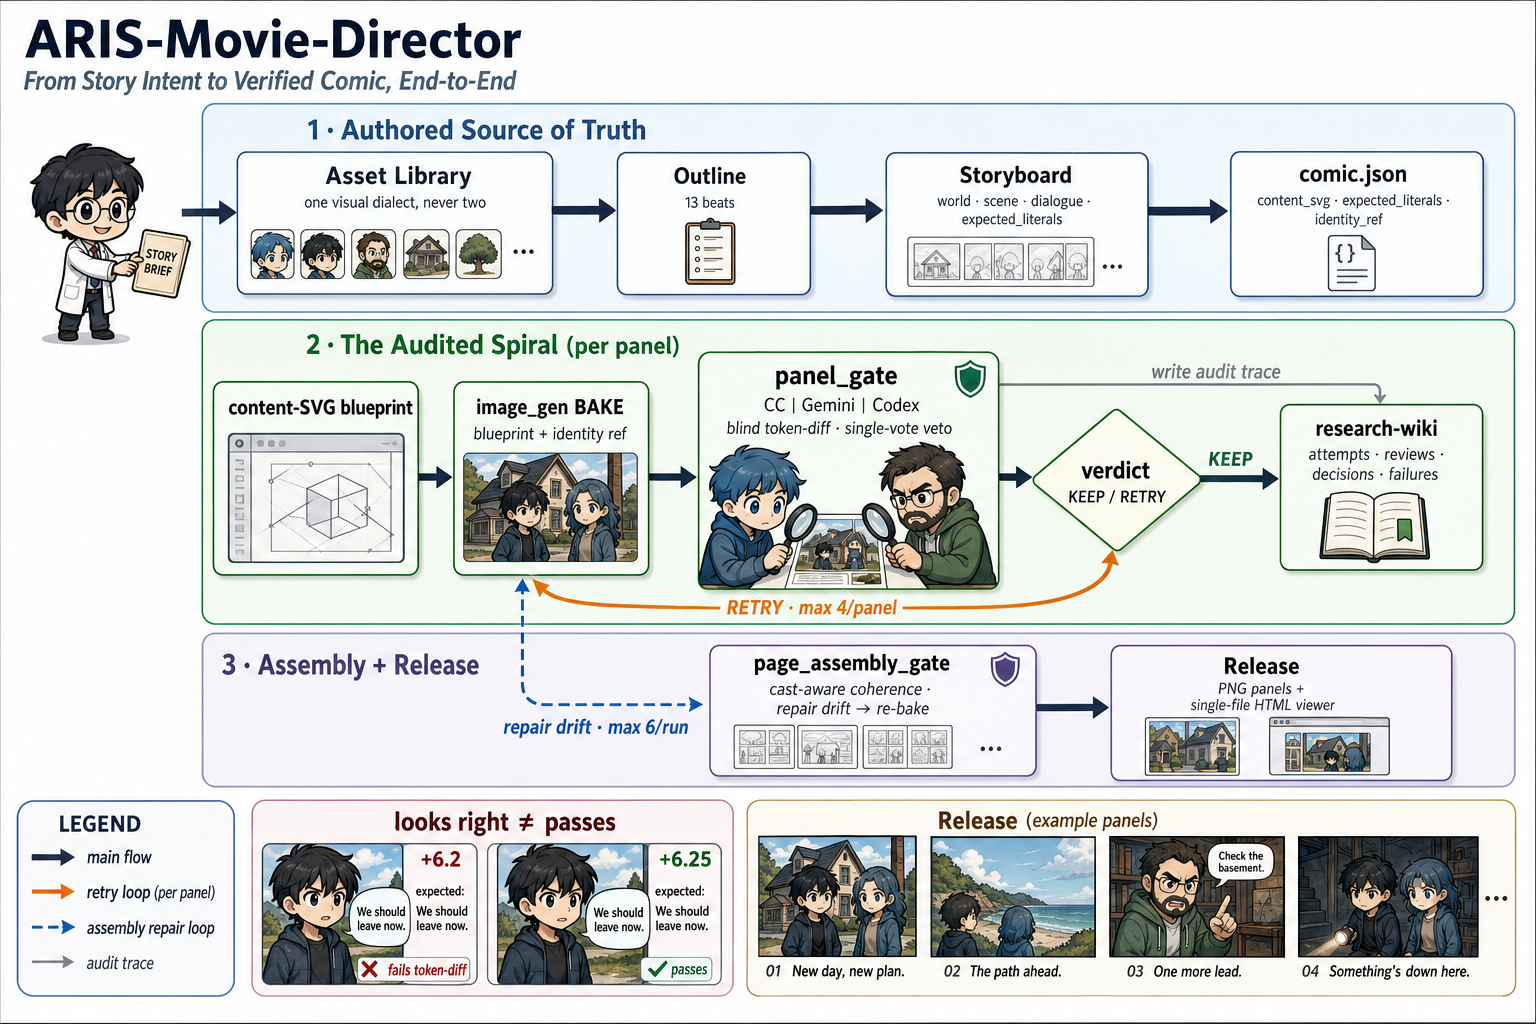
🎬 ARIS goes multimodal → ARIS-Movie-Director — hand it a rough story and get back a movie told in still frames, checked scene by scene (the reference run has 19 scenes). Long stories usually break when the model forgets earlier details or judges its own work — so ARIS keeps a research-wiki for memory and has other models check every frame.

🗺️ Method figure — story brief → authored source of truth → per-panel audited spiral → assembly & release, on one canvas

ARIS-Movie-Director method — the audited spiral: authored source of truth (asset library · outline · storyboard · comic.json) → per-panel image_gen + cross-model panel_gate (blind token-diff, single-vote veto) → research-wiki audit trace → assembly + release

🧭 *The same loop also makes clean method / flow diagrams — the figure above was made with it. Entry points in ARIS-Movie-Director: /movie-pipeline and /method-figure, the skill that made this figure.*

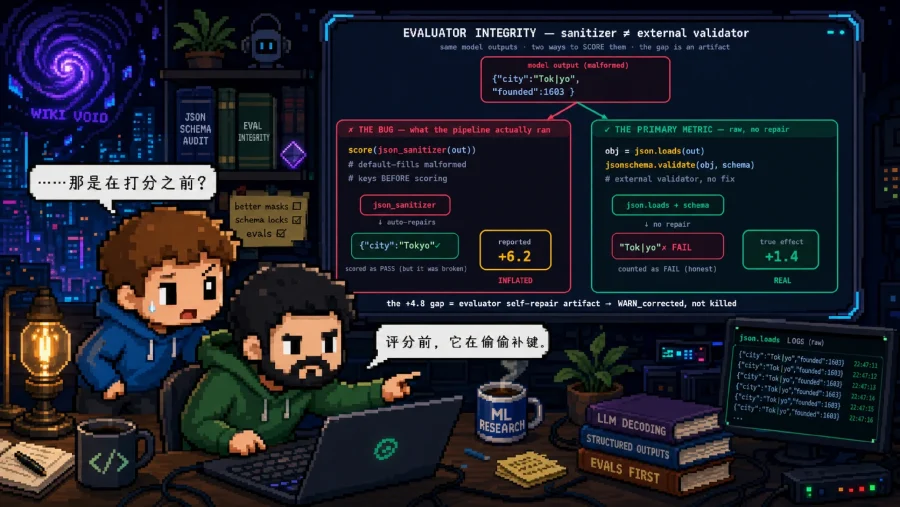
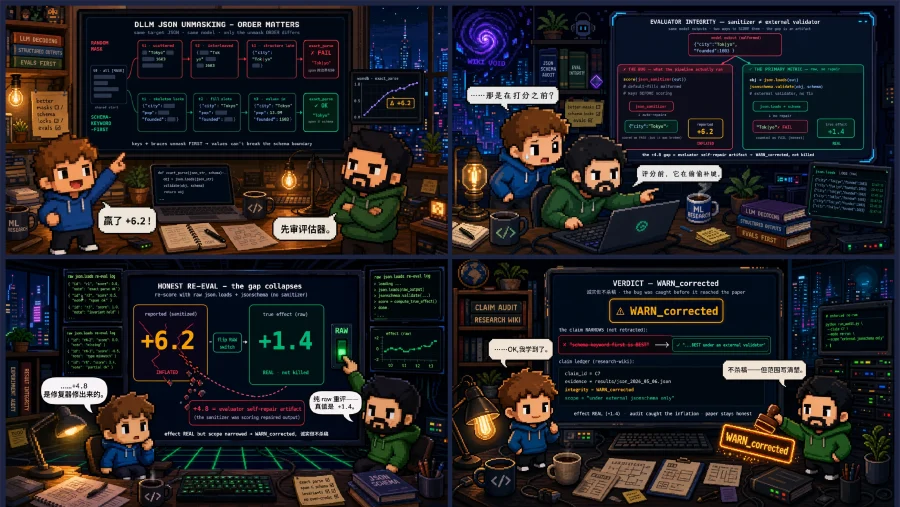
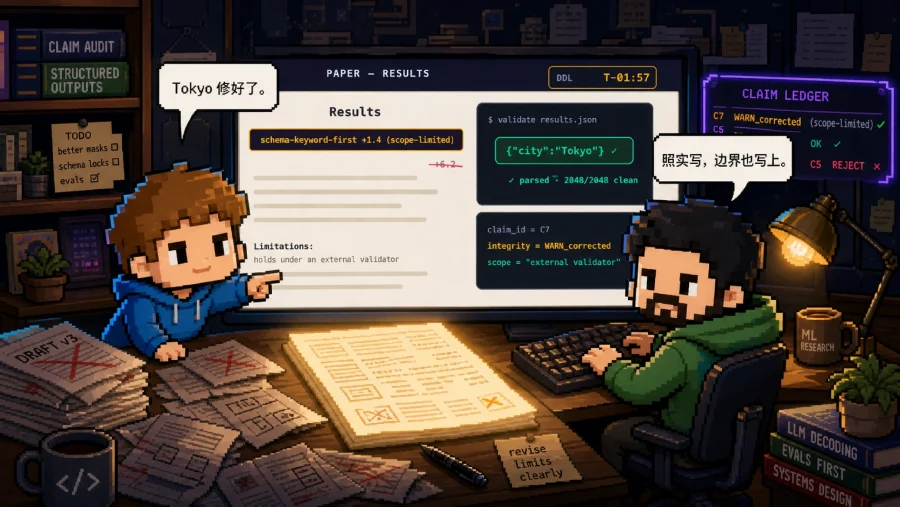
🎞️ A few frames from the reference movie — the story's own integrity beat: a run that reported +6.2 but really moved +1.4.  ▶ watch all 19 scenes →
ARIS-Movie-Director frame — the evaluator-integrity audit page ARIS-Movie-Director frame — a multi-panel scene ARIS-Movie-Director frame — the integrity beat (reported +6.2, really moved +1.4)

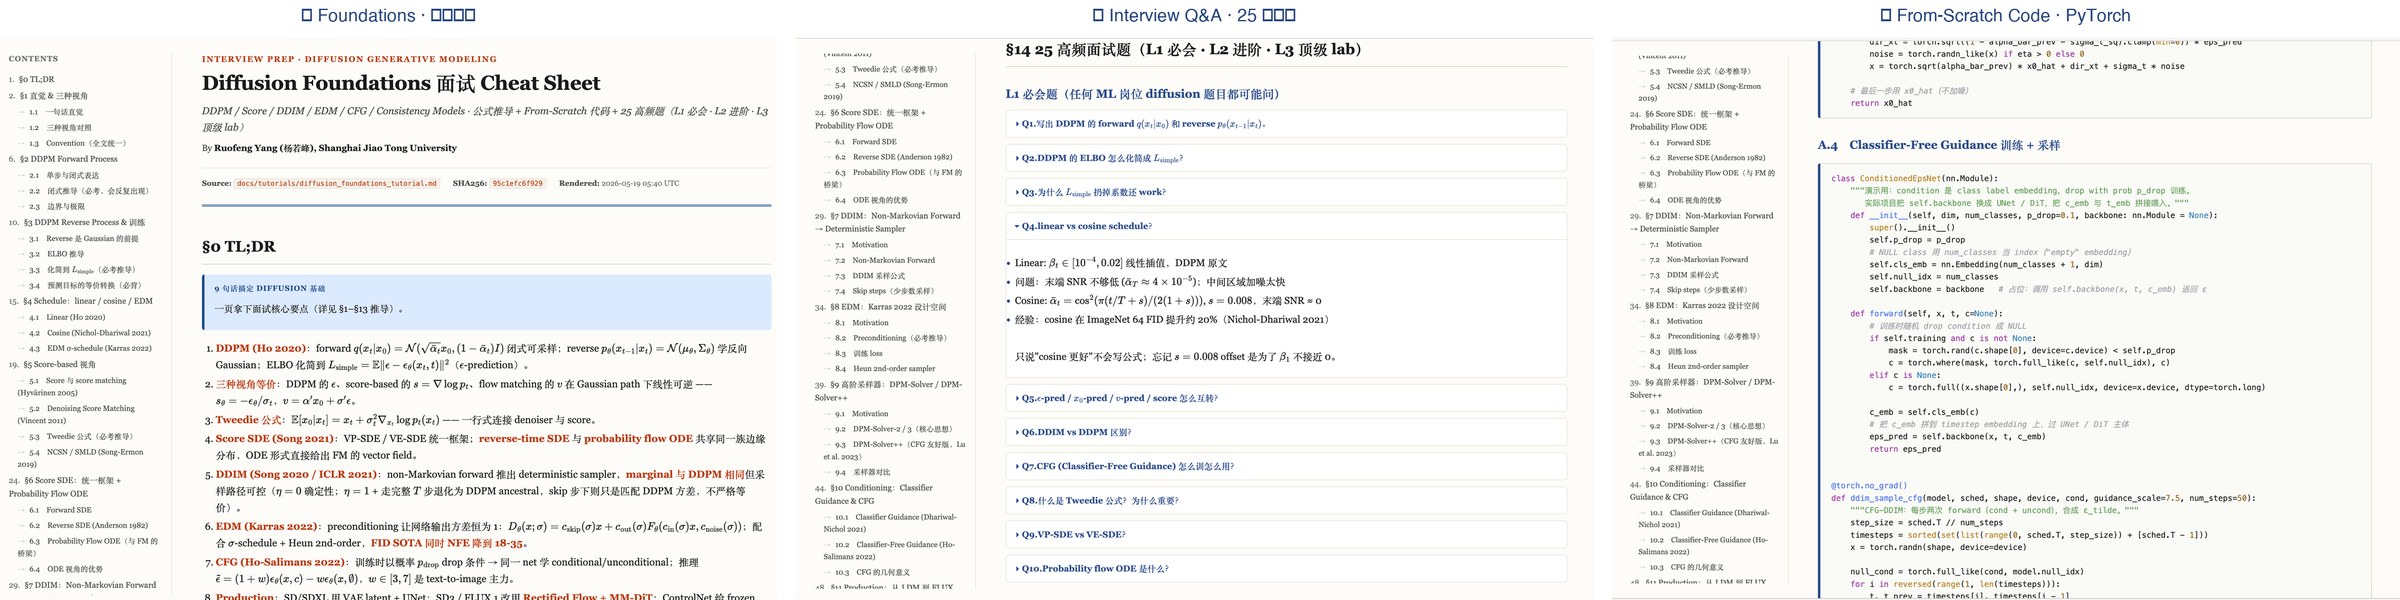
🎯 准备 2026 AI 秋招? → 🌐 ARIS-in-AI-Offer · GitHub repo · 中文 README —— 23 篇双语 ML / LLM / 多模态 / 生成式 / Agent 面试 cheat sheet,每篇 = 公式推导 + 从零 PyTorch + 25 高频面试题(L1 / L2 / L3),全部由 ARIS 的 /render-html 自动生成。希望大家秋招轻松一点 🌱

🖼️ Preview — the three-pillar cheat-sheet strip (① Foundations · ② Interview Q&A · ③ From-Scratch Code)

ARIS-in-AI-Offer preview — ① Foundations + ② Interview Q&A + ③ From-Scratch Code, three columns from a representative cheat sheet

📝 Three long-form blogs, cross-model collaborative writing via /render-html — Continuous DLM — a representation-perspective survey (2026 H1) · Cosmos 3 — understanding + generation in one Transformer (MoT) · Diffusion × representation × manifold learning.

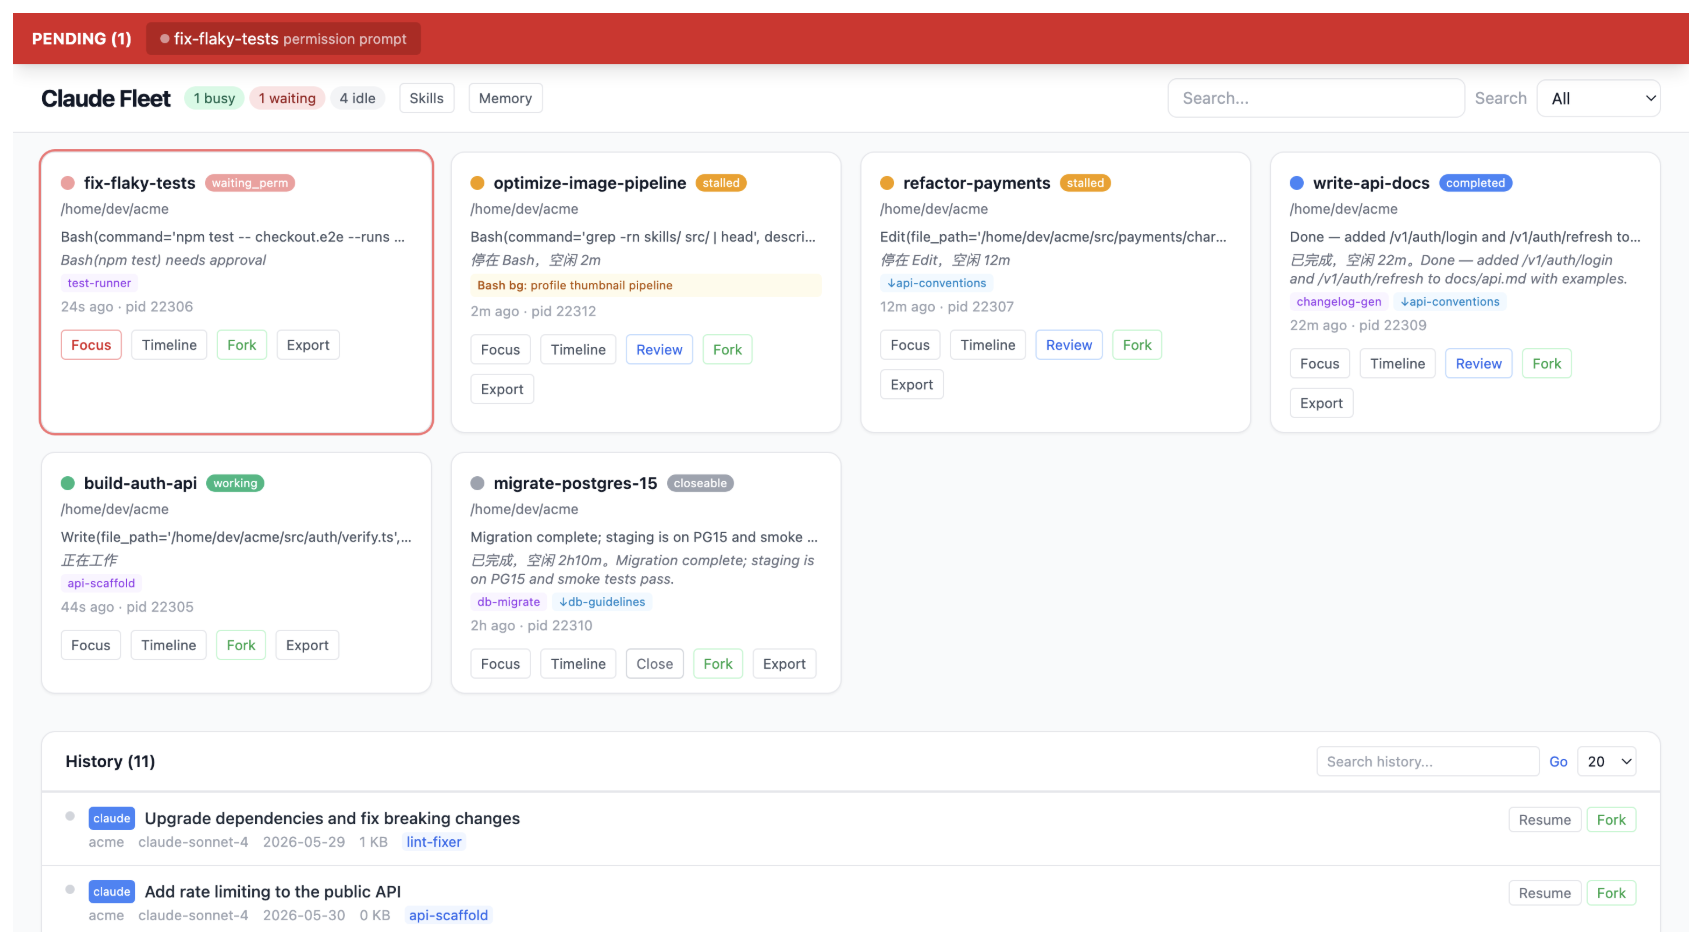
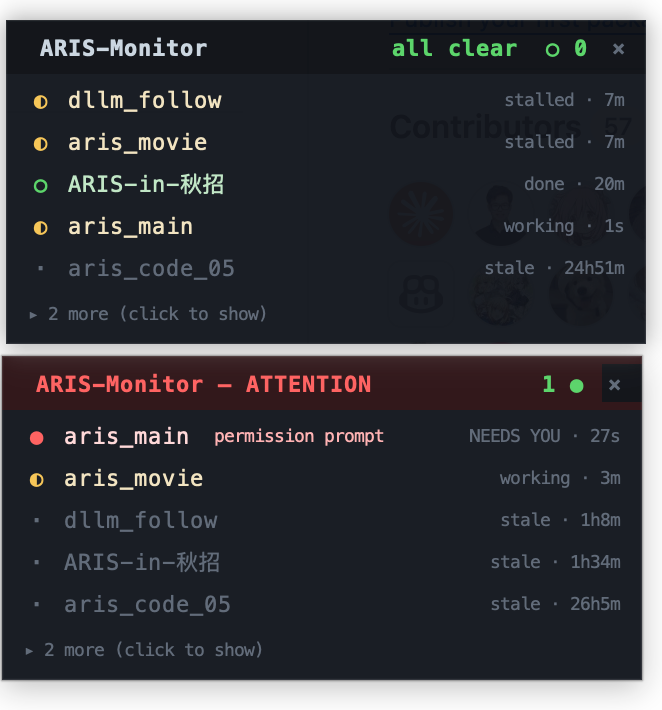
🛰 Keep an eye on your agent windows — Claude Fleet (by @tianyilt; local read-only dashboard for many parallel Claude Code / Codex windows, full-text transcript search — worth a ⭐), or the lighter built-in ARIS-Monitor (a tiny always-on-top macOS widget that lights up 🔴 when a session waits for your approval; click to jump there).

🖼️ Preview — Claude Fleet dashboard (full web) & ARIS-Monitor widget (minimal, built-in)
Claude Fleet — full local web dashboard for many concurrent Claude Code / Codex windows (triage, Focus, full-text search, skill/memory analytics) ARIS-Monitor — minimal always-on-top floating widget showing which Claude Code sessions need approval (calm all-clear vs red ATTENTION)
Claude Fleet · 全功能网页看板 ARIS-Monitor · 极简悬浮小窗(自带)
Run either in seconds — ARIS-Monitor (5s) / Claude Fleet (30s)

ARIS-Monitor — built-in, no clone / no pip / no browser:

cd aris-monitor && ./run.sh
# a borderless panel floats top-right; click a row to jump to that terminal

Claude Fleet — full web dashboard:

git clone https://github.com/tianyilt/claude-fleet
cd claude-fleet && bash run.sh
# open http://127.0.0.1:7878 in your browser

🚀 Beyond 科研 → 任何 "研究":ARIS-Anything 把 ARIS 的五步 loop(plan / draft / 对抗审 / 迭代 / 持久化)推广到非学术的结构化研究——投资尽调 / 法律研究 / 市场研究 / 自驱学习 / 调查新闻 / 工程复盘等。

🔥 ARIS-Code CLI — 独立安装版 · English | ⬇️ Download · Downloads

📰 ARIS-Code v0.4.24 (2026-08) — latest is the Claude 5 model refresh (#392): first-class Claude Opus 5 (new default, same $5/$25 tier) and Claude Fable 5 (Mythos-class flagship, correct $10/$50 pricing) — /model picker + fable/opus/sonnet aliases + an ordered availability chain (Opus 5 → 4.8 → 4.7) so accounts without Claude 5 access keep working untouched. Recent headliners: v0.4.23 — output folding (tool output folds to a few lines, ARIS_TOOL_OUTPUT_LINES=0 restores full dumps; 81 bundled skills incl. the Anti-Autoresearch /integrity-forensics launcher) and v0.4.17 — the MCP release (cross-model review needs no OpenAI API key — aris setup wires your ChatGPT subscription in as reviewer via Codex MCP). Caps a 20-release run (v0.4.5 → v0.4.24); per-release detail below. Credits: @GetIT-Sunday, @Anduin9527, @GO-player-hhy, @Jxy-yxJ, @screw-44, @StevenUST, @opposj, @ShijunLei-cn, @algojogacor, @YukinoshitaLove.

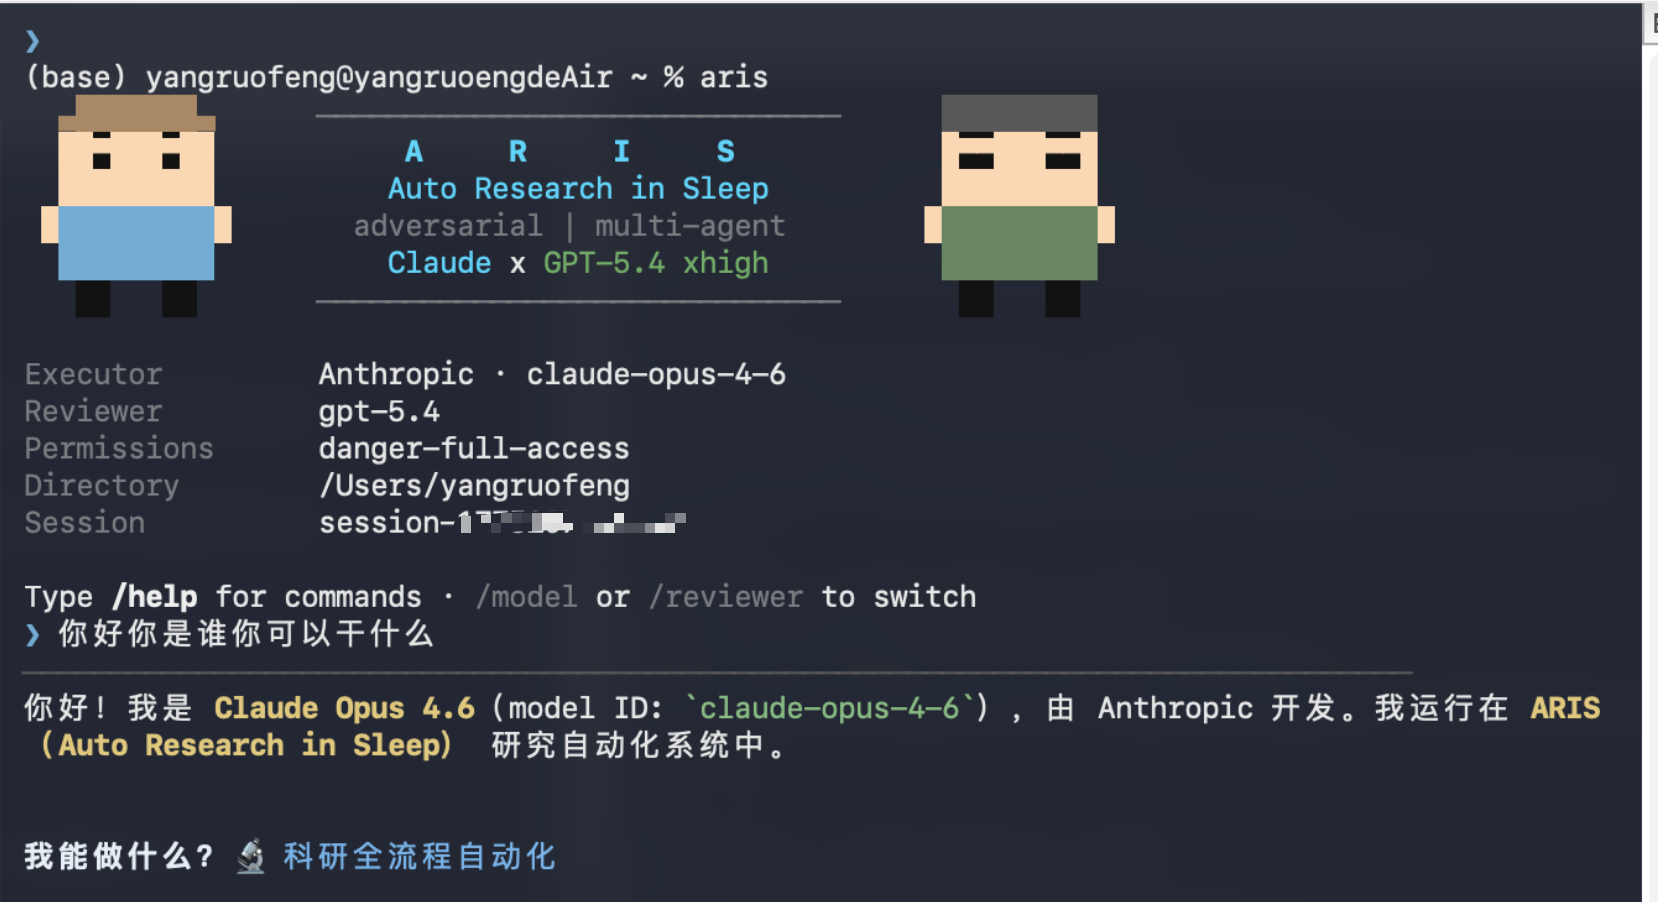
ARIS-Code CLI terminal — Auto Research in Sleep
Per-release details (v0.4.5 → v0.4.24)

v0.4.24 (2026-08-09) — the Claude 5 model refresh (#392, requested by @YukinoshitaLove). Explicit --model claude-opus-5 / claude-fable-5 already passed through on every platform — this release makes them first-class. Default → claude-opus-5 (main session, subagents, aris setup; same $5/$25 tier as Opus 4.8); the v0.4.18 availability fallback becomes an ordered chain walk (Opus 5 → Opus 4.8 → Opus 4.7, one step per precise 404 not_found_error, explicit choices never silently change) — the naive constant swap would have stranded 4.7-only accounts and configs saved by v0.4.23's setup, a regression the cross-model review caught and an end-to-end mock-404 chain test now locks. /model picker adds Fable 5 / Opus 5 / Sonnet 5; new fable alias. New Mythos-class pricing tier (fable/mythos = $10/$50, cache write $12.50 / read $1, verified 2026-08 — previously fell to the conservative $15/$75 unknown-model tier, a 1.5× over-estimate); Opus 5 / Sonnet 5 pinned on their existing branches. Tests: api 41 / aris-cli 213 + 4 e2e / runtime 226 / tools 70 / commands 5, all green; live smoke on claude-opus-5, claude-fable-5 and the fable alias. Codex MCP (gpt-6-astra xhigh) implementation gate: NO-GO → NO-GO → GO.

v0.4.23 (2026-08-02) — the output-folding release (top real-user complaint: "aris dumps thinking and the full content of documents it reads onto the screen"). 🧹 Tool-output folding, display layer ONLY: the disk-verified culprits were format_read_result appending the ENTIRE read payload, bash pushing full stdout/stderr, grep dumping its full content blob, and the edit preview capping line counts but not line LENGTH. Now Read/Grep show the first 6 lines, Bash shows first 4 + last 4 per stream (stderr keeps its red), each kept line capped at 240 chars (the minified-single-line case), then one dim "… (+N more lines — set ARIS_TOOL_OUTPUT_LINES=0 for full output)" hint. ONE env knob: unset = defaults, a positive integer overrides every tool, 0 = the exact old display; the session, model context, --output-format json and /export are untouched and always complete. Thinking was verified to never print (Anthropic deltas only accumulate; Kimi reasoning_content only feeds the replay cache — the "thinking dump" perception came from the document dumps); two end-to-end sentinel tests (real binary vs mock SSE server) lock that thinking/reasoning never reaches the terminal. Interactive expand/collapse was deliberately rejected as over-engineering. 🐛 Bash timeout now kills the command: a timed-out call reported interrupted: true while the dropped tokio future left the child RUNNING — side effects landed after the report; now kill_on_drop (escape hatch ARIS_BASH_KILL_ON_TIMEOUT=0; background tasks untouched; locked by a real behavioral test — a timed-out "sleep 1 && touch marker" must not create the marker). 📦 Bundle 79→81 (pin 7182624 → 3e49e63): /integrity-forensics — the Anti-Autoresearch SHA-pinned thin launcher (span-anchored evidence ledger → GPT auditors propose → deterministic rules-only adjudicator decides → typed BLOCK/WARN gate + obligations ledger) — and /web-debug-search, +tools/forensics_gate.py (29 helpers, 104 embedded resources). 🎁 Also: grep's content mode no longer shows a false "0 matches" above real results (the gate caught that "numMatches": null serializes with the key present, defeating a naive presence check); all four crates' local-mock-server tests are now proxy-immune (a shell with http(s)_proxy set used to turn 15 tests red on a released tag — 127.0.0.1 was routed through the proxy). The rest of the runtime-state package (compaction re-arm, failed-turn cleanup, /cost dollars, SSE tail) ships as v0.4.24 — the cached-token cost fix is deliberately held back because it changes what the compaction trigger measures. Tests: api 41 / aris-cli 212 + 3 e2e / runtime 225 / tools 69 / commands 5 (+13), all green under a live proxy; new-code clippy delta zero. Codex MCP (gpt-6-astra): ultra scope+design adjudication, then a 3-round implementation gate (round 1 caught the null-serialization defeat and a non-hermetic behavioral test; round 3 GO).

v0.4.22 (2026-07-12) — the skills-resync + GPT-6-Astra release. 📦 Bundle resync (pin 7e3ab67 → 7182624, 93 commits): 79 bundled skills (+meta-apply, +paper-poster-html; paper-poster retired to a redirect stub), 28 tools helpers (8 new: capture_filter, evidence_check, iteration_log, provenance, run_state, threat_scan, meta_opt/trigger_eval + sample evals), 11 new shared-references docs (fan-out-pattern, acceptance-gate, external-cadence, skill-governance, compute-env-contract, resumable-runs, evidence-precheck, injection-hygiene, capture-antipatterns, output-composition, taste-calibration); sync hardening — ARIS_SYNC_EXPECT_SHA guard (aborts before touching assets if main moved; it caught a real move on first use) + exact-inventory drift tests + the vendored posterly MIT license text now ships. 🎛 GPT-6-Astra two-tier reviewer alignment: the CLI's system-prompt nudge now passes the skills' explicit model: gpt-6-astra + per-call effort pins through (the v0.4.17 blanket "never pass a model" rule would have silently stripped deep audits from ultra to xhigh), carries the canonical capability-only fallback chain (effort-unsupported → same model xhigh, deep tier only; model-unknown → explicit gpt-5.5+xhigh; never degrade on transport-class errors; an explicit call-level override disables the chain), pins approval-policy: "never" + explicit sandbox on every fresh codex call, and makes the HTTP fallback pre-dispatch-only with parameter stripping; the HTTP LlmReview default deliberately stays gpt-5.5 pending a real smoke; gpt-5.6 family pricing (sol $5/$30, terra $2.50/$15, luna $1/$6) verified against the official page; banner/Reviewer display//reviewer are honest about primary-vs-fallback (pure-Codex setups get status + guidance instead of a fake picker). 🐛 8 verified fixes: explicit --model was silently overridden by the saved executor model (model provenance now tracked end-to-end; the 4.8→4.7 availability fallback respects explicit choices; /model and /setup re-arm it); saved models no longer leak across provider transports (blank saved models count as absent; OpenAI transport with no model source fails fast; the first-run wizard's config now actually feeds startup model resolution); --output-format json never prompts (locked by a real end-to-end binary test against a mock SSE server); Windows aris login fixed (PKCE randomness read /dev/urandom → getrandom); Windows command probing fixed (the PowerShell tool probed itself through sh; now where.exe); codex .cmd shims classified honestly (three-state probe; setup requires explicit confirmation before writing a config the MCP client can't spawn); nested config.json warns instead of silently parsing to all-defaults; NotebookEdit mints collision-fre

Auto-claude-code-research-in-sleep (wanshuiyin/Auto-claude-code-research-in-sleep)

Searching Database…

What is this?ARIS (Auto-Research-In-Sleep) is a pack of lightweight Markdown-only skills that turn coding agents like Claude Code into autonomous ML research assistants — covering idea discovery, cross-model review loops, and experiment automation. A standalone ARIS-Code CLI is also available.
Is this a framework I install, or a pack of skills for the agents I already use?Neither framework nor platform — it's Markdown-only skills with no lock-in that load into agents you already use; the README calls it a methodology you can take anywhere. For a bundled experience there's the standalone ARIS-Code CLI.
How do I load it into my agent?Drop the skills into your agent of choice — Claude Code, Codex CLI, Cursor, Trae, Antigravity, GitHub Copilot CLI, OpenClaw, or DeepSeek Harness. On DeepSeek Harness it's one command: dsh plugin --profile web add dsh-aris; otherwise grab the standalone ARIS-Code CLI.
Do I need an OpenAI API key for the cross-model review?No. Since the v0.4.17 MCP release, aris setup wires your ChatGPT subscription in as the reviewer through Codex MCP, so cross-model review works without a separate OpenAI API key.
Any gotchas worth knowing before trying it?A few: the dsh-aris plugin needs pnpm on your PATH, the built-in ARIS-Monitor widget is macOS-only, and the CLI walks a fallback chain (Opus 5 → 4.8 → 4.7) so accounts without Claude 5 access keep working untouched.
Is it built only for academic ML research?No — ARIS-Anything extends the same five-step loop (plan, draft, adversarial review, iterate, persist) to any structured research: investment due diligence, legal and market research, self-driven learning, investigative journalism, engineering retrospectives.
What does the cross-model review actually look like?One model does the work and a different one reviews it independently — typically Claude runs the research while Codex or GPT acts as reviewer. The README admits its own reviewer once proposed hashes nobody reads, which led to HERO: a ~550-token block for CLAUDE.md / AGENTS.md that bounds what the agent proposes (hashing, edge cases, rubrics, overbuild).
Can it catch an agent faking its research results?That's the Anti-Autoresearch audit: 61 signals — 46 integrity hack-patterns in 8 families, 13 AI-style impressions, and 2 advisory — compiled into a deterministic, reviewer-ready report. It relies on self-consistency and fabrication forensics rather than AI-text detection.
Besides papers, what else can it produce?ARIS-Movie-Director turns a rough story into a movie told in still frames, checked scene by scene (the reference run has 19 scenes), and the same loop draws clean method or flow diagrams. The /render-html skill has also generated 23 bilingual ML interview cheat sheets and three long-form blogs.
How do I keep an eye on long research runs?ARIS-Monitor is a built-in always-on-top macOS widget that lights up red when a session waits for your approval — it starts in about 5 seconds with no clone, pip, or browser. For more, Claude Fleet is a local read-only web dashboard for many parallel Claude Code / Codex windows with full-text transcript search.
Creator
wanshuiyin
Size
34.1 MB
Stars
17.6K
Age
7mo
Commits · 90 Days