hands-on-modern-rl README

The project's README from github.com/walkinglabs/hands-on-modern-rl. As one markdown file: README.md.

Hands-On Modern RL

From Markov decision processes and policy optimization to reasoning models, agents, and multimodal systems

Online Course PDF Download CC BY-NC-SA 4.0 License Node >= 18 VitePress

English · 中文

Train on ModelScope · Run the CartPole Notebook · ModelScope Script

Discussion Group (WeChat)

Book Features · About This Book · News · Contents · Book Structure · Experiment Code · Quick Start · Contributing

📣 Announcement

We sincerely thank everyone for your support of this tutorial! A new version is coming soon. Many sections are still being organized and refined, so we appreciate your patience. Suggestions and feedback are always welcome!

News

Note: This course was created with AI assistance and has not yet been fully reviewed. It may contain factual mistakes or code that does not run as expected. Issues and pull requests are very welcome.

Online Training Notebooks

WalkingLab is collaborating with ModelScope to provide online training environments for classic reinforcement learning experiments. A ModelScope Studio brings the experiment interface, runtime, and training entry point together on one page, so learners can start training in a browser and observe the agent without first configuring a local environment.

Every Studio has a companion notebook under code/online-experiments. The notebook imports the same training runtime as the Studio, exposes the experiment parameters, prints the full training log, plots checkpoint evaluations, and displays the learned-policy replay or result artifact.

Experiment Resource Companion notebook Live Studio
01 · CartPole PPO CPU Run Notebook Open Studio
Gymnasium Playground CPU Run Notebook Open Studio
02 · ViZDoom CPU Run Notebook Open Studio
03 · Atari / ALE xGPU Run Notebook Open Studio
04 · Board Games & Self-Play CPU Run Notebook Open Studio
05 · Multi-Agent Games CPU Run Notebook Open Studio
06 · MiniGrid Adventures CPU Run Notebook Open Studio
07 · JAX MinAtar CPU Run Notebook Open Studio
08 · ManiSkill xGPU Run Notebook Open Studio
10 · MineStudio / Minecraft xGPU Run Notebook Open Studio
11 · Unity ML-Agents xGPU Run Notebook Open Studio
12 · AI2-THOR xGPU Run Notebook Open Studio

CPU entries run on an ordinary notebook instance. Experiments 03, 08, 10, 11, and 12 require a scheduled ModelScope xGPU Notebook and check CUDA before training.

Book Features

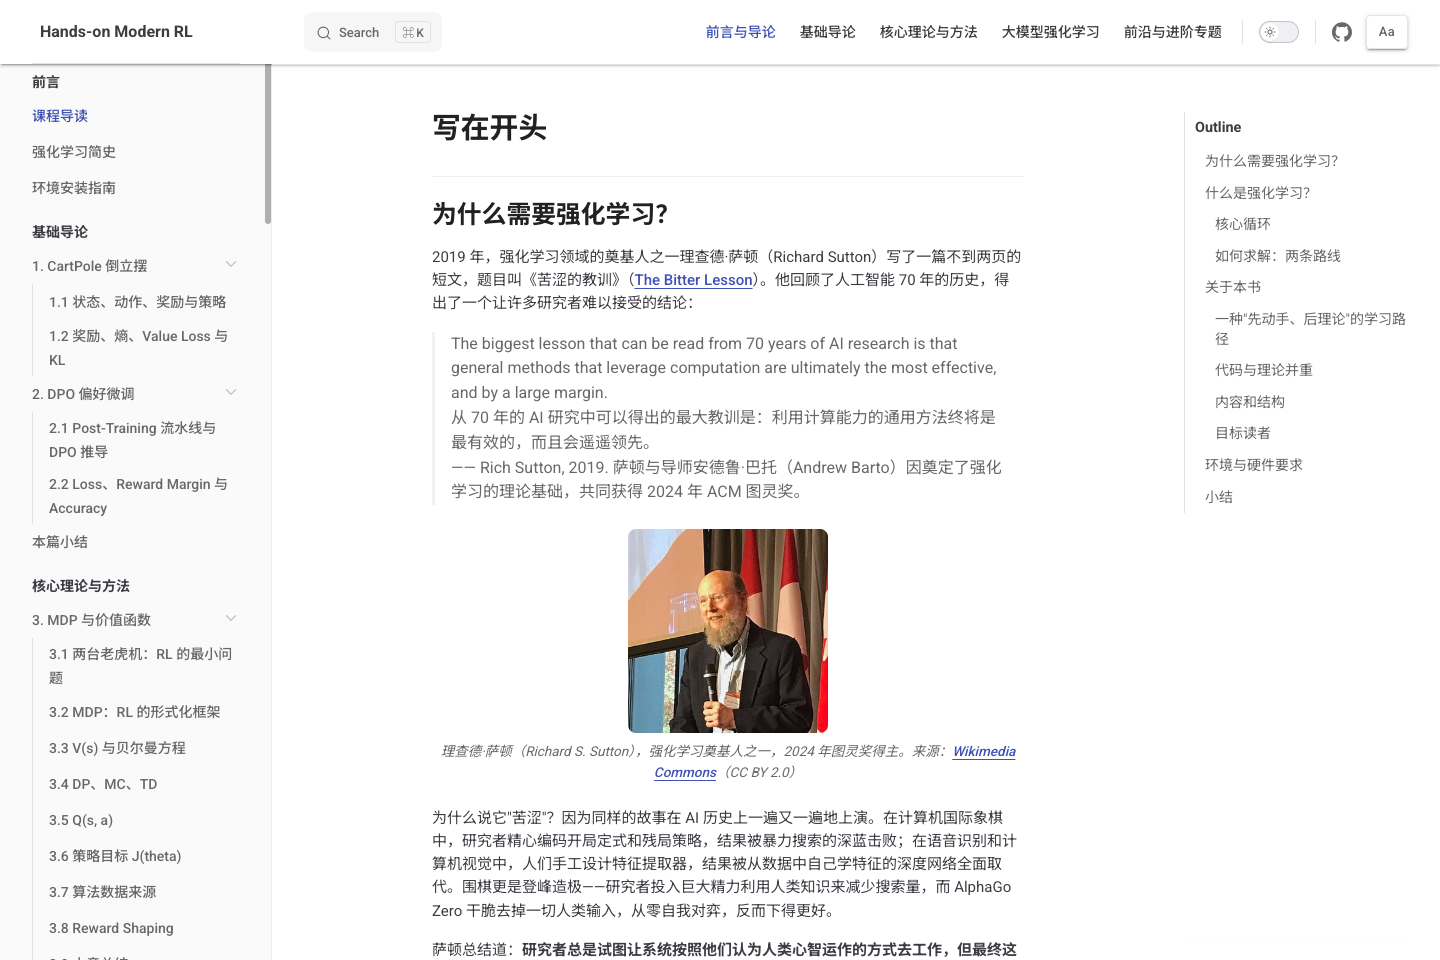
Course learning map screenshot
One continuous learning path
Begin with a CartPole trial and progress through value learning, policy optimization, and modern agents.
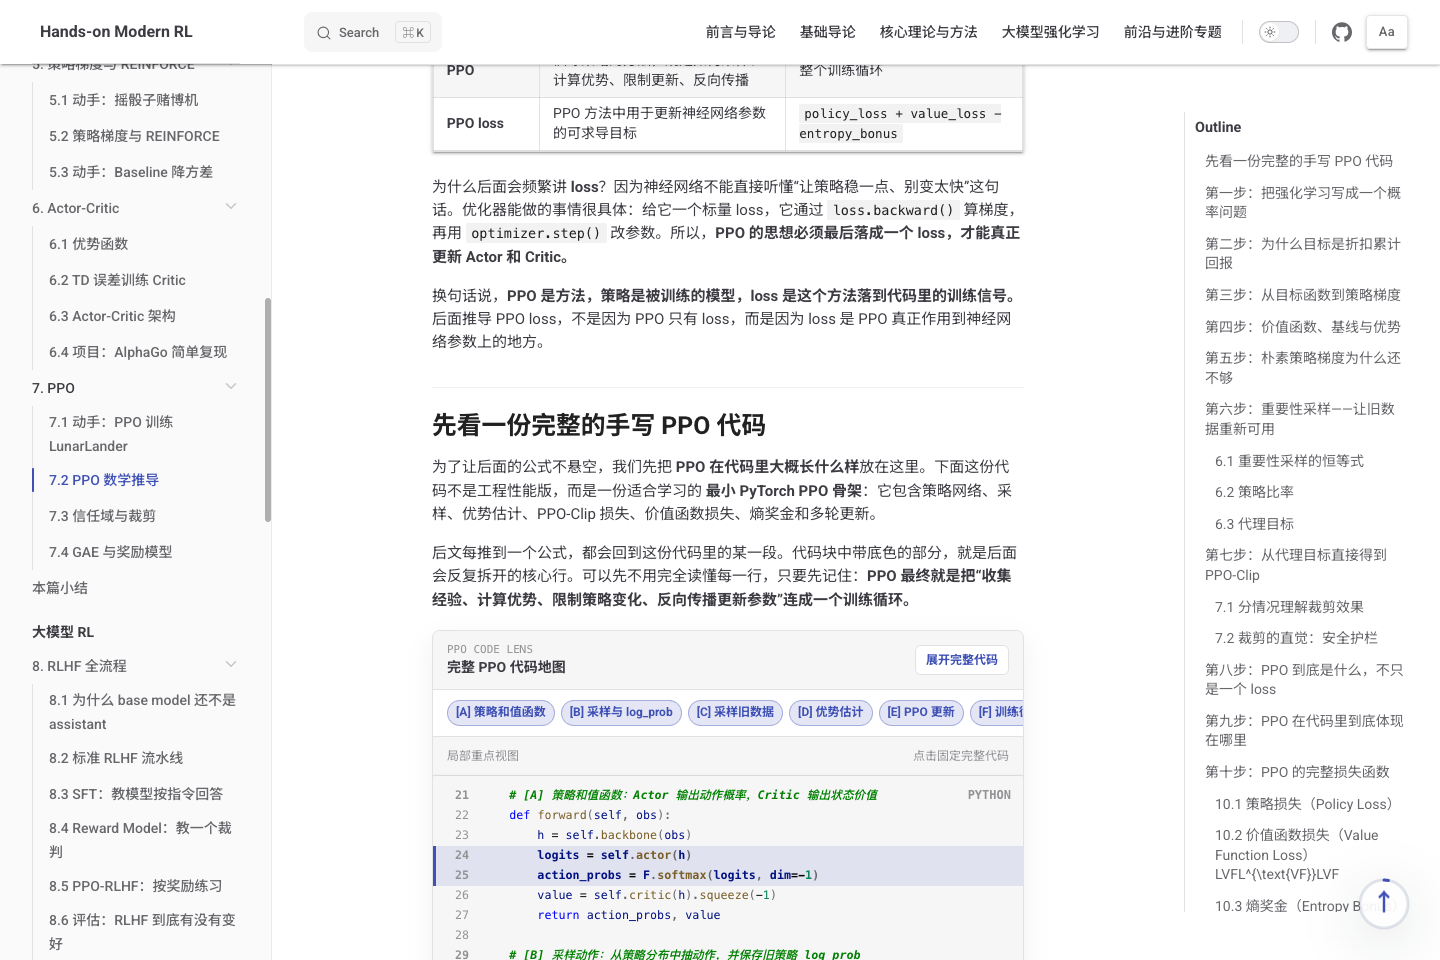
PPO code focus screenshot
Equations meet code
Key PPO, DPO, and GRPO derivations sit beside their implementations, with every tensor accounted for.
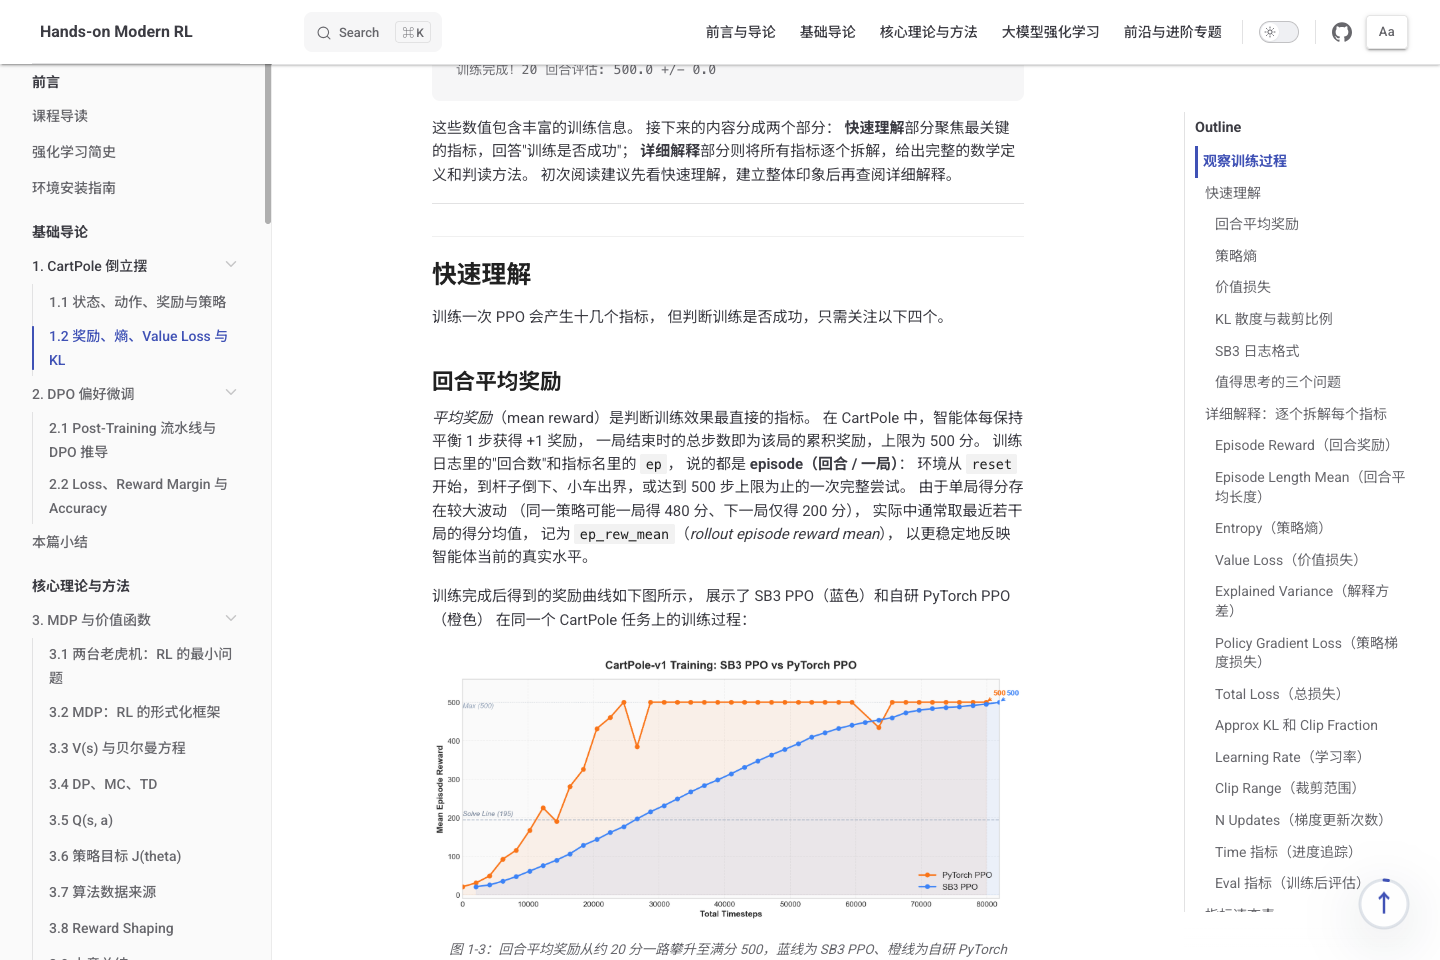
CartPole training metrics screenshot
Claims tested by experiments
Real training curves, ablations, and failure signals show when an algorithm works and when it does not.
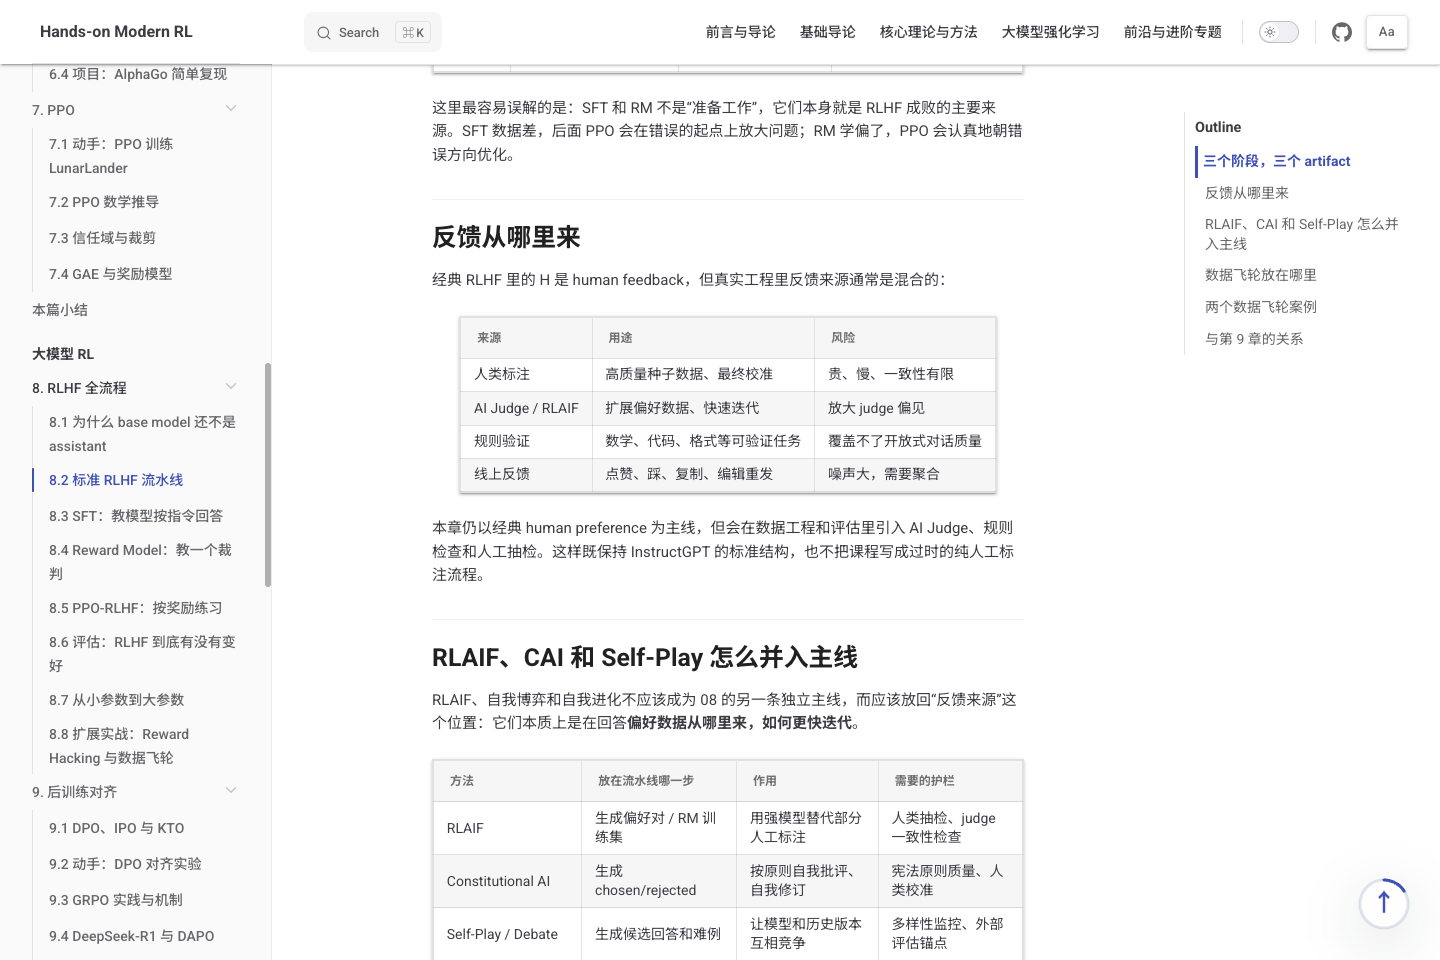
RLHF pipeline screenshot
Classic RL to language models
Policy gradients and PPO lead naturally into RLHF, DPO, GRPO, and RLVR.
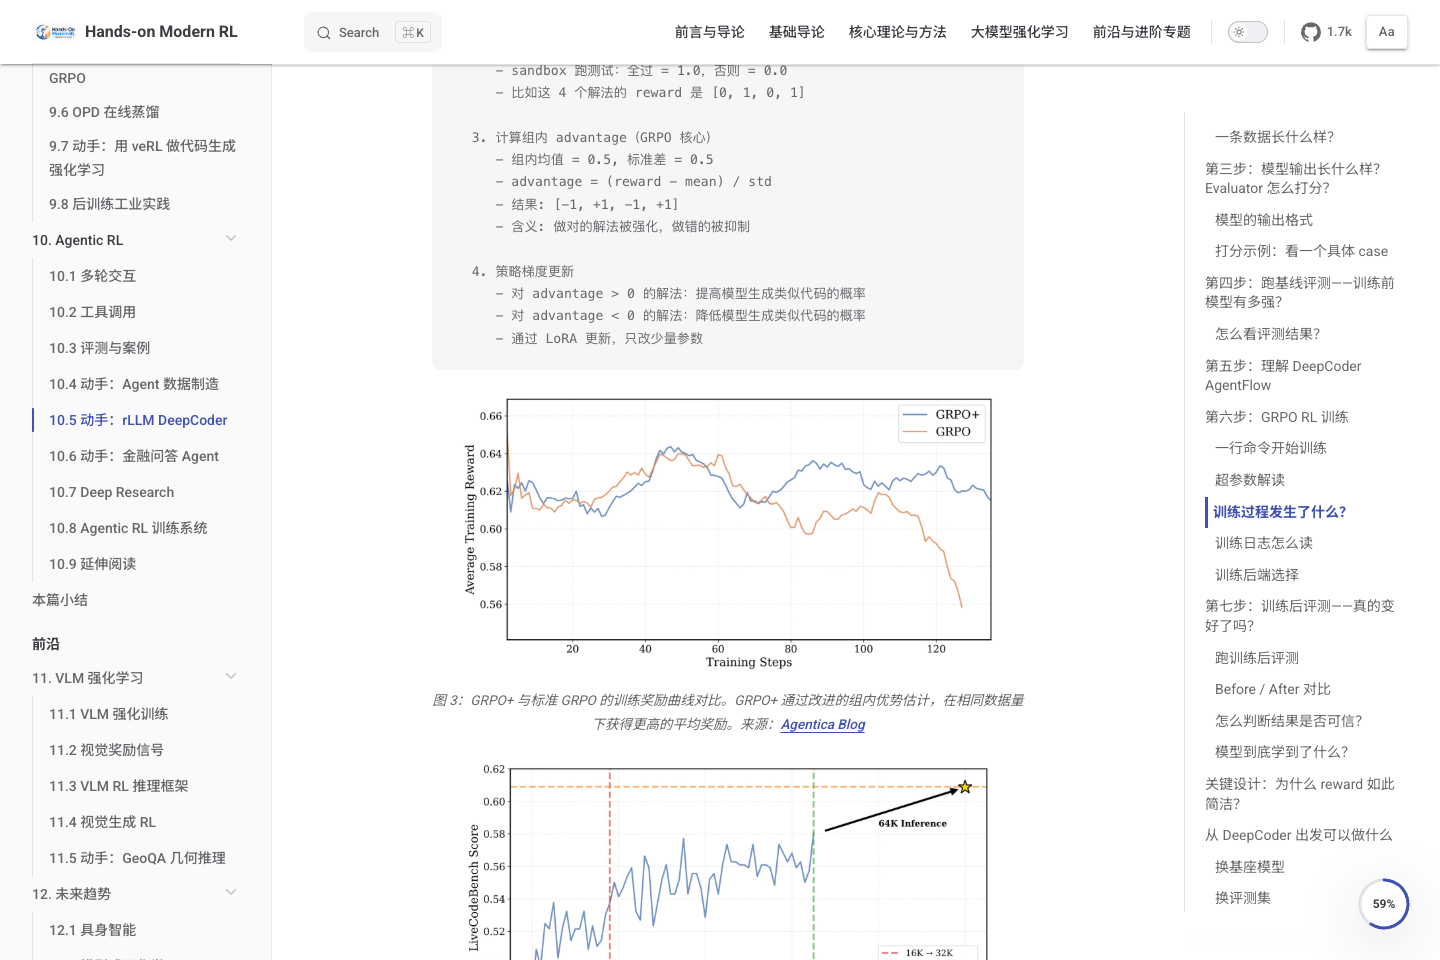
Agentic RL experiment page screenshot
Agents as sequential decisions
Tool use, browser interaction, and code repair become problems of states, actions, trajectories, and credit assignment.
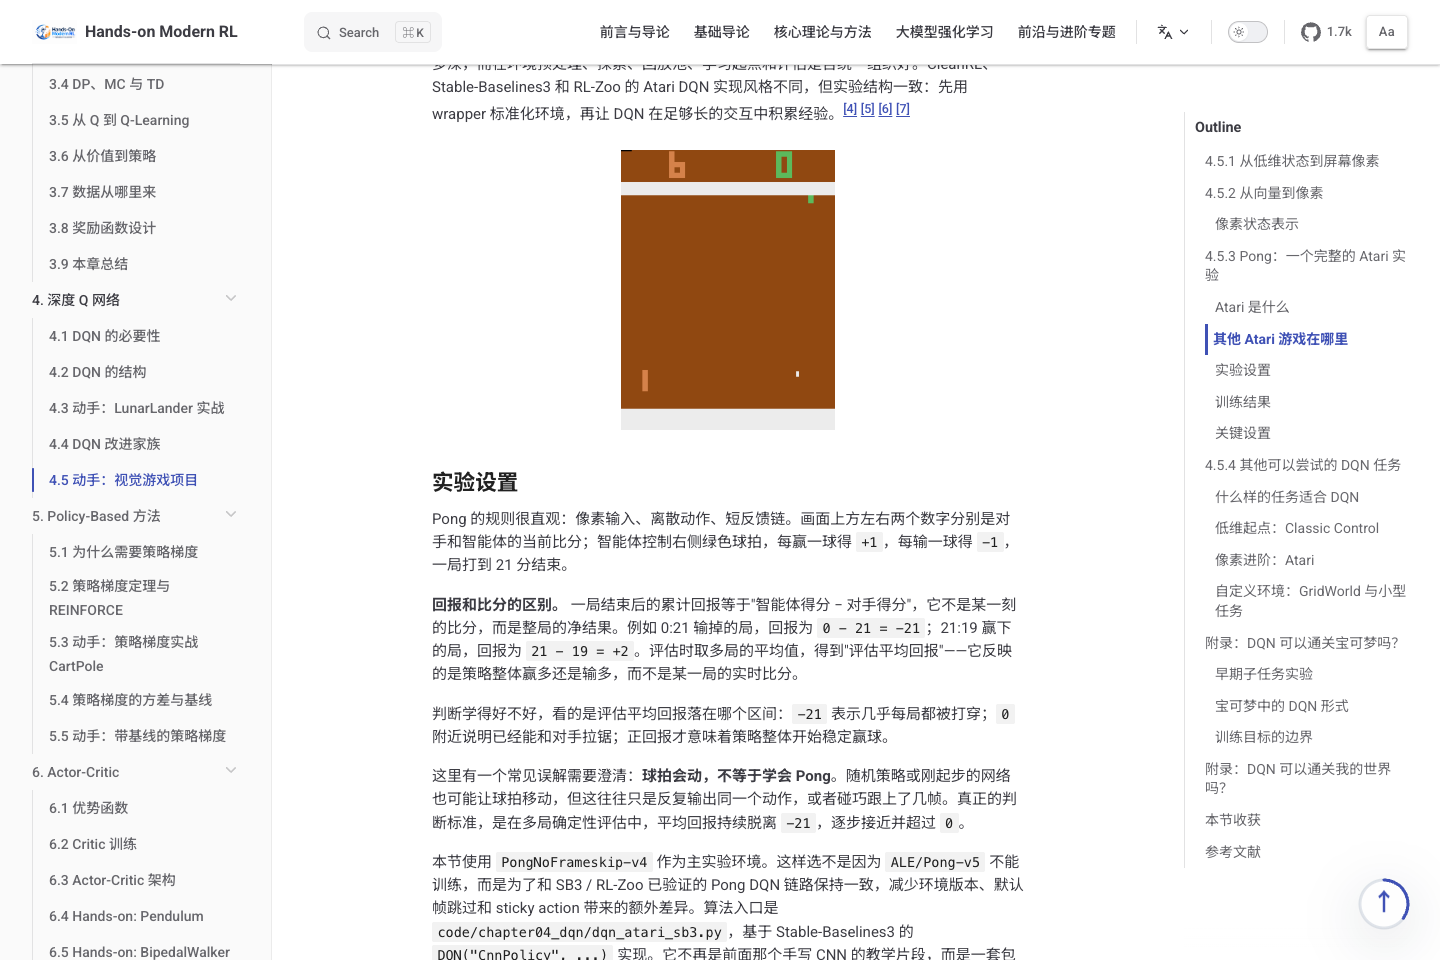
Atari Pong DQN experiment page screenshot
Phenomena before abstractions
CartPole, LunarLander, Atari, and LLM experiments pose the problem before introducing the mathematics.

[!NOTE] We hope this open course gives more learners the courage to climb toward the frontier of intelligence and solve more of the hard problems on the path to AGI.

The course is evolving quickly. We recommend focusing on chapters that are not marked as under construction; chapters still in progress may contain mistakes, and corrections or suggestions are welcome.

Help Wanted

Because compute resources are limited, we are seeking GPU support. If you can help with GPU access, please contact [email protected].

Contents

About This Book

Reinforcement learning studies a simple but difficult problem: a system acts, observes the consequences, and uses them to improve its next action. When rewards arrive late, observations are incomplete, and each update changes the distribution of future experience, the familiar supervised-learning model of inputs and labels is no longer enough. We need a language for interaction, a way to estimate long-term return, and methods that improve a policy stably from limited data.

Hands-On Modern RL follows that problem from beginning to end. CartPole and multi-armed bandits first make states, actions, rewards, and policies observable. Markov decision processes, value functions, and Bellman equations then provide a common language. From there, the book develops DQN, policy gradients, actor-critic methods, PPO, continuous control, and offline reinforcement learning. With those foundations in place, RLHF, DPO, GRPO, and RLVR become extensions of the same sequential-decision framework rather than an isolated collection of acronyms.

The second half expands the environment to tools, browsers, code repositories, vision, and audio. An action may be a passage of text, a function call, or a sequence of interface operations. A reward may come from human preference, a rule-based verifier, or a process reward model. The setting changes, but three questions run through the entire book: How should the decision process be represented? How should an outcome be credited to earlier actions? How can we tell whether a policy has actually improved?

How the Material Is Taught

Each chapter follows a problem–method–experiment–reflection rhythm. A concrete task first exposes the difficulty. The concepts and equations needed to solve it come next. Runnable code, training curves, and evaluation metrics then test the argument. The chapter closes by examining assumptions, failure modes, and the limits of the method. Mathematics explains observed behavior; experiments check the mathematics.

Implementations retain the visible skeleton of each algorithm. Readers can trace trajectory collection, advantage estimation, loss construction, and metric changes—and see how reward hacking, KL drift, entropy collapse, distribution shift, or evaluation leakage can invalidate an apparently successful run.

Who Should Read It

This book is for students, researchers, and engineers with basic machine-learning experience who want a systematic understanding of modern reinforcement learning. Readers should be comfortable with Python and basic PyTorch, and should know introductory linear algebra, probability, and calculus. The mathematical appendices rebuild these tools to the depth required by the chapters, so a separate advanced-mathematics sequence is not a prerequisite.

After completing the core chapters and labs, you should be able to:

Current Status

This repository is an active courseware project. Content is being expanded chapter by chapter, with emphasis on correctness, runnable examples, and a stable learning path.

Issues and pull requests are welcome for typo fixes, conceptual corrections, reproducibility improvements, references, and focused course extensions.

Roadmap

The course is under active development. Planned milestones:

Structure of the Book

The book contains seven parts and twenty-six chapters. Parts I–III establish the common language and algorithmic foundations of reinforcement learning. Part IV brings those tools into LLM post-training. Parts V and VI study what changes when the action space expands to tools and multimodal environments. Part VII asks how to detect failures, build trustworthy evaluations, and move the research frontier forward. The appendices provide implementation, mathematics, and engineering references.

Prologue: From Trial and Error to Modern Agents

Reading Central question
Introduction to Reinforcement Learning What does RL study, and how does the book connect classical methods to modern language models?
A History of Reinforcement Learning How did control, TD learning, DQN, AlphaGo, RLHF, and reasoning models develop?
Environment Setup How do you prepare the environments for documentation, control tasks, and LLM experiments?

Part I: The Language of Sequential Decisions

The book first makes an agent's failures and improvements observable, then develops the mathematical objects needed to describe long-term decisions.

Ch. Topic Through line
1 Starting with CartPole Use states, actions, rewards, policies, and training curves to see a complete RL loop.
2 RL Problems and Definitions Move from exploration and exploitation to MDPs, returns, trajectories, and partial observability.
3 Value Functions and Bellman Equations Express how a present action changes the future through state values, action values, and recursion.
4 Classical RL Methods Compare dynamic programming, Monte Carlo, and tempor

hands-on-modern-rl (walkinglabs/hands-on-modern-rl)

Searching Database…

Что это?Hands-On Modern RL — открытый курс и книга, ведущие учащегося от базовых концепций обучения с подкреплением через выравнивание LLM (RLHF, DPO, GRPO, RLVR) к продвинутым агентным системам и сочетающие теорию с исполняемым кодом.
Это книга, курс или библиотека кода?Это прежде всего сайт книги/курса (построен на VitePress), организованный по главам и дополненный исполняемым кодом экспериментов и ноутбуками, а не устанавливаемая библиотека.
Как начать учиться и запускать эксперименты?Читайте главы на сайте курса, затем запускайте сопутствующие Jupyter-ноутбуки в code/online-experiments или открывайте связанный ModelScope Studio прямо в браузере, чтобы тренировать без локальной настройки.
Какая подготовка и какие инструменты нужны перед стартом?Нужно свободно владеть Python и базовым PyTorch, знать начальный курс линейной алгебры, теории вероятностей и математического анализа; некоторым экспериментам также нужен доступ к GPU через ModelScope.
Контент завершён и надёжен?Курс активно дорабатывается, создан с помощью ИИ и ещё не полностью выверен, поэтому в некоторых главах могут оставаться фактические ошибки или неработающий код, а несколько глав помечены как «в разработке».
Для кого этот курс?Для студентов, исследователей и инженеров с базовым опытом машинного обучения, которые хотят системно и на практике разобраться в современном RL и его распространении на LLM и агентов.
Где можно запускать обучающие эксперименты?Эксперименты только на CPU идут в обычном экземпляре ноутбука, а требовательные к GPU (Atari/ALE, ManiSkill, Minecraft, Unity ML-Agents, AI2-THOR) требуют назначаемого ModelScope xGPU Notebook с CUDA.
Как устроена книга?В ней семь частей и двадцать шесть глав: от классических основ RL (части I-III) к пост-тренингу LLM вроде RLHF/DPO/GRPO (часть IV), затем использование инструментов, мультимодальные и эмбодиментные агенты (части V-VI) и наконец оценка и анализ сбоев (часть VII), плюс математические и инженерные приложения.
Есть ли курс на языках, кроме английского?Да, помимо полной английской версии есть полный китайский вариант, а PDF-сборки обоих изданий генерируются автоматически через CI.
Чем это отличается от простого чтения учебника по RL?Каждый алгоритм (DQN, PPO, DPO, GRPO и т.д.) сопровождается исполняемым кодом, реальными кривыми обучения и разбором режимов сбоев вроде reward hacking или коллапса энтропии, поэтому утверждения проверяются экспериментами, а не только выводятся математически.
Можно ли попробовать эксперименты без локальной настройки?Да, у каждой лабораторной есть живой ModelScope Studio, который можно открыть в браузере и сразу тренировать и наблюдать агента, помимо сопутствующего ноутбука.
Size
153 MB
Stars
4.7K
Age
6mo
Commits · 90 Days
