ShrimpReel
English | 简体中文
Built by 浅水虾 (qianshuixia).
An open-source template for "one photo → an AI video that follows a viral template" SaaS sites. Every trending keyword gets its own site: create a repo from this template, change the config, copy and media, and ship. Everything runs on Cloudflare: Workers + D1 + R2 + KV + Queues + Rate Limiting + Cron Triggers.
https://github.com/user-attachments/assets/ce92074a-2a09-4a3e-b750-4b888d12abf8
A 72-second tour, no sound (Chinese version; MP4 files in docs/media). Screens are from a local run; the demo site "Neon Shuffle AI" and its clips are placeholders.
Built with ShrimpReel
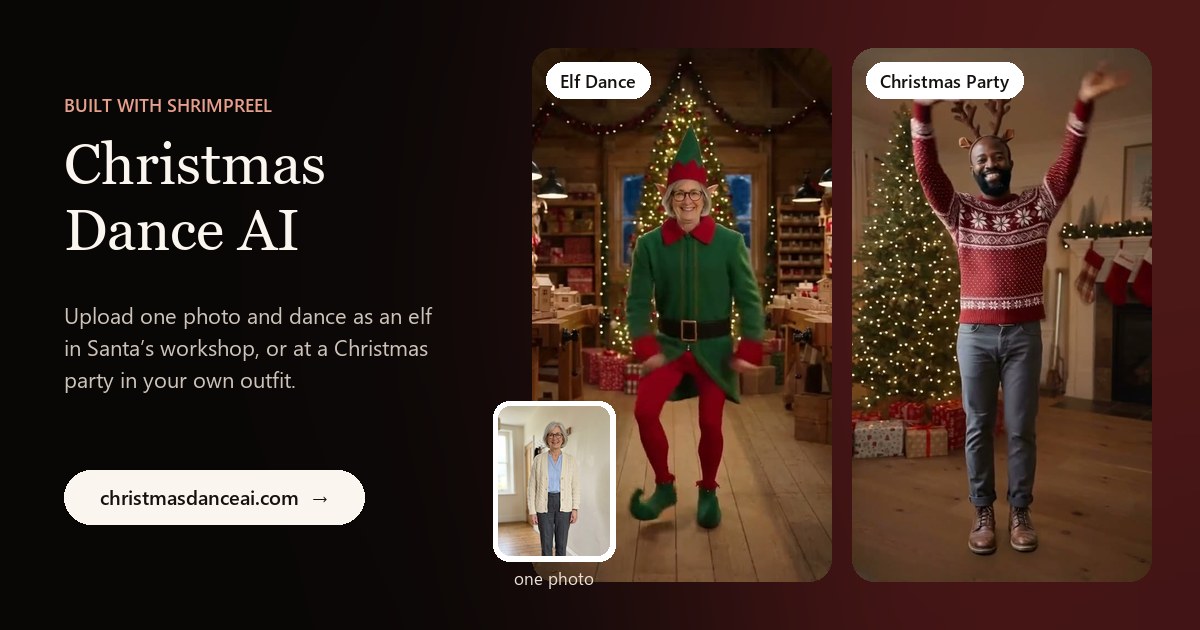
Christmas Dance AI: upload two photos for the Deck the Halls couple or kitchen duo dance, or one photo to dance as an elf in Santa's workshop or at a Christmas party in your own outfit. Four styles with soundtrack muxing (two 720p solo, two 480p duo), 20 bilingual guides (including a look-alike site comparison), Google sign-in, credit packs from $4.99 and subscriptions, all from this template.
Status: the full flow works locally (unit tests + Playwright e2e), and the site above runs it in production. The template itself is not deployed; ROADMAP.md lists what has and hasn't been verified against real services. Code comments, ROADMAP and docs/ are currently in Chinese.
- Frontend/SSR: TanStack Start (React 19) + Tailwind 4. English at
/, Chinese at /zh.
- API: Hono (
/api/*, /media/*, /sitemap.xml, /robots.txt, /llms.txt, IndexNow key file); entry point src/server.ts.
- Payments: Waffo Pancake (default) or Dodo Payments, both Merchants of Record, or Stripe (you are the merchant and handle sales tax yourself).
mock is for local dev and e2e only.
- Video: fal.ai queue API (default) or the optional yir.ai router or NanoAPI;
mock for local dev and e2e. See "Video providers" below.
- Included:
- Users and credits: Google sign-in (including One Tap), credit packs, monthly and yearly subscriptions and a credit ledger, dashboard (videos, billing, settings, redeem codes, invite link, account deletion, data export); billing shows amounts paid and refunded, orders and the ledger load page by page, and every order has a printable detail page (tax invoices come from the payment provider).
- Orders and generation: partial and full refunds that claw back credits, a generation queue with a dead-letter queue, credits returned automatically on failure.
- Try before signing in: the generator keeps the chosen photo, style and length in the browser (IndexedDB, 24 hours) through sign-in and checkout, and tells signed-out visitors their photo is kept and what the cheapest pack covering the chosen length costs. The draft is cleared once a generation is submitted or on sign-out.
- Upload from phone: on desktop the generator shows a QR code; the phone opens
/phone-upload (token only in the URL fragment), picks a photo, and the desktop picks it up within a few seconds. The photo is relayed through R2 under handoff/ (link valid for 10 minutes, one photo per code, swept by the cron after an hour) and is moderated when the desktop uploads it as usual.
- Growth: first- and last-touch attribution (UTM and ad click IDs), a visit → sign-up → checkout → paid → generate funnel, GA4 events behind a consent banner, public share pages for videos (opt-in per video, with link previews).
- Admin: overview (including provider cost and gross margin), users, orders, generations, takedowns, contact messages, payment events, emails, audit log, reports and order CSV, redeem codes, referral leaderboard, runtime settings and connection tests.
- Users: filter by status, role and paying, sort by sign-up, last login or credits; the detail page shows total paid, generation stats, orders, credit grants, the credit ledger and admin actions on that user (granted credits can have an expiry).
- Orders: search by order id, email or provider transaction id; the detail page merges payment webhooks, credit changes, admin actions and emails into one timeline, with refund, check-with-provider and mark-paid actions.
- Generations: search by job id, email or provider request id.
- Transactional email: credits added, video ready, generation failed and refunded, takedown receipts (signed-in users only) and outcomes; admins get new takedowns, deadline reminders, contact messages and payment disputes (Cloudflare Email Service, outbox with dedupe and retries).
- Compliance and safety: AI-generated label on videos plus an optional (off by default) machine-readable XMP label and free
/verify page; photos deleted after 7 days and videos after 30; takedown requests on a 48-hour queue (every video made from the same source photo is removed and the photo is blocked); upload moderation and optional frame-by-frame moderation of finished videos; the consent checkbox is recorded server-side; Turnstile on the contact and report forms.
- Payment disputes: chargebacks claw credits back and alert admins, won disputes give them back, and Stripe early fraud warnings are refunded automatically.
- Ops and security: maintenance mode, a checkout pause, the payment provider for new orders, a site-wide announcement and a daily generation cap switched from the admin without a deploy; health-check alert emails, instant payment notifications (Telegram, Feishu, Discord and more), daily D1 backups to R2, browser error reporting to Workers Logs, CSP (Report-Only, per-request nonce) and Permissions-Policy.
- Content and SEO: one-page home (How it works / What is, plus optional problem, "doing it yourself vs. this site" and spec-sheet blocks), an extensible article collection (
/guides hub, related articles), legal pages, contact form; SSR canonical, hreflang, JSON-LD and sitemap; copy is code-split per locale; npm run seo:check lints the whole site.
Release notes: CHANGELOG.md. Feature notes and plans: docs/SAAS_VIDEO_FEATURES.md and ROADMAP.md. SEO rules, keyword planning and audit results: docs/SEO_AUDIT.md. All environment variables and the launch-related site.ts fields: docs/env.md. Adding a payment provider and the webhook response-code contract: docs/payments.md. The subscription switch, plans and provider setup: docs/subscriptions.md. Conventions to follow before changing code (credits, payment fulfillment, bilingual copy, migrations, e2e): AGENTS.md. The docs/ files and AGENTS.md are in Chinese.
Local development
npm install
cp .dev.vars.example .dev.vars       # set at least SESSION_SECRET
npm run seed:local                   # apply D1 migrations and upload the mp4, jpg and m4a files in seed/templates/ to local R2
npm run dev -- --host 127.0.0.1      # http://127.0.0.1:3000
- Use npm 11.19 or newer;
devEngines in package.json warns on older versions. Running npm install with an older npm rewrites package-lock.json into a form that npm ci on CI rejects (Missing: @emnapi/core@… from lock file).
PAYMENT_PROVIDER=mock and VIDEO_PROVIDER=mock by default: buying opens a mock checkout and generating copies the template video. Nothing is charged.- Outside production the sign-in page has a "dev login" (
POST /api/auth/dev-login); in production it returns 404. Dev login, mock payments and /api/dev/* only accept direct requests from localhost: anything that came through a tunnel or proxy (with cf-connecting-ip, X-Forwarded-For or similar headers) gets 404. Someone on your LAN can fake those conditions, so don't start the dev server with --host 0.0.0.0 or expose it to the internet directly; for webhooks use scripts/webhook-proxy.mjs (see below).
MODERATION_PROVIDER=mock by default: an upload form with mockOutcome=reject simulates a rejected image. Leave TURNSTILE_SITE_KEY empty to disable Turnstile.POST /api/dev/sweep {"days": 8} (localhost only) runs retention cleanup as if N days had passed, for the signed-in user's media only.- Addresses in
ADMIN_EMAILS can open /admin; locally that is [email protected]. They are made admins when they sign in, and removing an address later doesn't take the role away: also click "取消管理员" (remove admin) on that user's page under /admin/users.
- Email is only simulated locally; check the outbox instead:
GET /api/dev/emails?to=<email>&ref=<order or takedown id> (localhost only). POST /api/dev/takedown-reminders {"takedownId": "tdr_…", "hours": 37} runs the takedown reminder check for one request as if N hours had passed.
- Windows: start with
--host 127.0.0.1, otherwise Playwright and other tools may resolve localhost to IPv6 and fail to connect. Stop the dev server before npm install, or locked .wrangler / miniflare files cause EBUSY.
drainUnreadBody in src/server.ts only runs in dev: with the current miniflare 5 beta, a Worker that responds without reading the request body breaks the next request on the same connection (500 fetch failed). After upgrading @cloudflare/vite-plugin, try removing it and run npm run test:e2e to check the CSRF tests.
Launching a site for a new keyword
Each keyword site is its own repository that tracks this template as upstream, so payment, security and framework fixes are made once in the template and merged into every site.
With Claude Code, once the site repo exists (step 1) you can just say "new hot site: Moon Hop, the moon-jump dance on TikTok". The bundled new-hot-site skill (.claude/skills/new-hot-site/) covers steps 2–4 and the local part of step 7: it writes a site brief, runs the scaffolder, sets pricing, rewrites the copy in both languages, generates placeholder media, then runs typecheck, tests, build, seo:check and an offline doctor. It only touches per-site files and never commits or deploys. Missing information (final domain, licensed media, etc.) is left as TODO(site): … comments; npm run doctor lists them and blocks a production deploy (APP_ENV=production) while any remain.
Create the site repo
git clone https://github.com/qianshuixia/shrimpreel.git moonhop && cd moonhop
git remote rename origin upstream
git remote add origin [email protected]:<owner>/moonhop.git
Don't use GitHub's "Use this template": the new repo shares no history with the template, so git merge upstream/main won't work later. Forks of a public repo can't be private, so site repos usually aren't forks either.
Run the scaffolder
node scripts/new-site.mjs --keyword "Moon Hop" --domain moonhop.ai --keywords "AI dance video,Moon Hop filter"          # dry run
node scripts/new-site.mjs --keyword "Moon Hop" --domain moonhop.ai --keywords "AI dance video,Moon Hop filter" --write  # write
It updates the following, then prints a checklist of what still has to be done by hand:
site.ts: keyword, brand, domain, email, the default style's id (styles[0].id), article slugs, secondary keywords, publish/update dates; it also clears the previous site's verification tokens, IndexNow key and analytics IDs.wrangler.jsonc: resource names and the ratelimit namespace_id; D1/KV ids are reset to placeholders.package.json: name.- Deletes
wrangler.staging.jsonc (the template's own staging config).
Adjust credit packs (packages), the subscription switch and plans (subscriptionsEnabled, plans; set the switch to false to sell packs only), durations and video.falModel in src/config/site.ts as needed. A pack can set anchorPriceCents to show a struck-through regular price and a discount. Use only a price that pack was actually sold at (EU rules use the lowest price in the 30 days before the reduction); new sites usually leave it unset. Each pack on the pricing page shows "Makes N × Xs or M × Ys videos" (the longest and shortest lengths it can afford), and the grid follows the pack count when there are 2 or 4 packs. You can add a single-video pack that covers exactly the shortest length (for example 6 credits for $4.99) for people who want just one clip; when the balance is short, the generator's main button checks out the cheapest pack that covers it instead of sending the user to the pricing page first.
Rewrite the copy in src/content/en.ts and src/content/zh.ts. Copy uses variables such as {keyword}. For every keyword, rewrite at least hero, whatIs, ideas, FAQ and both articles, and cover the secondary keywords naturally in the home page body. Rewrite the home page problem and withWithout blocks for the new trend, or set them to null to hide them. The specs block lists one fact per row (photo requirements, lengths, format, price); AI answers often quote such spec lists, so keep the values in line with site. Swapping only the keyword across the whole site can be treated by Google as scaled content abuse.
- Articles: add an entry to
articles in site.ts (key, slug, publish and update dates, optional related), then add the same key under articles in every locale's content file; typecheck fails if one is missing. The optional cover is a 1200×630 image under public/, shown on the /guides card and at the top of the article and used as that article's og:image and Article image; without it the card has no image and sharing falls back to public/og.png. node scripts/article-cover.mjs public/guides/<slug>.jpg --tag Guide --title "Short headline" public/demo/original.mp4@1 public/demo/ai1.mp4@2 builds one from frames of the site's own videos (or an image), with a headline, a tag and the brand name; --layout picks row, before-after (photo → video), vs, hero, grid or full (one wide image). Options are listed at the top of the script; it renders with Playwright's Chromium and needs ffmpeg for video frames. The article lives at /<slug> and is added to /guides, the sitemap and other articles' related links automatically. Optional style (a styles[].id) shows that style's original and AI sample videos after the intro and makes the closing button open /?style=<id>#create with the style preselected; an unknown id is ignored. Optional faq ([{ q, a }] on the article's content in each locale) renders a collapsible FAQ after the body and adds FAQPage structured data. A section can also carry an optional table ({ head, rows }), rendered after its paragraphs with the first column as row headers; use it for comparisons and spec sheets. trend and howTo are linked from the home page; keep them. Aim for at least one pillar page of 1,200+ words plus 4–6 long-tail pages (tutorials, ideas, troubleshooting, comparisons) per site.
- Copy is code-split per locale, so the browser only downloads the current language (legal pages included). Components call
getContent(locale) as usual; only code that needs copy outside the root route and before rendering has to await loadContent(locale) first.
- Adding a locale: register it in
LOCALES and LOCALE_META in site.ts, create src/content/<locale>.ts (same type as en.ts), and add a dynamic import to loaders in src/lib/i18n.ts. Email templates are typed per locale as well, so typecheck lists what else needs translating.
Replace the media
seed/templates/<style id>-<seconds>s.mp4: source videos for generation, one per duration for every style (site.styles[].sources); upload them to templates/ in R2 after deploying.seed/templates/<style id>-<seconds>s.m4a (optional): background music, one AAC file per duration for a style (site.styles[].music, keys = durations[].id, null by default). When set, after the video is stored in R2 the server replaces the video's audio track with this music in pure JS (mediabunny; the video stream is copied packet by packet, not re-encoded), before moderation and the XMP label. Each file should be as long as its duration and fade out at the end; audio past the video's end is dropped. Upload them like the source videos, with --content-type audio/mp4. On any failure (file missing in R2, video over 48 MB, unreadable MP4) the video is left as the provider made it and the job still succeeds. You must own a commercial license for the music (for example AI music you generated under terms that allow commercial use), never someone else's song. If your site copy says the videos are silent, update it.public/demo/*: home page demo videos and posters. They must be your own or licensed, with the source credited in site.styles[].examples.*.credit.public/og.png, public/favicon.svg.- Multiple dance styles (optional): add more entries to
site.styles. Each has an id (written to generations.template_id, don't change it once published), sources (one file per durations[].id), prompt (null = video.yir.prompt / video.nanoapi.prompt), scene (yir two-step { frame, prompt }, null = single step) and examples (original, aiVersions, madeWith). Optional per style: photos: 2 (a two-person style: photo 1 is the person on the left of the source video, photo 2 the right; the generator shows two upload zones), provider ('fal' | 'yir' | 'nanoapi', pins the style to one provider instead of VIDEO_PROVIDER; its secrets must be set too) and durations ([{ id, seconds, credits, isFull? }], this style's own length options instead of site.durations; ids must be unique across the site, and sources and music are keyed by them). photos: 2 needs a provider that takes several images, currently only nanoapi; fal and yir fail such a task. The first style is the default (used when a request has no styleId). Set site.featuredStyleId to another style's id to feature it: the home hero tabs and the generator select it by default and list it first, for example a new trend style. Add styles['<id>'] = { name, tagline } to en.ts and zh.ts. With one style the UI shows no style picker; with several, the generator gets a picker (/?style=<id> preselects), the home hero gets style tabs and "Made with" shows one row per style.
node scripts/generate-placeholder-media.mjs (requires ffmpeg) regenerates original placeholder media, named after site.styles[].sources and the brand. Delete the old style's files from seed/templates/ afterwards.
Set vars in wrangler.jsonc: SITE_URL, APP_ENV=production, PAYMENT_PROVIDER, VIDEO_PROVIDER, MODERATION_PROVIDER, TURNSTILE_SITE_KEY, ADMIN_EMAILS, EMAIL_FROM, *_PRODUCTS, GOOGLE_CLIENT_ID; write the D1/KV ids back after creating the resources (see below).
Create products with your payment provider: one one-time product per credit pack and one subscription product per plan, with the product ids in WAFFO_PRODUCTS, DODO_PRODUCTS or STRIPE_PRODUCTS (Stripe takes Price ids, price_...), e.g. {"starter":"prod_xxx","party":"prod_yyy","squad":"prod_zzz","monthly":"prod_aaa","yearly":"prod_bbb"}. Waffo subscriptions also need WAFFO_STORE_ID for the customer portal; with the subscription switch off, the setup scripts skip plan products. For Waffo, node scripts/waffo-setup.mjs --store STO_xxx --apply creates them in bulk; for Dodo, node scripts/dodo-setup.mjs --apply --write-dev-vars (add --webhook <url> to also create the webhook and write its signing secret to .dev.vars; when several sites share one Dodo business, add --brand <brand_id> so the products belong to this site's brand and checkout shows its name and logo); for Stripe, node scripts/stripe-setup.mjs --apply --write-dev-vars with the same --webhook option. Prices on the site are display-only; the provider's dashboard is what actually gets charged, so keep them in sync.
Verify locally: npm run typecheck && npm test && npm run test:e2e && npm run seo:check, then deploy (npm run deploy runs the pre-deploy check first, see below).
After launch
- Run
npm run seo:check -- --base https://<domain> --production.
- Verify the site in Search Console and Bing Webmaster Tools and submit
https://<domain>/sitemap.xml.
- If
site.seo.indexNowKey is set, run npm run seo:indexnow -- --submit.
- With Claude Code, the
launch-audit skill runs these checks and the remaining launch checklist in one go (see "Deploying to Cloudflare").
Merging template updates into a site
With Claude Code, just say "sync the template". The sync-upstream skill (.claude/skills/sync-upstream/) prints a sync plan, merges, resolves conflicts by the layers below, fills in local config and runs the full verification. It leaves the merge staged for you to review before committing. If the site doesn't have the skill yet, have it read the template's copy: git show upstream/main:.claude/skills/sync-upstream/SKILL.md (on Windows Git Bash, prefix with MSYS_NO_PATHCONV=1).
By hand:
git fetch upstream
git show upstream/main:scripts/sync-plan.mjs > .tmp/sync-plan.mjs && node .tmp/sync-plan.mjs   # sync plan, read-only
git merge --no-ff upstream/main
npm install && npm run typecheck && npm test && npm run test:e2e
npm run db:migrate:remote   # before deploying, if the template added files to migrations/
The plan uses the template's latest scripts/sync-plan.mjs and lists the sync base, new template commits, changes grouped by layer (shared code / site layer / removed in sites / lockfile), files changed on both sides, shared files the site has changed, new migrations, and new vars and secrets. --json prints machine-readable output.
The base is git merge-base HEAD upstream/main, so sync only with git merge. Squashing, rebasing or cherry-picking template commits leaves the base where it was, and the next plan lists already-merged commits again.
End the merge commit message with Template-sync: <template commit sha> (the plan prints it); git log --grep "Template-sync:" lists past syncs.
Keep site-specific changes in src/config/site.ts, src/content/*, public/*, seed/, wrangler.jsonc and the name in package.json. Keep everything else identical to the template: fix shared code in the template and merge it into each site rather than patching one site.
When those files conflict, keep the site's values and take the template's new keys; typecheck reports missing copy keys.
If the template changed wrangler.staging.jsonc, the site gets a modify/delete conflict; resolve it with git rm wrangler.staging.jsonc.
Deploying to Cloudflare
Create the resources once per site (names must match wrangler.jsonc):
npx wrangler d1 create <name>                  # put the database_id in wrangler.jsonc
npx wrangler r2 bucket create <name>-media
npx wrangler kv namespace create <name>-kv     # put the id in wrangler.jsonc; titles are unique per account, don't call them all KV
npx wrangler queues create <name>-jobs
npx wrangler queues create <name>-jobs-dlq
npm run db:migrate:remote
npx wrangler r2 object put <name>-media/templates/<file>.mp4 --file seed/templates/<file>.mp4 --content-type video/mp4 --remote
npx wrangler r2 object put <name>-media/templates/<file>.m4a --file seed/templates/<file>.m4a --content-type audio/mp4 --remote   # background music, if any
ratelimits[].namespace_id must be unique within an account; don't share the same numbers across sites.- Secrets:
SESSION_SECRET, GOOGLE_CLIENT_SECRET, WAFFO_MERCHANT_ID, WAFFO_PRIVATE_KEY, DODO_API_KEY, DODO_WEBHOOK_SECRET, FAL_KEY; with Stripe, STRIPE_SECRET_KEY and STRIPE_WEBHOOK_SECRET; optionally YIR_API_KEY (VIDEO_PROVIDER=yir), NANOAPI_API_KEY (VIDEO_PROVIDER=nanoapi), OPENAI_API_KEY (image moderation) and TURNSTILE_SECRET_KEY. Set them one by one with npx wrangler secret put <NAME>, or sync them in one go with scripts/sync-secrets.mjs:cp .dev.vars.example .dev.vars.production # fill in production values; .dev.vars.* is gitignored
node scripts/sync-secrets.mjs # plan only: new, existing, remote-only, still missing; never prints values
node scripts/sync-secrets.mjs --apply # write the secrets the Worker does not have yet
- Values go to
wrangler secret bulk over stdin, never through a temp file, and wrangler's output is redacted before it is printed.
- Existing secrets are not overwritten by default (rotating
SESSION_SECRET signs everyone out and invalidates signed image URLs); add --overwrite to replace them. Secrets that exist only on the Worker are listed, never deleted.
- It refuses to write when the file is not gitignored, a key is not in
.dev.vars.example or is a var, a value is empty or still the placeholder, or SESSION_SECRET is weak. If the remote list cannot be read (not logged in, or the Worker does not exist yet on the first deploy) it needs --overwrite; wrangler creates the Worker if it is missing.
- Staging:
node scripts/sync-secrets.mjs -c wrangler.staging.jsonc --file .dev.vars.staging.
SESSION_SECRET signs the photo URLs given to the video provider and the video provider callback token. Generate it with openssl rand -hex 32. In production and staging, a missing value, one shorter than 32 characters or the value from .dev.vars.example is refused: jobs can't be submitted (they are failed and refunded after the queue retries, and Workers Logs names the cause) and /media/uploads/* returns 503.
- Also add the R2 lifecycle rules described under "Compliance and content safety".
- The sending domain must be onboarded in Email Service; see "Transactional email".
- Pre-deploy check:
npm run doctor. npm run deploy runs it first and stops on errors.
- It checks
APP_ENV, that SITE_URL matches site.domain, leftover mocks, the secrets required by the selected payment, video and moderation providers, that *_PRODUCTS covers every credit pack, placeholder bindings and resource ids, the Cron trigger and dead-letter queue, unfilled TODO(site) markers in the site files, uncommitted git changes (production fails unless --allow-dirty is passed), and unapplied migrations on the remote D1.
- Secrets are checked by name only, via
wrangler secret list; values are never read. wrangler must be logged in. On the first deploy the Worker does not exist yet, so set secrets first (wrangler secret put or sync-secrets --apply --overwrite; both create the Worker). --offline skips every remote query, and -c wrangler.staging.jsonc checks the staging config.
- The "Launch config check" card on the admin overview runs the same rules (in
src/server/config-health.ts) against the runtime env, including the strength of SESSION_SECRET. It only lists problems and never shows values.
- Deploy with
npm run deploy. Attach a custom domain to the Worker in the Cloudflare dashboard; SITE_URL and site.domain must match it (canonical URLs, the sitemap and the CSRF same-origin check depend on it).
- When the site goes live, set the
vars in wrangler.jsonc to production values (APP_ENV=production, the real domain, real providers). The dev server (local dev, e2e, CI) doesn't use them: LOCAL_DEV_VARS in vite.config.ts swaps the environment, domain, providers, payment provider modes (always test), admins, sender address, Google and Turnstile for dev values, so dev login and mocks keep working. To try a real provider locally, override it in .dev.vars.
- With
APP_ENV=production or staging, checkout, generation and upload return 503 if they are still configured with mock, and dev login, the mock payment endpoint and the /checkout/mock page return 404. robots.txt only allows crawling in production.
- Post-deploy smoke:
SMOKE_BASE_URL=https://<domain> npm run test:smoke; add SMOKE_EXPECT=staging for staging.
- Deploying from GitHub Actions: in the site repo, copy .github/workflows/deploy.yml.example to
deploy.yml. A manual run does typecheck, unit tests, offline doctor, db:migrate:remote, npm run deploy, then the post-deploy smoke (report uploaded as an artifact).
- Under Settings → Environments create
production (Required reviewers recommended) with CLOUDFLARE_API_TOKEN and CLOUDFLARE_ACCOUNT_ID. Start the token from the "Edit Cloudflare Workers" template and add Account-level D1 Edit and Queues Edit, which the template lacks.
- Runtime secrets never pass through CI; sync them locally with sync-secrets. First-deploy steps (creating resources, uploading source videos, binding the domain) are also done locally.
- If the smoke fails, the new version is already live: read the artifact report and
npx wrangler rollback if needed. Migrations are not rolled back, so keep them compatible with the previous code.
- Launch audit: with Claude Code, say "launch audit". The
launch-audit skill (.claude/skills/launch-audit/) runs the pre-deploy checks (typecheck, test, build, doctor, TODO(site)) and the live checks (seo:check, test:smoke, HTTPS and R2 source videos, mobile Lighthouse and screenshots), then goes through the manual items (webmaster tools, a real payment and refund, sending domain, R2 lifecycle, Google OAuth and so on). It writes .tmp/launch-audit/<date>/report.md with one of three verdicts: ready, ready with follow-ups, or not ready. It is read-only: no deploys, migrations or secret writes.
- It only sends GETs and POSTs that must be rejected: no sign-in, no orders, no writes, so it is safe to run against production at any time. The browser user agent carries a bot marker so visits stay out of the traffic report, and if dev login turns out to be on it fails right away without calling the dev endpoints.
- It checks that every page in the sitemap returns 200 without script errors; the English and Chinese home pages (including dark mode) hydrate; dev login is off and the payment provider is not mock; dev and mock endpoints and the
/checkout/mock page return 404; cross-site POSTs are blocked; unsigned payment and video provider webhooks return 401; security headers are present (HSTS on https); robots.txt matches the environment.
- The report, plus traces for failures, goes to
.tmp/smoke-prod/.
- Once the custom domain works, set
"workers_dev": false and "preview_urls": false in the site's wrangler.jsonc. Otherwise the production Worker also answers on *.workers.dev, outside any WAF or rate-limiting rules on your domain, and each version gets a public Version URL that runs that version's code with the same D1 and R2. The template ships with workers_dev on so a new site is reachable before its domain is attached.
Template staging (workers.dev)
Without a domain, wrangler.staging.jsonc deploys the template itself to https://video-template-staging.<subdomain>.workers.dev to check real bindings, Google sign-in, payment providers in test mode and video provider callbacks.
APP_ENV=staging: like production, mocks and dev login are disabled and cookies are Secure, but robots.txt blocks crawling. Canonical URLs still point at site.domain.- All resource names end in
-staging, separate from the production site. tests/unit/staging.test.ts checks that its bindings and var keys match wrangler.jsonc. new-site deletes this file.
- No transactional email (
EMAIL_FROM is empty) and no image moderation by default (MODERATION_PROVIDER=none).
npx wrangler d1 create video-template-staging                # put the database_id in wrangler.staging.jsonc
npx wrangler r2 bucket create video-template-staging-media
npx wrangler kv namespace create video-template-staging-kv   # put the id in wrangler.staging.jsonc
npx wrangler queues create video-template-staging-jobs
npx wrangler queues create video-template-staging-jobs-dlq
npx wrangler r2 bucket lifecycle add video-template-staging-media expire-uploads uploads/ --expire-days 8
npx wrangler r2 bucket lifecycle add video-template-staging-media expire-outputs outputs/ --expire-days 31
npx wrangler d1 migrations apply DB --remote -c wrangler.staging.jsonc
npx wrangler r2 object put video-template-staging-media/templates/<file>.mp4 --file seed/templates/<file>.mp4 --content-type video/mp4 --remote
npx wrangler r2 object put video-template-staging-media/templates/<file>.m4a --file seed/templates/<file>.m4a --content-type audio/mp4 --remote   # background music, if any
npm run doctor -- -c wrangler.staging.jsonc                 # pre-deploy check
npx vite build --mode staging && npx wrangler deploy         # deploy reads the staging config from the build output
node scripts/sync-secrets.mjs -c wrangler.staging.jsonc --file .dev.vars.staging --apply   # or wrangler secret put <NAME> -c wrangler.staging.jsonc one by one
SMOKE_BASE_URL=https://video-template-staging.<subdomain>.workers.dev SMOKE_EXPECT=staging npm run test:smoke   # post-deploy smoke
- Except for
deploy, pass -c wrangler.staging.jsonc to every staging wrangler command: without it, commands such as deploy follow the config of the most recent build. npm run deploy rebuilds with wrangler.jsonc first.
- For the callback URLs below, replace
<domain> with the workers.dev host. Use only test stores with Waffo and Dodo, and a Stripe sandbox.
Third-party callback URLs
| Service |
Where |
URL |
| Google OAuth |
Google Cloud Console → Authorized redirect URIs |
https://<domain>/api/auth/google/callback |
| Waffo Pancake |
Dashboard → Settings → Webhooks |
https://<domain>/api/webhooks/waffo |
| Dodo Payments |
Dashboard → Webhooks |
https://<domain>/api/webhooks/dodo |
| Stripe |
Developers → Webhooks (or stripe-setup.mjs --webhook) |
https://<domain>/api/webhooks/stripe |
| fal.ai |
Added by the code |
https://<domain>/api/webhooks/fal |
| yir.ai |
Added by the code (https URLs only; local dev relies on polling) |
https://<domain>/api/webhooks/yir |
| NanoAPI |
Added by the code (https URLs only; local dev relies on polling) |
https://<domain>/api/webhooks/nanoapi |
- Waffo:
WAFFO_ENVIRONMENT is test or prod. Webhooks are verified with Waffo's public RSA key (bundled in src/server/payments/waffo.ts), so no secret is needed. WAFFO_PRIVATE_KEY accepts PKCS1/PKCS8 and can be a single line with \n.
- Refunds are asynchronous: the admin action only returns a ticket
TKT_; the PSP creates REF_ and sends refund.succeeded later, which took 12–22 minutes in test mode. Credits are clawed back when the webhook arrives.
- Each payment can be refunded once (partial allowed), within 14 days of payment. The admin blocks this up front with
waffo_refund_exists / refund_window_expired.
- If a webhook is lost, use "record only" with the
REF_ refund id (TKT_ is rejected, otherwise the late webhook would claw back credits a second time).
- Webhooks are delivered by Upstash QStash and retries only go to the URL set at creation, so use a stable domain.
- Testing real webhooks locally:
node scripts/webhook-proxy.mjs --port 3100 forwards only POST /api/webhooks/{waffo,dodo,stripe}; point the tunnel at it instead of exposing the dev server. Pinggy works (ssh -p 443 -R0:127.0.0.1:3100 [email protected], 60 minutes on the free plan); localhost.run dropped often. To run the checkout and webhooks end to end with sandbox e2e, see docs/payments.md.
- Dodo:
DODO_ENVIRONMENT is test or live. Webhooks are verified per Standard Webhooks; DODO_WEBHOOK_SECRET is the whsec_... value from the dashboard.
- API keys are scoped per resource:
dodo-setup.mjs needs Products write, plus Webhooks write with --webhook; at runtime the key needs Checkout sessions and Refunds write, plus read access to Checkout sessions and Payments for order reconciliation; selling subscriptions also needs Subscriptions write (cancel and undo), Customers write (customer portal) and Subscriptions read.
- Merchants can refund within 30 days of payment, in several partial refunds, but only one at a time (docs). After 30 days the admin returns
refund_window_expired.
- Refunds are paid from the merchant wallet. Each payment is credited only after taxes and fees, which took about 4–5 minutes in test mode. With an insufficient balance Dodo returns 409 "Insufficient funds in wallet", shown in the admin as
payment_provider_conflict. Full refunds on a new store or right after a payout often fail for this reason.
- In test mode the refund API returns
succeeded immediately and refund.succeeded arrives about 2 seconds later. Credits are still clawed back on the webhook.
- Webhooks are delivered by Svix. Payment events echo the metadata (
orderId etc.); refund events don't, so the order is looked up by payment_id. If the tunnel changes domain, update the URL with --webhook-id; the signing secret stays the same.
- Both successful and failed payments return to
return_url with payment_id, status and email (the buyer's email) appended. GA4's page_location has the email stripped.
- The merchant name on the checkout comes from your Dodo business registration; change it to the brand name before going live.
- Stripe:
STRIPE_ENVIRONMENT is test or live and must match the key prefix (sk_test_ / sk_live_) and the webhook's livemode. STRIPE_PRODUCTS maps packs and plans to Price ids. Webhooks are verified with STRIPE_WEBHOOK_SECRET (whsec_...), then checkout sessions and invoices are fetched again with the pinned API version before crediting.
- Stripe is not a Merchant of Record: you are responsible for sales tax and invoices. Refunds have no fixed window and can be partial several times; they are paid from your Stripe balance and wait as pending when it is short.
- Subscriptions are credited on
invoice.paid. The customer portal only opens after you save its settings once in Settings → Billing → Customer portal. Restricted keys (rk_) need the permissions listed under "Stripe" in docs/payments.md.
- fal, yir, NanoAPI: the webhook is only a "go check now" signal; results are always fetched again with
FAL_KEY, YIR_API_KEY or NANOAPI_API_KEY. A Cron every 5 minutes also polls stuck jobs and fails them (with a credit refund) after 45 minutes.
Design notes
- Themes:
site.theme picks the site's look and is set on <html data-skin>; visitors still switch light / dark. classic (default): warm paper, magenta accent, serif headings, pill buttons. acid: zinc black / cream, lime accent, bold sans headings, small-radius buttons. Colors, fonts and radii are CSS variables in src/styles.css; to add a theme, register it in src/lib/theme.ts and define both a light and a dark set (tests/unit/theme.test.ts checks).
- The analytics consent card (only with
ga4Id or clarityId set, and only shown automatically to visitors from the EEA, the UK, Switzerland or an unknown country) sits in the bottom-right corner and doesn't cover content; "Accept" and "Reject" are the same size, and × only hides it for this page view without recording a choice.
/llms.txt is generated from site and the English copy: key facts (input, styles, lengths and cost, packs and plans, background music when a style has it, no visible watermark, refunds, retention, sign-in), pages, guides and legal pages. Facts the config can't express, such as accepting pet photos or not being a similarly named site, go in site.seo.llmsFacts.- Footer "Ask AI": links
/llms.txt and shows ChatGPT, Claude, Perplexity, Gemini (Google AI Mode) and Grok buttons that open a pre-filled question (footer.askAiPrompt, with the home page and llms.txt URLs) in a new tab, with nofollow.
- Credits: every change writes a ledger entry with a unique
idempotency_key (order:<id>, order_refund:<id>, generation:<id>, …) in the same D1 batch as the grant and balance updates, so a duplicate credit rolls back as a whole.
- Grants: every credit is a grant (
credit_grants) that may expire. Purchased credits never expire; the sign-up bonus expires after the validity in runtime settings (default site.signupBonusValidDays, 0 = never); admins can set a validity of 1–3650 days when granting credits.
- Spending takes the grant that expires soonest first and never-expiring grants last, recording how much came from each grant in
credit_allocations. Allocation runs in SQL: insufficient credits roll back the whole batch, and concurrent spends can't overdraw. A failed render is refunded to the same grants; a refund clawback takes the order's own grant first.
- Expiry: the 5-minute Cron voids what's left on expired grants and writes an
expire ledger entry; spending also voids the user's expired grants first. users.credits caches the sum of remaining credits, so it can include credits that expired in the last 5 minutes; spending is never affected.
- Billing shows credits that are about to expire, and the admin user page lists each grant's remaining credits and expiry.
- Redeem codes:
/admin/redeem-codes generates up to 1000 random codes at a time (12 characters without look-alikes such as I/O/0/1, shown as XXXX-XXXX-XXXX) or one named campaign code (4–32 letters and digits, e.g. LAUNCH2026), and exports a batch as CSV. Each code has a credit amount, a number of uses (each account can use a code once), an optional credit validity and an optional redemption deadline; codes can be disabled, which doesn't touch credits already redeemed.
- Users redeem on the settings page (
POST /api/redeem, case, spaces and dashes ignored); it is rate-limited per user and per IP and needs Turnstile when it's configured. A redemption is a grant with source redeem and the code as its ref, so it expires and is spent like any other grant.
- Redemption runs in one D1 batch: the use is only inserted while the code is enabled, before its deadline and below its use count, a guard row asserts the insert happened, then the count and the grant are written. Concurrent redemptions can't exceed the use count, and an account redeeming twice gets 409
already_redeemed.
- Referral rewards: every user has an invite link
/i/<code> on the settings page (8 characters without look-alikes, created on first view). When a friend signs up through it and their first order is paid, the inviter gets the reward set in runtime settings (default site.referralRewardCredits = 10; 0 in site.ts turns the feature off and hides the card). Rewards are credits only, never cash.
- The link sets a
vt_ref cookie (30 days, noindex) that is consumed at sign-up; only brand-new accounts are bound, never existing users or the inviter themselves.
- Anti-abuse: at most
site.referralMaxPerIp sign-ups per inviter from the same IP (a salted hash; IPv6 by /64); later ones are recorded as rejected. At most site.referralMonthlyCap rewards per inviter in any 30 days, and no reward if the inviter is banned or deleted when the order is paid.
- The reward is written in the same D1 batch as the friend's purchase, with a guard row so concurrent first orders reward once. Any refund of the rewarded order (partial ones too) claws the whole reward back from the inviter, at most down to 0, once.
- The admin
/admin/referrals page lists inviters by rewards and the latest invites with their status and rejection reason. Data export includes each side's own records without the other side's id, email or the IP hash; the privacy policy mentions the cookie and the hash while the feature is on.
- Runtime settings:
/admin/settings changes non-secret parameters without a deploy: maintenance mode, a checkout pause, the payment provider for new orders (checked for complete secrets and product IDs before saving; existing orders keep their own provider for refunds, lookups and renewals), a site-wide announcement per locale, the sign-up bonus and its validity, the referral reward and a site-wide daily generation cap (src/server/settings.ts). Only values that differ from the defaults in site.ts are stored, in the D1 settings table; saving a default deletes the row, so later site.ts changes still apply. Reads go through KV with a 60-second cache, so a change can take about a minute to reach every location. Secrets stay in wrangler secrets. Every change is audited with its before and after values.
- Maintenance mode returns 503
maintenance for new generations and checkouts and shows a banner on every page. Sign-in, viewing, downloads and payment webhooks keep working, and admins are exempt so they can verify.
- Checkout pause is for a payment provider that isn't live yet or is temporarily broken: the pricing page buttons turn into a disabled "Payments opening soon" with a note at the top, and new checkouts return 503
checkout_paused. Generation and webhooks for existing orders keep working, and admins are exempt.
- The daily cap counts jobs created per UTC day (failed and refunded ones included) and returns 429
daily_limit without charging; concurrent submits are bounded by a guard row in the same D1 batch. 0 = no cap. Use it together with the spend limit in the provider's console.
- A referral reward of 0 pauses invites (card hidden, links no longer bind). A first order paid while paused is recorded as rejected (
paused), so resuming doesn't reward a later order. When site.referralRewardCredits is 0 the field is locked, because the privacy policy is generated from site.ts.
- "Test connections" probes R2, KV, email (a test email to you), the payment provider (Dodo and Stripe: each pack's product or Price compared with
site.ts, where a lower price fails because such payments would be held as mismatches, and Stripe also checks one-time vs recurring and the billing interval; Waffo: signature and auth by looking up a non-existent order), the video provider (auth and balance, warning below $5) and moderation (auth). Probes are read-only or clean up after themselves, never create a checkout or submit a job, and redact secret values from their messages.
- Subscriptions: on by default, switched by
site.subscriptionsEnabled. The template ships with monthly $14.90 and yearly $149, both granting 60 credits a month; set the switch to false to sell credit packs only (the subscription copy in the pricing page, terms, refund policy and FAQ disappears with it, while existing subscriptions keep renewing and granting credits). The switch, changing plans, provider setup and troubleshooting are covered in the manual, docs/subscriptions.md.
- Every charge is its own order. Renewal orders get an id derived from the provider's payment id, so a redelivered charge creates one order; the renewal amount is checked against the price locked at sign-up and a mismatch is held for review.
- Subscription credits are a grant that expires at the end of the month it covers (ledger reason
subscription) and are spent before longer-lived credits. Yearly plans grant the first month at payment and the 5-minute Cron grants the rest month by month, idempotently.
- Status events (past due, canceling, canceled…) are ordered by the provider's event time, so a late older event can't overwrite a newer one. One live subscription per user (409
subscription_exists), and an account that will still renew can't be deleted (409 subscription_active).
- Billing has a subscription card: next renewal, cancel at period end and undo, a past-due notice and the provider's customer portal. Waffo can only undo a cancellation in its portal, which needs
WAFFO_STORE_ID.
- A refund claws back only the subscription credits that order granted and stops further yearly grants; it doesn't cancel the subscription. Plan changes, trials and pausing aren't supported. Rules and the Dodo/Waffo differences: "订阅" in docs/payments.md.
- Tested in test mode with webhooks: on Waffo, the monthly first payment, activation, the month's credits, the customer portal and cancellation all pass; on Dodo, the first payment, activation, credits and the portal URL pass, while cancel and undo still need Subscriptions write on the API key before they can be verified. Renewals and failed charges can't be triggered in test mode and are covered by unit tests and the mock e2e. Waffo's payment event carries no period and its periods are date-only, so the period is corrected when the status event arrives and the current grant's expiry follows it.
- Disputes and chargebacks: Stripe
charge.dispute.* and Dodo dispute.* events go through processPaymentEvent like payments. Opening a dispute claws back the order's remaining credits (idempotency key dispute:<id>) and emails admins; a won or withdrawn dispute gives them back; a lost one marks the order refunded without clawing back twice. For an actionable Stripe early fraud warning, site.fraudWarningAutoRefund defaults to true: it marks any live subscription on the account canceled at period end (plus best-effort provider cancel), refunds the rest of the order through Stripe, and immediately claws back remaining credits; set it to false to notify admins without refunding. Admin orders show the dispute status. Waffo has no dispute webhook; record those by hand. Details: "争议与拒付" in docs/payments.md.
- Payment events:
payment_events (provider, event_id) is unique. Replays, concurrent retries and a late "paid" after a refund all take effect once. Refunds claw back MIN(balance, credits in the pack) and the ledger records what was actually deducted.
- Before crediting, a paid event is checked against the order: the product (Dodo product id, Stripe Price id, Waffo
productMetadata.packageId) must match, and in the same currency the amount actually charged (tax included) must not be below the list price. Different currencies (Dodo Adaptive Currency) and discount codes skip the amount check. A mismatch is not credited and is recorded as mismatch; a paid event with no matching order is recorded as orphan (events whose metadata.site names another site sharing the merchant account are ignored). Both return 200 and raise the "payments to review" alert: mark the order paid in the admin after checking, or refund it in the provider dashboard (the refund webhook then closes the order as refunded without touching credits).
- A refund that arrives before its payment (the paid webhook is still being retried) is recorded as failed and returns 5xx so the provider retries it after the payment is credited.
- If a webhook is lost or late, the site asks the provider directly (
src/server/reconcile.ts; Dodo: checkout session → payment, Stripe: checkout session with its line items and invoice, Waffo: GraphQL payments by merchant order id). The success page asks once at about 15 s and once at about 60 s; the 5-minute Cron checks pending orders between 10 minutes and 24 hours old with exponential backoff (about 10, 20, 40… minutes, at most 10 orders per run); the admin order page has a "查单" (check with provider) action to use before mark-paid. A payment found this way goes through the same checks and idempotency keys as the webhook, so a late webhook isn't credited again. The browser can only send the order id, never a payment status. Orders that already have a mismatch event are left for manual review.
- Generation: credits are deducted before enqueueing and returned automatically on failure, timeout or when an admin fails the job. The video provider webhook and the poller may handle the same job concurrently; only one of them can mark it succeeded, and the other never deletes the stored video.
- Cost and margin: when a video is produced, the provider cost is stored in
generations.provider_cost_cents: the actual charge when the yir or NanoAPI bill is already settled, otherwise an estimate from the prices in site.video.
- fal bills per frame: 16 frames count as one video second, $0.04 per video second at 480p (pricing). The template source videos are 24fps, so a video costs 6¢ per second, about $1.08 for 18 seconds. Update
costCentsPerVideoSecond and sourceFps when changing the model, resolution or source frame rate.
- Jobs failed after a video was produced (timeout, failed by an admin) still record the cost; failures without a video don't. mock records 0.
- The admin overview shows the last 30 days of provider cost, revenue from credits consumed and estimated gross margin; the generations list shows cost and margin per job. Revenue per credit = net revenue of paid USD orders ÷ credits not clawed back. The provider's invoice is the source of truth.
- Video providers:
VIDEO_PROVIDER picks fal (default), yir, nanoapi or mock. yir.ai is an image and video API router. To use it, set VIDEO_PROVIDER=yir and the YIR_API_KEY secret, and adjust the model and prompt in site.video.yir (src/server/video/yir.ts).
- yir has no character-replacement model like the one the template uses (
wan/v2.2-14b/animate/replace). The integration uses Kling 2.6 Motion Control (reference mode: the photo plus the template's source video). The template ships the integration code only and it hasn't been tested with a real key (submit, status and error mapping are covered by unit tests), so verify output quality and price yourself; costCentsPerSecond: 7 is an estimate, so update it from the yir model page before launch.
- Two-step mode (optional, per style:
site.styles[].scene = { frame, prompt }, null by default; shared image-model settings in site.video.yir.sceneImage): Motion Control takes the background from the user's photo. To keep the source video's scene, an image model (such as google/nano-banana-2) first puts the person from the photo into the source video's first frame, and the composite becomes the motion reference. Put the frame in seed/templates/ and upload it to templates/ in R2 like the source videos (--content-type image/jpeg). Background music files (site.styles[].music, .m4a) are uploaded the same way with --content-type audio/mp4. The composite is uploaded to the yir Files API and the second step references it by a fixed file_id, so a resubmit sends the same body. Each order pays for one extra image (sceneImage.costCents), and the user's photo also goes through the image model's channels.
- Jobs are submitted with the generation id as
Idempotency-Key, so a resubmit after a queue redelivery or an interrupted Worker gets the same yir job back and isn't billed twice. yir matches requests by body, so the signed photo URL is derived from the job's creation time (valid for 2 hours) and stays the same on resubmit.
- There is no per-job
max_cost: yir rejects max_cost on requests that reference media by URL. Motion Control is billed by the reference video's length, and the template's source videos have fixed lengths, so the price is already bounded. To cap total spend, set a monthly limit on the API key in the yir Console; past it, submits fail with YIR_SPEND_LIMIT_EXCEEDED.
- yir can route a job to third-party channels as well as official ones, and users' photos are sent to them.
site.video.yir.routingOnly defaults to null: the API key's Routing Profile picks the channel and a failed attempt can fall back to another. With channel IDs (such as ['official']) only those channels are used, and the job fails if they all fail. Either way, list the channels that actually handle photos in your privacy policy.
- A missing or revoked key, an empty yir balance or an exhausted key limit fails the job with a refund and fires the "Video provider account" alert (see "Monitoring and alerts") right away, without waiting for the failure rate to build up.
- Upstream attempts that were billed are charged even if the job fails, and the wallet balance can go negative. yir keeps results for only 7 days; the template copies each video to R2 as soon as it's ready.
- Disclosure: the yir links in this README are the author's referral link; per yir's terms the author earns a share of yir's margin on a referred account's spending for its first 6 months. To sign up without it, use yir.ai. Links to fal carry no referral.
- NanoAPI (
VIDEO_PROVIDER=nanoapi, secret NANOAPI_API_KEY, settings in site.video.nanoapi, code in src/server/video/nanoapi.ts) runs the genjutsu-1.0 model on the photo plus the template's source video. mode: 'motion_control' makes the person in the photo perform the source video's moves; 'replace_object' swaps an object in the source video for the one in the photo, and prompt must say which. Billing seconds are the source video's length (rounded, at least 4 s for motion control; rounded up for replace), times the per-second price of the resolution (480p $0.117, 720p $0.273, 1080p $0.78); see the pricing. Tested with a real key on 2026-10-25 at 480p (6 s source video, 4 to 7 minutes per clip): motion_control keeps the source video's scene and moves and the face from the photo, but also the clothes from the photo; replace_object keeps the source video's outfit and scene, but the face drifts toward the original dancer. To put the user in a costume, dress the photo first with an image model, then run motion_control; the template doesn't do that step for NanoAPI. replace_object billed a 6.04 s video as 7 s, so cut source videos to whole seconds.
- NanoAPI downloads the photo and the source video itself, with a browser User-Agent, and reads the video with Range requests. A source it can't read fails the task with
internal_error (refunded), not invalid_media; in testing that happened with a server without Range support and with a signed URL that had no file extension. The template's /media/* routes support Range and end in .mp4. Don't put a bot challenge (Bot Fight Mode, Under Attack mode, a WAF challenge) in front of /media/*. For local tests, Pinggy's free tunnel shows browsers an interstitial page, so use another tunnel.
- NanoAPI has no idempotency key, so on retries (
attempts > 0, e.g. after a queue redelivery or interrupted Worker) the provider first lists the last 3 hours of tasks and reuses the one whose photo URL and source video URL match (the signed photo URL is derived from the job's creation time, so it stays the same across retries of one job and differs for every other); the first submit creates directly. When a retry list check fails, the submit fails (and is retried when the error is retryable) instead of creating blindly.
- A missing or revoked key, an empty balance or a suspended account fails the job with a refund and fires the "Video provider account" alert right away. There is no monthly limit on the key; watch the balance in the NanoAPI console. Results are polled every 30 seconds (the docs ask for at least 15).
- Security: non-GET
/api/* requests (except webhooks, CSP reports and browser error reports) must have an Origin matching the site; uploads are type-checked by magic bytes; uploads and generation are rate-limited per user; banning a user invalidates their sessions immediately; admin actions are written to admin_audit.
- The
redirect after sign-in (sign-in page and Google callback) only accepts same-site paths: src/lib/redirect.ts rejects backslashes, control characters and anything that normalizes to a leading //, so links like /sign-in?redirect=/\evil.com land on the dashboard.
- For 5xx errors only admins get the
message; everyone else gets just the error code, and the details go to Workers Logs as [api] <method> <path> <code>: <message>.
- Google sign-in: the authorization code flow uses PKCE (S256) and a nonce. For signed-out visitors,
GET /api/me issues the One Tap nonce inline and sets the matching cookie in one round-trip (/api/auth/google/nonce stays available as a fallback after sign-out), and the two must match when the credential is submitted.
- Accounts are keyed on Google's
sub: if the same email comes back with a different Google account (a different sub), sign-in is refused and the sign-in page asks the user to contact support (account_conflict). Accounts created by dev login (no sub) are bound on their first Google sign-in.
- Deleting an account keeps only a salted hash of the email (
deleted_accounts table, salted with SESSION_SECRET), so signing up again with the same email gets no sign-up bonus and no referral binding. Rotating SESSION_SECRET invalidates the old hashes.
- Uploads must send
Content-Length (otherwise 411); oversized uploads get 413 before the body is read. Provider outputs over 100 MB fail the generation and refund credits; with a length they stream straight into R2, without one the download is counted as it is read and stops at 48 MB.
- Full-page browser translation (Chrome / Google Translate swaps text for nodes) made later React updates throw NotFoundError (insertBefore / removeChild) and show the error page:
src/lib/translate-guard.ts (the React issue #11538 patch, re-anchoring to the moved node's current child) is installed before hydration, so translation keeps working
- Photos are checked in the browser before upload (
src/lib/prepare-photo.ts, shared by the generator and the phone upload page): a short side under site.upload.minSide (300 px by default) or a long side more than site.upload.maxRatio times the short one (2.5 by default) shows a "pick another photo" error and nothing is uploaded; photos over 1.5 MB are shrunk to a 2048 px JPEG first (EXIF orientation applied, undecodable formats sent as they are). The upload API re-checks the size from the file header (422 photo_too_small / photo_bad_ratio) and base64-encodes for moderation in chunks: uploading phone originals with a byte-by-byte base64 made Workers Free end the request with exceededCpu (503). Both defaults come from Kling Motion Control's documented limits for reference images (at least 300 px on each side, aspect ratio between 1:2.5 and 2.5:1); photos outside them fail upstream
- When the payment result page has parameters other than
order (Dodo's return URL adds the buyer's email), the Worker 302s to a clean URL before rendering, so the email never reaches the page, analytics, error reports or browser history. The first request's URL still appears in Workers Logs.
- The takedown form doesn't require sign-in, so a receipt is only sent to signed-in reporters who enter their own account email; otherwise the form could be used to email arbitrary addresses. The report ID is shown after submitting, and the outcome is still emailed to the address given.
- To report a vulnerability, see SECURITY.md.
- Sharing videos: on the dashboard, users can share one of their own videos, which creates a public link
/v/<random id> (16 characters, not enumerable; /zh/v/… works too). On by default; set site.share.enabled to false to hide the button and the page. Face-swap or real-person sites should consider turning it off.
- The share page only has the video, the AI badge and disclosure, a "Make your own" button and a report link. It shows nothing about the creator, and neither the HTML nor the API exposes the video id. Both the response header and the meta tag say
noindex, and share pages aren't in the sitemap.
- Link previews: when sharing, the browser grabs a frame from the video, draws a 1200×630 JPEG with an AI label in the top-left corner and uploads it as the
og:image; the video URL goes into og:video. The poster goes through the same image moderation as uploads (422 share_rejected if it fails). If capturing fails (the browser can't decode the video, or it times out), the video is shared without a poster and the site's default OG image is used.
- Media is served from
/media/shares/<id>/video and /media/shares/<id>/poster.jpg with Range support and Cache-Control: public, max-age=300, so a visitor who already opened it may keep playing from cache for up to 5 minutes after sharing stops.
- Expiry: after sharing stops the old link returns 404, and sharing again creates a new link; once the video expires or is removed after a report it returns 410, the poster is deleted and the video can't be shared again; deleting the video also deletes the poster.
- Migration
0015_shares.sql adds share_id, share_poster_key and shared_at to generations. Data export includes the share link and when sharing started; while the feature is on, the privacy policy has a "Shared videos" section.
- CSP: pages are served with
Content-Security-Policy-Report-Only by default (controlled by site.cspReportOnly); the policy lives in src/server/csp.ts and includes media-src 'self' blob:.
- A nonce is generated per request (
src/server.ts → ssr.nonce in src/router.tsx) and added to every inline script the framework emits; script-src does not allow 'unsafe-inline'. Put custom inline scripts in headScripts() in __root.tsx instead of writing <script> directly.
- GA4, Cloudflare Web Analytics, Turnstile and Google sign-in are allowed per their official docs; add sources to
csp.ts when adding third-party scripts, iframes or APIs.
- Violation reports go to
/api/csp-report and are only written to Workers Logs as [csp] <directive> blocked=… page=… (URLs without query, rate-limited per IP). Once production has run for a while without false positives, set site.cspReportOnly to false in src/config/site.ts to enforce Content-Security-Policy.
- Every response has a
Permissions-Policy that disables camera, microphone, geolocation, payment and USB.
Compliance and content safety
- AI label: the generator and dashboard players show an "AI-generated" badge, with a note to keep the label when sharing. Downloads are named
<brand>-ai-video-<video id>.mp4, so a reporter can identify a video by its file name. Share pages show the same badge and an AI disclosure, and link preview images carry an AI label in the top-left corner.
- Machine-readable label (site switch
site.aiMetadata.enabled, off by default): when on, before a video is marked ready, the queue appends an XMP packet to the MP4 (a top-level uuid box, streamed back to R2 with an etag check) with IPTC DigitalSourceType = trainedAlgorithmicMedia, the brand, the model, the video id, the creation time and the verify URL (src/lib/xmp.ts, src/server/xmp.ts). Files that already carry XMP or can't be parsed safely are left as they are. exiftool -XMP:all <file> shows the fields. When off, videos are left untouched and /verify, GET /api/verify/:id, the footer link, the sitemap entry and the XMP sentence in the terms all disappear (the page and API return 404). Turn it on for sites with EU users (EU AI Act Art. 50(2)); California SB 942 only applies to providers with over 1 million monthly visitors.
- Verify page (only when the switch is on):
/verify (linked in the footer) reads a file in the browser, without uploading it, and shows whether it carries the label; with a video id or ?id= it also asks GET /api/verify/:id (rate-limited per IP), which only returns the brand, creation time and model, and found: false for unknown, deleted or removed videos.
- Not yet: a burned-in visible watermark, an invisible watermark and a signed C2PA manifest (requires Containers; see FEATURES P0-1). Metadata is stripped by re-encoding and most social platforms, so the badge, file name and verify page still matter.
- Output moderation:
OUTPUT_MODERATION=frames samples 3 frames of every finished video (1 s, the middle and 80%) through the Cloudflare Media Transformations binding and checks each with MODERATION_PROVIDER. A rejected video is deleted, the job fails with output_moderation_rejected and credits are refunded; if the moderation API is down the queue retries. Off by default because the binding only runs in remote mode during local dev; turning it on and the costs are described in docs/env.md. Videos of 100 MB or more can't be sampled.
- Consent record: creating a video requires
consent: true in the request (400 consent_required otherwise, before any credits are spent); the time and the exact consent text shown in that language are stored on the generation (consent_at, consent_text) as evidence for likeness disputes.
- Retention: controlled by
site.retention; photos are kept 7 days and videos 30 by default, and the privacy policy reads both numbers.
- Takedowns: "Report content" in the footer opens
/report; no account needed.
- Fields: full name, email, content locator, reason, non-consent statement and an electronic signature (the reporter types their name; required by the TAKE IT DOWN Act and shown to admins). Submissions go to
takedown_requests with a deadline 48 hours later (site.takedownSlaHours). A gen_ video id or a share link (/v/<id>, with or without a language prefix) in the locator is linked automatically; the report link on a share page pre-fills the share URL.
- Admins handle them at
/admin/takedowns; the overview shows pending and overdue counts.
- Removal finds every upload and video made from the same photo by its SHA-256, then:
- fails in-progress jobs and refunds credits;
- deletes the R2 objects (including share posters) and sets
removed_at, so share links return 410;
- adds the hash to
blocked_media, so uploading the same image again returns 422 content_rejected.
- Rejection requires a reason.
- Both outcomes are written to
admin_audit. ADMIN_EMAILS gets an email for new reports, 12 hours before the deadline and when overdue (see "Transactional email"), but someone still needs to check the queue daily.
- Upload moderation: chosen with
MODERATION_PROVIDER. Moderation runs before writing to R2; rejected images are never stored and no credits are spent.
openai: OpenAI omni-moderation-latest (free), requires OPENAI_API_KEY. Blocks the sexual, violence/graphic and self-harm categories. Uploads are refused with 503 if the API fails.none: no moderation.mock: non-production only.- Minors and public figures are not OpenAI image categories; those still rely on the consent statement and takedowns.
- Turnstile: create a widget in the Cloudflare dashboard, put the site key in
vars.TURNSTILE_SITE_KEY, then run npx wrangler secret put TURNSTILE_SECRET_KEY.
- It only protects the anonymous contact and report forms. Sign-in and generation rely on Google sign-in plus rate limits; add it there when offering a free trial.
- With a site key but no secret, both forms return 503 instead of silently letting requests through.
- Analytics and cookies: configured in
site.analytics; the "Cookies and analytics" section of the privacy policy adapts to it.
- Recommended: only set
cfBeaconToken (Cloudflare Web Analytics), which sets no cookies and needs no consent banner.
- Umami (optional): set
analytics.umamiWebsiteId and vars.UMAMI_ORIGIN (your instance, e.g. https://umami.example.com). The page loads /s/script.js and reports to /s/api/send on your own domain; the Worker (src/server/umami.ts) proxies both, so the instance's domain never appears in the page source or JS. It sets no cookies, so it isn't gated by the consent banner. The proxy forwards no cookies and passes the visitor IP (CF-Connecting-IP) only for country lookup and unique-visit counting. Only APP_ENV=production reports; local dev, e2e and staging get an empty script and nothing is forwarded. /admin pages are never reported.
- Microsoft Clarity (optional, heatmaps and session recordings): set
analytics.clarityId to the project ID. It only loads on site.domain (and www.), never on local dev, e2e, staging or /admin. It also turns on the consent banner: until a visitor accepts, Clarity records in cookie-free mode (consentv2 with analytics_Storage: denied, one ID per page view); accepting lets it set _clck / _clsk, rejecting makes it delete them. In Clarity's Settings → Setup, turn Cookies off so the project relies on these consent signals. Form inputs are masked by Clarity's default masking. The CSP allows https://*.clarity.ms and https://c.bing.com.
- GA4 is only enabled when
ga4Id is set, together with a consent banner and a "Cookie settings" footer link. It uses Consent Mode v2 basic: gtag.js isn't loaded until the visitor accepts, events only go to dataLayer, and ad consent is always denied. Declining or withdrawing deletes _ga, _ga_* and _gid (on the current host and each parent domain). The choice is stored as consent.analytics in localStorage; see src/lib/consent.ts.
- Regional default (like most consumer sites): the Worker reads
cf-ipcountry and writes the default on <html data-consent-default>. Visitors from the EEA, the UK and Switzerland, and visitors whose country is unknown (XX, T1 or no header, which includes local dev), default to denied and see the banner. Everyone else defaults to granted with no banner: GA4, Clarity cookies and vt_attr work from the first page view, and the footer "Cookie settings" opens the card to reject. A stored choice always wins over the default. The privacy policy describes this split.
- Attribution uses a first-party cookie
vt_attr (90 days). With ga4Id set it waits for consent like GA4: accepting records the current visit's source, declining or withdrawing deletes it, and visitors without the cookie are attributed as direct on sign-up and orders (visits are still counted). Without ga4Id there is no banner and vt_attr is written directly; under a strict reading of the EU ePrivacy Directive that also needs prior consent, so enable the banner if you mainly serve EU users. See src/lib/attribution.ts.
- Export my data (GDPR Art. 15 and 20): the dashboard settings page downloads JSON (
GET /api/account/export) with the account, sessions, orders, credit ledger and grants, uploads and generations, contact messages, the user's own takedown reports and email log; rate-limited per user. It excludes R2 paths, provider request ids, internal errors and costs, and reports others filed against the user's videos. Media files aren't bundled; those still within retention can be downloaded from the dashboard. Field list: src/server/account-export.ts.
- Database backups: when the 5-minute Cron finds no backup for the current UTC day, it exports D1 as SQL (schema plus all data;
sessions is schema only), gzips it to backups/d1/<date>.sql.gz in MEDIA and keeps 30 days (src/server/backup.ts). It tries at most 3 times a day and emails ADMIN_EMAILS a backup_failed alert if the third attempt fails. There is no public route to backups/, and R2 lifecycle rules shouldn't cover it.
Transactional email
Sent directly from the Worker with Cloudflare Email Service (public beta): the send_email binding is EMAIL and the sender is vars.EMAIL_FROM.
- To users: credits added, video ready (with the retention date), generation failed and refunded, takedown receipt (only to signed-in reporters using their own account email), takedown outcome, video removed after a report. The language follows the UI language of the user's latest order or generation; takedown emails use the language of the report page. Deleted or banned users get nothing.
- To admins (
ADMIN_EMAILS, in Chinese): new takedown; one reminder 12 hours before the deadline and one when overdue; new contact message (Reply-To is the sender); payment disputes and Stripe early fraud warnings, one per dispute and stage. Senders don't get an auto-reply, so the form can't be used to email arbitrary addresses.
- Delivery: business events are first written to the D1
email_outbox table with a unique dedupe_key (e.g. order_paid:<order id>), so webhook replays, queue redelivery and overlapping Crons send one email.
- Emails are sent right after being written. On rate limits, daily quota or server errors they back off 5, 15, 45… minutes, up to 5 attempts, retried by the 5-minute Cron; permanent errors such as an unverified sender fail immediately.
- Delivery is at-least-once: if the Worker stops after sending but before saving the status, an email may be sent twice.
- The outbox is kept 30 days; a user's records are deleted with their account.
- Admin:
/admin/emails searches by recipient, order id or takedown id and can resend failed or unsent emails; the overview shows the failure count.
- Going live:
- Cloudflare dashboard → Compute > Email Service → Onboard Domain, add the site's domain (DNS must be on Cloudflare) and add the SPF/DKIM records it shows.
- Sending to arbitrary recipients requires Workers Paid. 3,000 emails a month are included, then $0.35 per thousand (pricing).
- Set
vars.EMAIL_FROM to noreply@<domain> (new-site.mjs does this), then run npm run db:migrate:remote.
- Optional: send through Resend (e.g. on Workers Free, where Email Service only reaches addresses verified in Cloudflare): sign up at Resend, verify the sending domain under Domains, create an API key, put it in
.dev.vars.production as RESEND_API_KEY and run node scripts/sync-secrets.mjs --apply (or npx wrangler secret put RESEND_API_KEY). With the key set and EMAIL_FROM non-empty, all emails go through Resend instead of the send_email binding (free tier: 3,000 a month, 100 a day; hitting the quota is retried like any rate limit). Run "Test connection" for email in the admin to confirm; the result names the channel used. Without the key nothing changes.
- With
EMAIL_FROM empty or no binding, nothing is sent and emails are marked "not sent"; resend them from the admin once configured. Local wrangler dev only simulates sending; don't add "remote": true to the binding.
Monitoring and alerts
A health check (src/server/alerts.ts) runs on the 5-minute Cron. When a threshold is crossed it emails ADMIN_EMAILS (in Chinese) and writes console.error('[alert] …') to Workers Logs:
| Alert |
Condition |
Admin page |
| Generation failure rate |
In the last hour, ≥ 3 failed jobs and ≥ 30% of finished jobs (excluding manual admin failures and takedowns) |
/admin/generations |
| Dead letters |
A job was failed in the last hour because its queue message ran out of retries |
/admin/generations |
| Video provider account |
In the last hour a job failed because the key is missing or revoked, the yir or NanoAPI balance is empty or the key's monthly limit is used up (alerts on the first one) |
/admin/generations |
| Video provider balance |
Hourly (the Cron run at the top of the UTC hour), the yir, NanoAPI or fal balance is below $10; alerts before jobs start failing, and a failed lookup is only logged |
/admin/generations |
| Backlog |
A job created more than 30 minutes ago is still unfinished |
/admin/generations |
| Payment webhooks |
A payment webhook failed to process in the last 24 hours |
/admin/events |
| Payments to review |
In the last 24 hours a paid webhook had no matching order, or its amount, currency or product didn't match the order (until the order is marked paid or refunded) |
/admin/events |
| Email |
In the last 6 hours, ≥ 3 emails failed or are still unsent after 3 attempts (alert emails excluded) |
/admin/emails |
- Dedupe: each alert type is sent at most once per 6-hour UTC bucket, with
dedupe_key admin_alert:<type>:<bucket>:<admin email>. If the problem persists, it alerts again in the next bucket.
- Dead-letter queue: a message that still fails after 10 retries (about 35 minutes) goes to
<name>-jobs-dlq. The same Worker consumes it (src/server.ts routes by the -dlq suffix), fails the job (error_code = dead_letter) and refunds credits; the user gets a generation-failed email. New sites need both queues (see "Deploying to Cloudflare"); new-site.mjs renames both.
- D1 backup failures aren't part of the health check above; a
backup_failed alert is emailed when the third export of the day fails. See "Database backups" under "Compliance and content safety".
- Instant payment notifications: set the secret
PAYMENT_NOTIFY_WEBHOOK_URL and every order's first credit (including renewals and admin mark-paid) posts a message to a Telegram, Feishu / Lark, Discord or Slack chat with the amount, package, credits, source and order id. URL formats are in docs/env.md (in Chinese). Failures are only logged and never block crediting; the webhook URL (which contains a token) never appears in logs or errors. The same URL also receives the alerts above and D1 backup failures (one message per alert type per bucket, deduped in KV); if a Feishu bot checks keywords, add "告警".
- If email itself is broken (unverified domain, quota exhausted), alert emails may not go out either; Workers Logs
[alert] lines are the source of truth. With PAYMENT_NOTIFY_WEBHOOK_URL set, the chat is the second channel; for a third, push logs to an external monitoring service with Workers Logpush and alert on [alert].
- Browser errors: uncaught exceptions, unhandled promise rejections and error-page render failures are sent by
src/lib/error-report.ts with sendBeacon to /api/client-error, which only writes to Workers Logs: [client-error] id=… kind=error|rejection|boundary page=… message=… stack=….
- The error page shows an error ID; search Workers Logs for
id=<ID> to find the stack trace when a user reports it.
- Emails are masked, URLs lose credentials, query and hash, and stacks keep the first 6 frames. Each distinct error is reported once per page, at most 5 per page, and the endpoint is rate-limited per IP. Cross-origin
Script error. is ignored.
- Production code is bundled, so stack traces point at minified line/column numbers. To map them to source or aggregate alerts, swap the sending code for an SDK such as Sentry (and allow it in
connect-src in csp.ts).
Testing
npm run typecheck
npm test            # vitest: Waffo/Dodo/Stripe signatures and event mapping, refund ratios and refund id rules, attribution parsing, mocks disabled in production, Turnstile and moderation error paths, email templates and retry decisions, alert thresholds and buckets, GA4 not loading before consent and cookie removal on withdrawal, CSP report and browser error summaries and redaction, sign-in redirect validation, PKCE and nonce for Google sign-in, binding accounts by sub and no second sign-up bonus for deleted emails, output download size limits, SQL escaping in D1 backups, payment notification formats and URL redaction, the attribution cookie waiting for consent, 5xx details hidden from non-admins, weak SESSION_SECRET refused in production, launch config check and doctor rules and wrangler output parsing, template sync plan layers, secret sync plan validation and redaction, credit accounting, redeem codes, referral rewards and subscriptions (calendar months, yearly grants, renewals, out-of-order events, aligning the current grant's expiry when the period is corrected, refunds, Dodo/Waffo event mapping) on SQLite, runtime settings validation, cache and daily cap, connection probes and their redaction, the e2e catalog matching the tests
npm run test:e2e    # Playwright: run npm run seed:local first; reuses a dev server already running on 127.0.0.1:3000; serial, about 10 minutes
E2E_PORT=3200 npx playwright test tests/e2e/payments.spec.ts tests/e2e/smoke.spec.ts   # only the specs related to a change, see the "改哪里跑哪些" (which specs to run) table in tests/e2e/CATALOG.md
E2E_PORT=3200 npm run test:e2e   # use another port when 3000 is taken
npm run seo:check   # needs the dev server running; writes its report to .tmp/seo-check/
SMOKE_BASE_URL=https://<domain> npm run test:smoke   # read-only production smoke, see "Deploying to Cloudflare"
SANDBOX_PROVIDER=dodo E2E_PORT=3200 npm run test:sandbox   # real test-mode checkout (dodo, waffo or stripe); needs test credentials in .dev.vars, not run in CI
The risk-ranked e2e acceptance catalog and known gaps are in tests/e2e/CATALOG.md (in Chinese). Update it when you add or rename a test; npm test checks that the two match. For sandbox e2e prerequisites, webhook mode and test cards, see "sandbox e2e" in docs/payments.md (in Chinese).
e2e coverage (81 tests):
- Purchase and generation: the full main path (including the Chinese site and the AI badge), buying the cheapest covering pack straight from the generator when credits run short (disabled while checkout is paused), failed payment, returning to the result page signed out (the email is removed by a 302 before rendering), insufficient credits, refund on failed generation; three pollers handling the same job concurrently store it once without deleting the video, and the admin shows cost and margin.
- Compliance:
- Retention: photos used by in-progress jobs are kept; expired photos can't be reused; expired videos return 410 and show as expired in the dashboard; repeated cleanup is idempotent.
- Takedowns: an anonymous report at
/report, removed by an admin. Both videos from the same photo are deleted, unrelated videos are kept, and re-uploading the photo is blocked; a handled report can't be handled again, and the outcome is audited.
- Moderation: rejected uploads return 422.
- AI label: the downloaded video ends with exactly one XMP box holding the video id and
trainedAlgorithmicMedia and no user data, and Range reads still work; /verify recognises the file, reports a stripped file as unlabelled and a deleted record as unknown; a video rejected by output moderation isn't delivered, is refunded and isn't found by the verify API.
- Consent: creating a video without
consent: true (missing, false or not a boolean) returns 400 and spends nothing; a report without a signature is refused and the admin list shows the signature.
- Data export: the JSON downloaded from settings contains all of the user's records and none of other users' data or internal fields; 401 when signed out or after account deletion.
- Sharing: after sharing from the dashboard, an anonymous visitor sees a noindex share page with the AI badge and no video id; other users can't start or stop sharing; the old link returns 404 after sharing stops and 410 once the video expires or is removed after a report; non-JPEG or rejected posters are refused; a report that only has a share link with a language prefix still finds the video.
- Credit grants: after an admin grants time-limited credits, a render spends them first and a failed render returns them; once they expire the billing notice disappears. With credits for only one render, two concurrent renders give one success and one 402. Unit tests run the accounting rules on SQLite with every migration applied.
- Redeem codes: the admin generates a batch and exports CSV, disables one; a user redeems on the settings page and gets credits with an expiry; redeeming twice, a used-up code, a disabled or malformed code and non-admin access are refused; five users redeeming a 3-use campaign code at once give three successes.
- Referral rewards: a friend signs up through the settings-page link and the first paid order rewards the inviter once; a second order, other users' orders and invalid codes or existing accounts don't; refunding the first order claws the reward back once; sign-ups over the per-IP limit are rejected and shown with the reason in the admin; data export only shows each side's own records.
- Runtime settings: admin-only, and an unknown or out-of-range value rejects the whole save; a new sign-up bonus and validity apply to the next sign-up and are audited with before and after values; maintenance mode blocks generation and checkout with 503 while an existing order's payment is still credited and admins are exempt, with a banner in both languages; checkout pause returns 503
checkout_paused and disables the pricing buttons in both languages while generation and existing orders keep working; an unknown payment provider rejects the whole save and checkout keeps the deploy config; announcements per language; the daily cap returns 429 without charging; the admin page saves only changed fields, and every connection test passes locally.
- Subscriptions: monthly: subscribe from the pricing page, credits expire with the period, a replayed renewal is credited once and an underpaid one is held, past due and recovery, cancel at period end and undo on the billing page, the portal, a second subscription and account deletion refused while it renews, re-subscribing after it ends; yearly: monthly grants that a repeated Cron run doesn't duplicate, an older status event arriving late is ignored, and a refund claws back only the subscription credits and stops the grants.
- Alerts and dead letters: a dead-lettered job is failed and refunded once; the health check raises failure-rate and dead-letter alerts and doesn't resend within the same bucket.
- Transactional email: replayed payment webhooks send one email in the user's language; one email each for success and failure, none for a repeated failure; no takedown receipt for signed-out reporters and a receipt only when a signed-in user enters their own email, one deadline and one overdue reminder, notifying the reporter and the creator after removal and no further reminders; contact messages only notify admins; account deletion clears the email log; the admin email page.
- Disputes: an opened dispute claws back the order's credits once (replays and repeat events are duplicates), winning gives them back once; a lost dispute marks the order fully refunded, and the admin order page shows the dispute.
- Payment events and refunds: concurrent and replayed payment events, refunds after partial use, two partial refunds, a late webhook with the same refund id after a manual record doesn't claw back twice; a refund arriving before its payment is retried and still claws back; underpaid or wrong-package payments are not credited and raise an alert until refunded, discounted or other-currency payments are credited, orphan events alert and other sites' events are ignored; a lost webhook is recovered by the success page and by the Cron (backoff, five concurrent checks credit once, a late webhook isn't credited again, other users get 404, underpaid payments aren't re-checked), and the admin check action credits or points to manual review.
- Order and user data: billing and the order detail page show amounts paid and partial refunds; another user's order returns 404 from the API and "not found" on the page; the admin searches orders, an invalid refund amount is blocked and can be retried, and the timeline is complete after a partial refund and a mark-paid; users filter by paying and banned and sort by credits, and invalid sort values never reach SQL; a ledger longer than one page loads more without duplicates or gaps.
- Security and permissions: CSRF, forged uploads and access to other users' data, admin permissions, no secret values in the admin config check, credit adjustments and bans, dev login and mock payments only accepted from localhost; off-site
redirect values after sign-in fall back to the dashboard, and unknown error codes on the sign-in page (such as __proto__) show the generic message; the email parameter on the payment result page is removed by a 302 before rendering.
- Security headers: every inline script carries the request's nonce; zero CSP violations across public pages, a signed-in generation and the admin; an injected script without a nonce is reported; report endpoints aren't subject to the same-origin check.
- Browser error reporting: global errors and unhandled rejections are reported once each without the query string, duplicates aren't re-sent, at most 5 per page; on a render error, the ID on the error page matches the report, and "Try again" recovers once the API is back.
- Attribution and reports: UTM attribution persists across sessions; reports and CSV.
- Generator draft and phone upload: a signed-out visitor's photo, style and length survive sign-in and checkout and are cleared once a generation starts; a photo uploaded from the phone page reaches the desktop and the code can't be reused; the phone page rejects a missing token and wrong formats; unknown tokens, disguised files and a second take are refused.
- SEO: every seo-check rule, hydration of the English and Chinese home pages, head updates after client-side navigation, crawlable language links.
Artifacts go to .tmp/video-template-e2e/: report/ (HTML report with screenshots and traces for every step), results.json and test-results/. In CI (CI set) only failed tests keep traces and screenshots, and the workflow uploads report/ only when the run fails, kept for 3 days: artifacts from private site repos count against the account's Actions storage (500 MB on GitHub Free).
Project layout
src/config/site.ts      per-site config
src/content/            English and Chinese copy (one chunk per locale)
src/routes/             pages ({-$locale} is the optional locale prefix, admin/ is the admin)
src/server/             API: auth, credits, orders, payments/, video/, jobs (queue, dead letters, Cron), alerts, admin, seo, retention, takedown, moderation, turnstile, email (outbox), notifications (events → email), settings (runtime settings), probes (connection tests), csp, client-error
migrations/             D1 migrations
containers/postprocess/ post-processing container: burned-in watermark, C2PA signing, cover and preview (experimental, not wired into the Worker yet; see ROADMAP)
seed/templates/         source videos for generation
.claude/skills/         Claude Code skills: new-hot-site (launch a keyword site), sync-upstream (merge template updates), launch-audit (launch checks)
scripts/                new-site, doctor (pre-deploy checks), sync-plan (template sync plan), sync-secrets (secret sync), seo-check, indexnow, waffo-setup, dodo-setup, stripe-setup, webhook-proxy, seed-local, placeholder media
tests/                  unit, e2e (mock providers), smoke (post-deploy), sandbox (payment provider test mode)
License
MIT

 ShrimpReel 是一个开源模板,用于搭建“一张照片变成遵循热门模板的 AI 视频”的 SaaS 网站,每个热门关键词对应一个独立网站,完全运行在 Cloudflare 基础设施上。