Что это такое?
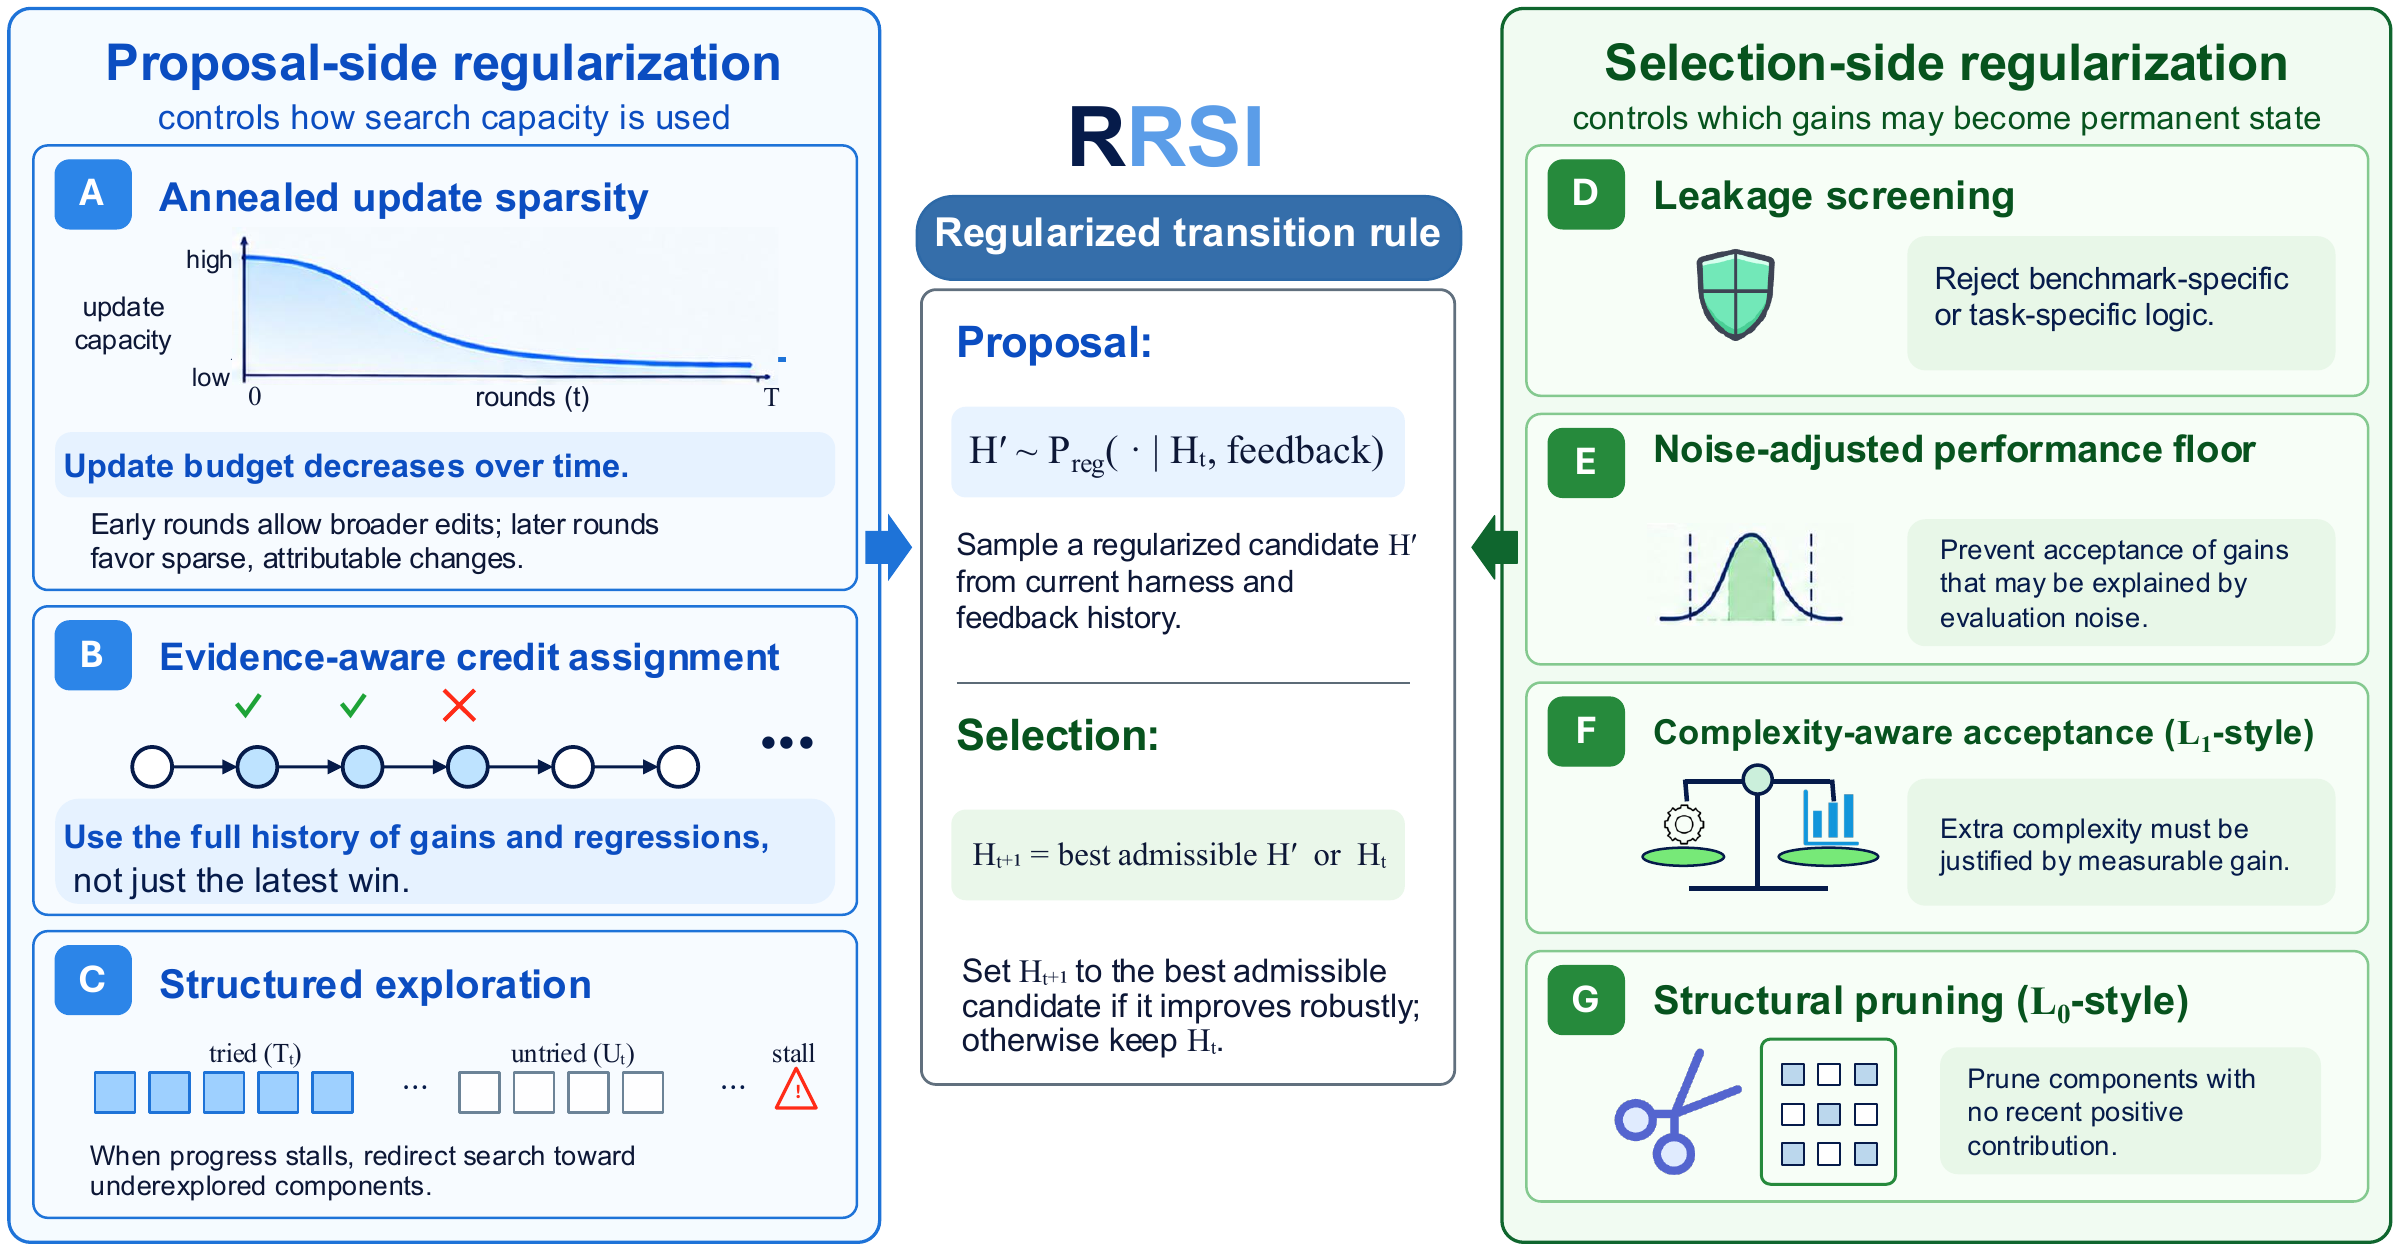
 RRSI (Regularized Recursive Self-Improvement) — исследовательский фреймворк от Google, который автоматически улучшает обвязку (harness) LLM-агента — промпты, логику управления, инструменты, память, управление контекстом вокруг замороженной модели. Он ищет варианты изменений обвязки и оставляет только те, что дают измеримый и проверяемый прирост.
Так это готовый агент, с которым можно общаться, или исследовательский код для улучшения агентов?Исследовательский код, а не готовый продукт: основное поисковое ядро (proposer, analyst, critic, evaluator) плюс адаптеры Domain. В комплекте три инстанса — агент для кодинга в терминале, агент для работы с документами и агент для инженерного проектирования; каждый — это адаптер Domain плюс своя стартовая обвязка.
Исследовательский код, а не готовый продукт: основное поисковое ядро (proposer, analyst, critic, evaluator) плюс адаптеры Domain. В комплекте три инстанса — агент для кодинга в терминале, агент для работы с документами и агент для инженерного проектирования; каждый — это адаптер Domain плюс своя стартовая обвязка.Как запустить один из инстансов?Создайте окружение Python 3.11 и выполните pip install -e '.[agentic]' для инстансов workspace и engineering (инстанс кодинга вместо этого использует harbor в domains/coding/.venv), настройте свою модель, затем запустите инстанс — в каждом раунде в отдельных git worktree создаются, отбираются и оцениваются два кандидата.
Создайте окружение Python 3.11 и выполните pip install -e '.[agentic]' для инстансов workspace и engineering (инстанс кодинга вместо этого использует harbor в domains/coding/.venv), настройте свою модель, затем запустите инстанс — в каждом раунде в отдельных git worktree создаются, отбираются и оцениваются два кандидата.Какие LLM для этого нужны — получится только с Claude?По умолчанию proposer, analyst, critic и замороженная политика работают на Claude Opus 4.8 через Vertex AI, но подойдёт любая модель в виде строки LiteLLM. Судья Harvey LAB — это Gemini 3.5 Flash, а раннер инстанса кодинга живёт в собственном окружении harbor.
По умолчанию proposer, analyst, critic и замороженная политика работают на Claude Opus 4.8 через Vertex AI, но подойдёт любая модель в виде строки LiteLLM. Судья Harvey LAB — это Gemini 3.5 Flash, а раннер инстанса кодинга живёт в собственном окружении harbor.Держится ли выигрыш на задачах, которых поиск никогда не видел?Отчасти — прирост внутри распределения уменьшается вне его, и именно это RRSI регуляризует. В статье Terminal-Bench 2.1 вырос с 74.2 до 80.2 на наборе evolve, а SWE-bench Verified, который поиск не видел, — только с 82.0 до 83.8; прирост вне распределения остался положительным на JobBench, GDPval, APEX-Agents и Frontier-Eng.
Отчасти — прирост внутри распределения уменьшается вне его, и именно это RRSI регуляризует. В статье Terminal-Bench 2.1 вырос с 74.2 до 80.2 на наборе evolve, а SWE-bench Verified, который поиск не видел, — только с 82.0 до 83.8; прирост вне распределения остался положительным на JobBench, GDPval, APEX-Agents и Frontier-Eng.Какие результаты привела статья?С Claude Opus 4.8 в роли замороженной политики: Terminal-Bench 2.1 — с 74.2 до 80.2 (набор evolve), SWE-bench Verified — с 82.0 до 83.8 (вне распределения), Harvey LAB — с 89.4 до 90.5, JobBench — с 36.0 до 40.7 (вне распределения), EngDesign — с 50.0 до 54.9, Frontier-Eng — с 17.7 до 22.0 (вне распределения). С Gemini 3.5 Flash в роли политики тот же инстанс кодинга вырос с 64.6 до 78.7 на Terminal-Bench 2.1.
С Claude Opus 4.8 в роли замороженной политики: Terminal-Bench 2.1 — с 74.2 до 80.2 (набор evolve), SWE-bench Verified — с 82.0 до 83.8 (вне распределения), Harvey LAB — с 89.4 до 90.5, JobBench — с 36.0 до 40.7 (вне распределения), EngDesign — с 50.0 до 54.9, Frontier-Eng — с 17.7 до 22.0 (вне распределения). С Gemini 3.5 Flash в роли политики тот же инстанс кодинга вырос с 64.6 до 78.7 на Terminal-Bench 2.1.Что мешает ему обманывать бенчмарк?Критик проверяет каждого кандидата на логику, заточенную под конкретный набор задач, перед оценкой (регулярное выражение с блок-листом для домена плюс проверка LLM с ограниченными исправлениями), шумовой порог отсекает прирост в пределах разброса оценок, а компоненты, которые перестают помогать, удаляются.
Критик проверяет каждого кандидата на логику, заточенную под конкретный набор задач, перед оценкой (регулярное выражение с блок-листом для домена плюс проверка LLM с ограниченными исправлениями), шумовой порог отсекает прирост в пределах разброса оценок, а компоненты, которые перестают помогать, удаляются.На какие бенчмарки нацелены три инстанса?domains/coding: Terminal-Bench 2.1, затем SWE-bench Verified. domains/workspace: Harvey LAB, затем JobBench, GDPval и APEX-Agents. domains/eng: EngDesign, затем EngDesign v1 и Frontier-Eng.
domains/coding: Terminal-Bench 2.1, затем SWE-bench Verified. domains/workspace: Harvey LAB, затем JobBench, GDPval и APEX-Agents. domains/eng: EngDesign, затем EngDesign v1 и Frontier-Eng.Это официальный продукт Google?Нет. Это исследовательский релиз под Apache 2.0, и в README сказано, что это не официально поддерживаемый продукт Google и он не подпадает под программу Google OSS Vulnerability Rewards Program. Стартовые обвязки — это агент Terminus-2 из harbor и агент reacttoolbelt из archipelago.
Нет. Это исследовательский релиз под Apache 2.0, и в README сказано, что это не официально поддерживаемый продукт Google и он не подпадает под программу Google OSS Vulnerability Rewards Program. Стартовые обвязки — это агент Terminus-2 из harbor и агент reacttoolbelt из archipelago.What are similar projects?harness-sdk, awesome-rsi, imp, Raven, hive, adk-python, Recuris, autoagent
harness-sdk, awesome-rsi, imp, Raven, hive, adk-python, Recuris, autoagentWhich topics is it in?vertex-ai, benchmarks, self-improvement, self-improving, self-improving-agents, context-management, evals, research-tools, self-evolving, papers, agent-harness, agentic
vertex-ai, benchmarks, self-improvement, self-improving, self-improving-agents, context-management, evals, research-tools, self-evolving, papers, agent-harness, agentic