
druid README

The project's README from github.com/apache/druid. As one markdown file: README.md.

Coverage Status Docker Helm

Workflow Status
⚙️ CodeQL Config codeql-config
🔍 CodeQL codeql
🕒 Cron Job ITS cron-job-its
🏷️ Labeler labeler
🛠️ Static Checks static-checks
🧪 Unit and Integration Tests Unified unit-and-integration-tests-unified

Website Twitter Download Get Started Documentation Community Build Contribute License


Apache Druid

Druid is a high performance real-time analytics database. Druid's main value add is to reduce time to insight and action.

Druid is designed for workflows where fast queries and ingest really matter. Druid excels at powering UIs, running operational (ad-hoc) queries, or handling high concurrency. Consider Druid as an open source alternative to data warehouses for a variety of use cases. The design documentation explains the key concepts.

Getting started

You can get started with Druid with our local or Docker quickstart. For Kubernetes deployments, the druid-operator is maintained in a separate repository.

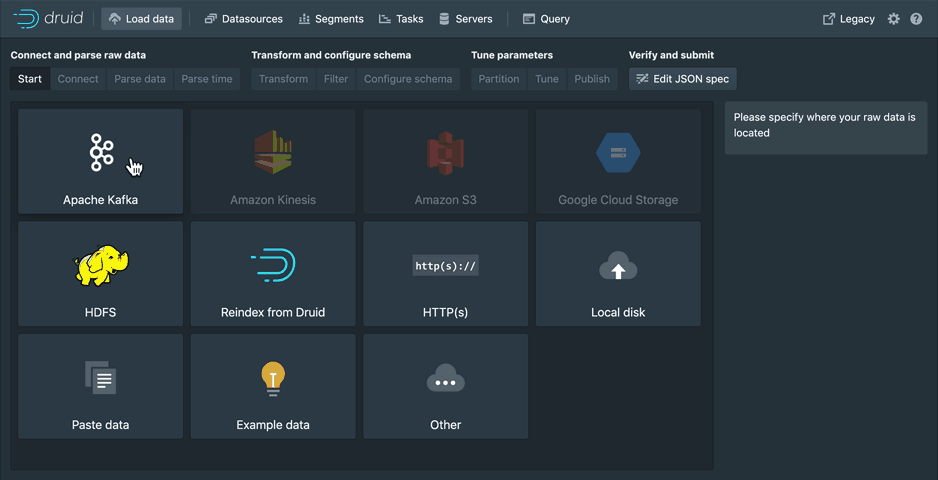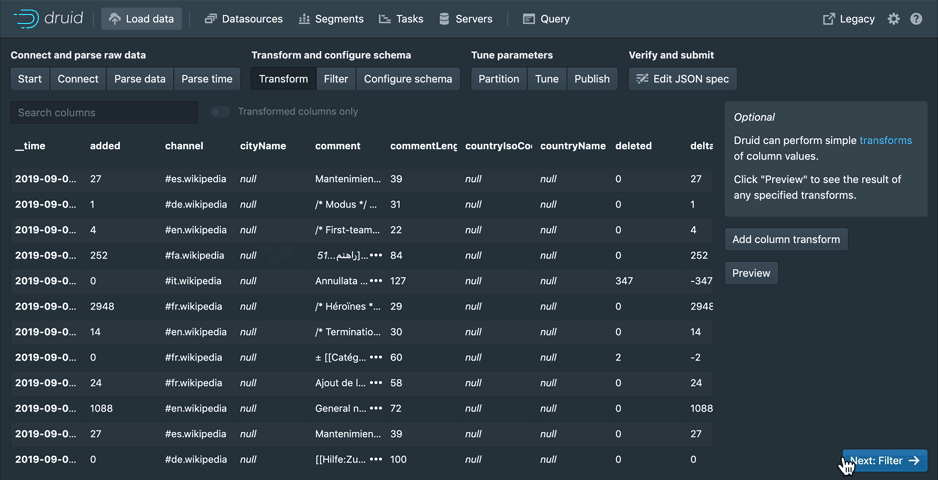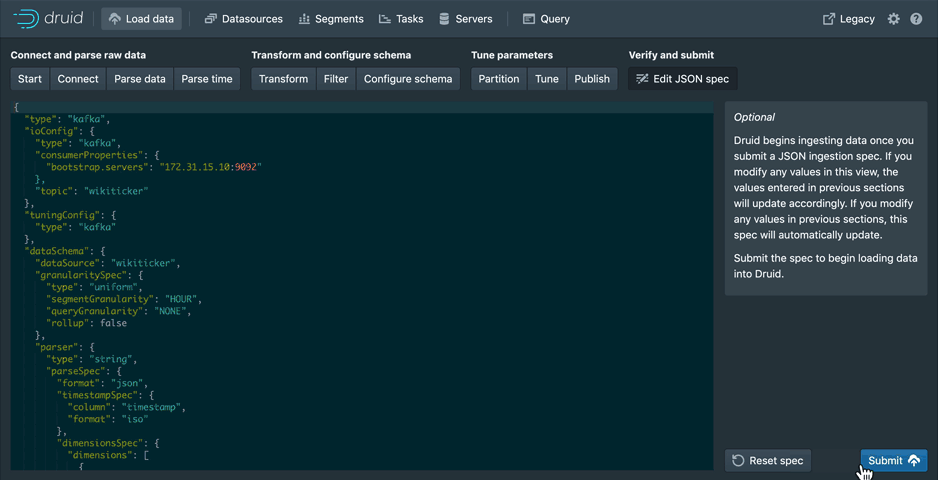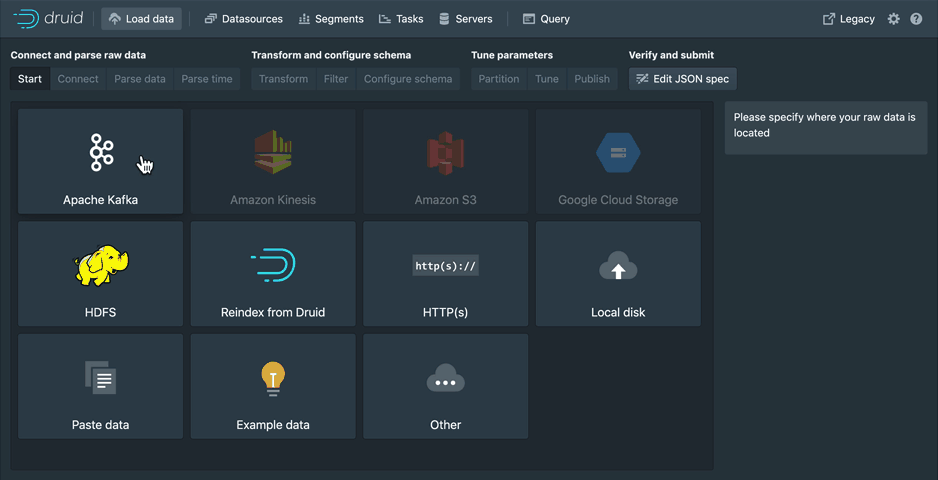
Druid provides a rich set of APIs (via HTTP and JDBC) for loading, managing, and querying your data. You can also interact with Druid via the built-in web console (shown below).

Load data

data loader Kafka

Load streaming and batch data using a point-and-click wizard to guide you through ingestion setup. Monitor one off tasks and ingestion supervisors.

Manage the cluster

management

Manage your cluster with ease. Get a view of your datasources, segments, ingestion tasks, and services from one convenient location. All powered by SQL systems tables, allowing you to see the underlying query for each view.

Issue queries

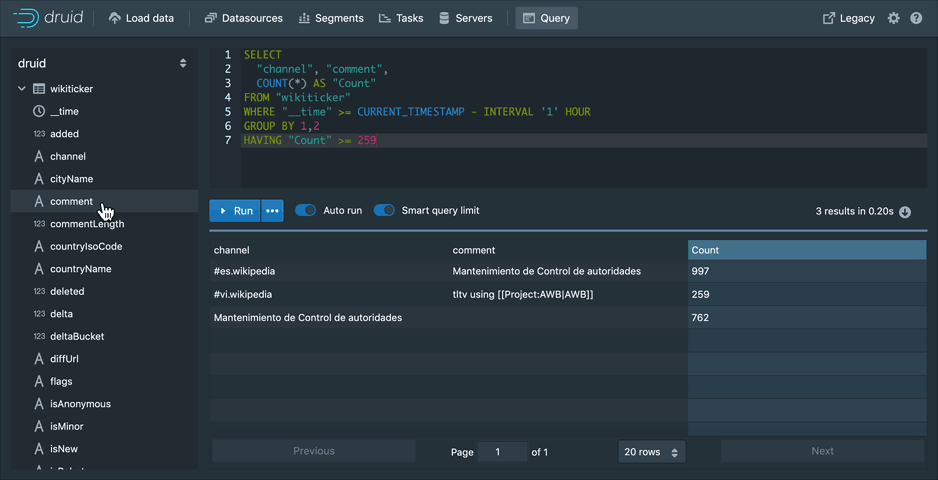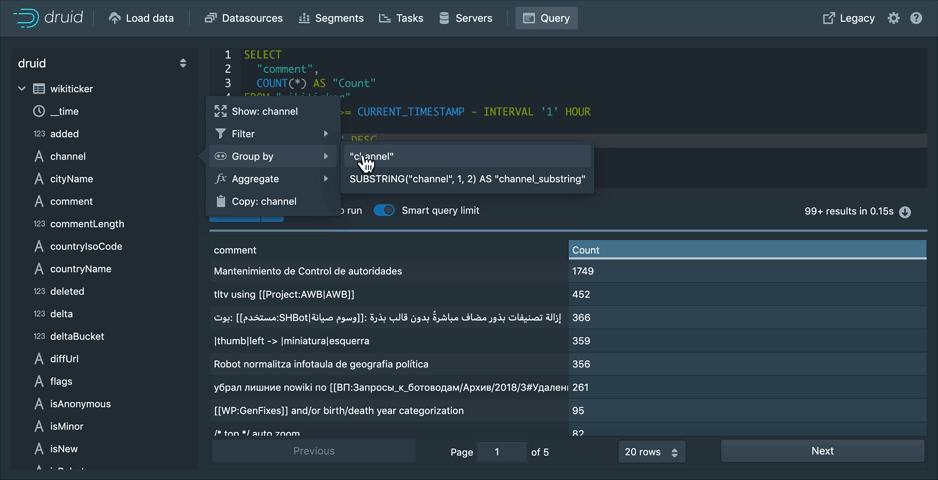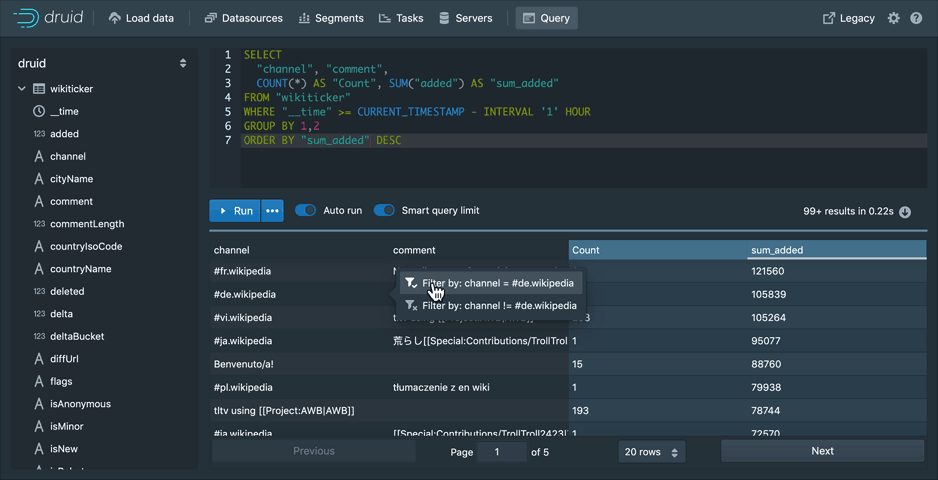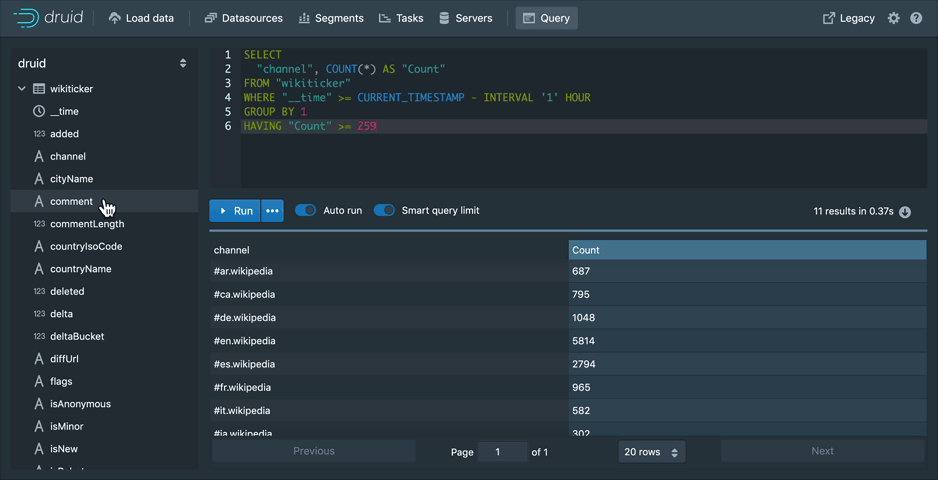
query view combo

Use the built-in query workbench to prototype DruidSQL and native queries or connect one of the many tools that help you make the most out of Druid.

Documentation

See the latest documentation for the documentation for the current official release. If you need information on a previous release, you can browse previous releases documentation.

Make documentation and tutorials updates in /docs using Markdown or extended Markdown (MDX). Then, open a pull request.

To build the site locally, you need Node 22 or higher and to install Docusaurus 3 with npm|yarn install in the website directory. Then you can run npm|yarn start to launch a local dev preview of the docs.

If you're looking to update non-doc pages like Use Cases, those files are in the druid-website-src repo.

For more information, see the README in the ./website directory.

Community

Visit the official project community page to read about getting involved in contributing to Apache Druid, and how we help one another use and operate Druid.

Check out the official community page for details of how to join the community Slack channels.

Find articles written by community members and a calendar of upcoming events on the project site - contribute your own events and articles by submitting a PR in the apache/druid-website-src repository.

Building from source

Please note that JDK 25 is required to build Druid.

See the latest build guide for instructions on building Apache Druid from source.

Contributing

Please follow the community guidelines for contributing.

For instructions on setting up IntelliJ dev/intellij-setup.md

License

Apache License, Version 2.0

druid (apache/druid)

Searching Database…

14.1K ·GitHub
这是什么?Apache Druid 是一个高性能的实时分析数据库,旨在缩短数据到达与可查询之间的时间差,因此即使在高并发下,仪表盘和临时查询也能保持快速响应。
这是我可以嵌入的库,还是我要单独运行的数据库?它是一个独立的分布式数据库服务器,你需要部署并进行查询,而不是可以导入应用程序中的库;你可以通过 HTTP/JDBC API 或内置的 Web 控制台与它交互。
我该如何让 Druid 运行起来?使用本地快速启动或 Docker 快速启动,即可搭建单节点 Druid 集群,并开始加载数据。
Druid 是否内置 Kubernetes 支持?在本仓库中没有直接提供。Kubernetes 部署由 druid-operator 负责,它位于单独的仓库中,并未与 Druid 本身捆绑。
Druid 支持哪些平台?Druid 以自托管服务器的形式运行在 Linux 上,可以通过本地方式启动,也可以使用提供的 Docker 快速启动方式。
我到底该如何在 Druid 中查询数据?你可以使用内置的查询工作台编写 DruidSQL 或原生 JSON 查询,也可以连接支持 Druid 的外部 BI/SQL 工具。
我可以在 Web 控制台中做什么?通过可点选操作的向导加载流式和批量数据,监控摄取任务和 supervisor,并查看数据源、段和服务,所有这些都由 SQL 系统表提供支持。
为什么要用 Druid 而不是传统的数据仓库?Druid 针对快速摄取和快速查询进行了优化,因此非常适合为界面提供数据支持、临时运营查询,以及在传统数据仓库速度过慢的高并发工作负载场景。
What are similar projects?trino, doris, starrocks, ClickHouse, oceanbase, tidb, questdb, timescaledb
Creator
apache
Size
426.2 MB
Stars
14.1K
Age
13y
Commits · 90 Days