



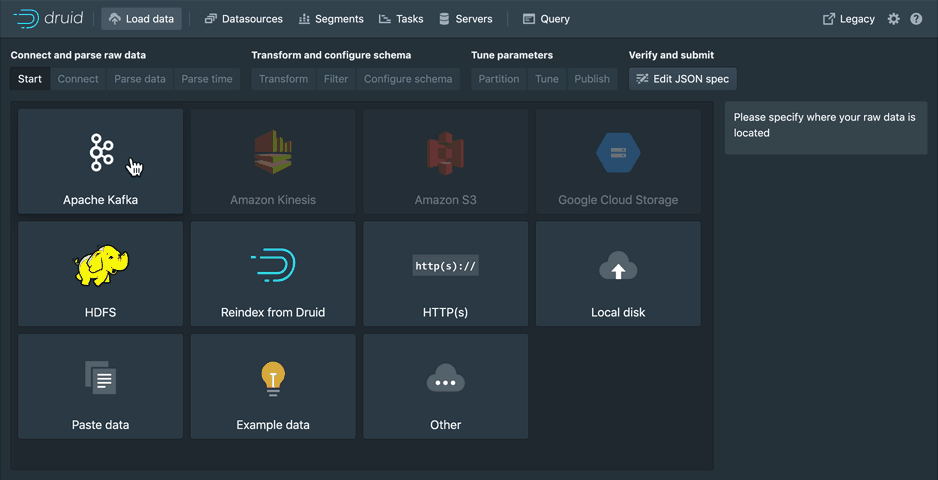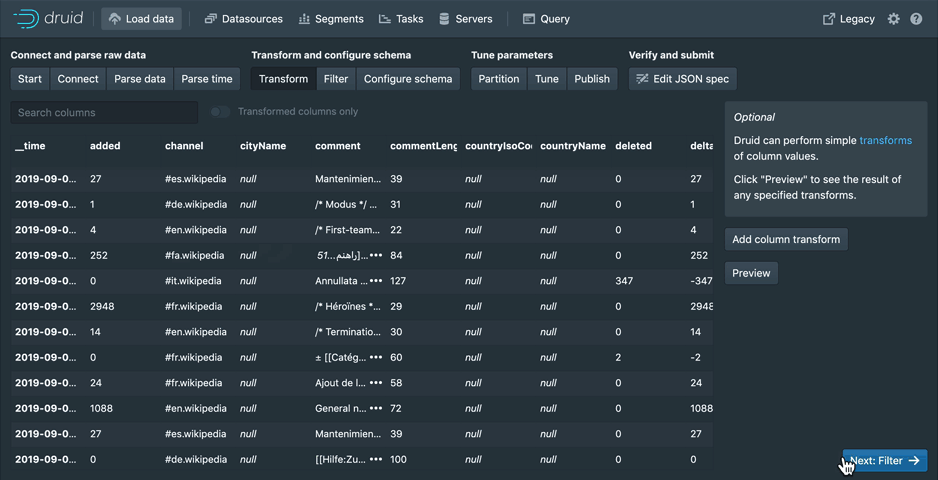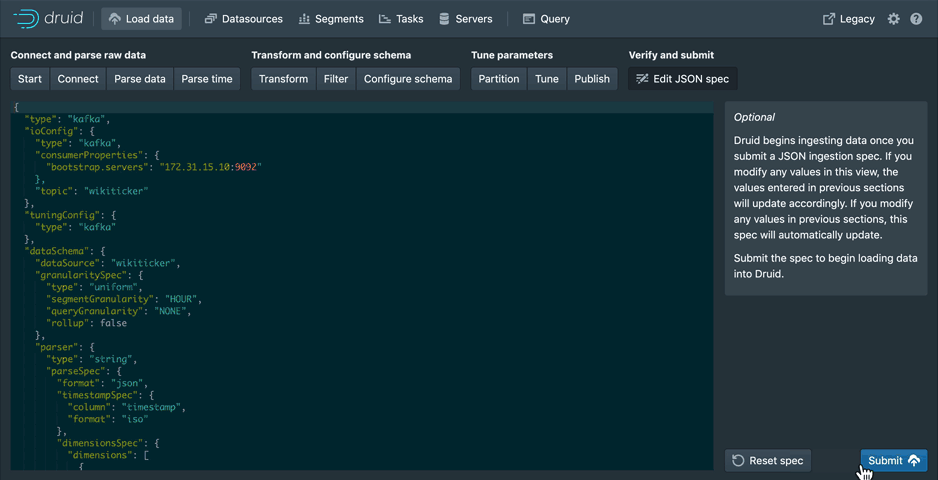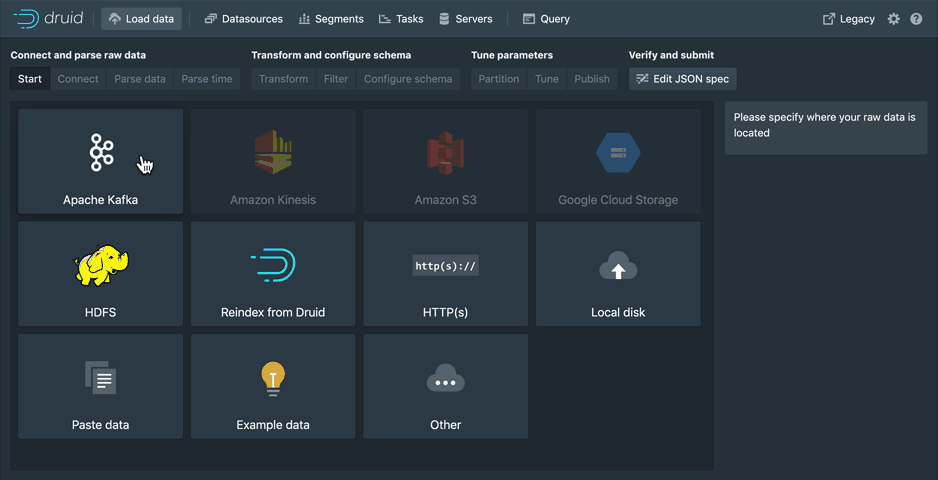

Что это такое?
 Apache Druid — это высокопроизводительная аналитическая база данных реального времени. Она создана для того, чтобы сократить время между поступлением данных и возможностью их запроса, поэтому дашборды и ad-hoc запросы остаются быстрыми даже при высокой параллельной нагрузке.
Это библиотека, которую я встраиваю, или самостоятельная база данных, которую я запускаю?Это самостоятельный распределённый сервер базы данных, который вы развёртываете и к которому отправляете запросы. Это не библиотека, которую импортируют в приложение: вы работаете с ним через HTTP/JDBC API или встроенную веб-консоль.
Это самостоятельный распределённый сервер базы данных, который вы развёртываете и к которому отправляете запросы. Это не библиотека, которую импортируют в приложение: вы работаете с ним через HTTP/JDBC API или встроенную веб-консоль.Как запустить Druid?Используйте локальный быстрый старт или быстрый старт через Docker, чтобы поднять кластер Druid из одного узла и начать загрузку данных.
Используйте локальный быстрый старт или быстрый старт через Docker, чтобы поднять кластер Druid из одного узла и начать загрузку данных.Есть ли в Druid встроенная поддержка Kubernetes?Напрямую в этом репозитории — нет. Развёртыванием в Kubernetes занимается druid-operator, который находится в отдельном репозитории и не входит в состав самого Druid.
Напрямую в этом репозитории — нет. Развёртыванием в Kubernetes занимается druid-operator, который находится в отдельном репозитории и не входит в состав самого Druid.На каких платформах работает Druid?Druid работает как сервер для самостоятельного развёртывания на Linux и может быть запущен локально или через предоставленный быстрый старт с Docker.
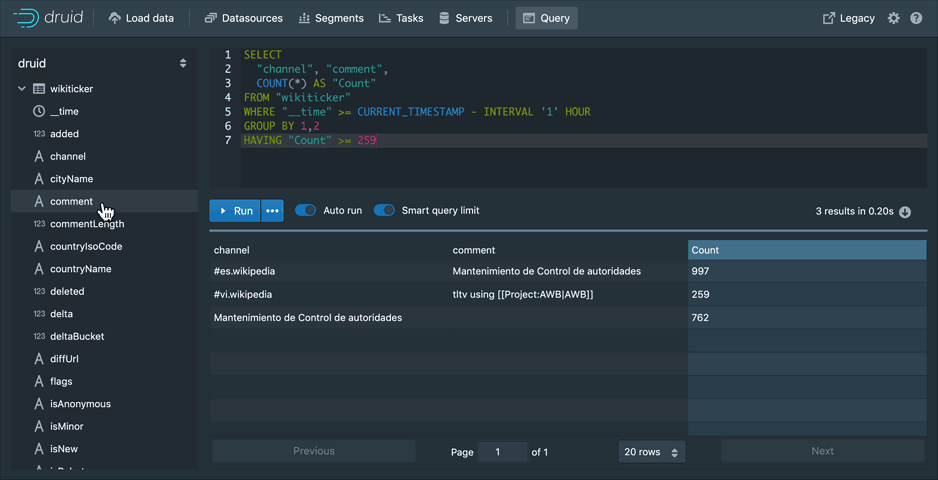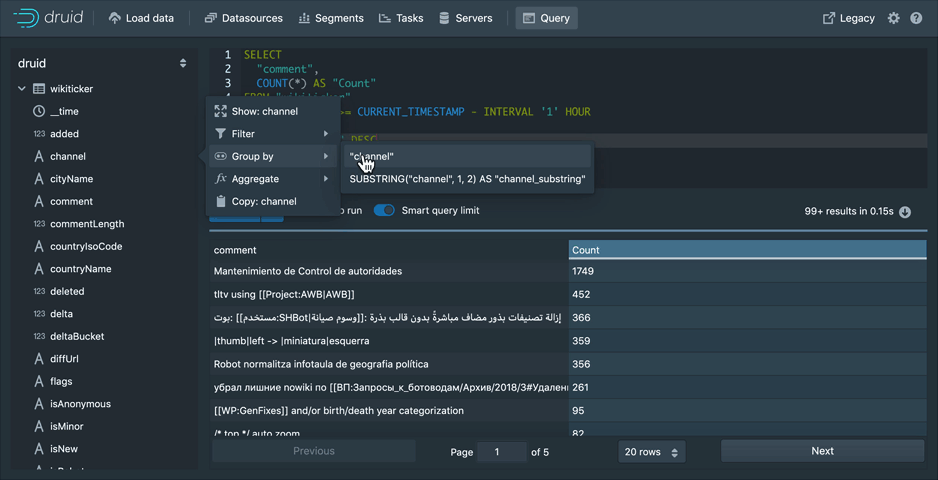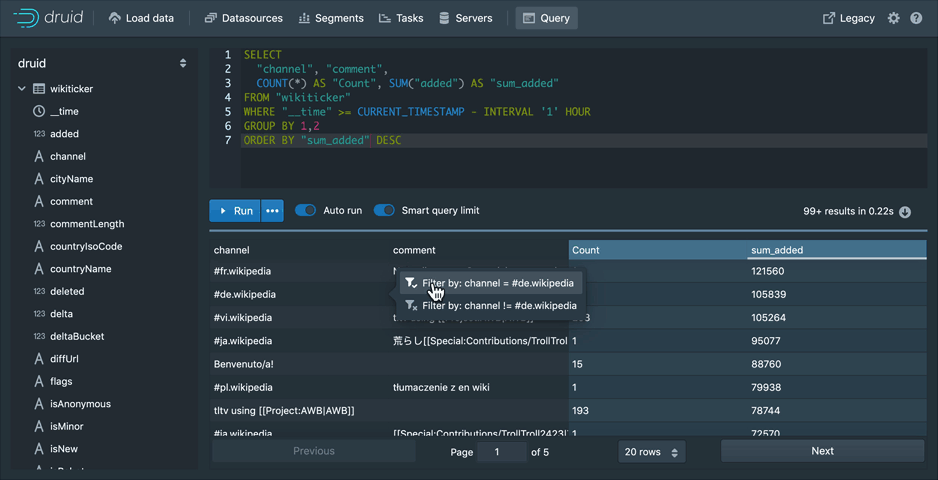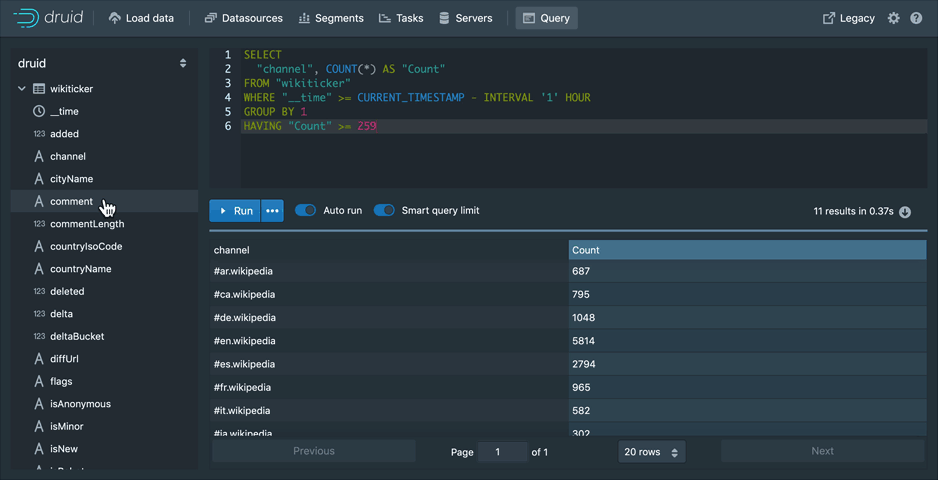
Druid работает как сервер для самостоятельного развёртывания на Linux и может быть запущен локально или через предоставленный быстрый старт с Docker.Как на самом деле запросить данные в Druid?Используйте встроенный инструмент для запросов, чтобы написать запросы на DruidSQL или в нативном JSON-формате, либо подключите внешний BI- или SQL-инструмент, который поддерживает Druid.
Используйте встроенный инструмент для запросов, чтобы написать запросы на DruidSQL или в нативном JSON-формате, либо подключите внешний BI- или SQL-инструмент, который поддерживает Druid.Что можно делать в веб-консоли?Загружать потоковые и пакетные данные через пошаговый мастер с управлением мышью, отслеживать задачи приёма данных и супервизоры, а также просматривать источники данных, сегменты и сервисы — всё это опирается на системные таблицы SQL.
Загружать потоковые и пакетные данные через пошаговый мастер с управлением мышью, отслеживать задачи приёма данных и супервизоры, а также просматривать источники данных, сегменты и сервисы — всё это опирается на системные таблицы SQL.Зачем использовать Druid вместо традиционного хранилища данных?Druid оптимизирован для быстрой загрузки и быстрых запросов. Поэтому он хорошо подходит для питания интерфейсов, ad-hoc операционных запросов и нагрузок с высокой параллельностью, с которыми типичное хранилище данных работает слишком медленно.
Druid оптимизирован для быстрой загрузки и быстрых запросов. Поэтому он хорошо подходит для питания интерфейсов, ad-hoc операционных запросов и нагрузок с высокой параллельностью, с которыми типичное хранилище данных работает слишком медленно.What are similar projects?trino, doris, starrocks, ClickHouse, oceanbase, tidb, questdb, timescaledb
trino, doris, starrocks, ClickHouse, oceanbase, tidb, questdb, timescaledbWhich topics is it in?olap, distributed-database, time-series, data-engineering, big-data, analytics, sql, real-time, distributed-systems, kubernetes, cloud, java
olap, distributed-database, time-series, data-engineering, big-data, analytics, sql, real-time, distributed-systems, kubernetes, cloud, java