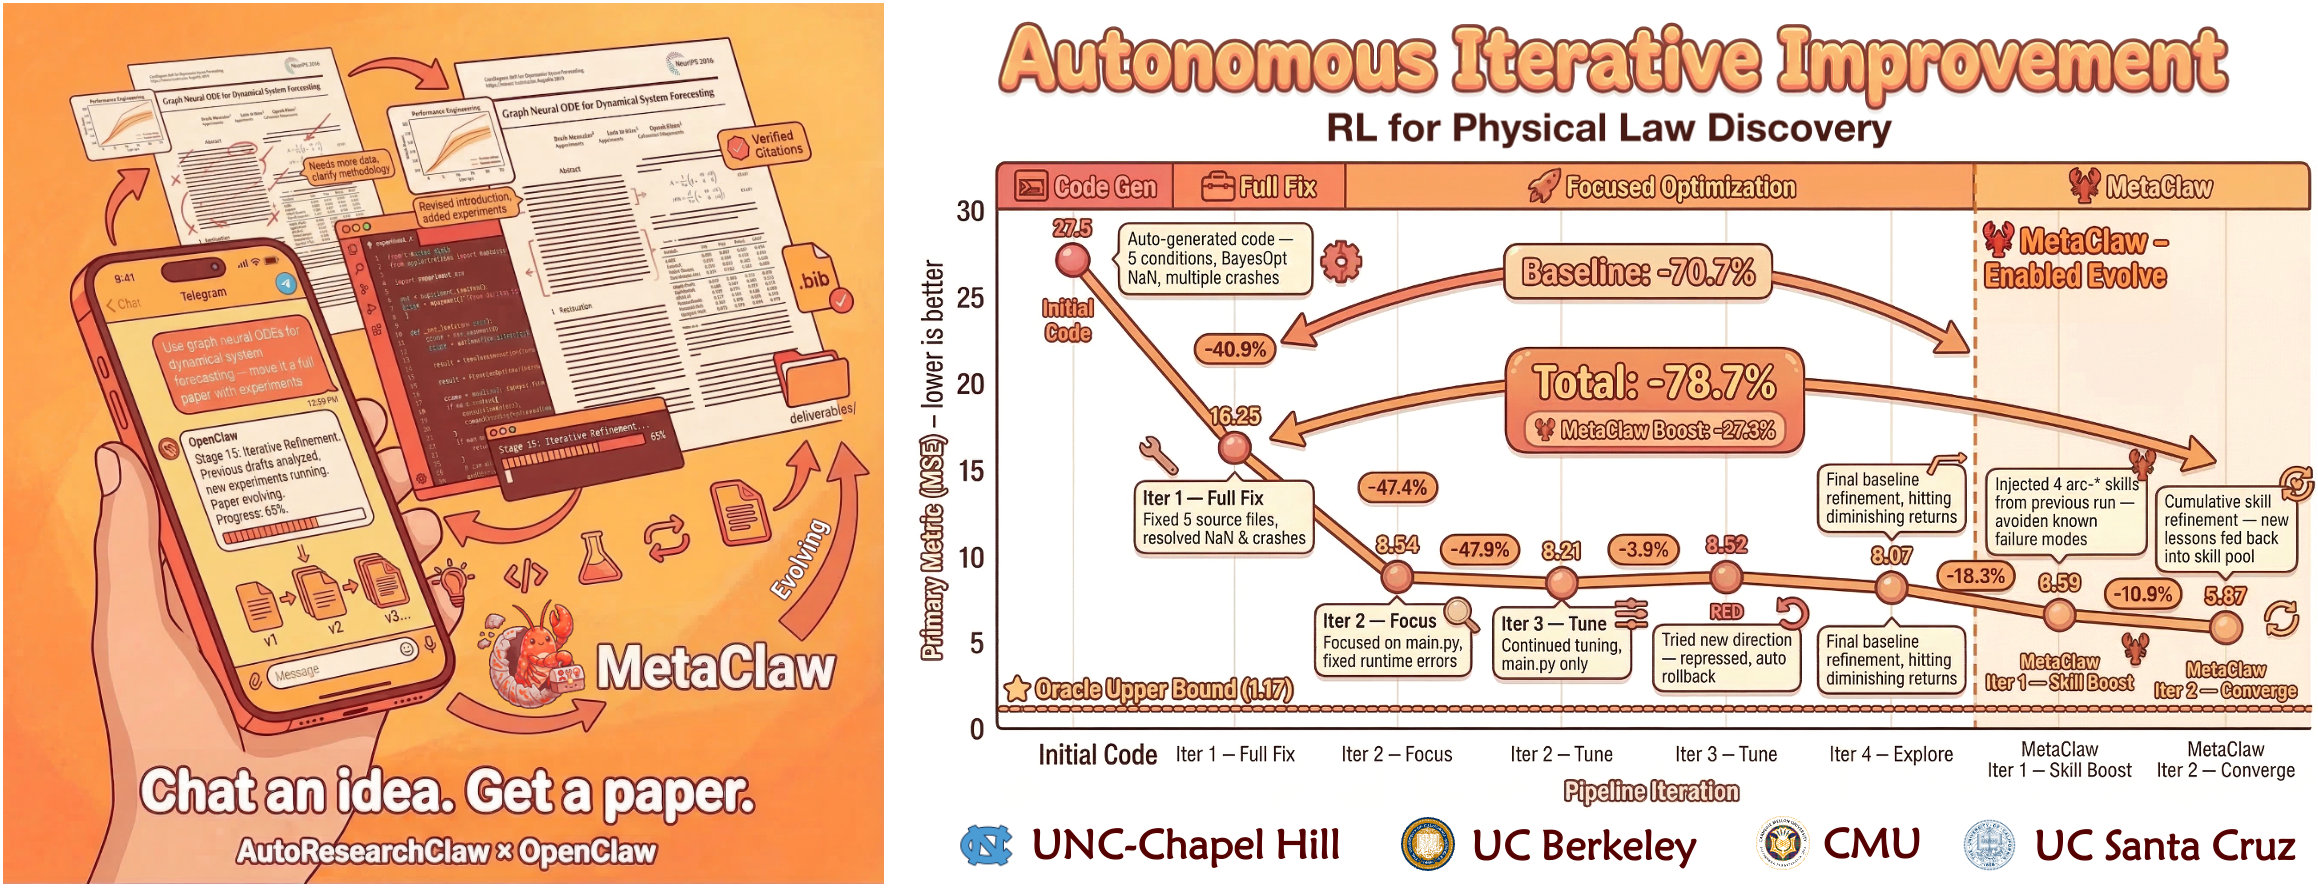
Chat an Idea. Get a Paper. Autonomous, Collaborative & Self-Evolving.
Just chat with OpenClaw: "Research X" → done.
📄 Our paper is on arXiv — come read it! AutoResearchClaw: Self-Reinforcing Autonomous Research with Human-AI Collaboration


🇨🇳 中文 ·
🇯🇵 日本語 ·
🇰🇷 한국어 ·
🇫🇷 Français ·
🇩🇪 Deutsch ·
🇪🇸 Español ·
🇧🇷 Português ·
🇷🇺 Русский ·
🇸🇦 العربية
🏆 Paper Showcase · 🧑✈️ Co-Pilot Guide · 📖 Integration Guide · 💬 Discord Community
|
🏆 Generated Paper Showcase
8 papers across 8 domains — math, statistics, biology, computing, NLP, RL, vision, robustness — generated fully autonomously or with Human-in-the-Loop co-pilot guidance.

|
🧪 We're looking for testers! Try the pipeline with your own research idea — from any field — and tell us what you think. Your feedback directly shapes the next version. → Testing Guide | → 中文测试指南 | → 日本語テストガイド
🔥 News
- [05/19/2026] v0.5.0 — Multi-Domain Experiment Agents + ARC-Bench — Two headline updates. (1) Domain-specialist execution agents: the experiment stage (Stages 10–13) now routes beyond the default ML sandbox to specialist agents per field — high-energy physics (ColliderAgent: Lagrangian → FeynRules → MadGraph5 → Delphes via the Magnus cloud), biology (COBRApy genome-scale metabolic modelling), and statistics (simulation-study agent), with a generic Docker executor covering chemistry/materials. The pipeline auto-selects the right executor from the research domain. (2) ARC-Bench: a 55-topic open-ended autonomous-research benchmark spanning ML (25), HEP (10), quantum (10), biology (7), and statistics (3) — each topic ships a manifest (research question + conditions + metrics + datasets) and a rubric for graded scoring, all under
experiments/arc_bench/, and also released on 🤗 Hugging Face. → Domain Integration Guide
- [04/01/2026] v0.4.0 — Human-in-the-Loop Co-Pilot System — AutoResearchClaw is no longer purely autonomous. New HITL system adds 6 intervention modes (
full-auto, gate-only, checkpoint, step-by-step, co-pilot, custom), per-stage policies, and deep human-AI collaboration. Includes: Idea Workshop for hypothesis co-creation, Baseline Navigator for experiment design review, Paper Co-Writer for collaborative drafting, SmartPause (confidence-driven dynamic intervention), ALHF intervention learning, anti-hallucination claim verification, cost budget guardrails, pipeline branching for parallel hypothesis exploration, and CLI commands (attach/status/approve/reject/guide). → Full HITL Guide
- [03/30/2026] Flexible Skill Loading — AutoResearchClaw now supports loading open-source and custom skills from any discipline to further enhance your research experience. 20 pre-loaded skills are included as ready-to-use references, covering scientific writing, experiment design, chemistry, biology, and more — including an A-Evolve agentic evolution skill contributed by the community. Load your own via
researchclaw skills install or drop a SKILL.md into .claude/skills/. See Skills Library.
- [03/22/2026] v0.3.2 — Cross-Platform Support + Major Stability — AutoResearchClaw now runs on any ACP-compatible agent backend (Claude Code, Codex CLI, Copilot CLI, Gemini CLI, Kimi CLI) and supports messaging platforms (Discord, Telegram, Lark, WeChat) via OpenClaw bridge. New CLI-agent code generation backend delegates Stages 10 & 13 to external CLI agents with budget control and timeout management. Also includes anti-fabrication system (VerifiedRegistry + experiment diagnosis & repair loop), 100+ bug fixes, modular executor refactoring,
--resume auto-detection, LLM retry hardening, and community-reported fixes.
Earlier releases
- [03/18/2026] v0.3.1 — OpenCode Beast Mode + Community Contributions — New "Beast Mode" routes complex code generation to OpenCode with automatic complexity scoring and graceful fallback. Added Novita AI provider support, thread-safety hardening, improved LLM output parsing robustness, and 20+ bug fixes from community PRs and internal audit.
- [03/17/2026] v0.3.0 — MetaClaw Integration — AutoResearchClaw now supports MetaClaw cross-run learning: pipeline failures → structured lessons → reusable skills, injected into all 23 stages. +18.3% robustness in controlled experiments. Opt-in (
metaclaw_bridge.enabled: true), fully backward-compatible. See Integration Guide.
- [03/16/2026] v0.2.0 — Three multi-agent subsystems (CodeAgent, BenchmarkAgent, FigureAgent), hardened Docker sandbox with network-policy-aware execution, 4-round paper quality audit (AI-slop detection, 7-dim review scoring, NeurIPS checklist), and 15+ bug fixes from production runs.
- [03/15/2026] v0.1.0 — We release AutoResearchClaw: a fully autonomous 23-stage research pipeline that turns a single research idea into a conference-ready paper. No human intervention required.
⚡ One Command. One Paper.
# Fully autonomous — no human intervention
pip install -e . && researchclaw setup && researchclaw init && researchclaw run --topic "Your research idea here" --auto-approve

# Co-Pilot mode — collaborate with AI at key decision points
researchclaw run --topic "Your research idea here" --mode co-pilot
🤔 What Is This?
You think it. AutoResearchClaw writes it. You guide the key decisions.
Drop a research topic — get back a full academic paper with real literature from OpenAlex, Semantic Scholar & arXiv, hardware-aware sandbox experiments (GPU/MPS/CPU auto-detected), statistical analysis, multi-agent peer review, and conference-ready LaTeX targeting NeurIPS/ICML/ICLR. Run it fully autonomous, or use Co-Pilot mode to guide the AI at critical decision points — choose research directions, review experiment designs, and co-write the paper. No hallucinated references.
| 📄 | paper_draft.md | Full academic paper (Introduction, Related Work, Method, Experiments, Results, Conclusion) |
| 📐 | paper.tex | Conference-ready LaTeX (NeurIPS / ICLR / ICML templates) |
| 📚 | references.bib | Real BibTeX references from OpenAlex, Semantic Scholar and arXiv — auto-pruned to match inline citations |
| 🔍 | verification_report.json | 4-layer citation integrity + relevance verification (arXiv, CrossRef, DataCite, LLM) |
| 🧪 | experiment runs/ | Generated code + sandbox results + structured JSON metrics |
| 📊 | charts/ | Auto-generated condition comparison charts with error bars and confidence intervals |
| 📝 | reviews.md | Multi-agent peer review with methodology-evidence consistency checks |
| 🧬 | evolution/ | Self-learning lessons extracted from each run |
| 📦 | deliverables/ | All final outputs in one folder — compile-ready for Overleaf |
The pipeline runs end-to-end — fully autonomous or with human-in-the-loop collaboration. When experiments fail, it self-heals. When hypotheses don't hold, it pivots. When citations are fake, it kills them. When you want to steer, it pauses and listens.
🌍 Run it anywhere. AutoResearchClaw isn't locked to a single platform. Use it standalone via CLI, plug it into OpenClaw, or wire it up through any ACP-compatible agent — 🤖 Claude Code, 💻 Codex CLI, 🐙 Copilot CLI, ♊ Gemini CLI, 🌙 Kimi CLI, you name it. And because OpenClaw bridges to messaging platforms, you can kick off a full research run from 💬 Discord, ✈️ Telegram, 🐦 Lark (飞书), 💚 WeChat, or wherever your team already hangs out. One topic in, one paper out — no matter where you type it.
🚀 Quick Start
# 1. Clone & install
git clone https://github.com/aiming-lab/AutoResearchClaw.git
cd AutoResearchClaw
python3 -m venv .venv && source .venv/bin/activate
pip install -e .

# 2. Setup (interactive — installs OpenCode beast mode, checks Docker/LaTeX)
researchclaw setup

# 3. Configure
researchclaw init          # Interactive: choose LLM provider, creates config.arc.yaml
# Or manually: cp config.researchclaw.example.yaml config.arc.yaml

# 4. Run
export OPENAI_API_KEY="sk-..."
researchclaw run --config config.arc.yaml --topic "Your research idea" --auto-approve
Output → artifacts/rc-YYYYMMDD-HHMMSS-<hash>/deliverables/ — compile-ready LaTeX, BibTeX, experiment code, charts.
📝 Minimum required config
project:
  name: "my-research"

research:
  topic: "Your research topic here"

llm:
  base_url: "https://api.openai.com/v1"
  api_key_env: "OPENAI_API_KEY"
  primary_model: "gpt-4o"
  fallback_models: ["gpt-4o-mini"]

experiment:
  mode: "sandbox"
  sandbox:
    python_path: ".venv/bin/python"
🧠 What Makes It Different
| Capability |
How It Works |
| 🧑✈️ Co-Pilot Mode |
6 intervention modes — from fully autonomous to step-by-step. Guide the AI at critical decisions (hypotheses, baselines, paper writing) or let it run free. SmartPause auto-detects when human input would help. |
| 🔄 PIVOT / REFINE Loop |
Stage 15 autonomously decides: PROCEED, REFINE (tweak params), or PIVOT (new direction). Artifacts auto-versioned. |
| 🤖 Multi-Agent Debate |
Hypothesis generation, result analysis, and peer review each use structured multi-perspective debate. |
| 🧬 Self-Learning |
Lessons extracted per run (decision rationale, runtime warnings, metric anomalies) with 30-day time-decay. Future runs learn from past mistakes. |
| 📚 Knowledge Base |
Every run builds structured KB across 6 categories (decisions, experiments, findings, literature, questions, reviews). |
| 🛡️ Sentinel Watchdog |
Background quality monitor: NaN/Inf detection, paper-evidence consistency, citation relevance scoring, anti-fabrication guard. |
| 🔍 Claim Verification |
Inline fact-checking: extracts claims from AI-generated text and cross-references against collected literature. Flags ungrounded citations and fabricated numbers. |
| 🌿 Branch Exploration |
Fork the pipeline to explore multiple research directions simultaneously, compare results side-by-side, and merge the best path forward. |
🦞 OpenClaw Integration
AutoResearchClaw is an OpenClaw-compatible service. Install it in OpenClaw and launch autonomous research with a single message — or use it standalone via CLI, Claude Code, or any AI coding assistant.
🚀 Use with OpenClaw (Recommended)
If you already use OpenClaw as your AI assistant:
1️⃣  Share the GitHub repo URL with OpenClaw
2️⃣  OpenClaw auto-reads RESEARCHCLAW_AGENTS.md → understands the pipeline
3️⃣  Say: "Research [your topic]"
4️⃣  Done — OpenClaw clones, installs, configures, runs, and returns results
That's it. OpenClaw handles git clone, pip install, config setup, and pipeline execution automatically. You just chat.
💡 What happens under the hood
- OpenClaw reads
RESEARCHCLAW_AGENTS.md → learns the research orchestrator role
- OpenClaw reads
README.md → understands installation and pipeline structure
- OpenClaw copies
config.researchclaw.example.yaml → config.yaml
- Asks for your LLM API key (or uses your environment variable)
- Runs
pip install -e . + researchclaw run --topic "..." --auto-approve
- Returns the paper, LaTeX, experiments, and citations
🔌 OpenClaw Bridge (Advanced)
For deeper integration, AutoResearchClaw includes a bridge adapter system with 6 optional capabilities:
# config.arc.yaml
openclaw_bridge:
  use_cron: true              # ⏰ Scheduled research runs
  use_message: true           # 💬 Progress notifications (Discord/Slack/Telegram)
  use_memory: true            # 🧠 Cross-session knowledge persistence
  use_sessions_spawn: true    # 🔀 Spawn parallel sub-sessions for concurrent stages
  use_web_fetch: true         # 🌐 Live web search during literature review
  use_browser: false          # 🖥️ Browser-based paper collection
Each flag activates a typed adapter protocol. When OpenClaw provides these capabilities, the adapters consume them without code changes. See docs/integration-guide.md for full details.
ACP (Agent Client Protocol)
AutoResearchClaw can use any ACP-compatible coding agent as its LLM backend — no API keys required. The agent communicates via acpx, maintaining a single persistent session across all 23 pipeline stages.
| Agent |
Command |
Notes |
| Claude Code |
claude |
Anthropic |
| Codex CLI |
codex |
OpenAI |
| Copilot CLI |
gh |
GitHub |
| Gemini CLI |
gemini |
Google |
| OpenCode |
opencode |
SST |
| Kimi CLI |
kimi |
Moonshot |
# config.yaml — ACP example
llm:
  provider: "acp"
  acp:
    agent: "claude"   # Any ACP-compatible agent CLI command
    cwd: "."          # Working directory for the agent
  # No base_url or api_key needed — the agent handles its own auth.
# Just run — the agent uses its own credentials
researchclaw run --config config.yaml --topic "Your research idea" --auto-approve
🛠️ Other Ways to Run
| Method |
How |
| Standalone CLI |
researchclaw run --topic "..." --auto-approve (autonomous) or --mode co-pilot (collaborative) |
| Python API |
from researchclaw.pipeline import Runner; Runner(config).run() |
| Claude Code |
Reads RESEARCHCLAW_CLAUDE.md — just say "Run research on [topic]" |
| Copilot CLI |
researchclaw run --topic "..." with llm.acp.agent: "gh" |
| OpenCode |
Reads .claude/skills/ — same natural language interface |
| Any AI CLI |
Provide RESEARCHCLAW_AGENTS.md as context → agent auto-bootstraps |
🔬 Pipeline: 23 Stages, 8 Phases
Phase A: Research Scoping          Phase E: Experiment Execution
  1. TOPIC_INIT                      12. EXPERIMENT_RUN
  2. PROBLEM_DECOMPOSE               13. ITERATIVE_REFINE  ← self-healing

Phase B: Literature Discovery      Phase F: Analysis & Decision
  3. SEARCH_STRATEGY                 14. RESULT_ANALYSIS    ← multi-agent
  4. LITERATURE_COLLECT  ← real API  15. RESEARCH_DECISION  ← PIVOT/REFINE
  5. LITERATURE_SCREEN   [gate]
  6. KNOWLEDGE_EXTRACT               Phase G: Paper Writing
                                     16. PAPER_OUTLINE
Phase C: Knowledge Synthesis         17. PAPER_DRAFT
  7. SYNTHESIS                       18. PEER_REVIEW        ← evidence check
  8. HYPOTHESIS_GEN    ← debate      19. PAPER_REVISION

Phase D: Experiment Design         Phase H: Finalization
  9. EXPERIMENT_DESIGN   [gate]      20. QUALITY_GATE      [gate]
 10. CODE_GENERATION                 21. KNOWLEDGE_ARCHIVE
 11. RESOURCE_PLANNING               22. EXPORT_PUBLISH     ← LaTeX
                                     23. CITATION_VERIFY    ← relevance check
Gate stages (5, 9, 20) pause for human approval or auto-approve with --auto-approve. On rejection, the pipeline rolls back.
Co-Pilot mode (--mode co-pilot): Deep human-AI collaboration at Stages 7-8 (Idea Workshop), Stage 9 (Baseline Navigator), and Stages 16-17 (Paper Co-Writer). Other stages auto-execute with SmartPause monitoring.
Decision loops: Stage 15 can trigger REFINE (→ Stage 13) or PIVOT (→ Stage 8), with automatic artifact versioning.
📋 What Each Phase Does
| Phase |
What Happens |
| A: Scoping |
LLM decomposes the topic into a structured problem |

 AutoResearchClaw is a fully autonomous, self-evolving research pipeline that turns a single research idea into a complete, conference-ready academic paper, handling literature review, sandboxed experiments, statistical analysis, multi-agent peer review and LaTeX writing end-to-end.