cheat-on-content README

The project's README from github.com/XBuilderLAB/cheat-on-content. As one markdown file: README.md.

Cheat on Content

Cheat on Content

English  ·  简体中文

Watcha Hot List · 观猹热榜 · #1

Version   License

For content creators — a skill that turns every post into a calibrated experiment.

You're reading this. The skill predicted it.
It turns every "I feel this will go viral" into a calibrated experiment.
It took me from zero to 1M followers in a month. It said I'd write this. I did.
Your doubt — predicted too.


🎬 What it actually does

Most creators live in the same gambling loop:

Publish → Numbers come in → Learn nothing → Roll the dice again

A creator who's shipped 200 pieces is barely 10% sharper than someone who's shipped 1 — because they never kept books after each round.

Cheat on Content makes every judgment get logged, retrospected, absorbed into the next:

📊 Score → 🎯 Blind-predict → 🚀 Publish → 📈 T+3d retro → 🧬 Evolve your rubric

This isn't motivation. It's compounding — every piece you don't retro is silently eroding your ability to see yourself.

One month in = you have a hit-formula that's only yours. Three months in = you're 10× sharper than your first-day self.


🌀 Origin

I never believed in fate. Until this skill made me film a video — and predicted exactly how much traffic that video would pull.

I tried to break it. I told my audience. I hoped collective observation would collapse the wave function and shift the trajectory.

The data was accurate.

I didn't escape fate. I just moved from first-order to second-order.

If even my awakening — even my audience's observation — was already in its prediction, then right now, reading this: are you here out of curiosity, or just closing the algorithm's last move?

— the creator


⚖️ How it differs from other "creator tools"

Others This
Give you "inspiration" Make your own intuition measurable
AI writes for you AI judges for you — the script stays yours
Ship 10 versions, A/B test Ship one — bet in writing, settle the books with data
Static dashboard An evolving rubric — your formula 3 months from now isn't the starting one

In a sentence: other tools help you "ship more." This helps you "judge sharper."


🤔 Can't I just use ChatGPT / DeepSeek / Doubao?

Those are general assistants — they tell everyone the same thing. You ask "will this go viral?" and the answer is fitted to global average opinion, not your channel. Ask again tomorrow — same answer. It doesn't remember you. It doesn't change because of you.

This is your own ops expert — serving only your one channel:

General LLMs help everyone. This helps your account.


🛡️ Why the loop actually evolves

📝 Every piece is logged: Score and prediction get written before publish, archived end-to-end. Three days later you settle accounts — you see exactly where you were sharp, where you were off. No more vague "I feel this one didn't land."

🔁 It gets sharper: Three same-direction misses in a row, the tool actively prompts you to upgrade your scoring formula. You don't have to remember — it remembers for you.

🛡️ Upgrades have a brake: Switching the formula requires re-scoring all historical samples — only released if it ranks more accurately than the old. Plus a cross-model independent audit — so you can't fool yourself.

🪒 The rubric is a workbench, not a museum: Observations refuted by data get deleted; observations absorbed into formal dimensions also get deleted. It only holds what's most useful right now.


📦 Install

git clone https://github.com/XBuilderLAB/cheat-on-content.git
cd cheat-on-content
bash install.sh

⚠️ Upgrading from v0.x? Run /cheat-migrate in your content project after git pull. The 1.3 → 1.4 migration is BREAKING for blind-channel integrity — it splits rubric_notes.md so the blind sub-agent can't leak actuals. Without migrate, blind scoring will keep flagging non_blind_warning. See CHANGELOG and migrations/1.3-to-1.4.md.

14 sub-skills are symlinked into your agent's skill directory. One install, every content project gets it.

Supported agents: Claude Code (default) · Codex (bash install.sh --codex) · Both (bash install.sh --all)

Frozen version: bash install.sh --copy / bash install.sh --codex --copy

Uninstall: bash uninstall.sh / bash uninstall.sh --codex (your content data is not touched)


🚀 First run

In your content project directory, open a skill-compatible agent and say:

初始化 cheat-on-content

(or init cheat-on-content)

Five yes/no questions complete onboarding. Strongly recommend importing a benchmark account — 5–10 samples and the tool gets an anchor immediately. Without one, your first 5 predictions land at ±50% precision.


⚡ Daily use

score this scripts/<...>.md       → grade only
start prediction scripts/<...>.md → blind prediction + decision log
shot scripts/<...>.md             → create video folder + buffer +1
shipped https://...                → buffer -1
retro videos/<...>/                → T+3d data + retrospective
status / fetch trends / find topic / bump rubric / find benchmark

Hook-aware agents auto-report buffer + pending retros + top candidates at every session start — no need to ask. Other agents: just say status.

Full workflow + sub-skill details: see SKILL.md.


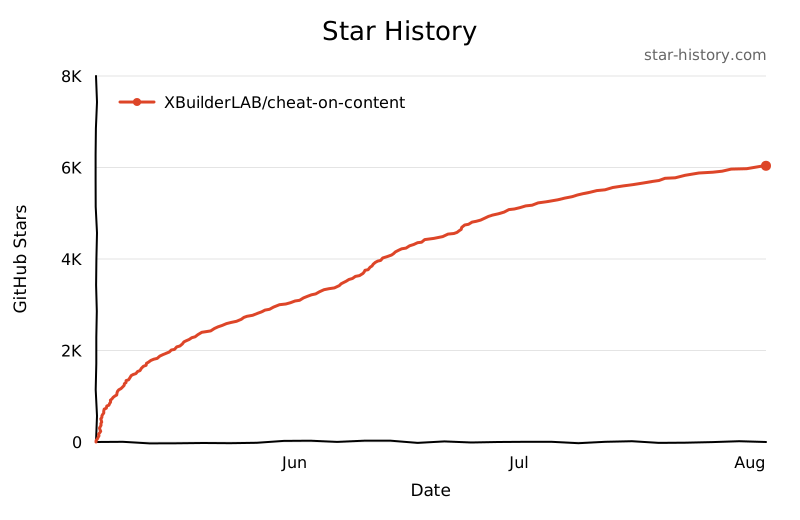
📈 Star History

Star History Chart

📜 License

MIT. Commercial use, modification, closed-source integration — all fine.


Is this cheating? So was the calculator. So was Google. The future doesn't reward effort — it rewards those who see the pattern first.

You reading this line — that's predicted too.

cheat-on-content (XBuilderLAB/cheat-on-content)

Searching Database…

这是干什么的?这是一个面向内容创作者的 AI 编程 agent 技能:每篇发布的内容都变成一次经过校准的实验——先打分、盲测预测它的表现、发布,然后在三天后复盘真实数据,并不断迭代你的评分标准。作者称靠它一个月内从 0 涨到了 100 万粉丝。
那它是一个独立应用,还是装在我的 AI agent 里的东西?它装在你的 AI agent 里,不是独立应用:安装程序会把 14 个子技能以符号链接的方式放进 agent 的技能目录,装一次就能覆盖你所有的内容项目。
我该怎么安装并开始使用?在仓库里运行 bash install.sh,然后在你的内容项目中打开一个支持技能的 agent,说 'init cheat-on-content'——回答五个是否问题就能完成初始化。
哪些编程 agent 可以运行它?Claude Code 默认就能用,Codex 用 bash install.sh --codex 安装,两个都要就用 --all。支持钩子的 agent 会在每次会话开始时自动汇报缓冲中的复盘和待复盘条目;用其他 agent 的话,你只需说 'status'。
我刚开始用的时候,它的预测能准吗?冷启动是个坎:如果没有导入一个基准账号的数据(5–10 个样本),你的前 5 次预测精度只有 ±50%。另外,1.3 升级到 1.4 是一次破坏性迁移——git pull 之后要运行 /cheat-migrate,否则盲测评分会一直报 nonblindwarning。
它是给谁用的?我必须是开发者才能用吗?适合经常发布内容、希望把自己的直觉变成可量化而非自我合理化的创作者。你确实需要一个像 Claude Code 或 Codex 这样的编程 agent,还要用终端执行 bash 安装,所以对开发工具有一定熟悉度会更有帮助。
操作系统对这个有影响吗?唯一的要求是你的编程 agent 得能在上面运行——本项目支持 Linux、macOS 和 Windows。
可以免费使用吗?商用呢?可以——MIT 许可证,明确允许商用、修改和集成到闭源项目中。
这和直接问 ChatGPT 我这篇内容能不能火有什么区别?通用助手只会按全网平均水平回答,回复完就把你忘了。这个技能会从你自己频道的历史数据中反推出一套评分公式,每发一篇就更新一次,并记住你的基准账号、发布节奏和最近三次翻车的作品。
完整用一轮是什么样子的?发布前你先给内容打分并记录一个盲测预测,三天后再拿真实数据对账。整个循环是:打分 → 盲测预测 → 发布 → 三天后复盘 → 迭代公式;如果连续三次预测偏差方向一致,它会提示你升级公式。
它怎么防止我自欺欺人地打高分?每次切换公式都会强制对所有历史样本重新打分,只有新标准比旧的排名更准才会生效,另外还有一次跨模型的独立审计。被数据推翻的观察会被删掉,所以评分标准里留下的只是当下真正有效的东西。
如果我卸载它,已记录的预测数据会丢吗?不会——bash uninstall.sh(或 bash uninstall.sh --codex)只把技能从你的 agent 里移除,你的内容数据完全不受影响。
Size
0.5 MB
Stars
7.3K
Updated
CommitOct 12
Age
5mo
Commits · 90 Days
