Please check out our new release on YOLOE.

Comparison of performance, training cost, and inference efficiency between YOLOE (Ours) and YOLO-Worldv2 in terms of open text prompts.
YOLOE(ye) is a highly efficient, unified, and open object detection and segmentation model for real-time seeing anything, like human eye, under different prompt mechanisms, like texts, visual inputs, and prompt-free paradigm, with zero inference and transferring overhead compared with closed-set YOLOs.

Abstract
Object detection and segmentation are widely employed in computer vision applications, yet conventional models like YOLO series, while efficient and accurate, are limited by predefined categories, hindering adaptability in open scenarios. Recent open-set methods leverage text prompts, visual cues, or prompt-free paradigm to overcome this, but often compromise between performance and efficiency due to high computational demands or deployment complexity. In this work, we introduce YOLOE, which integrates detection and segmentation across diverse open prompt mechanisms within a single highly efficient model, achieving real-time seeing anything. For text prompts, we propose Re-parameterizable Region-Text Alignment (RepRTA) strategy. It refines pretrained textual embeddings via a re-parameterizable lightweight auxiliary network and enhances visual-textual alignment with zero inference and transferring overhead. For visual prompts, we present Semantic-Activated Visual Prompt Encoder (SAVPE). It employs decoupled semantic and activation branches to bring improved visual embedding and accuracy with minimal complexity. For prompt-free scenario, we introduce Lazy Region-Prompt Contrast (LRPC) strategy. It utilizes a built-in large vocabulary and specialized embedding to identify all objects, avoiding costly language model dependency. Extensive experiments show YOLOE's exceptional zero-shot performance and transferability with high inference efficiency and low training cost. Notably, on LVIS, with $3\times$ less training cost and $1.4\times$ inference speedup, YOLOE-v8-S surpasses YOLO-Worldv2-S by 3.5 AP. When transferring to COCO, YOLOE-v8-L achieves 0.6 $AP^b$ and 0.4 $AP^m$ gains over closed-set YOLOv8-L with nearly $4\times$ less training time.

Official PyTorch implementation of YOLOv10. NeurIPS 2024.
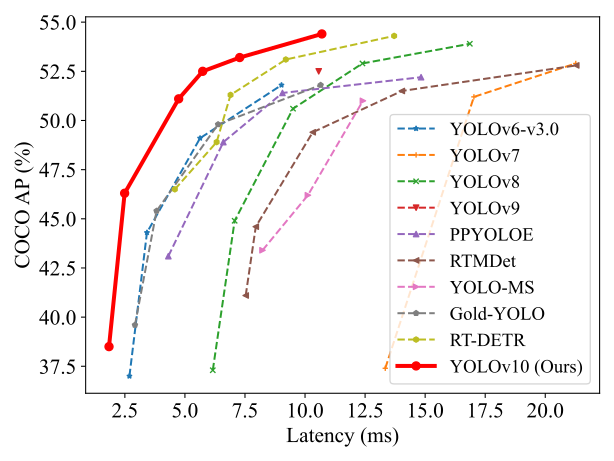
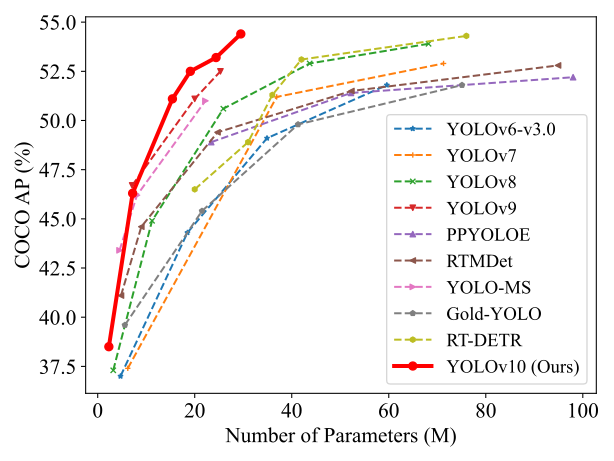
Comparisons with others in terms of latency-accuracy (left) and size-accuracy (right) trade-offs.
YOLOv10: Real-Time End-to-End Object Detection.
Ao Wang, Hui Chen, Lihao Liu, Kai Chen, Zijia Lin, Jungong Han, and Guiguang Ding




Abstract
Over the past years, YOLOs have emerged as the predominant paradigm in the field of real-time object detection owing to their effective balance between computational cost and detection performance. Researchers have explored the architectural designs, optimization objectives, data augmentation strategies, and others for YOLOs, achieving notable progress. However, the reliance on the non-maximum suppression (NMS) for post-processing hampers the end-to-end deployment of YOLOs and adversely impacts the inference latency. Besides, the design of various components in YOLOs lacks the comprehensive and thorough inspection, resulting in noticeable computational redundancy and limiting the model's capability. It renders the suboptimal efficiency, along with considerable potential for performance improvements. In this work, we aim to further advance the performance-efficiency boundary of YOLOs from both the post-processing and the model architecture. To this end, we first present the consistent dual assignments for NMS-free training of YOLOs, which brings the competitive performance and low inference latency simultaneously. Moreover, we introduce the holistic efficiency-accuracy driven model design strategy for YOLOs. We comprehensively optimize various components of YOLOs from both the efficiency and accuracy perspectives, which greatly reduces the computational overhead and enhances the capability. The outcome of our effort is a new generation of YOLO series for real-time end-to-end object detection, dubbed YOLOv10. Extensive experiments show that YOLOv10 achieves the state-of-the-art performance and efficiency across various model scales. For example, our YOLOv10-S is 1.8$\times$ faster than RT-DETR-R18 under the similar AP on COCO, meanwhile enjoying 2.8$\times$ smaller number of parameters and FLOPs. Compared with YOLOv9-C, YOLOv10-B has 46\% less latency and 25\% fewer parameters for the same performance.
Notes
- 2024/05/31: Please use the exported format for benchmark. In the non-exported format, e.g., pytorch, the speed of YOLOv10 is biased because the unnecessary
cv2 and cv3 operations in the v10Detect are executed during inference.
- 2024/05/30: We provide some clarifications and suggestions for detecting smaller objects or objects in the distance with YOLOv10. Thanks to SkalskiP!
- 2024/05/27: We have updated the checkpoints with class names, for ease of use.
UPDATES 🔥
COCO
| Model |
Test Size |
#Params |
FLOPs |
APval |
Latency |
| YOLOv10-N |
640 |
2.3M |
6.7G |
38.5% |
1.84ms |
| YOLOv10-S |
640 |
7.2M |
21.6G |
46.3% |
2.49ms |
| YOLOv10-M |
640 |
15.4M |
59.1G |
51.1% |
4.74ms |
| YOLOv10-B |
640 |
19.1M |
92.0G |
52.5% |
5.74ms |
| YOLOv10-L |
640 |
24.4M |
120.3G |
53.2% |
7.28ms |
| YOLOv10-X |
640 |
29.5M |
160.4G |
54.4% |
10.70ms |
Installation
conda virtual environment is recommended.
conda create -n yolov10 python=3.9
conda activate yolov10
pip install -r requirements.txt
pip install -e .
Demo
python app.py
# Please visit http://127.0.0.1:7860
Validation
yolov10n yolov10s yolov10m yolov10b yolov10l yolov10x
yolo val model=jameslahm/yolov10{n/s/m/b/l/x} data=coco.yaml batch=256
Or
from ultralytics import YOLOv10

model = YOLOv10.from_pretrained('jameslahm/yolov10{n/s/m/b/l/x}')
# or
# wget https://github.com/THU-MIG/yolov10/releases/download/v1.1/yolov10{n/s/m/b/l/x}.pt
model = YOLOv10('yolov10{n/s/m/b/l/x}.pt')

model.val(data='coco.yaml', batch=256)
Training
yolo detect train data=coco.yaml model=yolov10n/s/m/b/l/x.yaml epochs=500 batch=256 imgsz=640 device=0,1,2,3,4,5,6,7
Or
from ultralytics import YOLOv10

model = YOLOv10()
# If you want to finetune the model with pretrained weights, you could load the
# pretrained weights like below
# model = YOLOv10.from_pretrained('jameslahm/yolov10{n/s/m/b/l/x}')
# or
# wget https://github.com/THU-MIG/yolov10/releases/download/v1.1/yolov10{n/s/m/b/l/x}.pt
# model = YOLOv10('yolov10{n/s/m/b/l/x}.pt')

model.train(data='coco.yaml', epochs=500, batch=256, imgsz=640)
Push to hub to 🤗
Optionally, you can push your fine-tuned model to the Hugging Face hub as a public or private model:
# let's say you have fine-tuned a model for crop detection
model.push_to_hub("<your-hf-username-or-organization/yolov10-finetuned-crop-detection")

# you can also pass `private=True` if you don't want everyone to see your model
model.push_to_hub("<your-hf-username-or-organization/yolov10-finetuned-crop-detection", private=True)
Prediction
Note that a smaller confidence threshold can be set to detect smaller objects or objects in the distance. Please refer to here for details.
yolo predict model=jameslahm/yolov10{n/s/m/b/l/x}
Or
from ultralytics import YOLOv10

model = YOLOv10.from_pretrained('jameslahm/yolov10{n/s/m/b/l/x}')
# or
# wget https://github.com/THU-MIG/yolov10/releases/download/v1.1/yolov10{n/s/m/b/l/x}.pt
model = YOLOv10('yolov10{n/s/m/b/l/x}.pt')

model.predict()
Export
# End-to-End ONNX
yolo export model=jameslahm/yolov10{n/s/m/b/l/x} format=onnx opset=13 simplify
# Predict with ONNX
yolo predict model=yolov10n/s/m/b/l/x.onnx

# End-to-End TensorRT
yolo export model=jameslahm/yolov10{n/s/m/b/l/x} format=engine half=True simplify opset=13 workspace=16
# or
trtexec --onnx=yolov10n/s/m/b/l/x.onnx --saveEngine=yolov10n/s/m/b/l/x.engine --fp16
# Predict with TensorRT
yolo predict model=yolov10n/s/m/b/l/x.engine
Or
from ultralytics import YOLOv10

model = YOLOv10.from_pretrained('jameslahm/yolov10{n/s/m/b/l/x}')
# or
# wget https://github.com/THU-MIG/yolov10/releases/download/v1.1/yolov10{n/s/m/b/l/x}.pt
model = YOLOv10('yolov10{n/s/m/b/l/x}.pt')

model.export(...)
Acknowledgement
The code base is built with ultralytics and RT-DETR.
Thanks for the great implementations!
Citation
If our code or models help your work, please cite our paper:
@article{wang2024yolov10,
  title={YOLOv10: Real-Time End-to-End Object Detection},
  author={Wang, Ao and Chen, Hui and Liu, Lihao and Chen, Kai and Lin, Zijia and Han, Jungong and Ding, Guiguang},
  journal={arXiv preprint arXiv:2405.14458},
  year={2024}
}

 YOLOv10 is a real-time object detection model (NeurIPS 2024) that removes the need for non-maximum suppression (NMS) post-processing, enabling true end-to-end detection with lower latency than previous YOLO versions.