

3.6K ·GitHub
Что это?
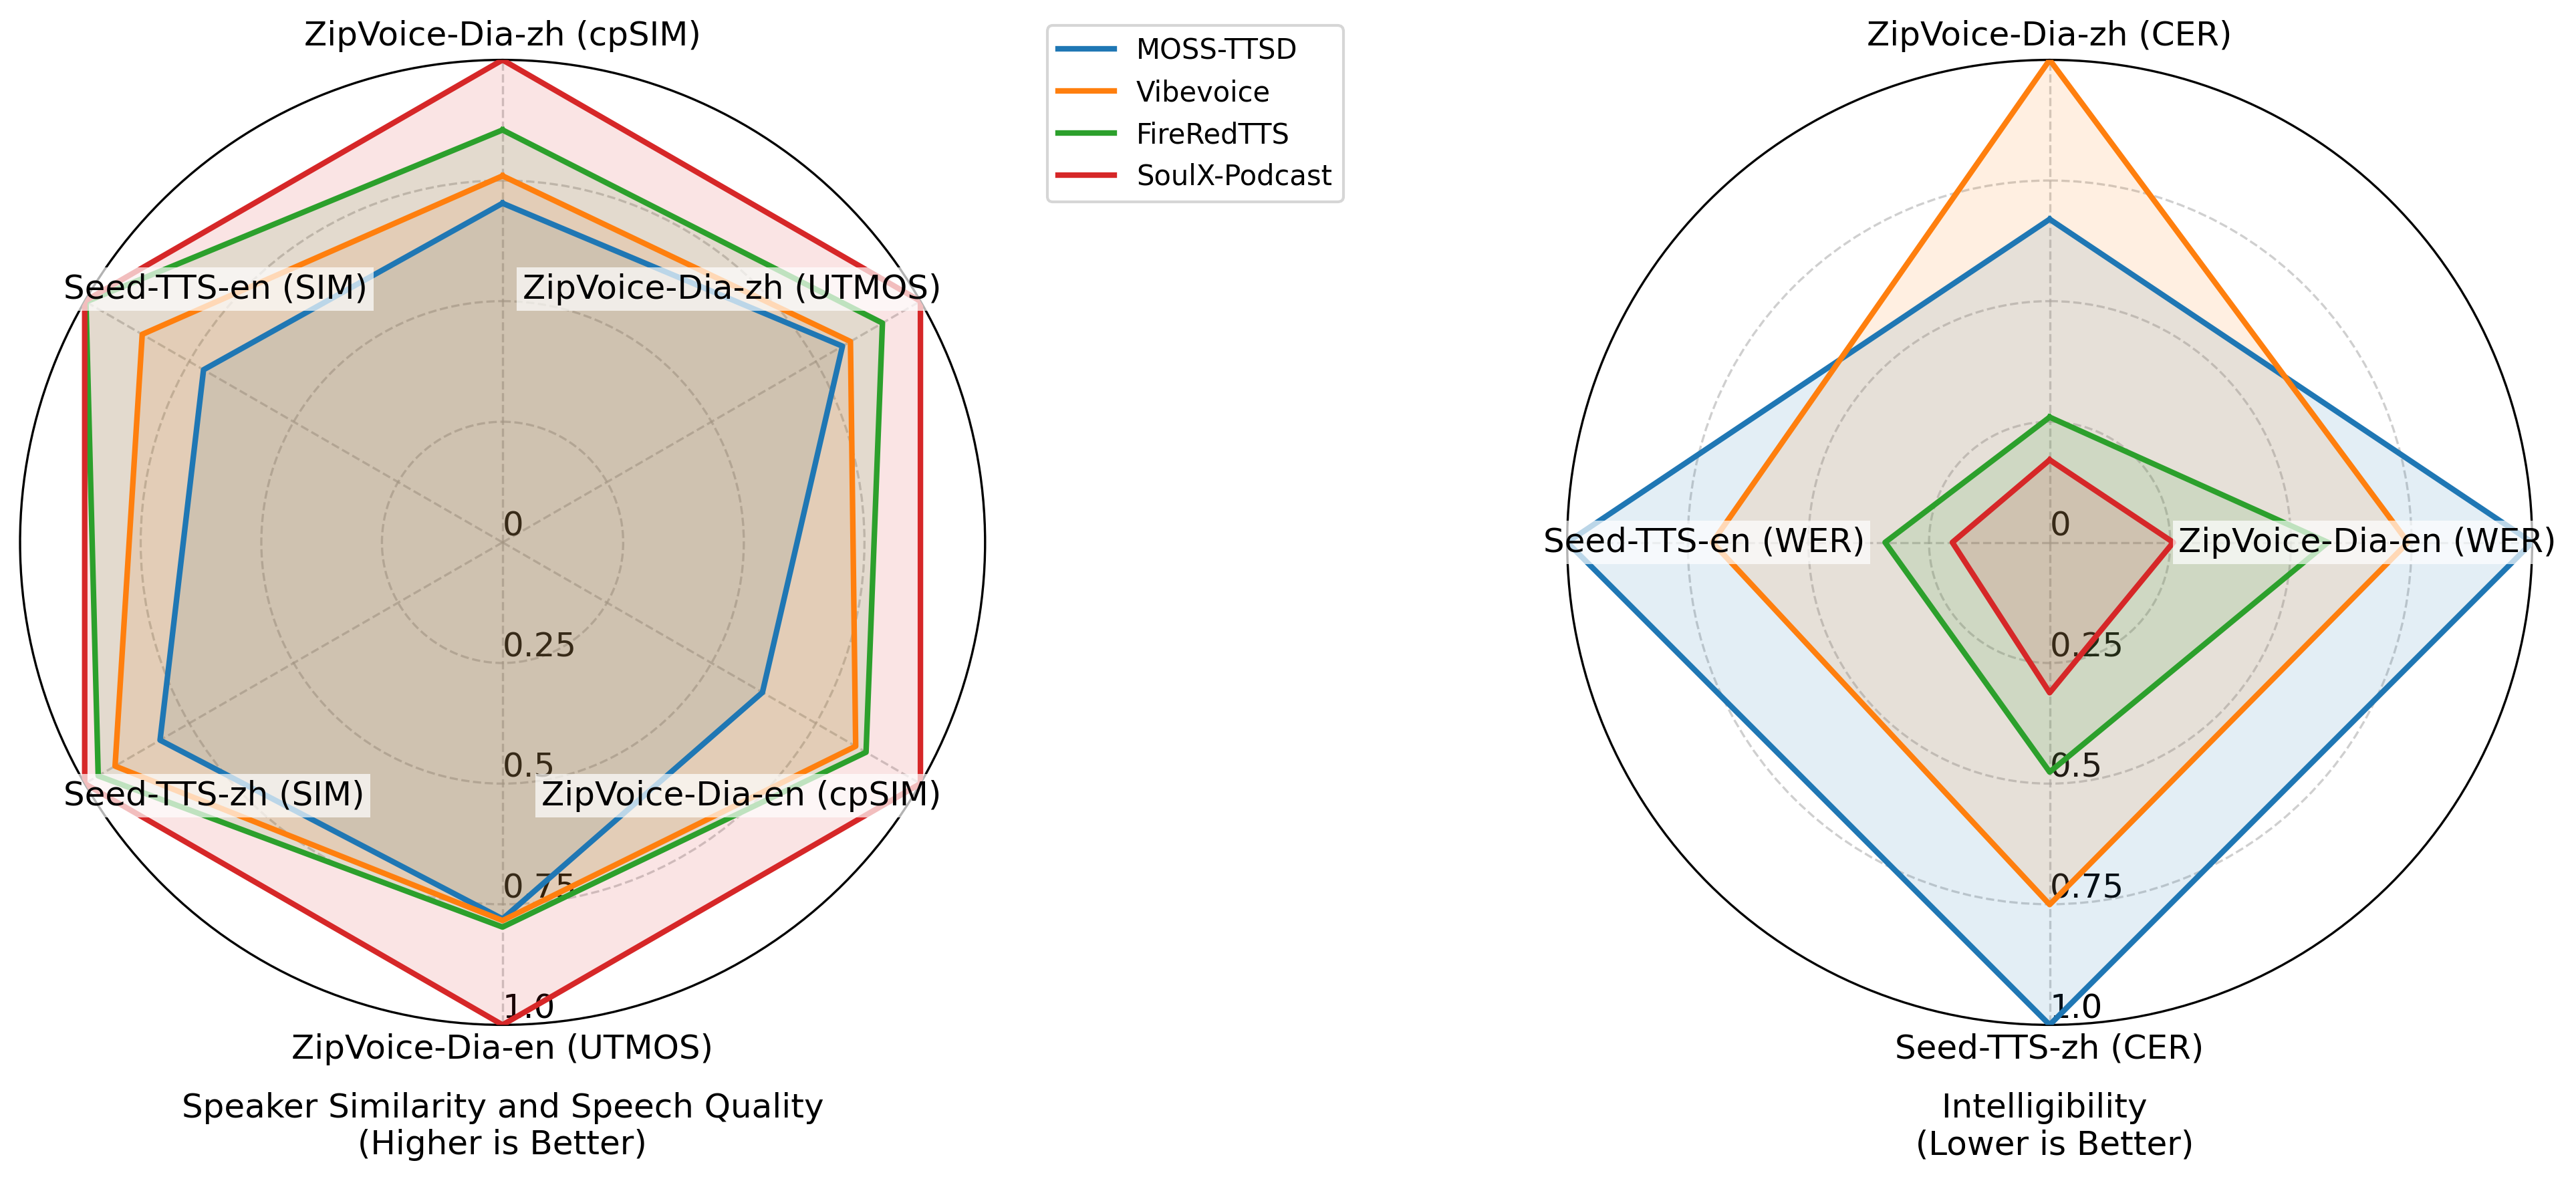
 SoulX-Podcast — кодовая база для инференса, которая генерирует по тексту реалистичные длинные диалоги в стиле подкаста с несколькими дикторами, включая паралингвистические эффекты и несколько китайских диалектов.
Это готовое приложение или код, который я запускаю сам?Это исследовательская кодовая база, а не упакованное приложение: вы клонируете репозиторий, скачиваете чекпойнты моделей и сами запускаете прилагаемые скрипты или WebUI.
Это исследовательская кодовая база, а не упакованное приложение: вы клонируете репозиторий, скачиваете чекпойнты моделей и сами запускаете прилагаемые скрипты или WebUI.Как его запустить?Склонируйте репозиторий, установите Conda, создайте Conda-окружение, затем скачайте чекпойнты моделей с Hugging Face (через Python-скрипт или git clone), прежде чем запускать демо или скрипты WebUI.
Склонируйте репозиторий, установите Conda, создайте Conda-окружение, затем скачайте чекпойнты моделей с Hugging Face (через Python-скрипт или git clone), прежде чем запускать демо или скрипты WebUI.Что нужно перед установкой?Нужны Conda, машина с Linux и чекпойнты модели SoulX-Podcast с Hugging Face; опционально для более быстрого инференса можно использовать модифицированную сборку vLLM 0.10.1.
Нужны Conda, машина с Linux и чекпойнты модели SoulX-Podcast с Hugging Face; опционально для более быстрого инференса можно использовать модифицированную сборку vLLM 0.10.1.Есть ли подводные камни при установке или отсутствующие функции на данный момент?Инструкции по установке охватывают только Linux, а потоковый инференс все еще числится в открытом TODO, а не как доступная сегодня возможность.
Инструкции по установке охватывают только Linux, а потоковый инференс все еще числится в открытом TODO, а не как доступная сегодня возможность.Для кого это предназначено?Оно нацелено на исследователей и разработчиков, работающих над TTS в стиле подкастов и клонированием голоса, а использование ограничено академическими, образовательными и другими законными применениями согласно дисклеймеру проекта.
Оно нацелено на исследователей и разработчиков, работающих над TTS в стиле подкастов и клонированием голоса, а использование ограничено академическими, образовательными и другими законными применениями согласно дисклеймеру проекта.Каковы условия лицензии?Код выпущен под Apache 2.0, но авторы явно запрещают недобросовестное использование, например несанкционированное клонирование голоса, выдачу себя за другого, мошенничество или дипфейки.
Код выпущен под Apache 2.0, но авторы явно запрещают недобросовестное использование, например несанкционированное клонирование голоса, выдачу себя за другого, мошенничество или дипфейки.Какие диалекты он поддерживает помимо мандаринского и английского?Поддерживается несколько китайских диалектов, включая сычуаньский, хэнаньский и кантонский, для zero-shot клонирования голоса и генерации речи.
Поддерживается несколько китайских диалектов, включая сычуаньский, хэнаньский и кантонский, для zero-shot клонирования голоса и генерации речи.Может ли он добавлять в речь естественные эффекты вроде смеха?Да, есть паралингвистические теги для эффектов вроде смеха и вздохов, чтобы генерируемый диалог звучал реалистичнее.
Да, есть паралингвистические теги для эффектов вроде смеха и вздохов, чтобы генерируемый диалог звучал реалистичнее.Есть ли веб-интерфейс или только скрипты командной строки?Помимо демонстрационных скриптов командной строки для монологового TTS есть WebUI для удобного инференса.
Помимо демонстрационных скриптов командной строки для монологового TTS есть WebUI для удобного инференса.Можно ли ускорить инференс или запустить его в контейнере?Да, проект поставляет модифицированную сборку vLLM 0.10.1 для ускорения, а с ноября 2025 года также поддерживает запуск через Docker с vLLM.
Да, проект поставляет модифицированную сборку vLLM 0.10.1 для ускорения, а с ноября 2025 года также поддерживает запуск через Docker с vLLM.What are similar projects?VoxCPM, ChatTTS, Index-Translate, fish-speech, MOSS-TTS, MOSS-TTS-Nano, FireRedTTS3, Speech
VoxCPM, ChatTTS, Index-Translate, fish-speech, MOSS-TTS, MOSS-TTS-Nano, FireRedTTS3, SpeechWhich topics is it in?podcast, speech, speech-synthesis, webui, tts, vllm, text-to-speech, academic-research, multilingual, audio, inference, huggingface
podcast, speech, speech-synthesis, webui, tts, vllm, text-to-speech, academic-research, multilingual, audio, inference, huggingface