Gander: Omni Interaction Agent
Natural voice interaction, continuous omni perception, and long-horizon agentic execution in one system.

Talk while it works.
Interrupt it, redirect it, or show it what you see without stopping the task.
News ·
Demo ·
System ·
Evaluation ·
Quick Start ·
Training ·
Inference ·
Citation
📰 News
- 2026-09-10: The dataset is currently undergoing the open source release process and will be made publicly available soon.
- 2026-09-09: Gander is officially released.
✨ Overview
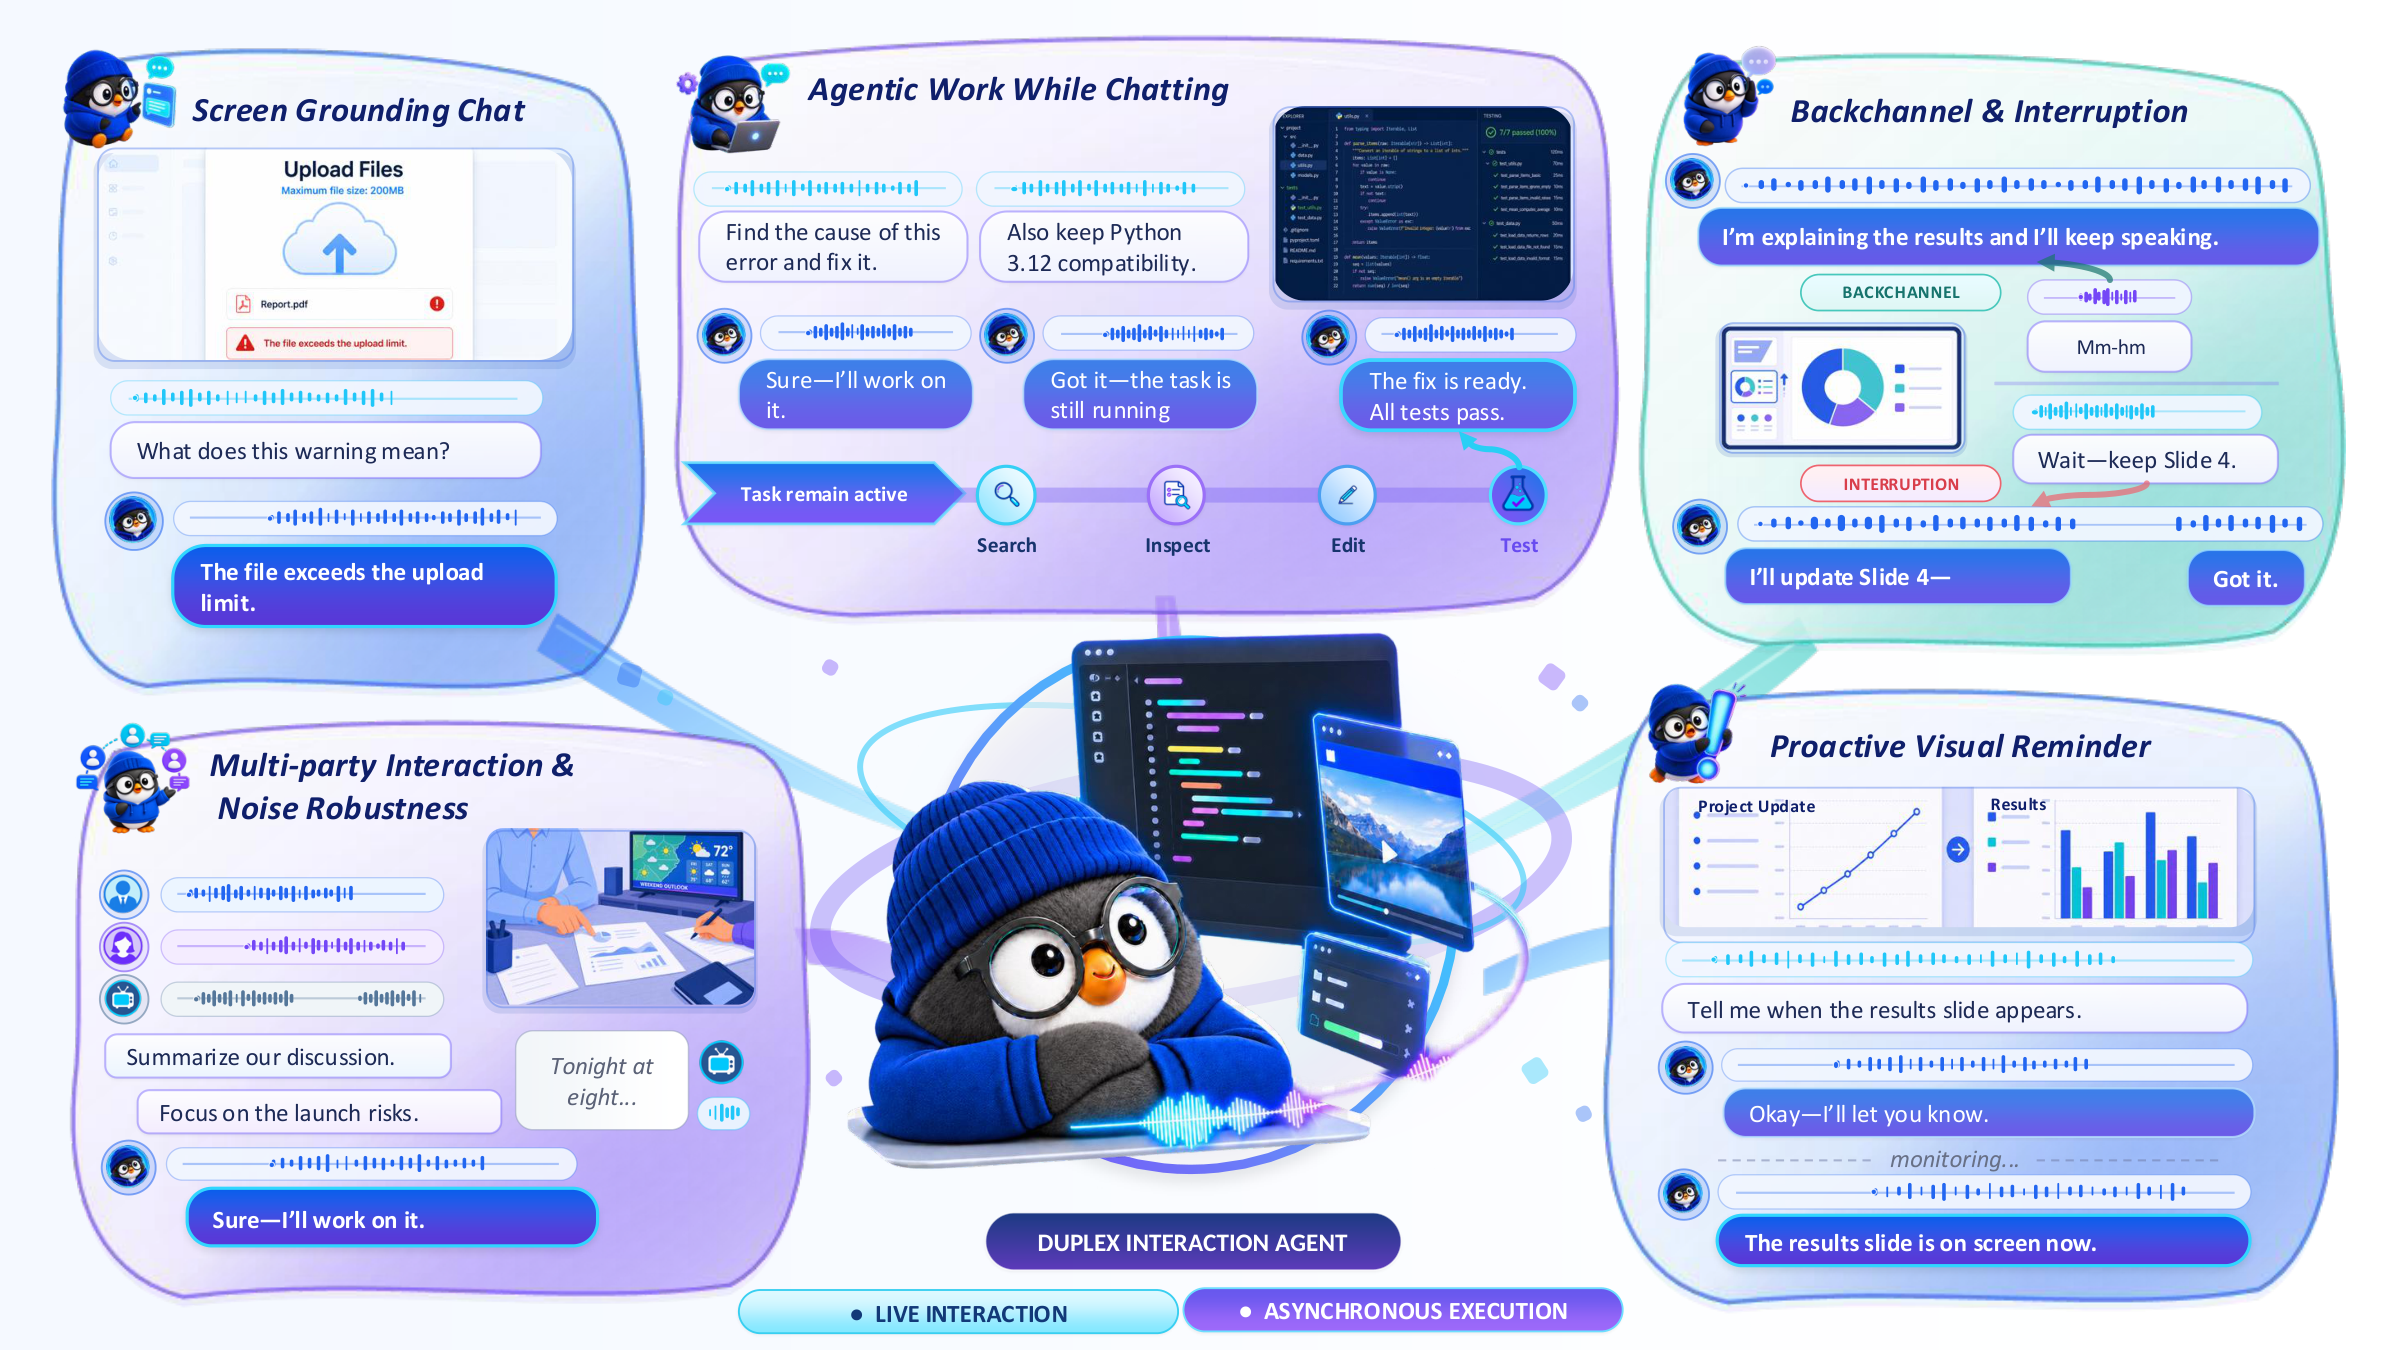
Gander is an open-source, end-to-end omni interaction agent that keeps the conversation flowing while getting work done. It unifies natural voice chat, native full-duplex interaction, and continuous multimodal perception—so you can speak, interrupt, or share your screen while work continues.
Trained for spoken collaboration, Gander combines natural, expressive dialogue with competitive knowledge and instruction-following performance. Its Cerebellum-Brain architecture pairs a capable streaming conversational model with an asynchronous reasoning agent, bringing responsive interaction and long-running execution into the same conversation.
- Natural conversation, learned interaction. Turn-taking, backchannels, overlap handling, interruption, and proactive responses are learned model behaviors. Gander learns both what to say and when to say it.
- See and hear as events unfold. Speech, video, and text share a causal timeline, grounding dialogue in your words, your screen, and the changing scene around you.
- Keep talking while it works. Delegate complex tasks and stay involved throughout execution: refine requirements, ask follow-up questions, check progress, grant permissions, or cancel—all through the ongoing conversation.
🎬 Demo

▶ Watch the Gander demo on YouTube
🧠 System Design
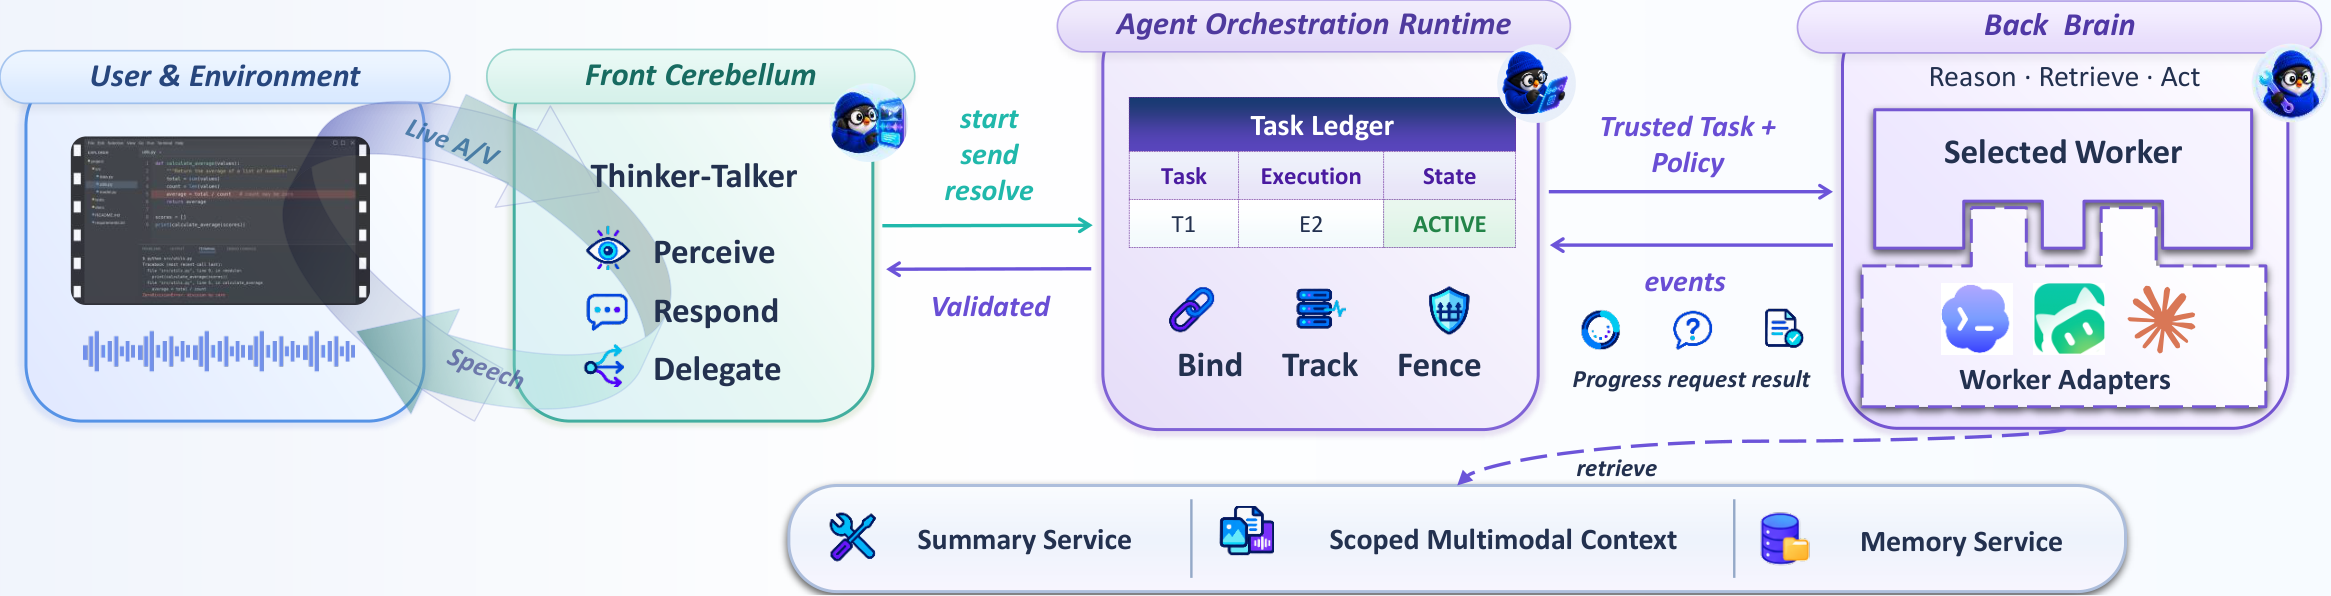
The Cerebellum owns realtime interaction, the Brain owns long-horizon work, and the runtime connects both on one task timeline.
The system separates responsibilities without separating the conversation:
| Module |
Implementation |
Responsibility |
| Streaming Cerebellum |
minicpm_ft |
Realtime audio-visual perception, interaction control, text generation, and speech synthesis. |
| Agent Orchestration Runtime |
gander_runtime |
Trusted-turn binding, task state, multimodal context, worker events, permissions, and delivery. |
| Pluggable Back Brain |
Provider interface |
Long-horizon reasoning, tool use, file and application operations, and workflow execution. |
A live request follows one causal path:
- The browser streams microphone audio and optional camera or screen frames.
Source timestamps align visual evidence with the audio captured at that time.
- The Cerebellum predicts whether to listen, speak, interrupt, or invoke a task
operation. Simple requests are answered locally.
- The runtime binds agentic work to the finalized user turn and starts a tracked
Brain execution with bounded text and visual context.
- The Brain works asynchronously. Milestones, questions, permissions, and final
results return through the same live conversation.
Managed ASR supplies the browser transcript and the trusted text instruction
passed to the Brain; the Cerebellum itself consumes raw audio directly.
1. Streaming Cerebellum
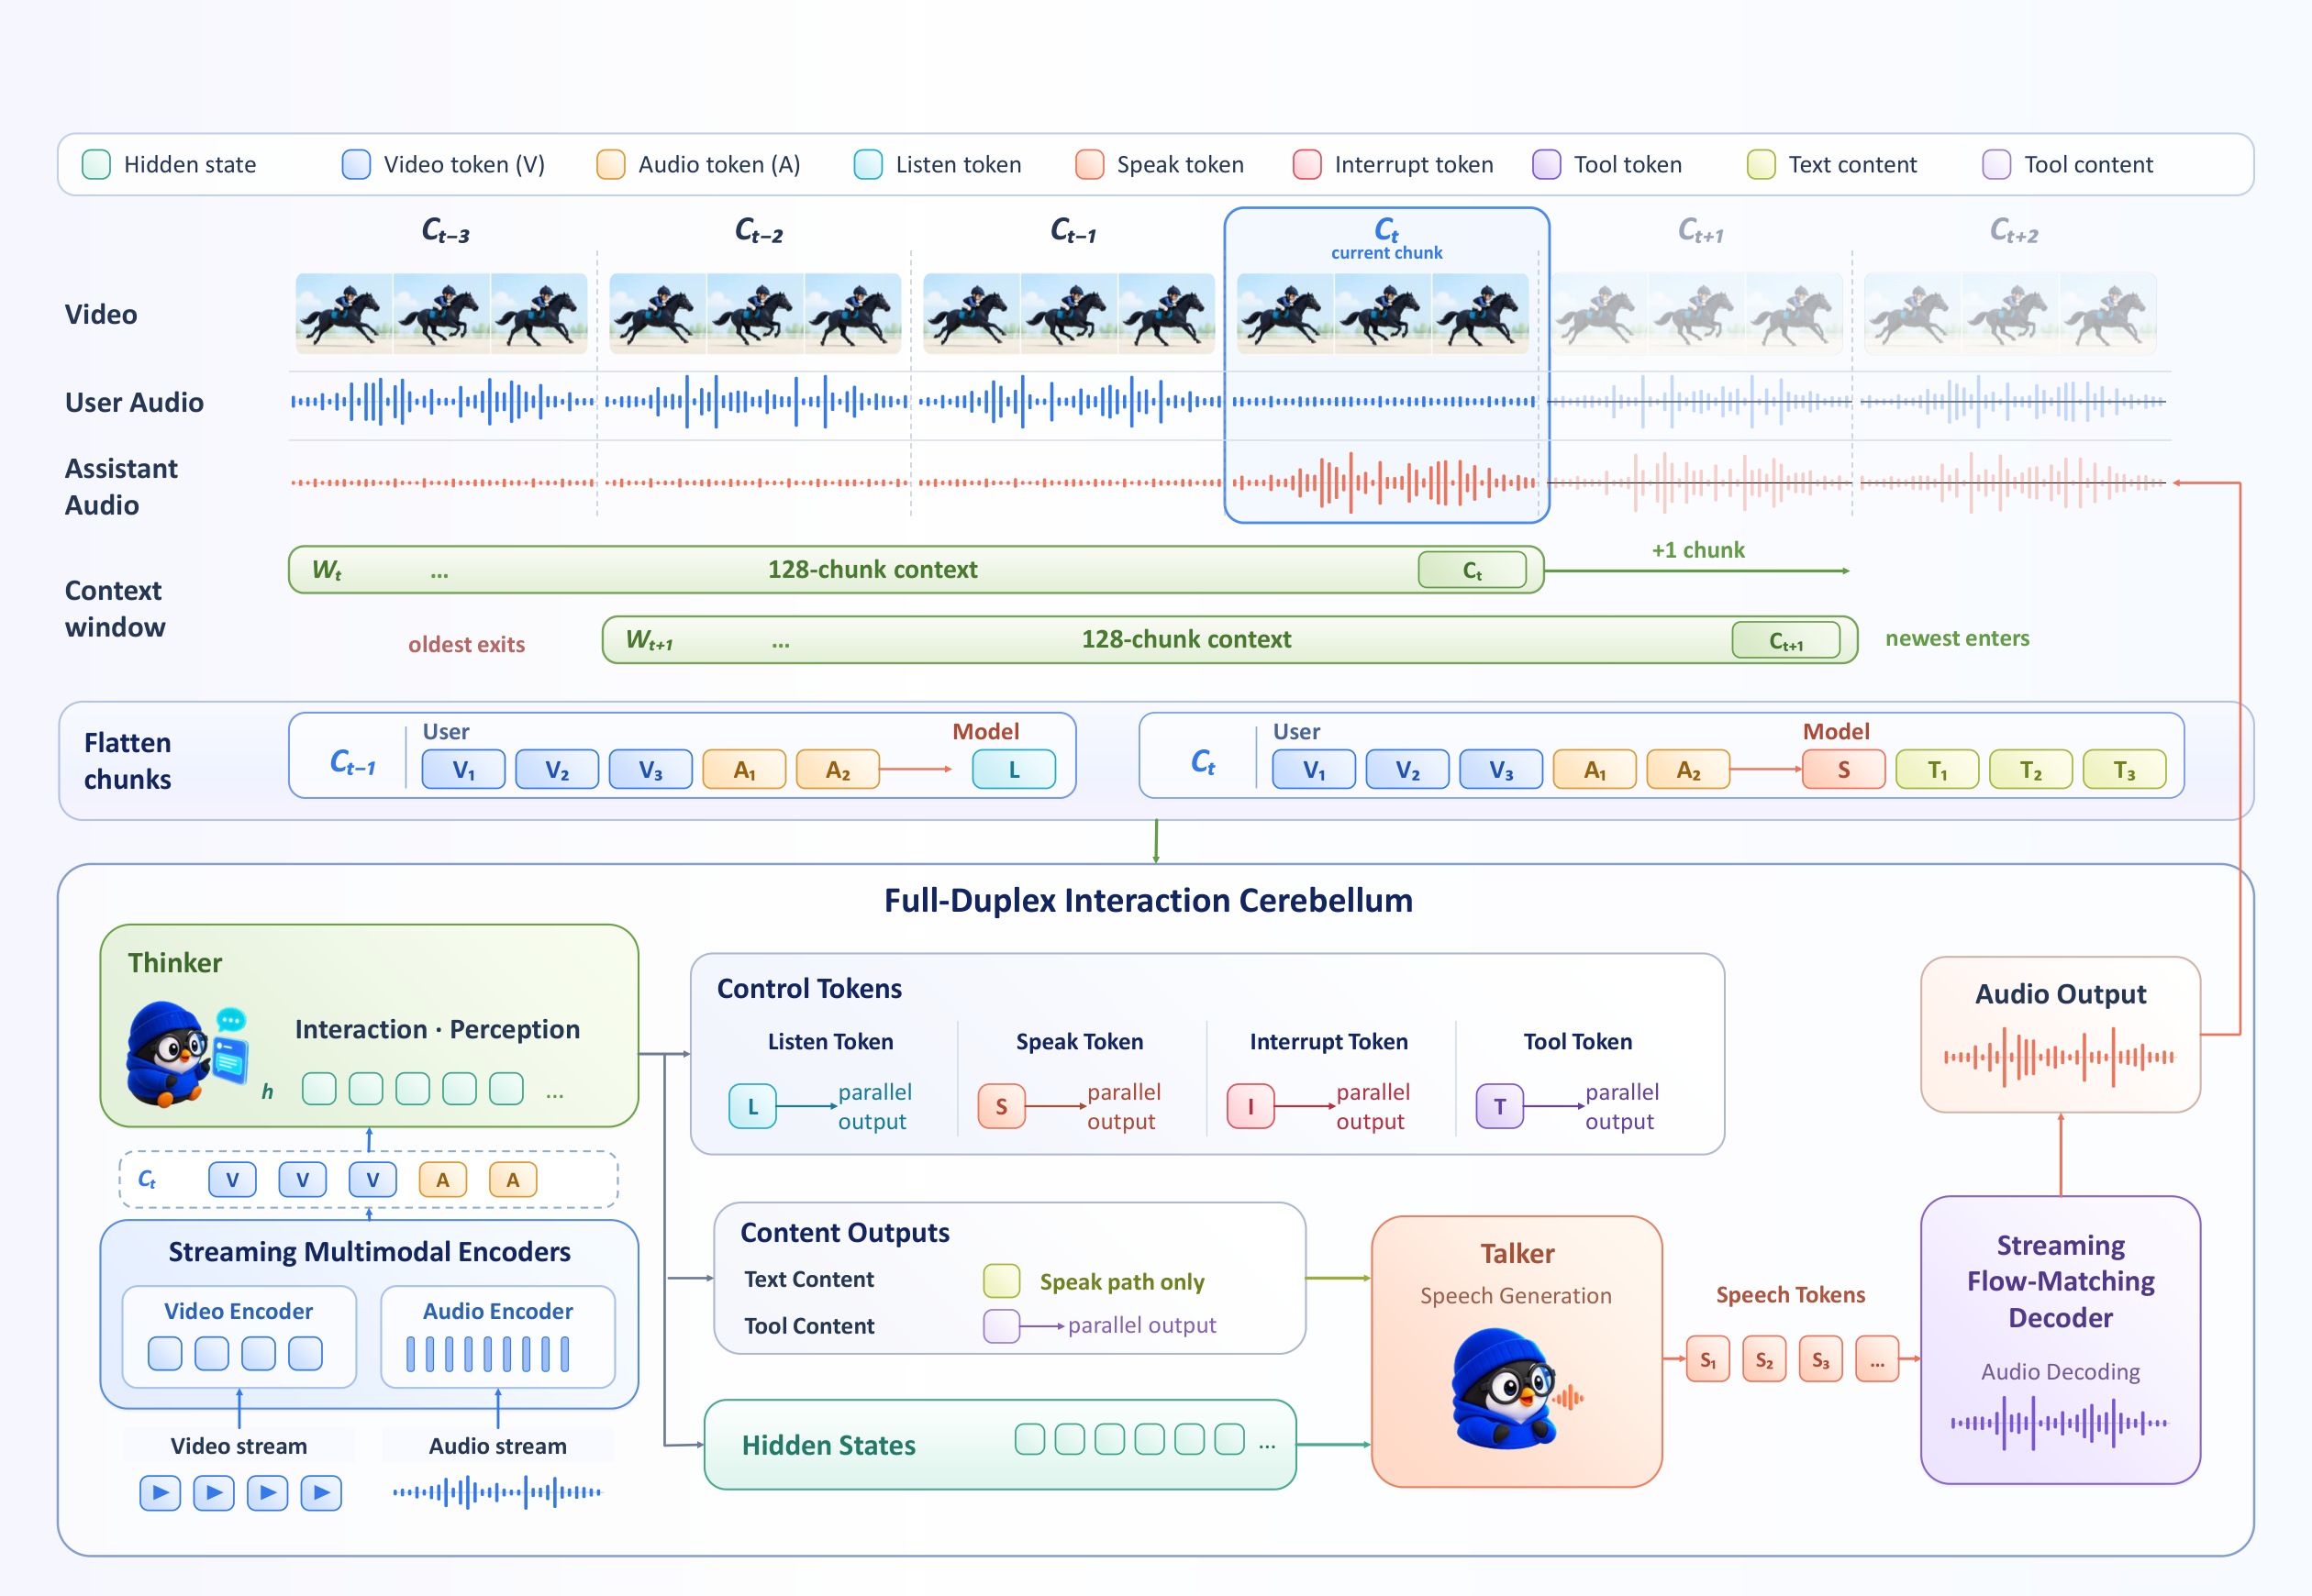
The Thinker controls interaction and content while the detached Talker renders speech without blocking perception.
The Cerebellum starts from MiniCPM-o 4.5 and flattens continuous interaction into
one-second causal units:
[video] [audio] [optional task context] -> [control] [text or tool content]
The control token is predicted before content, separating whether to act from
what to produce.
| Control |
Behavior |
listen |
Stay silent and continue observing the stream. |
speak |
Generate a bounded text segment and send it to the Talker. |
interrupt |
Stop an utterance that is no longer appropriate, including when the user takes the floor. |
tool |
Emit a structured task operation for the runtime. |
On a speak unit, the Talker conditions on Thinker hidden states and aligned text
tokens to predict S3 speech tokens. A causal flow-matching decoder renders audio
incrementally. The released alignment is eight text tokens to 50 S3 tokens per
unit, and detached deployment lets perception continue while speech is generated.
For long sessions, the model retains up to 128 recent units. The runtime supports
context_no_previous, context_slate, and context_memory; the release serving
profile uses context_slate, which preserves active task state without requiring
a memory model.
2. Agent Orchestration Runtime
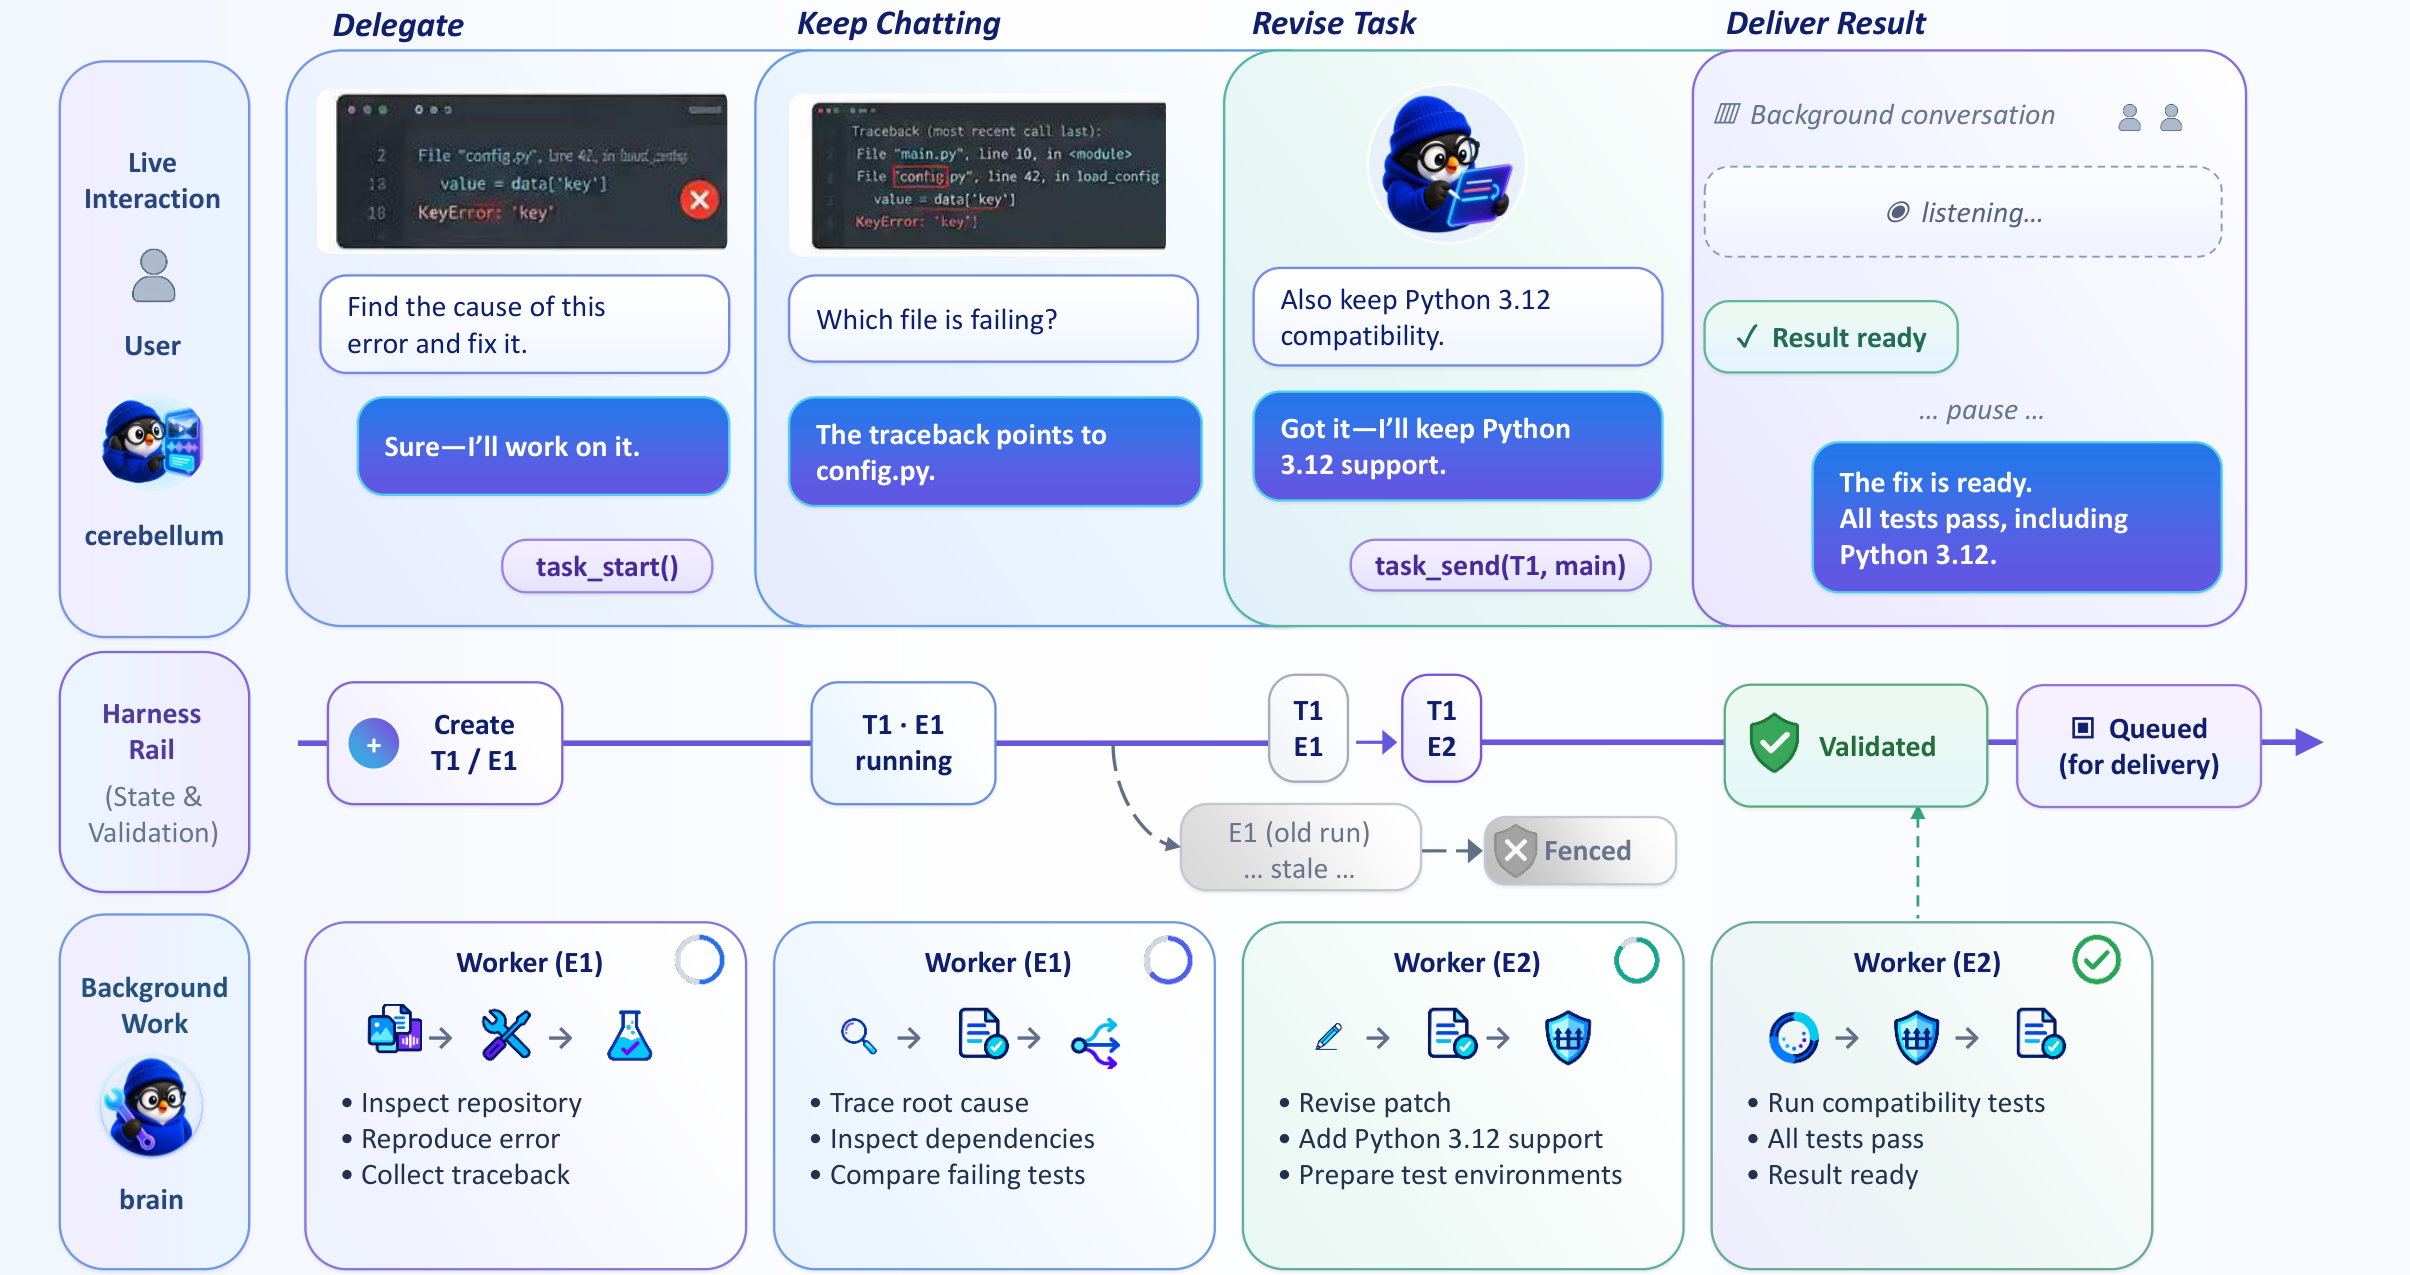
Users can keep talking or revise a task while execution generations prevent stale work from becoming the final answer.
The Cerebellum exposes a small task vocabulary. The runtime turns it into a full
execution lifecycle:
| Operation |
Meaning |
task_start |
Create a background task from the current trusted user turn. |
task_send with main |
Add information or a constraint and steer the primary execution. |
task_send with fork |
Run a read-only side inquiry without modifying the primary task. |
task_resolve |
Cancel a task or answer a permission request. |
Projects, tasks, runs, worker events, and deliveries are tracked separately.
Execution generations fence stale results after a revised objective, while
native event types preserve milestones, multi-question clarification, permission
decisions, stop, reset, and clear as distinct interactions.
3. Pluggable Back Brain
The included Brain provider is Codex. Provider construction is registry-based,
so another agent can be integrated without changing the Cerebellum task protocol
or gateway state machine. With worker.profile: full, the Brain keeps its native
tool surface and receives Gander-specific interfaces:
| Interface |
Purpose |
| Provider tools |
Use the worker's configured file, shell, retrieval, application, and other tools. |
context_fetch |
Retrieve trusted turns, task events, artifacts, and camera or screen frames from the current task lineage. |
memory_search |
Retrieve cross-session evidence when an external memory provider is configured. |
share |
Return a verified milestone, important finding, or correction while work continues. |
| Native questions and approvals |
Ask for missing information or permission and resume the same execution with the user's answer. |
📊 Evaluation
The technical report evaluates conversational ability, full-duplex interaction,
agentic execution, and omni understanding. Human evaluation confirms that
Gander delivers natural, expressive, and highly conversational speech. This
spoken quality is matched by strong instruction-following and knowledge
performance: across 2,052 benchmark utterances, Gander leads the full-duplex
streaming group on both SpokenQA subsets and places second on both VoiceBench
subsets. After adding native full-duplex interaction and agentic capabilities,
it also preserves strong audio-visual understanding, reaching 78.53% accuracy
on Daily-Omni.
| Capability |
Evaluation |
Result |
| Spoken knowledge and QA |
SpokenQA, Llama Questions / Web Questions |
75.60 / 59.30; best in the full-duplex group on both subsets |
| Spoken instruction and dialogue |
VoiceBench, AlpacaEval / SD-QA |
3.96 / 5 and 46.84%; second in the full-duplex group on both subsets |
| Interaction timing |
Full-Duplex-Bench v3 |
100% appropriate turn-taking; 8.0% premature interruption |
| Agentic delivery |
Delegated Full-Duplex-Bench scenarios |
45 / 45 final responses correctly bound |
| Audio-visual understanding |
Daily-Omni |
78.53% accuracy after full-duplex and agentic post-training |
🚀 Quick Start
The following launches the complete browser system: managed ASR, streaming
Thinker, detached Talker, agent runtime, web UI, and a Codex-backed Brain.
Requirements
| Requirement |
Notes |
| System |
Linux, Conda, and an NVIDIA driver compatible with the CUDA 12.4 PyTorch stack. |
| GPUs |
The release profile uses three physical GPUs, one each for Thinker, Talker, and ASR. |
| Models |
MiniCPM-o 4.5, a matching Gander Thinker/Talker pair, and faster-whisper large-v3. |
| Brain |
An authenticated Codex CLI or compatible executable supporting app-server --stdio. |
1. Install the repository
git clone https://github.com/Omni-Interaction-Gander/Omni-Interaction-Agent.git
cd Omni-Interaction-Agent

conda env create -f environment.yml
conda activate gander
2. Install the Brain
Install Codex CLI on the serving
machine, then run it once to complete sign-in:
curl -fsSL https://chatgpt.com/codex/install.sh | sh
codex
After sign-in, verify that codex app-server --help succeeds. Gander starts and
manages the app server itself.
3. Download model weights
mkdir -p checkpoints

hf download openbmb/MiniCPM-o-4_5 \
  --local-dir checkpoints/MiniCPM-o-4_5
hf download Gander-Omni/Gander \
  --local-dir checkpoints/Gander
hf download Systran/faster-whisper-large-v3 \
  --local-dir checkpoints/faster-whisper-large-v3
Existing local copies work as well. Select the matching Thinker and Talker pair
listed on the Gander model page.
cp gander_runtime/configs/serve.example.yaml \
  gander_runtime/configs/serve.local.yaml
mkdir -p workspace
Replace the path placeholders in serve.local.yaml with absolute paths:
| Asset |
Configuration fields |
| MiniCPM-o 4.5 |
model.model_name_or_path, model.processor_name_or_path, model.token2wav_dir, and duplex.ref_audio_path |
| Gander |
duplex.checkpoint and duplex.talker_checkpoint |
| Managed ASR |
asr.model_path |
| Brain |
worker.settings.codex_bin; use codex_home only for a separate authenticated home |
The Brain configuration is compact:
worker:
  provider: codex
  cwd: ../workspace
  profile: full
  settings:
    codex_bin: codex
    model: null
    reasoning_effort: medium
    codex_home: null
cwd is the workspace available to the Brain. codex_bin may be a command on
PATH or an absolute path, and model: null keeps the Codex default model.
The release template already sets 8/50 token alignment, context_slate, full
Brain tools, and the three-GPU mapping: GPU 0 for Thinker, GPU 1 for Talker, and
GPU 2 for ASR.
5. Validate and launch
./scripts/serve.sh --check-config
./scripts/serve.sh
--check-config validates the service without loading model weights. Open
http://127.0.0.1:8000 after launch; /health and /api/asr/health report
runtime and ASR readiness. For remote access, proxy both HTTP and WebSocket
routes through HTTPS so browser media permissions work normally.
🧪 Training
Training uses one entry point and layered YAML configuration. scripts/train.sh
loads minicpm_ft/configs/train.yaml, applies supplied dataset or experiment
YAMLs in order, and applies dotted command-line overrides last.
Data and train-serve alignment
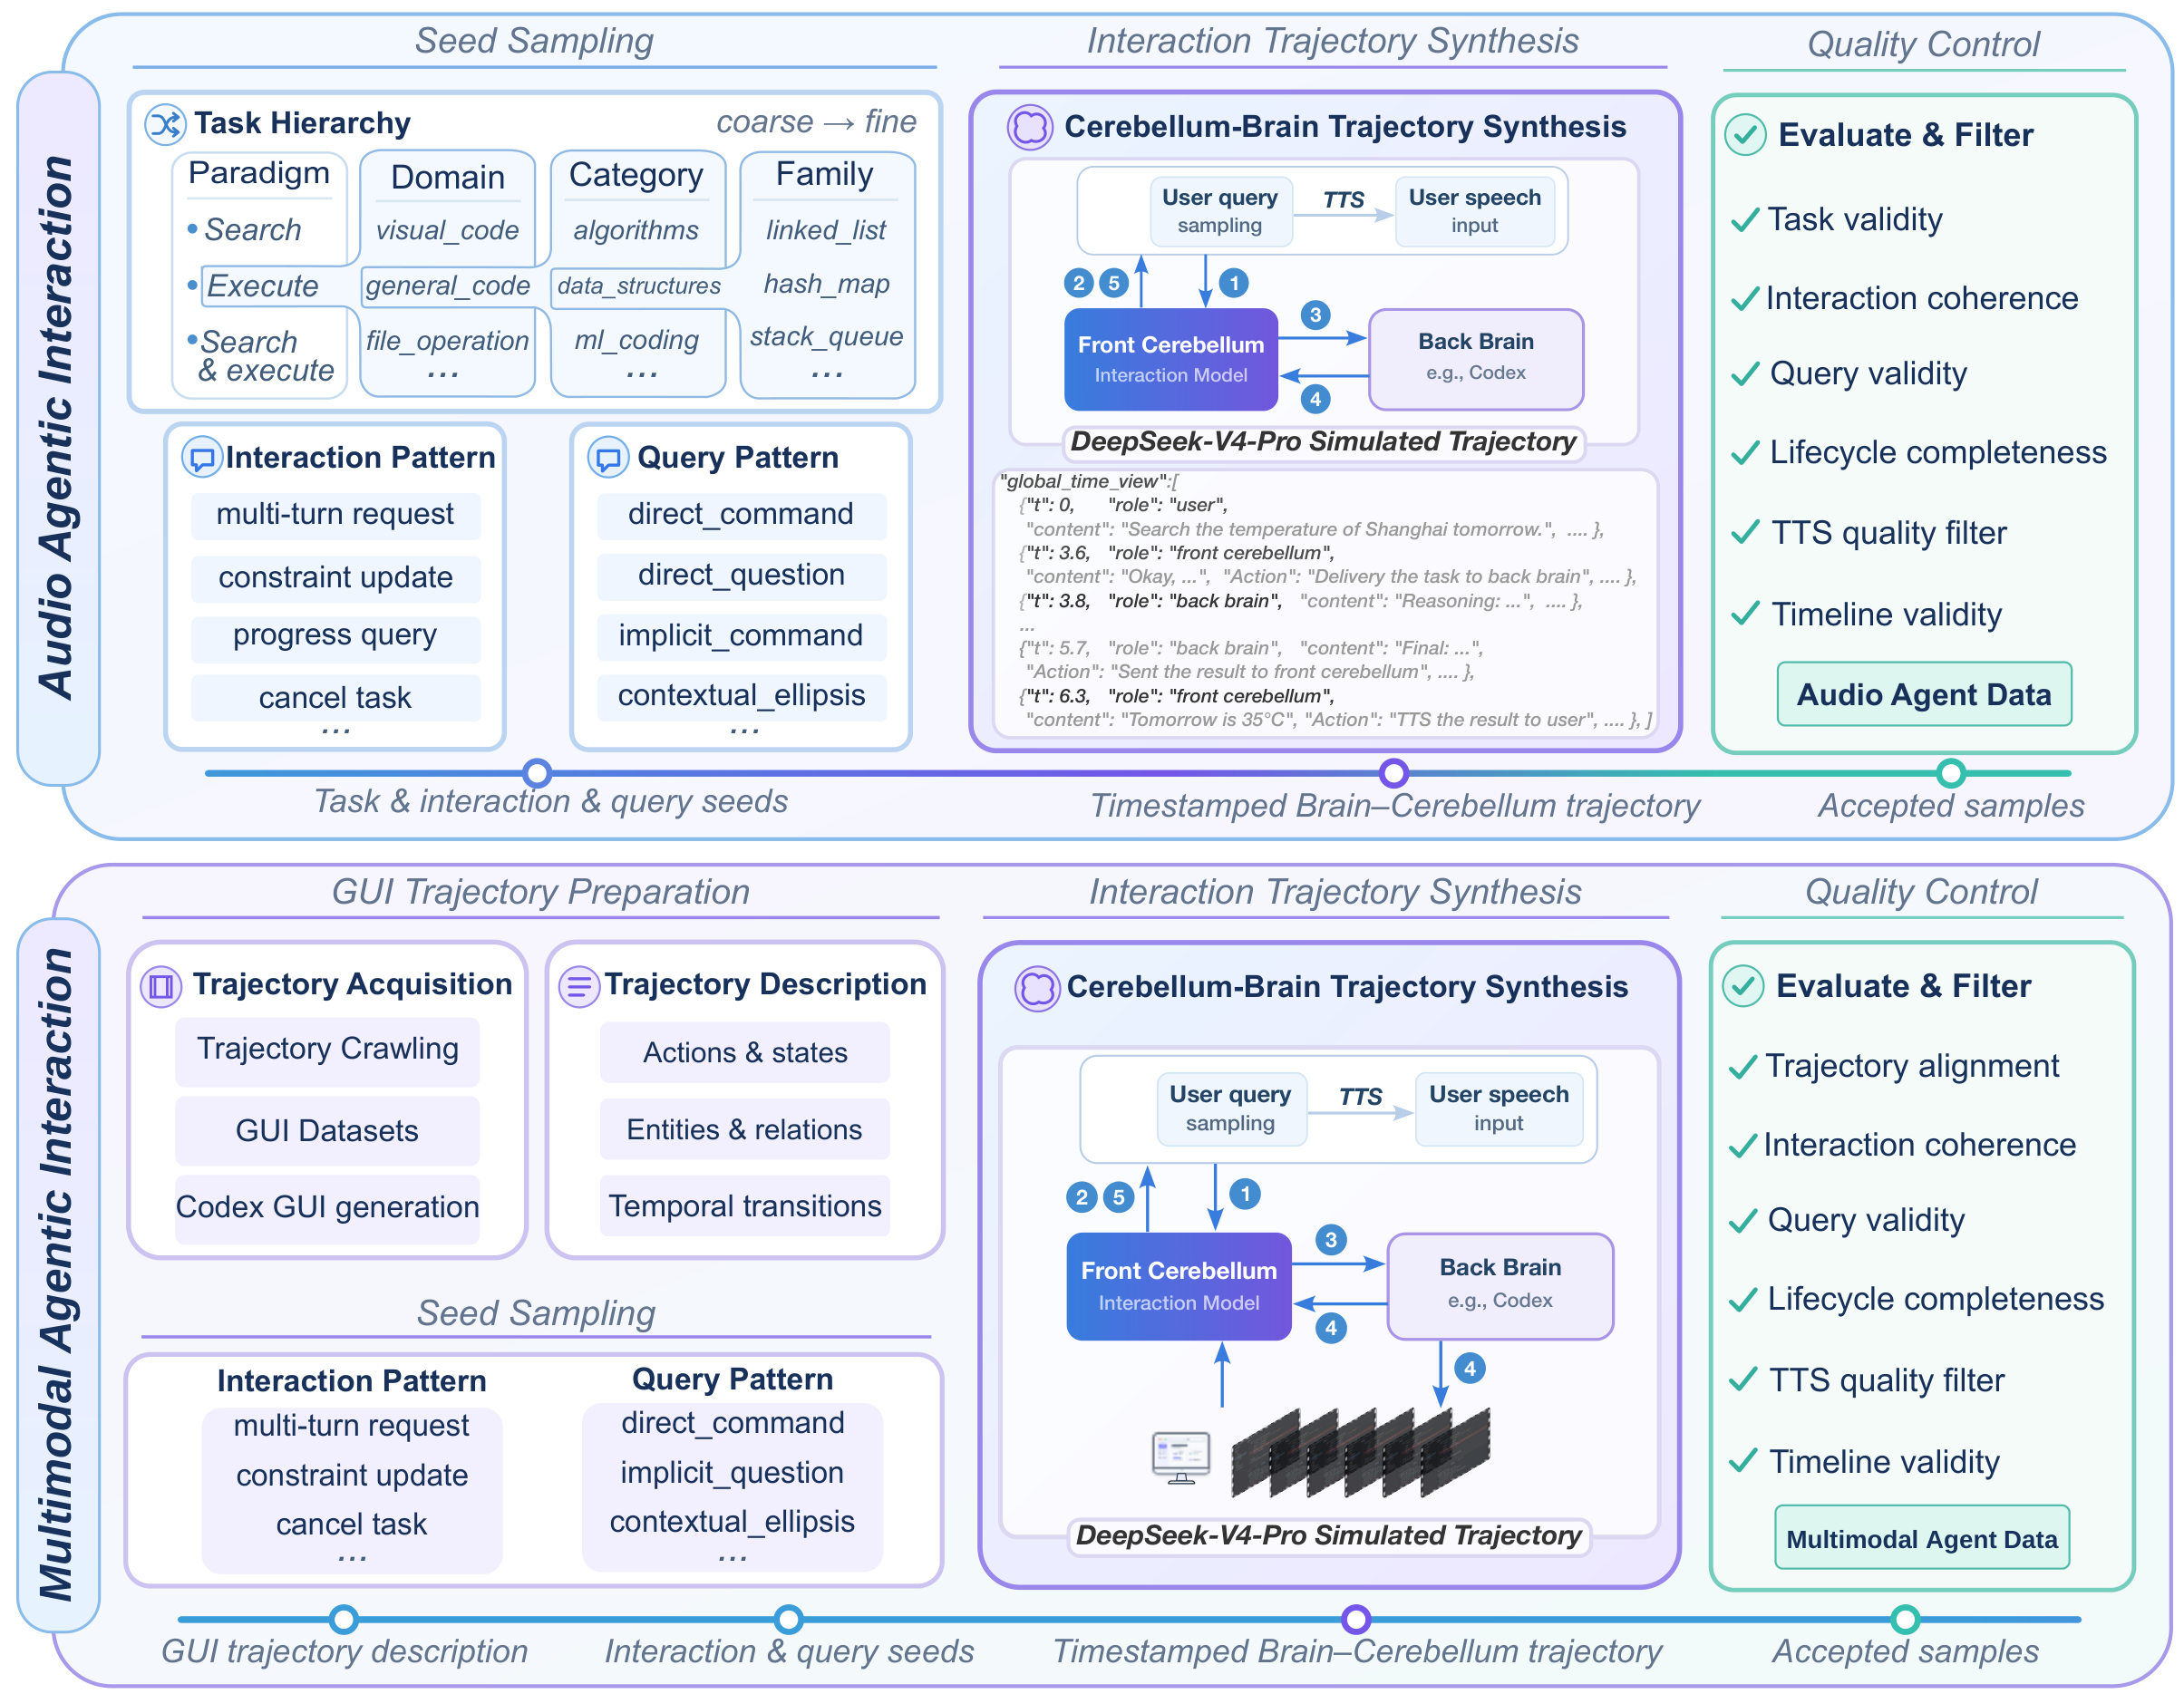
Training examples preserve the causal unit timeline and task lifecycle used by the deployed system.
Gander is trained on a 2.7M-example mixture:
| Data family |
Scale |
Main supervision |
| Speech interaction |
1.01M |
Spoken dialogue and QA, InteractionSpeech, interruption, backchannels, and simultaneous translation. |
| Audio-visual interaction |
1.10M |
Streaming video QA, narration, temporal grounding, and proactive visual responses. |
| Agentic interaction |
359.6K |
Delegation, steering, progress, clarification, permissions, cancellation, GUI trajectories, and tool reasoning. |
| Robustness and negatives |
229.7K |
Irrelevant video, no-command environments, interference, overlapping distractors, and multi-party tracking. |
Training and serving share three core contracts:
- Inputs and outputs use the same one-second causal units, with visual evidence
selected by source time.
- Long-context training retains up to 128 prior units and 1,500 previous-context
tokens; examples beyond the 16,384-token limit are filtered rather than
truncated.
- Acoustic augmentation preserves the interaction timeline while adding noise,
babble, transients, device coloration, room response, echo, or idle periods.
The released recipe uses two stages:
| Stage |
Trainable modules |
Objective |
| Thinker |
LLM and audio projection |
Text, interaction-control, and structured tool-call tokens. |
| Talker |
TTS projection and decoder; Thinker frozen |
Time-aligned S3 speech tokens conditioned on Thinker hidden states. |
A joint mode remains available for experiments; the released checkpoint recipe
and composition follow the two-stage path above.
Validate the bundled examples
The repository includes 12 Thinker and 6 Talker examples with local media for a
small end-to-end data-path check:
./scripts/prepare_data.sh check \
  minicpm_ft/examples/release/thinker/train_config.yaml
./scripts/prepare_data.sh check \
  minicpm_ft/examples/release/talker/train_config.yaml
Train the Thinker
BASE=/absolute/path/to/MiniCPM-o-4_5

./scripts/train.sh minicpm_ft/examples/release/thinker/train_config.yaml \
  --model.model_name_or_path "$BASE" \
  --model.processor_name_or_path "$BASE" \
  --launch.gpus_per_node 1 \
  --train.output_dir outputs/thinker
Thinker mode trains the LLM and audio projection while keeping the vision tower,
resampler, and TTS modules frozen. The default objective combines text loss with
an interaction-control loss weighted by 1.5.
Train the Talker
BASE=/absolute/path/to/MiniCPM-o-4_5
THINKER=/absolute/path/to/thinker-checkpoint

./scripts/train.sh minicpm_ft/examples/release/talker/train_config.yaml \
  --model.model_name_or_path "$BASE" \
  --model.processor_name_or_path "$BASE" \
  --runtime.init_checkpoint "$THINKER" \
  --launch.gpus_per_node 1 \
  --train.output_dir outputs/talker
Talker mode freezes the completed Thinker's LLM and audio projection, and trains
only the TTS projection and decoder. Bundled examples contain S3 targets. For a
dataset without inline turn.meta.s3_codes, set data.s3_cache_dir in its
training YAML and build the cache first:
./scripts/prepare_data.sh s3 /path/to/release/train_config.yaml --device cuda:0
Both stages default to save_trainable_only: true. At deployment, the Thinker is
composed on top of MiniCPM-o 4.5, then the Talker is composed on top of that
Thinker. Neither checkpoint duplicates frozen base-model parameters.
Use a full dataset release
Create an overlay YAML with data.release_root, ordered manifest lists, and row
counts or sampling weights. Relative media paths resolve below the release root.
Enable audio_augment and provide the noise/RIR indices when using acoustic
augmentation.
Multi-node execution uses launch.hosts or launch.hostfile. Inspect the fully
merged recipe before a large run:
./scripts/train.sh /path/to/release/train_config.yaml --show-config
🔍 Offline Inference
One entry point covers two distinct paths:
| Mode |
Input and behavior |
turn |
A bounded text, audio, image, or combined input followed by one generated response. |
duplex |
Audio consumed in online one-second units, producing per-unit control decisions, incremental text, tool traces, and optional speech. |
Start from the release profile. Set model.model_name_or_path,
model.processor_name_or_path, inference.checkpoint, and the fields below
inference.input, then run it:
cp minicpm_ft/configs/infer.yaml /tmp/gander-infer.yaml
./scripts/infer.sh /tmp/gander-infer.yaml
For turn-based inference, keep inference.mode: turn and set any supported
combination of input.text, input.audio, and input.image.
For chunk-wise duplex inference, use the released streaming values:
inference:
  mode: duplex
  checkpoint: /path/to/gander-thinker-checkpoint
  input:
    text: null
    audio: /path/to/input.wav
    image: null
  duplex:
    chunk_ms: 1000
    speak_text_tokens_per_unit: 8
    talker_speech_tokens_per_unit: 50
    sliding_window_mode: context_slate
    context_previous_max_tokens: 1500
To generate speech, also configure the Talker and reference audio:
model:
  init_tts: true
  token2wav_dir: /path/to/MiniCPM-o-4_5/assets/token2wav

inference:
  talker_checkpoint: /path/to/gander-talker-checkpoint
  generate_audio: true
  output_audio: /path/to/output.wav
  input:
    audio: /path/to/input.wav
    ref_audio: /path/to/reference.wav
Turn mode measures a bounded multimodal response. Duplex mode exercises the same
incremental control and context behavior used by the realtime Cerebellum.
⚙️ Configuration Reference
The main deployment choices live in the serving YAML:
| Setting |
Options |
server.mode |
lean uses the shortest trusted task path; coordinator adds a planning and supervision layer. |
duplex.media_mode |
voice starts with audio, omni requires visual input, and auto permits client selection. |
duplex.allow_client_video |
Independently enables camera and screen attachment. |
| `duplex.sliding_window_mode |
|

 Gander 是一个开源的端到端全模态交互智能体,把自然的全双工语音对话、持续的视听感知和长程智能体任务执行融合在一个系统里。