What is this?
 Benjamin-Plus is a token-efficiency skill for coding agents: it teaches five habits around looking things up and waiting (not what the agent builds), measured to cut cost by up to 18% with quality unchanged.
Is this a plugin I install, or text I inject into the agent's prompt?It is not a package you install — it is a short rules file (RULESET.md, about 745 tokens) that you inject directly into the agent's system prompt or hook; packaging it as a discoverable skill folder saved nothing in testing because agents burned steps just finding SKILL.md.
It is not a package you install — it is a short rules file (RULESET.md, about 745 tokens) that you inject directly into the agent's system prompt or hook; packaging it as a discoverable skill folder saved nothing in testing because agents burned steps just finding SKILL.md.How do I add it to my agent?For Claude Code, append the ruleset to CLAUDE.md (for example with 'cat ~/.benjamin-plus/injected-instruction.md >> CLAUDE.md') or wire it via a hook in ~/.claude/settings.json; for Codex CLI append it to AGENTS.md since that file loads every session; for any other agent, append injected-instruction.md to its system prompt.
For Claude Code, append the ruleset to CLAUDE.md (for example with 'cat ~/.benjamin-plus/injected-instruction.md >> CLAUDE.md') or wire it via a hook in ~/.claude/settings.json; for Codex CLI append it to AGENTS.md since that file loads every session; for any other agent, append injected-instruction.md to its system prompt.Which coding agents can use it?It was benchmarked on Claude Code 2.1.201 (Sonnet 5) and Codex CLI (gpt-5.6-luna), but it works with any coding agent whose system prompt or context you can edit — no API keys or extra tooling required.
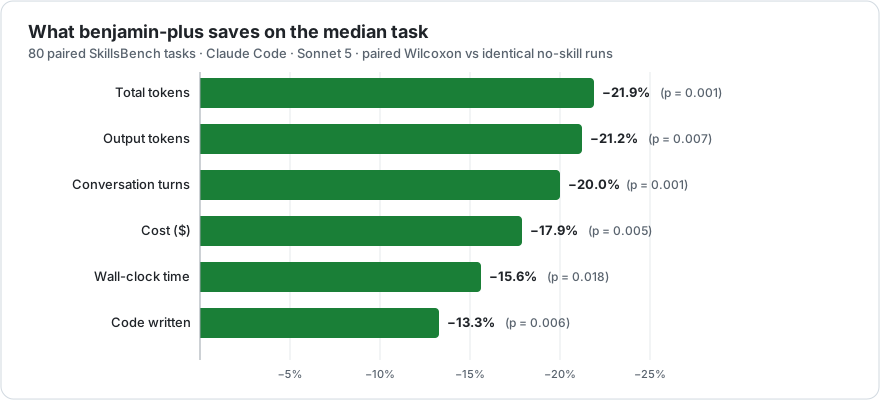
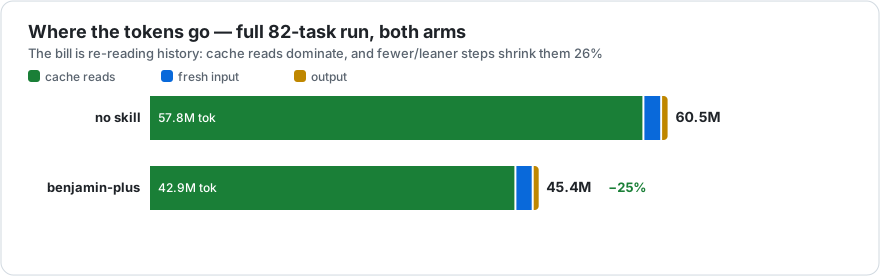
It was benchmarked on Claude Code 2.1.201 (Sonnet 5) and Codex CLI (gpt-5.6-luna), but it works with any coding agent whose system prompt or context you can edit — no API keys or extra tooling required.Does it always save the same amount of cost?Savings scale with how bloated your baseline sessions already are, roughly −10% to −18% cost; an identical run against a leaner-running baseline a day earlier only measured −10%, and the quality comparison (7 better/5 worse/68 ties) wasn't statistically powered to rule out small effects either way.
Savings scale with how bloated your baseline sessions already are, roughly −10% to −18% cost; an identical run against a leaner-running baseline a day earlier only measured −10%, and the quality comparison (7 better/5 worse/68 ties) wasn't statistically powered to rule out small effects either way.What are the five habits the skill teaches?Gather facts in one combined recon pass instead of many small lookups, read only the needed lines of a file (keyhole reads), probe every dependency in one go, treat the task's own verification command as the definition of done, and count polling as a step by checking every 30 seconds instead of every second.
Gather facts in one combined recon pass instead of many small lookups, read only the needed lines of a file (keyhole reads), probe every dependency in one go, treat the task's own verification command as the definition of done, and count polling as a step by checking every 30 seconds instead of every second.How was Benjamin-Plus developed and tested?An agent mined about 1,200 old agent traces in a loop, drafted rules, and ran paired A/B tests on 80 SkillsBench tasks (Claude Code 2.1.201, Sonnet 5) across six revisions, keeping only the rules that survived the evidence.
An agent mined about 1,200 old agent traces in a loop, drafted rules, and ran paired A/B tests on 80 SkillsBench tasks (Claude Code 2.1.201, Sonnet 5) across six revisions, keeping only the rules that survived the evidence.Does it only work on Claude Code?No — it was also measured on Codex CLI with gpt-5.6-luna on a Java SWE-bench set (675 paired replicas), showing −4.4% cost with an unchanged solve rate, so it generalizes across harnesses.
No — it was also measured on Codex CLI with gpt-5.6-luna on a Java SWE-bench set (675 paired replicas), showing −4.4% cost with an unchanged solve rate, so it generalizes across harnesses.How big is the injected payload?The whole integration is about 3 KB of text, with the core ruleset itself only around 745 tokens once injected into the system prompt.
The whole integration is about 3 KB of text, with the core ruleset itself only around 745 tokens once injected into the system prompt.What are similar projects?SkillOpt, Intent-Router, ralph, pstack, headroom, HERO-Anti-OverDefense, SwiftUI-Agent-Skill, SwiftUI-Agent-Skill
SkillOpt, Intent-Router, ralph, pstack, headroom, HERO-Anti-OverDefense, SwiftUI-Agent-Skill, SwiftUI-Agent-SkillWhich topics is it in?optimization, prompt-engineering, shell, benchmark, coding-agent, claude, agent-skills, performance, codex, research, agent, claude-code
optimization, prompt-engineering, shell, benchmark, coding-agent, claude, agent-skills, performance, codex, research, agent, claude-code