





Что это такое?
 CleanRL — это набор качественных реализаций алгоритмов глубокого обучения с подкреплением (PPO, DQN, C51, SAC, DDPG, TD3, PPG и другие) в виде отдельных файлов. Код написан так, чтобы его читали и изменяли, а не подключали как библиотеку.
Это библиотека, которую можно установить и импортировать в свой проект?Нет — авторы прямо говорят, что это не модульная библиотека и она не предназначена для импорта. Каждая вариация алгоритма живёт в одном самодостаточном Python-файле, а дублирование кода — сознательная цена за читаемость.
Нет — авторы прямо говорят, что это не модульная библиотека и она не предназначена для импорта. Каждая вариация алгоритма живёт в одном самодостаточном Python-файле, а дублирование кода — сознательная цена за читаемость.Как запустить эксперимент?Установите Python (>=3.7.1,<3.11) и uv 0.7.9+, затем запустите один из обучающих скриптов, например ppo.py. Без uv можно установить зависимости из requirements.txt или открыть готовую среду разработки в Gitpod.
Установите Python (>=3.7.1,<3.11) и uv 0.7.9+, затем запустите один из обучающих скриптов, например ppo.py. Без uv можно установить зависимости из requirements.txt или открыть готовую среду разработки в Gitpod.Как обстоят дела с поддержкой Gymnasium?Проект переходит на Gymnasium — поддерживаемого преемника openai/gym. Ход работы отслеживается в issue #277, так что поддержка сред пока в процессе перехода.
Проект переходит на Gymnasium — поддерживаемого преемника openai/gym. Ход работы отслеживается в issue #277, так что поддержка сред пока в процессе перехода.Кому стоит выбрать CleanRL вместо обычной RL-библиотеки?Тем, кто хочет понимать каждую деталь реализации конкретной вариации алгоритма или прототипировать продвинутые функции, которых нет в модульных DRL-библиотеках. Минимум кода упрощает отладку без глубокой вложенности классов.
Тем, кто хочет понимать каждую деталь реализации конкретной вариации алгоритма или прототипировать продвинутые функции, которых нет в модульных DRL-библиотеках. Минимум кода упрощает отладку без глубокой вложенности классов.Какие алгоритмы и их вариации реализованы?PPO (примерно с дюжиной вариаций: Atari, непрерывные действия, LSTM, несколько GPU, Isaac Gym, Procgen и другие), DQN, C51, SAC, DDPG, TD3, PPG, RND и Qdagger — всего около 30 вариантов скриптов.
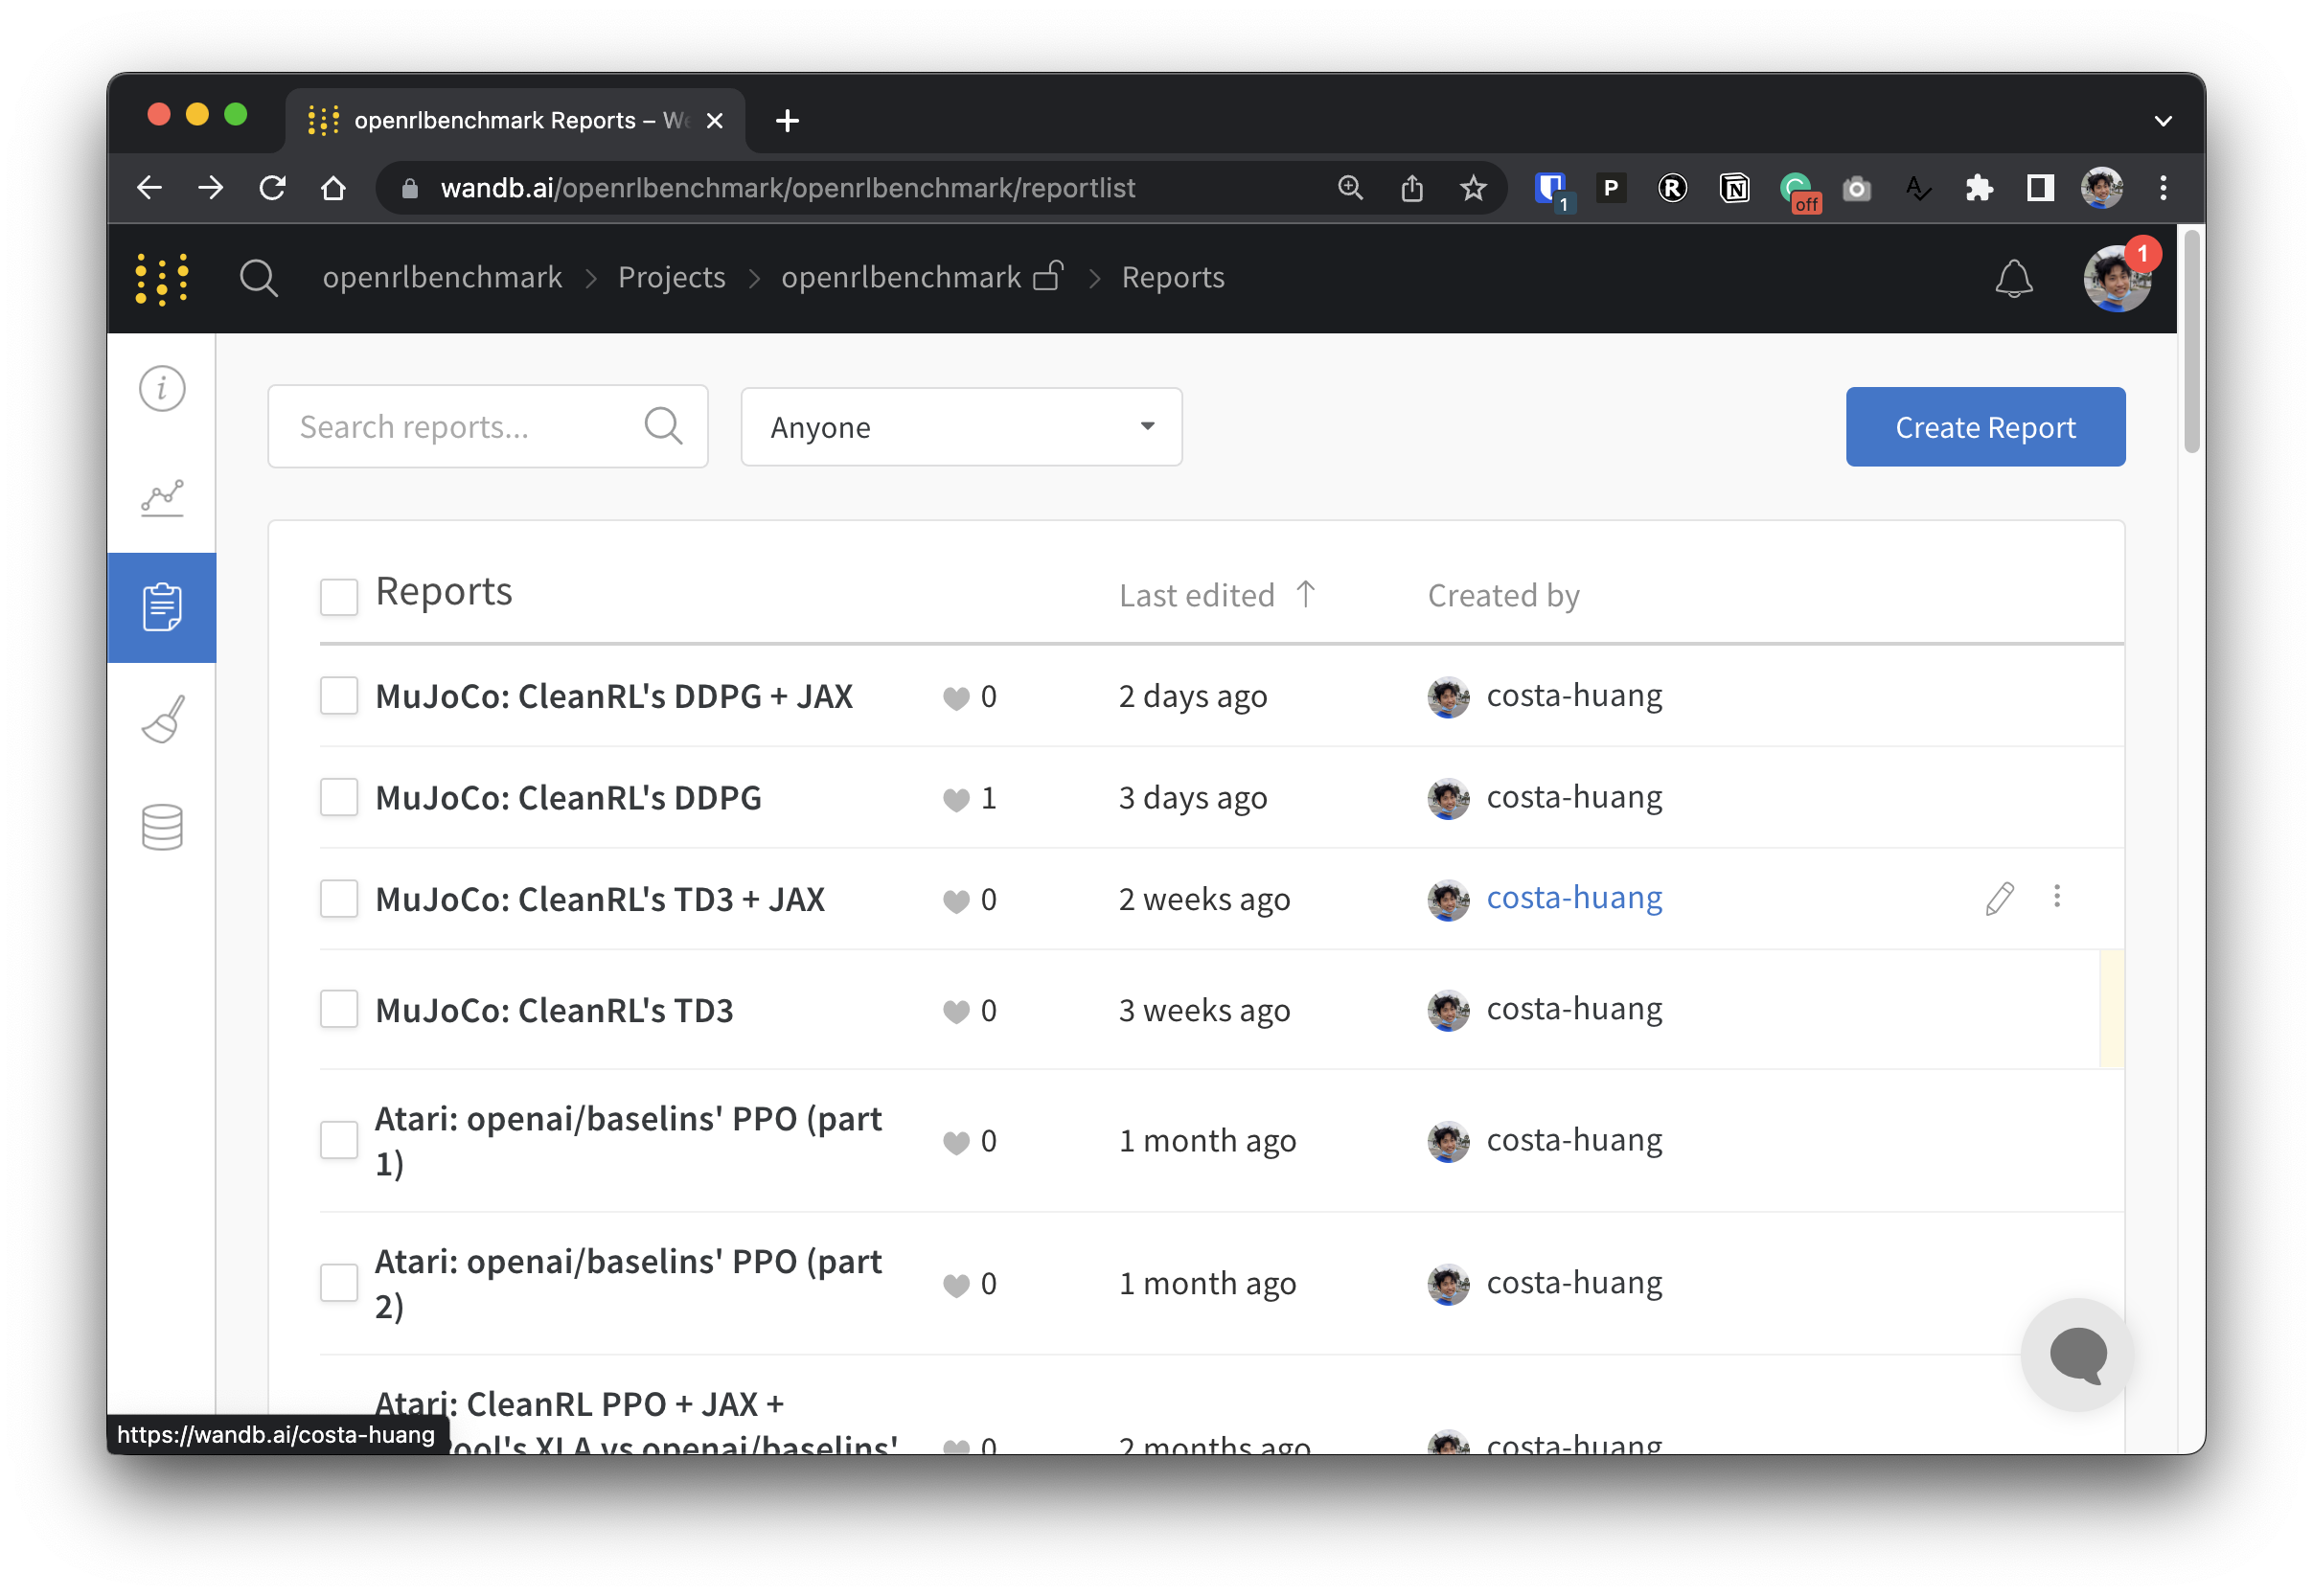
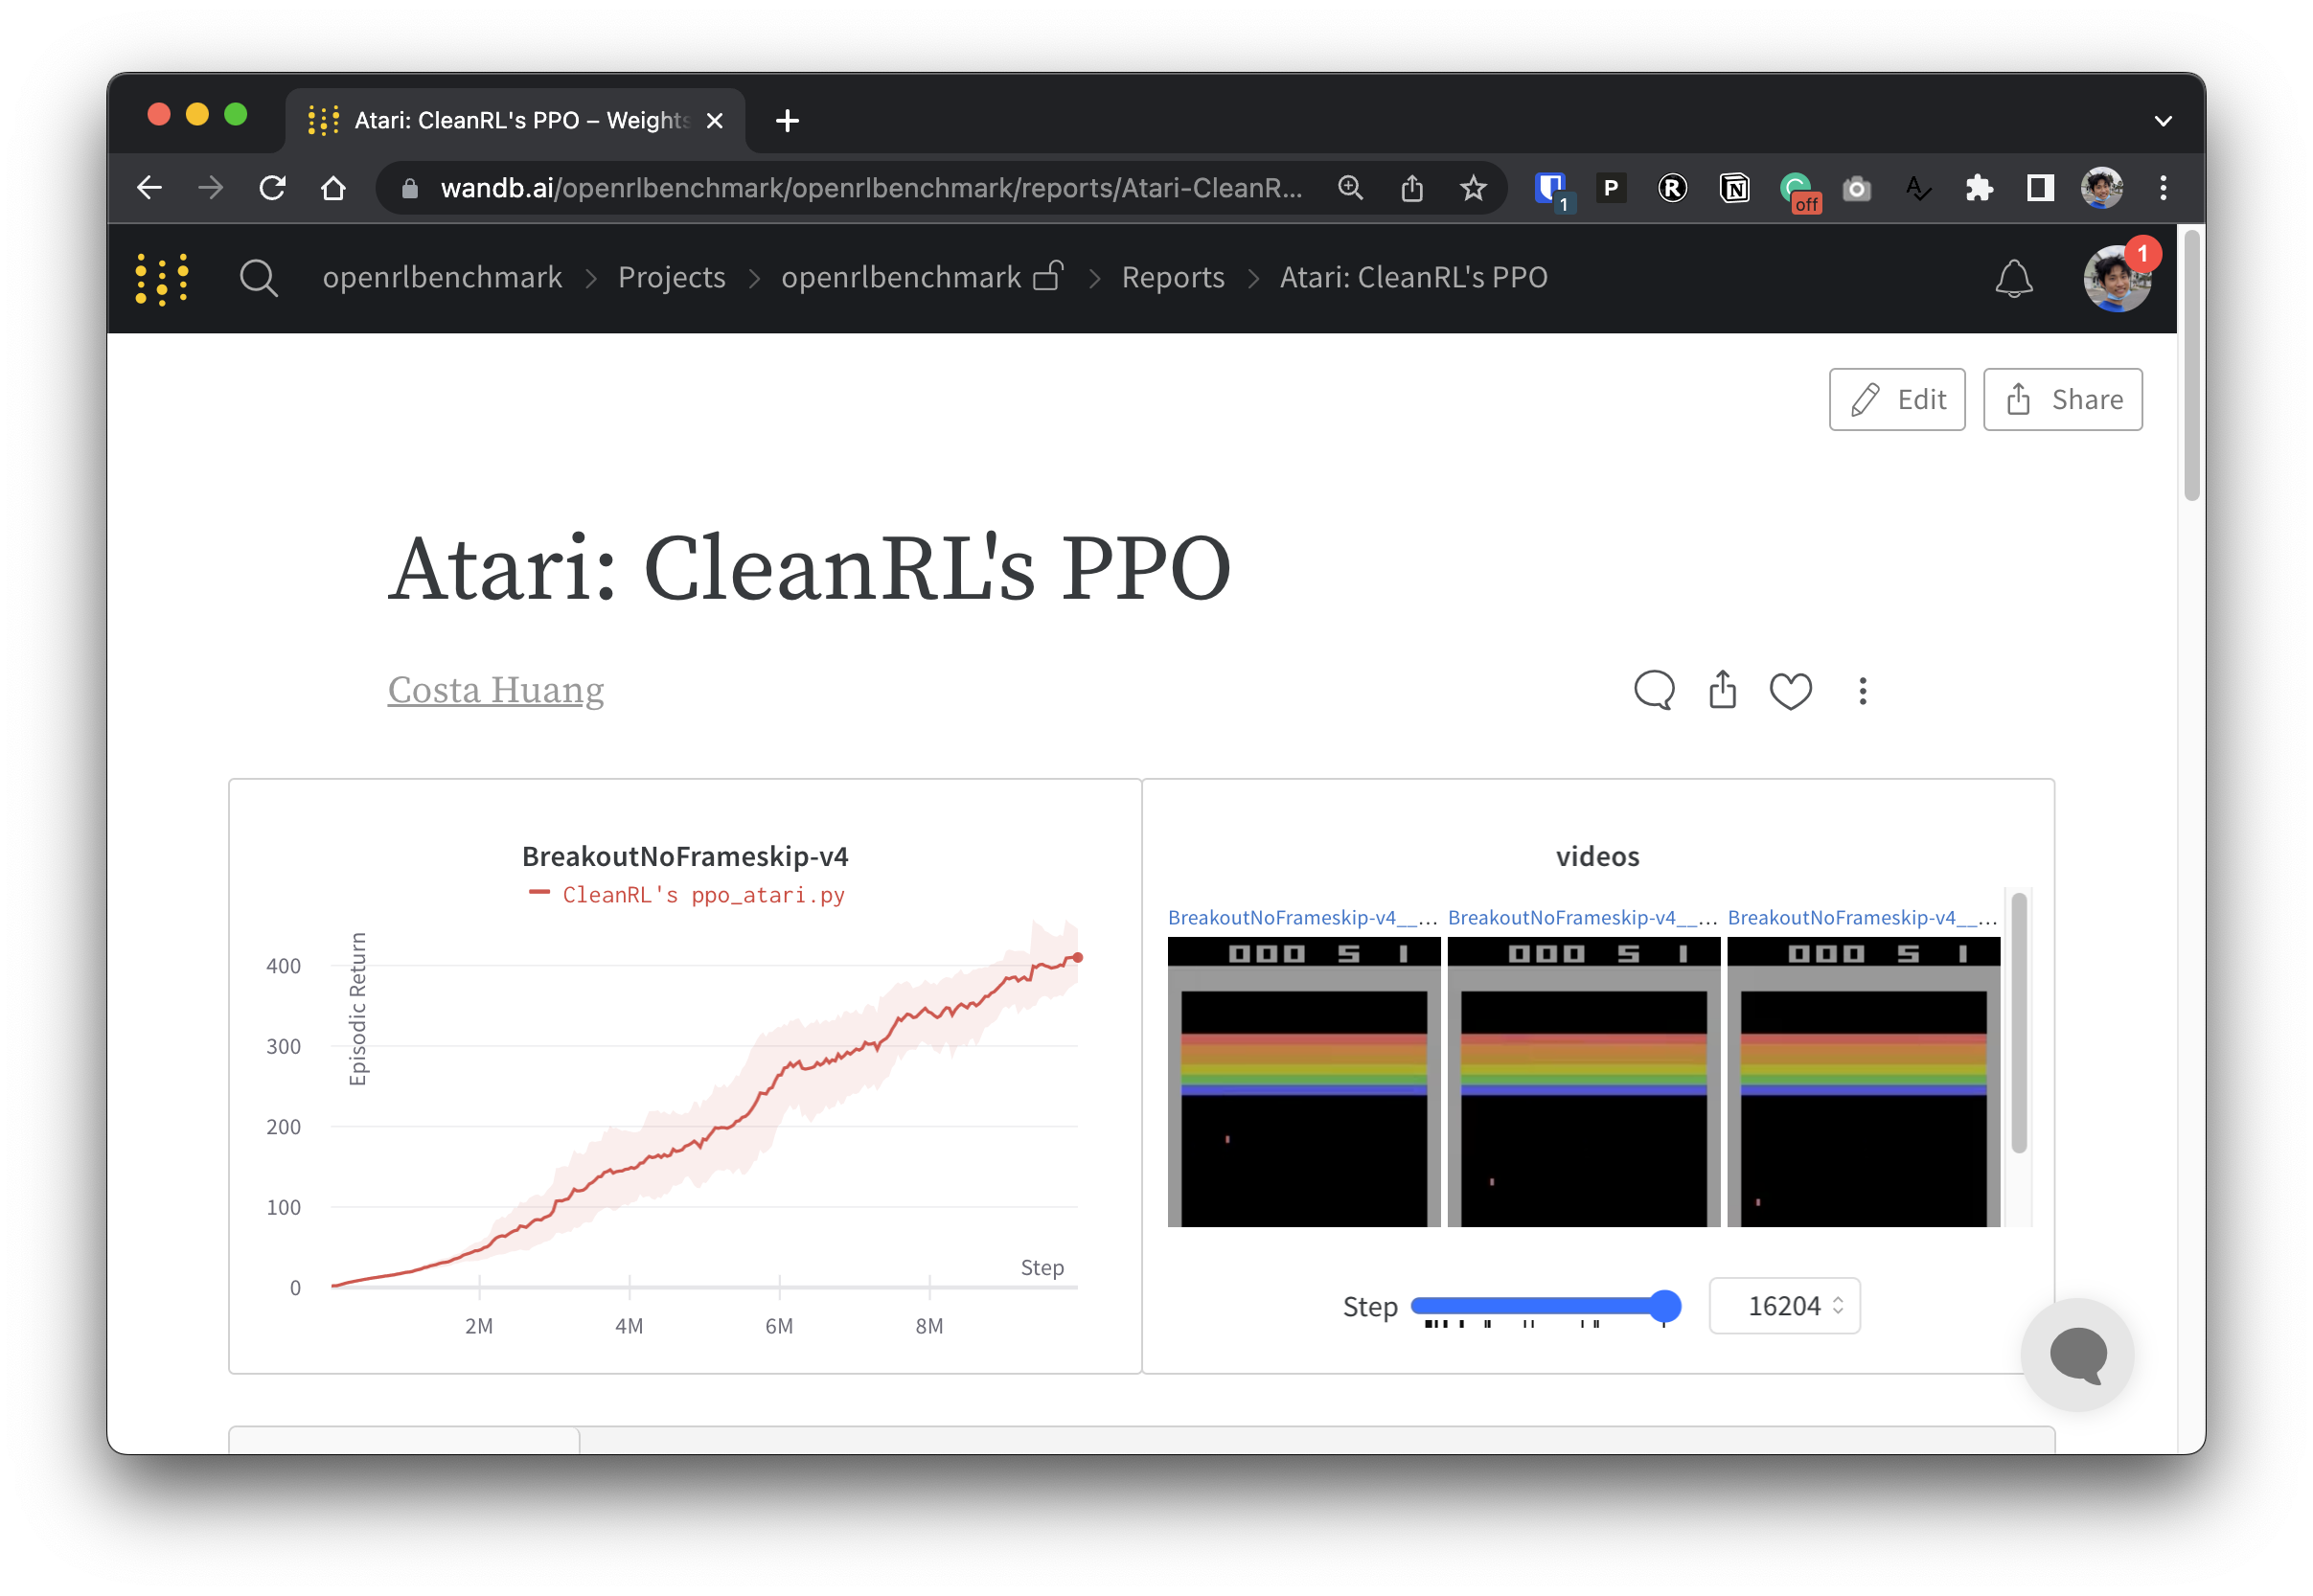
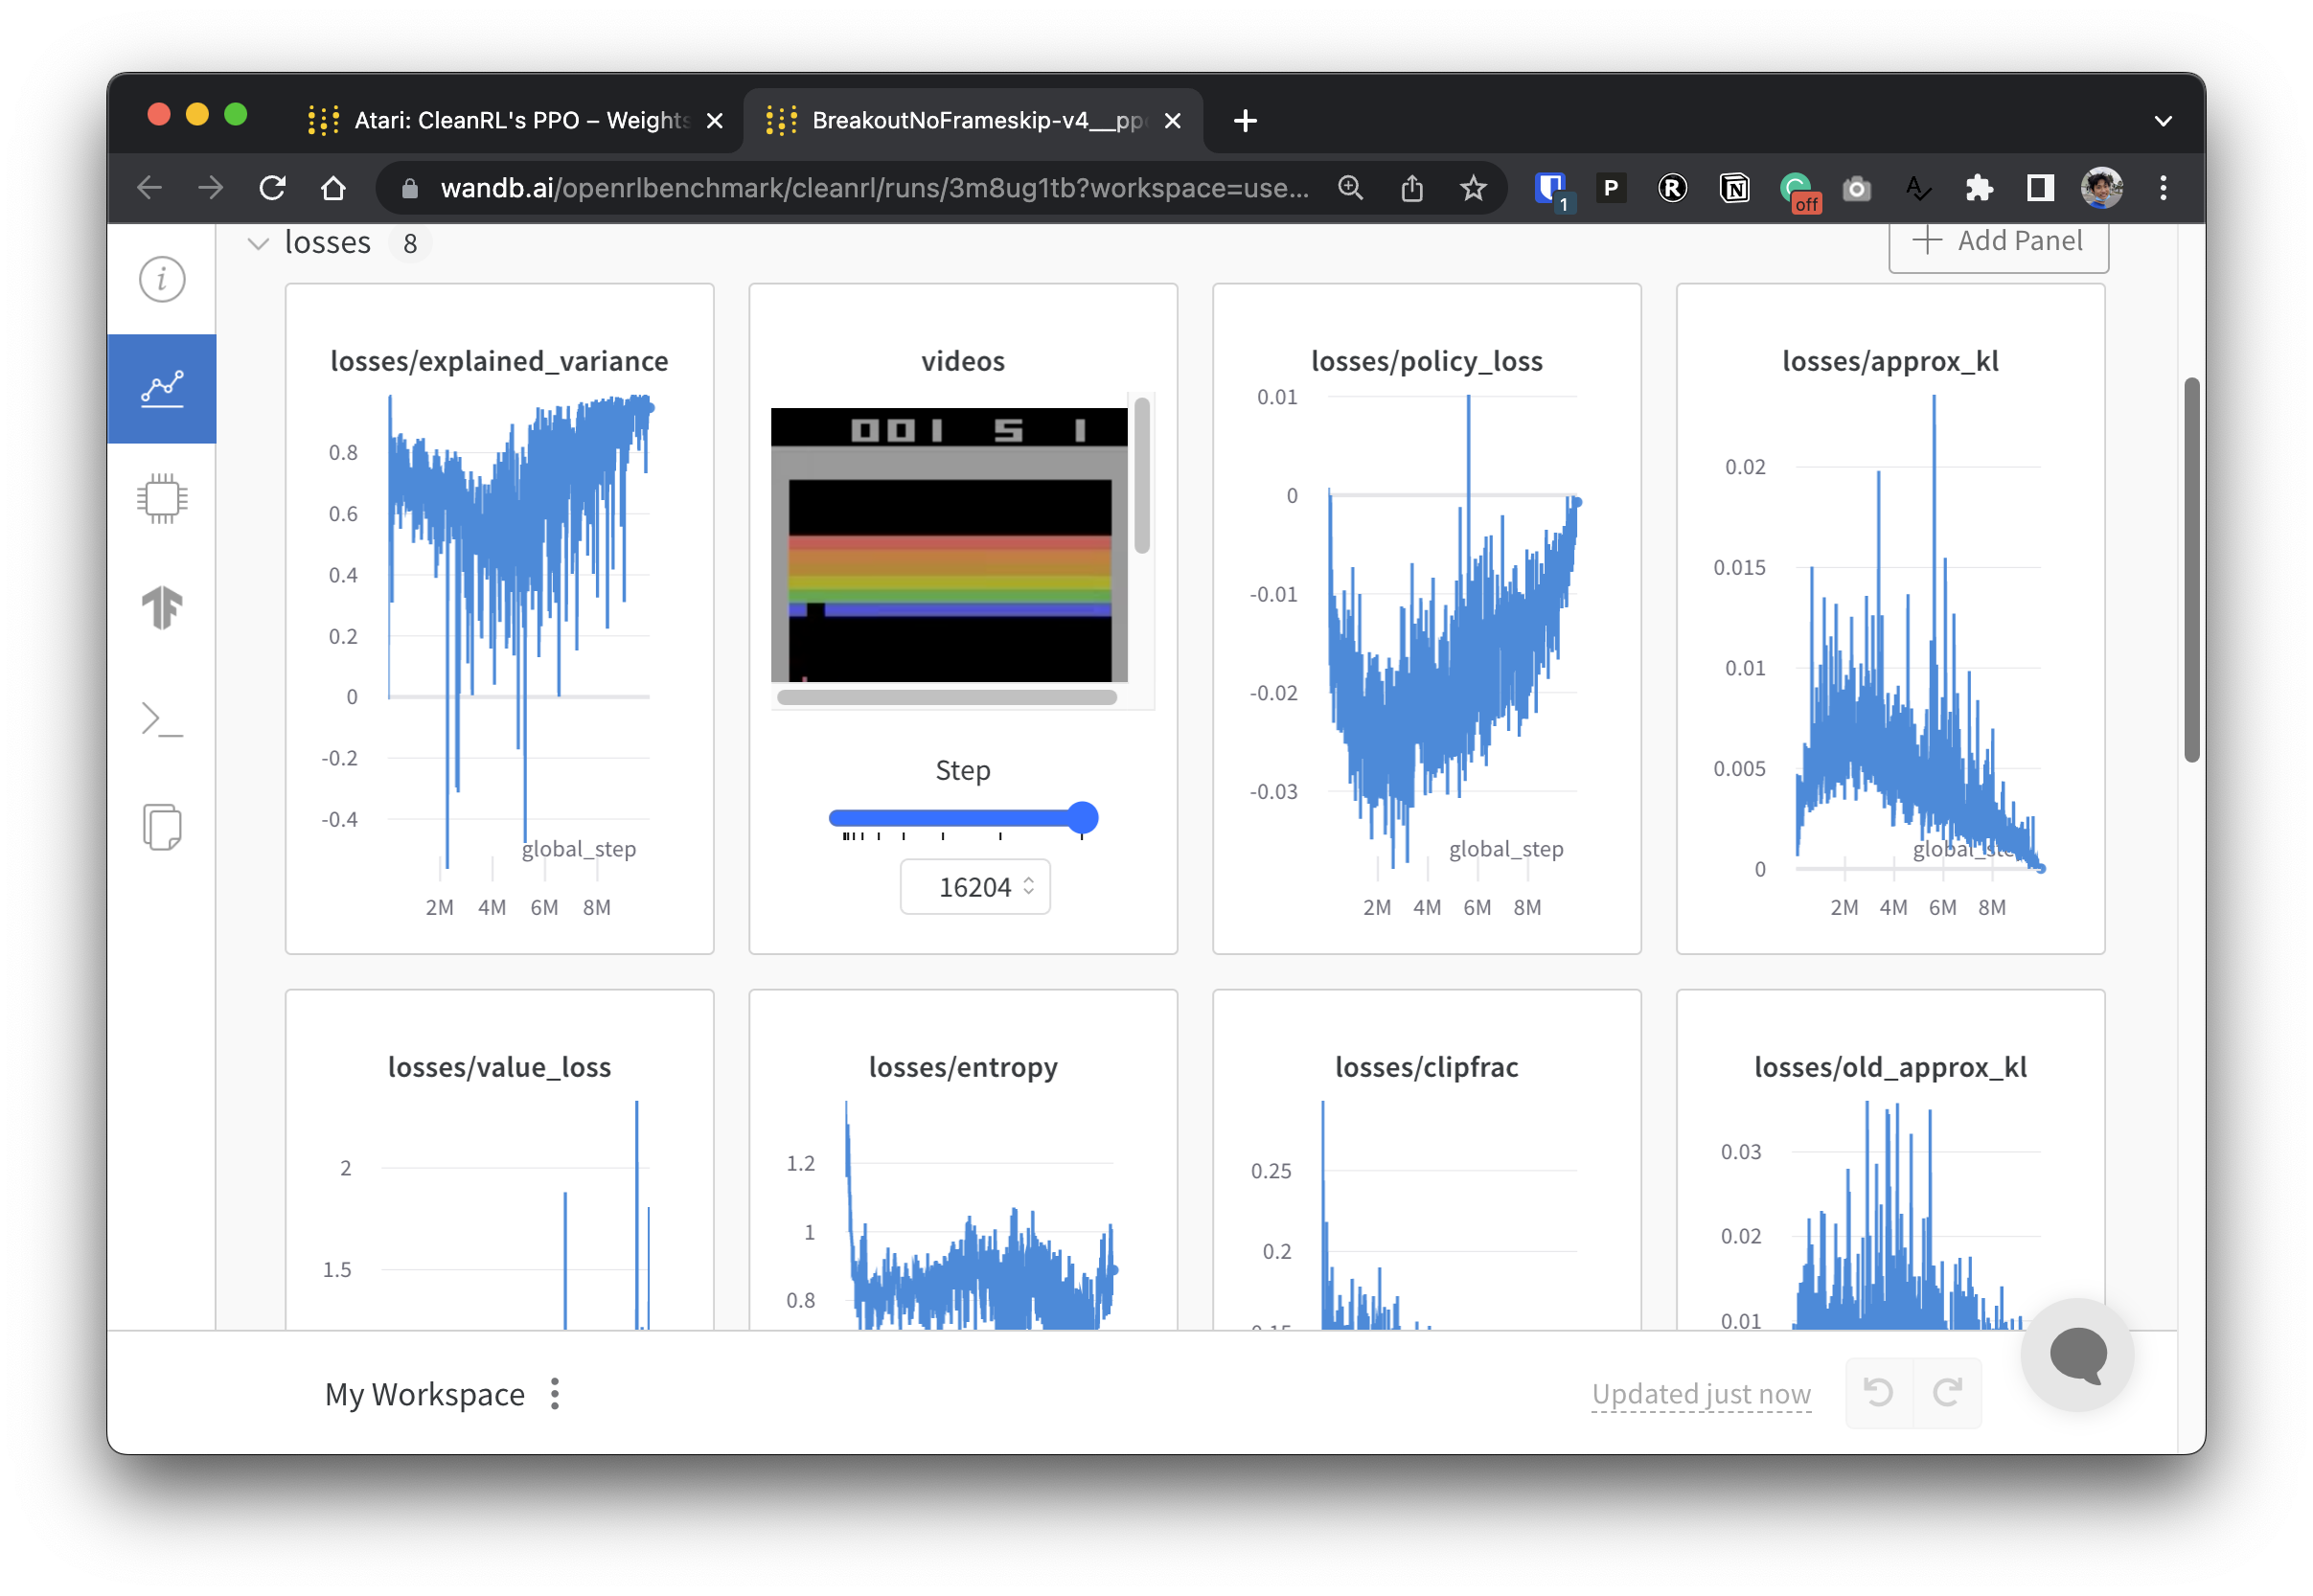
PPO (примерно с дюжиной вариаций: Atari, непрерывные действия, LSTM, несколько GPU, Isaac Gym, Procgen и другие), DQN, C51, SAC, DDPG, TD3, PPG, RND и Qdagger — всего около 30 вариантов скриптов.Как отслеживать и сравнивать свои запуски обучения?Обучение интегрируется с Weights & Biases для учёта экспериментов, а через связанный проект Open RL Benchmark можно смотреть интерактивные отчёты, где CleanRL сравнивается со Stable-Baselines3, openai/baselines и jaxrl — вплоть до загрузки GPU и видео игрового процесса.
Обучение интегрируется с Weights & Biases для учёта экспериментов, а через связанный проект Open RL Benchmark можно смотреть интерактивные отчёты, где CleanRL сравнивается со Stable-Baselines3, openai/baselines и jaxrl — вплоть до загрузки GPU и видео игрового процесса.Есть ли какие-то алгоритмы в версиях на JAX?Да — в таблице алгоритмов рядом с версиями на PyTorch указаны порты на JAX, например dqnjax.py, c51atarijax.py, ddpgcontinuousactionjax.py и td3continuousactionjax.py, плюс несколько вариантов PPO и Qdagger на основе JAX.
Да — в таблице алгоритмов рядом с версиями на PyTorch указаны порты на JAX, например dqnjax.py, c51atarijax.py, ddpgcontinuousactionjax.py и td3continuousactionjax.py, плюс несколько вариантов PPO и Qdagger на основе JAX.Есть ли статья, которую нужно процитировать, если я использую это в исследовании?Да — в README просят сослаться на техническую статью по CleanRL, когда вы используете его в своей работе.
Да — в README просят сослаться на техническую статью по CleanRL, когда вы используете его в своей работе.What are similar projects?tianshou, reinforcement-learning, dopamine, Gymnasium, easy-rl, train-llm-from-scratch, verl, GR00T-WholeBodyControl
tianshou, reinforcement-learning, dopamine, Gymnasium, easy-rl, train-llm-from-scratch, verl, GR00T-WholeBodyControlWhich topics is it in?gym, wandb, ppo, deep-reinforcement-learning, jax, training, reinforcement-learning, pytorch, benchmark, deep-learning, research, gpu
gym, wandb, ppo, deep-reinforcement-learning, jax, training, reinforcement-learning, pytorch, benchmark, deep-learning, research, gpu