AgentMeasure
Find repeated failures and retries in your Codex sessions, with local evidence.
Healthcheck reads existing Codex Desktop rollout logs and produces a terminal
summary and a local HTML report. It checks duplicate records, retry chains, and
consecutive tool failures. Missing evidence is UNPROVABLE, never silently zero.
# Requires Python 3.9+, Git, and pipx. Installation uses the network.
pipx install "git+https://github.com/roy-tong/AgentMeasure#subdirectory=healthcheck"
agentmeasure demo   # synthetic example; no personal logs needed
agentmeasure check  # your local Codex sessions, last 7 days
Analysis runs locally with no runtime network calls. Engineering preview:
Codex CLI is not yet independently verified; Claude Code is not supported yet.
The Git install above is available now; PyPI publishing is being prepared.
Quick start and supported formats ·
Try it and share feedback safely ·
What our contributions changed · The Token-Accounting Bug Report — ~110 tools audited, 45+ verified bugs, 10 merged fixes · Maintain a usage tool? Audit it in 10 minutes ·
中文
Found a useful result? Keep a snapshot and compare your next run. Feedback is
optional: you can use the tool without opening an issue or uploading logs.
Measurement infrastructure
The open yardstick for agent usage and AI outcomes.
Test whether your agent metrics mean what their labels claim.
Conformance checks for AI-agent telemetry — a retry is one logical operation, not two requests; a reasoning-token subset must not be added into totals; a cache hit is not a new measurement. Every check reports PASS / FAIL / UNPROVABLE, and UNPROVABLE is a first-class result: when the evidence to decide is absent, it is disclosed, never zeroed.
# .github/workflows/conformance.yml — turn measurement assumptions into CI checks
- uses: roy-tong/AgentMeasure@2cf476d6f7d0fc45401db5a822e1f12de009ac74
  with:
    fixture: fixtures/telemetry.jsonl   # your FMT-002 event fixture
Run conformance locally · See real failures · Read the spec · 中文


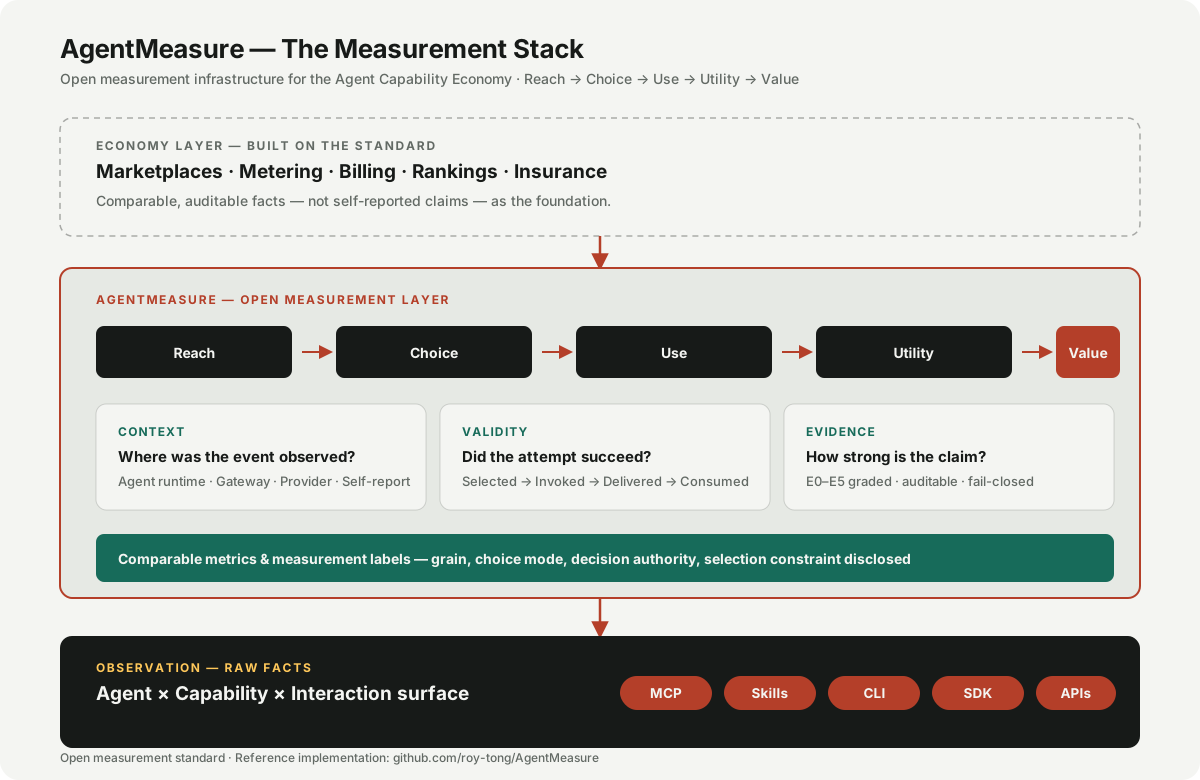
AgentMeasure separates execution facts from logical operations, evidence
from inference, and economic settlement from value — an open measurement
layer for the Agent Capability Economy. One number for your dashboards
(logical operations), the evidence for what each number counts, and explicit
disclosure for what it cannot prove.
Today: measure agent-facing capability usage — attempts, operations, retry
inflation, success rates with numerators you can audit.
Next: make capabilities comparable and meterable — including the outcome units
now being billed (what counts as one resolution, one completed task).
Long term: provide the measurement foundation for Capability as a Service (CaaS).
Reach → Choice → Use → Utility → Value
AgentMeasure is not a payment protocol, marketplace, or universal ranking system.
It standardizes the facts and measurement semantics those systems can build on.
Why now
AI services have started charging by the outcome: Zendesk at $1.50–2.00 per automated resolution since Aug 2024, Intercom Fin at $0.99 per resolution with a money-back guarantee, Sierra's outcome-based enterprise contracts. But what counts as one outcome has no standard — retries, reopens, and silent "assumed resolutions" all change the number, and the bill. When money rides on a measured unit, someone has to define the unit. That is what we build. → Read the note
Principles (written down before anyone asked)
- Free, forever. Spec, engine, SDK, conformance, local dashboard — the free list is part of governance, not revocable later. Adoption is the product.
- Local-first, opt-in. Raw data never leaves your machine by default; only aggregated, anonymized evidence returns, and only if you opt in.
- The referee doesn't open a store. No paid rankings, no recommendation slots, no custody of funds. Neutrality is the product.
Website · Send a trace → get a measurement check · Free 7-day audit — apply · 30 Projects / 30 Days campaign · Whitepaper · Core Specification
Start with the story: When the Software Consumer Becomes an Agent (EN) · 当软件的消费者变成 Agent (ZH)
Try it in 2 minutes
./examples/demo-e2e.sh
Mock MCP server → canonical observations → local metrics, all on your machine, no
cloud. The demo is reproducible: it runs in an isolated workspace (never touches
~/.agentmeasure) — same fixture + same policy = same result (42 calls → 84
canonical observations, caller claims claude:14 · codex:14 · unknown:14).
Then read why we audit the ecosystem's usage claims:
Benchmark Run #001 — six real claims profiled with
the Evidence Profile (multi-axis, no composite scores), and
Pipeline Validation #001 — our own fixture,
kept out of the ranking as a reference baseline.
Run a preregistered experiment — AgentMeasure Lab
python3 lab/am lab selftest                                   # planted uplift recovered + honest null
python3 lab/am lab init                                       # workspace + example experiment
python3 lab/am lab preregister am-lab/experiments/example-manifest.json
python3 lab/am lab run am-lab/experiments/example-manifest.prereg.json
The open experiment engine (lab/): task set × harness matrix × factor
variants → Reach → Choice → Success → Consumption funnel → effect sizes with
confidence intervals, guardrails, honest nulls, and an offline HTML report that opens
with a bilingual decision-maker one-pager. Preregistration is enforced (hypothesis /
primary metric / guardrails / analysis plan hashed before the run — with a scale /
power / budget preview), seeds replay deterministically, and a budget circuit breaker
stops safely with the data it has. Selection uplift that loses consumption is
rejected at the decision exit (unverified_growth — do not ship), and candidates
that make no more money at higher cost are flagged as dominated.
The shipped demo runs on a synthetic harness (planted ground truth at realistic,
literature-scale amplitudes, disclosed in every report) — it validates the engine,
not real-agent claims. Real harness adapters (Claude Code / Codex) are runner plugins
against the same interface; that is the highest-value contribution right now.
Docs: lab/README.md · formats:
lab/schemas/ (experiment manifest / funnel events / report).
Why the split matters, in one line
1 user intent
2 provider attempts
1 final success
That is 1 operation, 2 attempts, operation success 100%, attempt success 50%,
attempts per operation 2.
It is not "2 operations with 50% success".
Attempts are execution facts. Operations are logical intents. Mixing the two is how agent
reliability reports get distorted.
External provider trials
Start smaller than a trial: send a trace, get a measurement check — 20–100 anonymized trace/log rows (or a public export), mapped locally, with a short report of what safely counts as attempts vs operations, where retries may inflate usage, and what the telemetry cannot prove. No SDK, no integration; raw data stays local unless you explicitly authorize sharing a sanitized sample. A sample check is not a full audit and claims no causal effect.
If the check pays for itself, AgentMeasure is looking for 3 MCP/API providers for short external measurement runs.
The goal is not to prove the model works. It is to find where it breaks on real provider traffic.
A trial can stay fully local, requires no agent-side install, and can start with one capability.
Best feedback: a concrete trace, counterexample, or field that cannot be measured safely.
→ The formal offer, schedule, and FAQ live in product/AUDIT.md · apply in Issue #2 — Looking for 3 MCP/API providers for external measurement runs.
Why capabilities need a new measurement layer
The software consumer is changing from humans to agents, and the economic unit is shifting from software seats toward callable capabilities.
Skill / MCP / CLI / SDK
        ↓
Describe / expose / distribute a capability

Capability
        ↓
Data / Compute / Action / Permission / Transaction
        ↓
Creates scarce economic value
Interfaces may become cheap to create; capabilities remain scarce to deliver.
The first generation of capability distribution is already here — open Skills, open MCP adapters, open CLIs. The scarce layer underneath them is what the next economy is built on: proprietary data, compute, execution, permissions, and real-world fulfillment.
From software to capability economy
Human Software Economy
User → UI → SaaS → Seat / Month

             ↓

Agent Capability Economy
Agent → Capability → Execution → Outcome
                       ↓
              Usage / Value / Transaction
If a capability is to become an economic unit that agents can discover, compare, and eventually purchase automatically, it must first be identifiable, measurable, and comparable under a shared semantics. That is what AgentMeasure provides.
Traditional usage metrics cannot support this economy — the old chain breaks at every link, and the last link is new:
Install ≠ Available
Available ≠ Presented
Presented ≠ Selected
Selected ≠ Used
Used ≠ Useful
Useful ≠ Incremental Value
Measured Usage ≠ Billable Usage
The last inequality is why the Operation/Attempt model matters commercially: 3 attempts of one operation are not 3 billable operations — unless the metering policy says so.
The extended thesis — economic units, scarcity, measurement before monetization,
metering semantics, and the evidence that commerce is arriving before measurement —
lives in docs/CAPABILITY-ECONOMY.md.
The measurement view: Reach → Choice → Use → Utility → Value
AgentMeasure defines metric families, not a universal KPI. A search capability, a booking API, and a compute job have different value structures.
| Layer |
Question |
Representative metrics |
| Reach |
Did the capability enter the agent's choice range? |
Eligible Opportunities · Presentations · Presentation Rate · Distribution Coverage |
| Choice |
When the agent had the chance, did it choose it? |
Observed Selection Rate · Observed Head-to-Head Choice Share |
| Use |
After selection, was it actually used? |
Operations · Attempts · Completion Rate · Success Rate |
| Utility |
Did it produce a usable result or confirmed effect? |
Result Consumption · Effect Confirmation |
| Value |
Did it improve the task outcome? |
Incremental Task Success(Draft 0.5) |
The five layers are the measurement view. The same facts map onto an economic view:
| CaaS Domain |
AgentMeasure |
| Demand |
Reach + Choice |
| Delivery |
Use + Utility |
| Outcome |
Value |
| Economics |
Metering / Attribution(future extension) |
Claim discipline throughout: observed choice is not preference. A selection can be made by the model, a router, a workflow, the user, a policy, or the platform; Observed Selection Rate reports what was observed, and Observed Head-to-Head Choice Share is an observed head-to-head choice share under comparable candidate conditions — comparable means the same candidate set, category, choice mode, and decision axes (Decision Authority / Selection Constraint) are declared.
How AgentMeasure works in production
Agent Runtime                     Capability Provider

Claude / Codex
      │
      │ MCP / API
      ▼
                         ┌──────────────────────┐
                         │ Customer Capability  │
                         │                      │
                         │ AgentMeasure SDK     │
                         │ Business Handler     │
                         └──────────┬───────────┘
                                    │
                               observations
                                    │
                                    ▼
                              Collector
                                    │
                                    ▼
                            AgentMeasure Cloud
Four things a real developer needs to know:
Your software does not need to be open source.
MCP is not required — it is the first reference surface.
Third-party agents do not need AgentMeasure installed for provider-side usage measurement.
AgentMeasure is not on the critical request path.
Product architecture (Provider SDK → local buffer → hosted ingestion → dashboard):
product/ARCHITECTURE.md.
What AgentMeasure measures today
- Decision Opportunity / Candidate Set / Presentation / Selection — the four objects of choice; the Observed Selection Rate denominator is Presented, not Available
- Software Entity → Capability → Interaction Surface — what exists, what it can do, and the observable interface; observation happens on surfaces, attribution resolves to entities through the machine-readable registry
- Operation / Attempt — one logical use vs. one execution; retries are multiple attempts of one operation, not a validity class (they are kept as reliability signals, not counted as distinct logical uses)
- Qualified Usage — production usage after excluding test, benchmark, synthetic, replay, duplicate and other invalid traffic according to policy
- Result Consumption — defined, reference partial: the result was used by the task
- Effect Confirmation — domain model defined, metric planned for Draft 0.5: the intended world-state change was confirmed
- Measurement Label — a nutrition label for every public number (coverage / sampling / policy / method)
The full model lives in the Core Specification, Metrics, Entity, and Quality. The README is not a spec summary.
From measurement to CaaS
AgentMeasure is progressively standardizing the measurement chain from discovery
and choice through execution, utility and value: core usage semantics are defined
today; utility/value and commercial metering remain active drafts. Metering and
commercial attribution are future extensions; payment rails can be provided by
existing payment infrastructure.
AgentMeasure standardizes economic facts, not money movement.
Extended thesis: docs/CAPABILITY-ECONOMY.md ·
Economic semantics: extensions/COMMERCIAL.md(Experimental)
Harness profiles — what each runtime can (and cannot) observe
Portable semantics need a public record of observation blind spots. Per-harness
profiles map each runtime's native objects to AgentMeasure semantics:
As harnesses compose software at runtime, one behavior gets described by
different objects and units in different runtimes. Experiment
D turns that into
evidence; Proposal: Delegation
defines the agent-to-agent boundary the object model was missing.
What AgentMeasure is / is not
| AgentMeasure is |
AgentMeasure is not |
| Measurement standard |
Payment protocol |
| Usage analytics foundation |
Marketplace |
| Metering semantics |
Wallet |
| Comparable quality signals |
Universal reputation score |
| Attribution framework |
Single global source of truth |
Who it is for
| Audience |
Why |
| Capability Provider |
measure and eventually meter agent usage of your capabilities |
| Agent Runtime |
expose decision / usage signals consistently |
| Registry / Marketplace |
compare capabilities using standardized signals |
| Data / Measurement Provider |
produce comparable agent-usage analytics |
| Commerce / Payment Infrastructure |
consume standardized billable events in future profiles |
| Researchers / Standard Contributors |
evolve the methodology |
Try the standard
git clone https://github.com/roy-tong/AgentMeasure && cd AgentMeasure
python3 conformance/runners/run_metrics.py   # metric vectors (M2.2 / M2.5 / M4.1)
python3 verify_vectors.py                     # verification / correlation / operation vectors
python3 registry/validate_entities.py         # validate the machine-readable registry
Product MVP — firs

 AgentMeasure — это открытый слой измерений для использования ИИ-агентов: бесплатный CLI и SDK, которые проверяют логи сессий Codex и Claude Code и удостоверяются, что метрики агентов и цифры учёта соответствуют тому, что заявляют их названия.