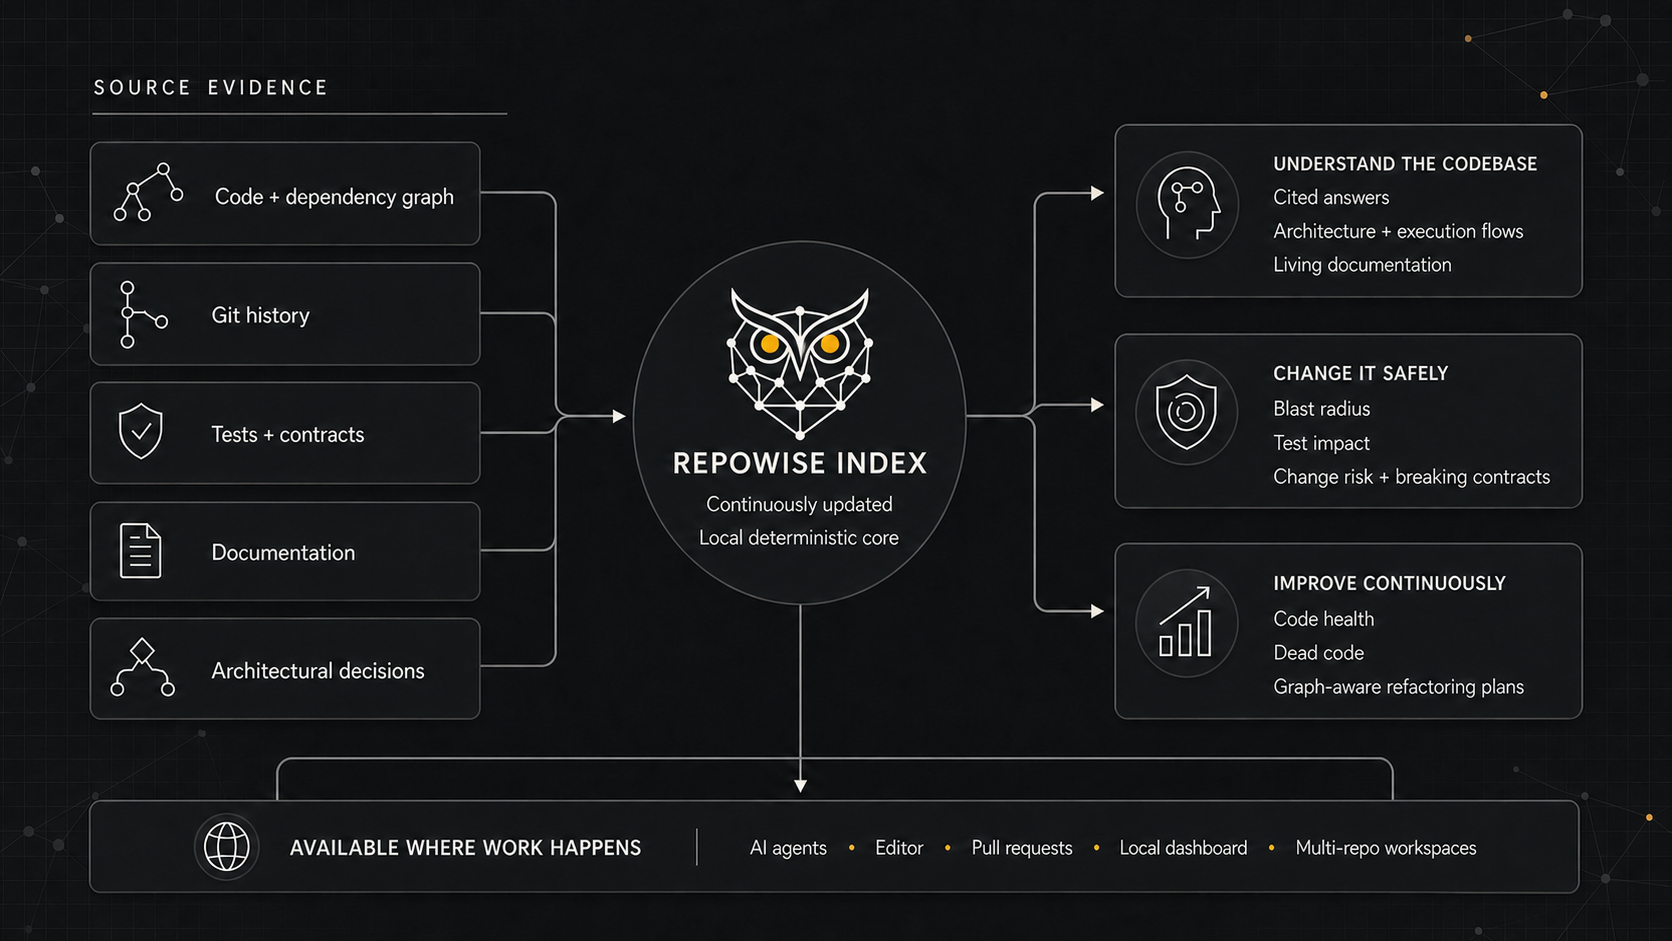
Understand your codebase without paying your agent to rediscover it.
Repowise indexes your code, dependency graph, git history, tests,
documentation, and decisions once, then gives agents and developers cited answers,
change impact, and concrete code-health fixes.
−31.6% |
97.2% |
2.3× |
less agent output
3.8 vs 7.2 tool calls
n=43 · p<0.0001 |
smaller context payload
393 vs 13,984 tokens
30 Flask commits |
more defects surfaced
same 20%-of-lines budget
2,770 files · p=0.003 |
Graph accuracy leader at matched coverage.
No tool finding as much was more precise in all 7 compiler-graded cells.
5 tools · 37,853 oracle edges
Zero LLM calls for graph, risk, health, tests,
dead code, and PR review. Generated prose is optional. Every benchmark publishes its
sample, method, limitations, and losing rows.
Free and self-hosted · core analysis stays on your infrastructure · no API key needed ·
AGPL-3.0 or commercial
Why Repowise ·
Agents ·
Changes ·
Code health ·
Workspaces ·
Evidence ·
Enterprise ·
Docs
One index. Three ways to use it.
| Understand the code |
Change it safely |
Improve it continuously |
| Ask cited questions · explore architecture and execution flows · read always-current docs · recover the decisions behind the code |
See symbol-level blast radius · run only the tests a diff exercises · catch missing companion files · detect breaking contracts before merge |
Find defect-prone files · separate maintainability from performance risk · remove dead code · hand concrete, graph-aware refactoring plans to an agent |
These are not disconnected scanners. The graph locates what git history flags; code
health measures it; tests show what guards it; decisions explain why it exists; and
the same evidence reaches your agent, editor, pull request, local dashboard, and
cross-repository system map.
A dashboard tour recorded on this repository. The same local index powers the UI,
MCP tools, editor views, and PR analysis. No API key and nothing uploaded.
Pick your front door
| If you care about… |
Start here |
| A coding agent that understands the repository |
Repowise finds the right files, returns task-shaped context in fewer calls, and proactively supplies decisions and risk. For agents ↓ |
| Safer pull requests and faster test feedback |
Get change risk, symbol-level callers, co-change partners, and a measured or graph-inferred test run list before merge. Change intelligence ↓ |
| Finding and fixing the code most likely to hurt you |
A defect-validated 1–10 health score across defect risk, maintainability, and performance, followed by the concrete refactoring plan. Code health ↓ |
| Understanding an estate, not one repository |
Match backend and frontend contracts, catch breaking providers, map downstream services, enforce architecture rules, and query every repo through one MCP endpoint. Workspaces ↓ |
| Rolling this out across an engineering organization |
Keep analysis on your infrastructure, give agents and reviewers the same evidence, and add commercial licensing, security controls, custom extensions, and SLA-backed support. Teams and enterprise ↓ |
Start in minutes (no API key)
pip install repowise
cd /path/to/your/repo
repowise init --no-prose -y
repowise serve
That builds the graph, git, decisions, health, dead-code and structural-wiki layers
locally. Connect Claude Code, Codex, Cursor or any MCP host, or open the dashboard.
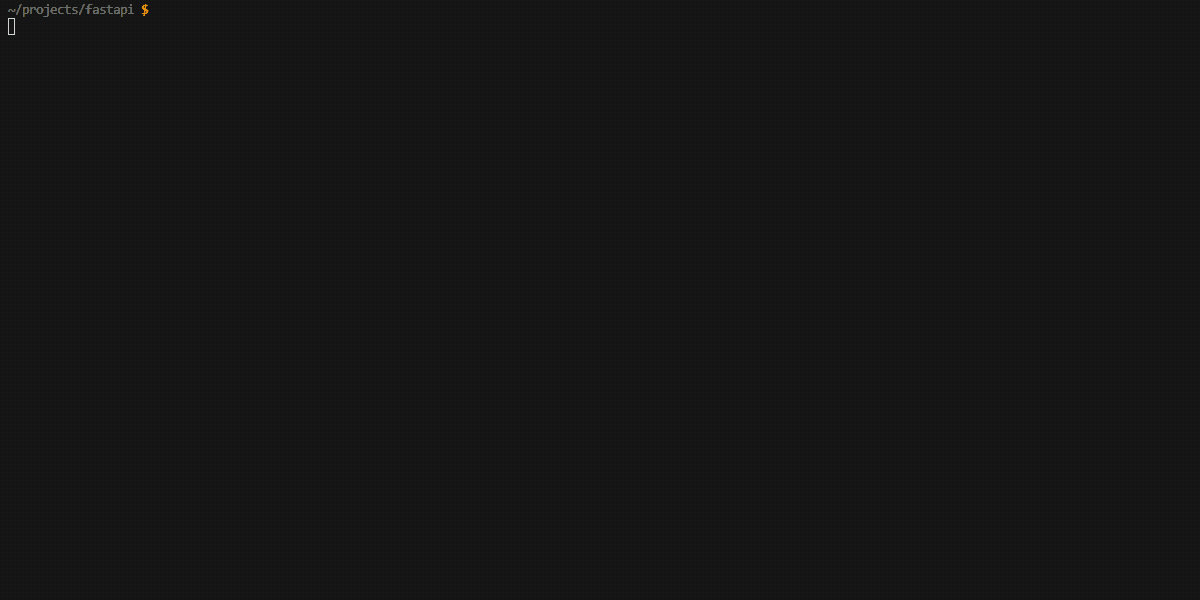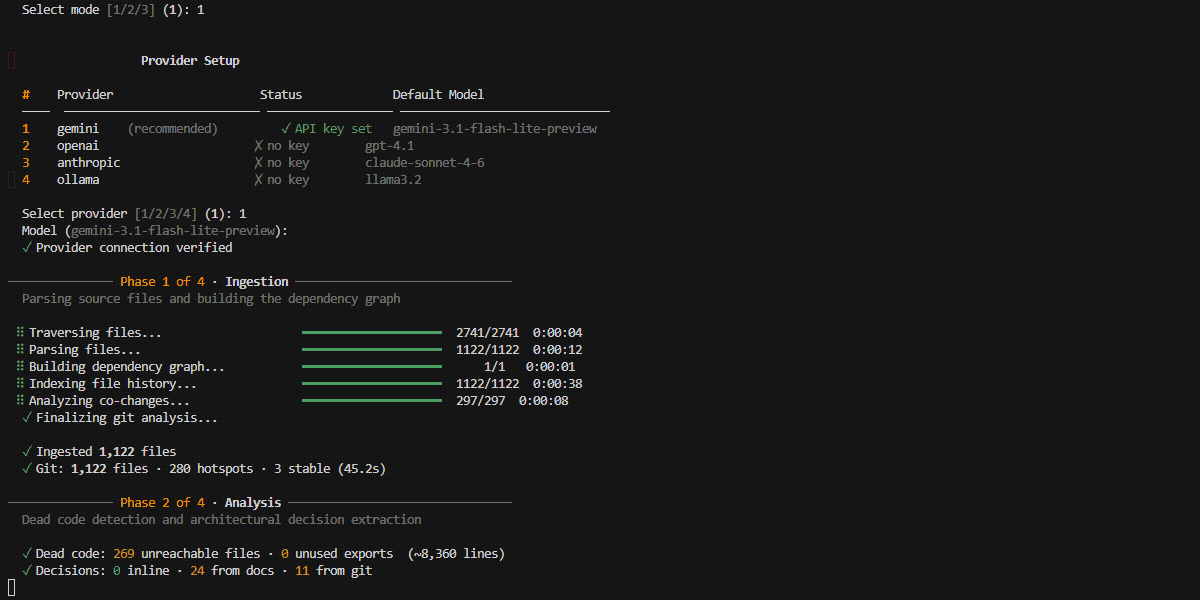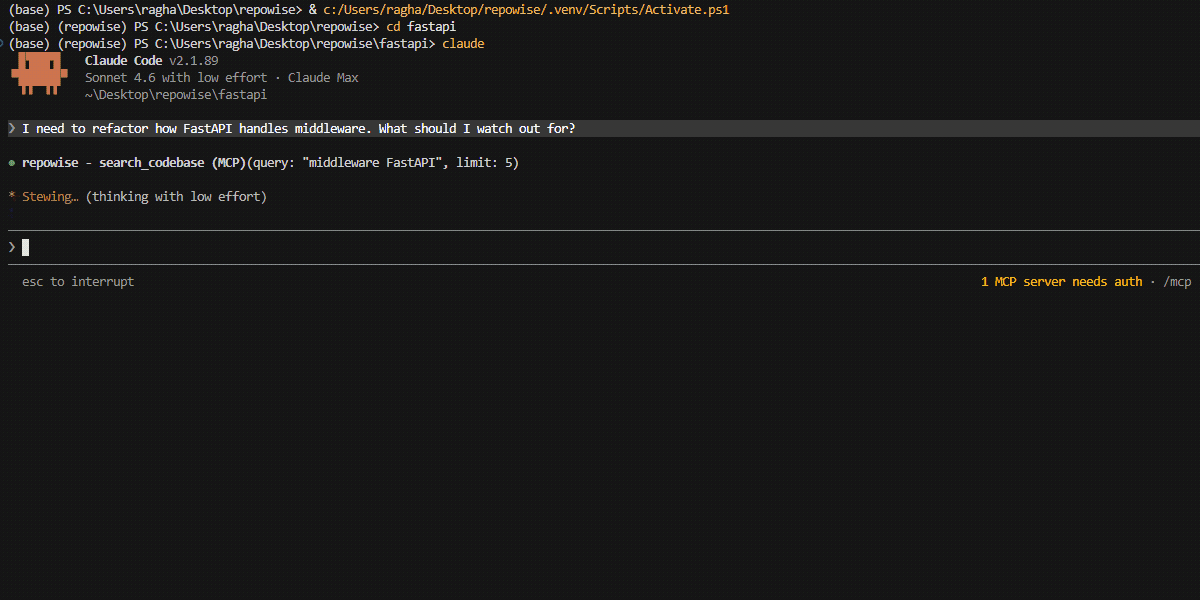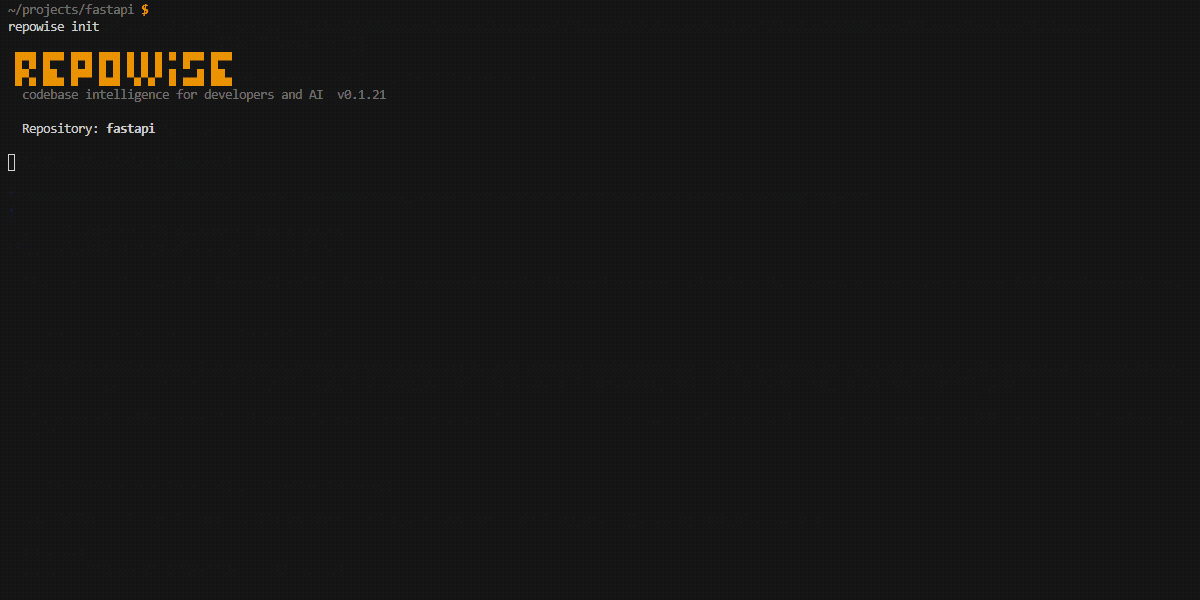
init wires Claude Code automatically. Then ask your agent: "Use Repowise
get_overview to summarize this repository" or "What breaks if I change
src/auth.py?"
Full setup, every agent, and optional model-written prose →
Your agent stops guessing
Every question your agent asks about a repository has an answer that could have been
computed ahead of time. Who calls this function? What breaks if I change it? Why is
it written this way? Which files are actually dangerous? Without an index, the agent
rediscovers that answer on every task: grep, read, re-read, forget.
Repowise exposes ten task-shaped MCP tools to Claude Code, Codex, Cursor, VS Code
and anything else that speaks MCP: graph, git, docs, decisions, and ten MCP tools
behind one index. See the canonical surface. Most tools are built around data entities (one
file, one symbol), which forces agents into long chains of sequential calls. These are
built around tasks: pass several targets in one call, get complete context back.
Because the exploration work is already done, that phase mostly disappears. In a
measured agent loop across 43 questions on django/django, Repowise cut the agent's
own output by 31.6% (p<0.0001) and reached the answer in 3.8 tool calls
instead of 7.2. That is the end-to-end result.
One mechanism is much larger but narrower: loading a commit's context through
get_context costs 393 tokens instead of 13,984, or 97.2% less. That is one
retrieval payload, not a claim of 97.2% total agent savings. Both measurements and
every competitor row are published in the benchmark report.
And it arrives without being asked. Optional hooks push
context into the session at the moment it matters: the governing architectural
decision when your agent edits a file that decision covers, a warning when it touches
a file with a run of recent bug fixes, a compact briefing at session start. Repowise
also generates your CLAUDE.md and AGENTS.md from the real index, so even an agent
with no MCP support starts informed.
It learns from how you actually work. Repowise reads your own agent transcripts
for the corrections you keep making ("use the shared HTTP client, not raw requests")
and turns the durable ones into tracked decisions it delivers back later. The wiki
generation budget tilts toward the modules you and your agent ask about most. All
local, all deterministic, no extra LLM calls.
What the index builds
| Foundation |
What it contributes |
| Graph |
File + symbol dependencies across 25 AST-parsed languages, confidence-stamped call resolution, communities, centrality, cycles, and execution flows |
| Git |
Hotspots, ownership, co-change, bus factor, and bug-fix history: behavioral signals static analysis cannot see |
| Docs |
A wiki for every module and file, rebuilt incrementally with freshness and confidence scoring plus hybrid search |
| Decisions |
Architectural rationale mined from five index-time sources plus human and agent capture, each claim traced to evidence |
| Code health |
49 deterministic detectors across defect risk, maintainability, and performance, followed by concrete refactoring plans |
The structural wiki needs no model. Model-written prose is an optional upgrade, one
page or directory at a time. Six of the seven decision sources are deterministic too;
only comment archaeology needs a provider.
The intelligence layers → ·
How the graph earns trust →
Also: stop paying for output nobody reads
Most of what an agent reads back from a shell command is noise: 300 lines of passing
tests wrapped around 4 failures, full commit bodies when it asked "what changed
recently". repowise distill <cmd> compresses command output before the agent reads
it, errors first, exit code preserved.
repowise distill pytest          # 61% fewer tokens, all 11 failure lines kept
repowise distill git log -50     # 89% fewer tokens
repowise saved                   # what distillation saved you, in tokens and dollars
Nothing is lost. Every omission leaves an inline [repowise#<ref>] marker that
repowise expand <ref> reverses in full, so the agent can always pull the detail back
without re-running the command. Small outputs pass through untouched. An opt-in hook
rewrites noisy commands automatically, shown to you for approval first.
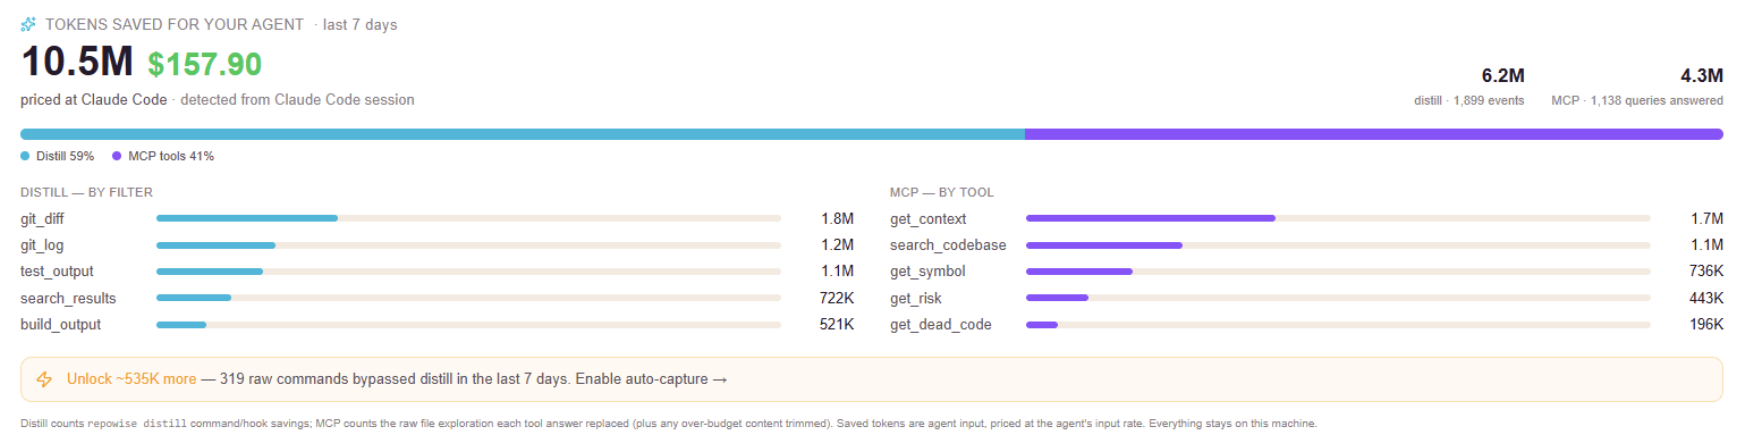
The Costs dashboard tallies both savings surfaces, priced at your own agent's model. Example from a week of heavy local use.
Full guide: docs/agent/DISTILL.md →
Know what's dangerous before you merge
Four deterministic signals, all computed from the graph and git history, no LLM:
- Change risk. Score any commit or
base..HEAD range 0-10 from the shape of
the diff, ranked against your repo's own recent commits. PR mode returns directives
rather than vibes: may_break, missing_cochanges, missing_tests, tests_to_run.
One command: repowise risk main..HEAD. (reference →)
- Bug history. Which files and symbols actually get bug-fixed, and how recently.
Doc, test and config commits are filtered out so the count means what it says, and a
file with a run of recent fixes gets flagged as a bug magnet while you edit it.
(reference →)
- Test intelligence. Which
tests reach a file and which ones a diff actually exercises, from the call graph,
with or without a coverage report.
(reference →)
- Change coordination. Which other open branches edit the files you are editing,
every row saying why it is listed (
same file, or a co-change pair with the commit
counts behind it), and whether the diff in front of you is one change or several
groups the index links nothing between. Both stay quiet when there is nothing to
report. repowise overlap and repowise risk.
(reference →)
Plus the free Repowise PR Bot, which puts all of it on every pull
request. Zero LLM calls.
Which tests cover this file, without a coverage report
Ingest LCOV, Cobertura or Clover and you get the measured answer. Most
repositories never produce one, so the graph answers instead: a test file that
imports a source file reaches it, which is a recorded edge rather than the
name-shaped guess everything else falls back to.
That fallback fails in both directions, and this repo is the proof. Five of its
six worst bug-magnet files have no test named for them and read as untested while
the graph names 3 to 23 test files each. The sixth is worse: matching on basename
paired the health engine with the distill engine's tests and called it tested.
repowise impacted-tests main..HEAD   # only the tests this diff actually exercises
repowise health                      # untested hotspots, now graph-aware
Dogfooded against a real coverage run --contexts=test:
95.7% precision on what reaches a file and 97.5% on the
run list, at a 100% hit rate, against 72.1% and 94.8% for the one-hop
import walk this replaced. The two tiers are never averaged: rows are stamped
basis: "measured" or "inferred", measured wins outright
where both can answer, and the inferred tier may never produce a percentage.
Sound as a floor, unsound as a quantity, and labelled so.
Test intelligence →
The PR bot
Install the GitHub App and the index shows up
where the decision actually gets made. One comment per pull request, edited in place on
every push rather than reposted, and a green PR gets no comment at all.
See a real comment on a real PR, not a mockup:
repowise-dev/repowise#1204.
What decides a review is inline. What is context sits behind one fold, so the comment
stays about seventeen rows whatever it finds.
- Blast radius, at symbol level. The contracts this PR changed and every caller of
them in a file the PR does not touch. Importing a module says nothing about whether
the function you changed is the one being called, so file-level impact is the wrong
altitude for the question a reviewer actually has.
- Before you merge. The tests that import your changed files, and the files that
changed alongside them in past commits but are missing here.
- A Check Run that can gate the merge, with annotations on the specific lines the
PR added. Advisory by default.
- Change risk, scored against the repository's own commit distribution rather than
an absolute scale, so it stays meaningful on a repo whose typical commit is large.
- AI vs human authorship of the changed files, with the average health of each.
- Then hotspots, hidden coupling, declining health, dead code and the change map, one
fold down.
And a page the comment links to
Markdown runs out. The comment shows three callers and says "+6 more"; the page shows
all nine. Public, no sign-in, on a repository the reader has never seen.
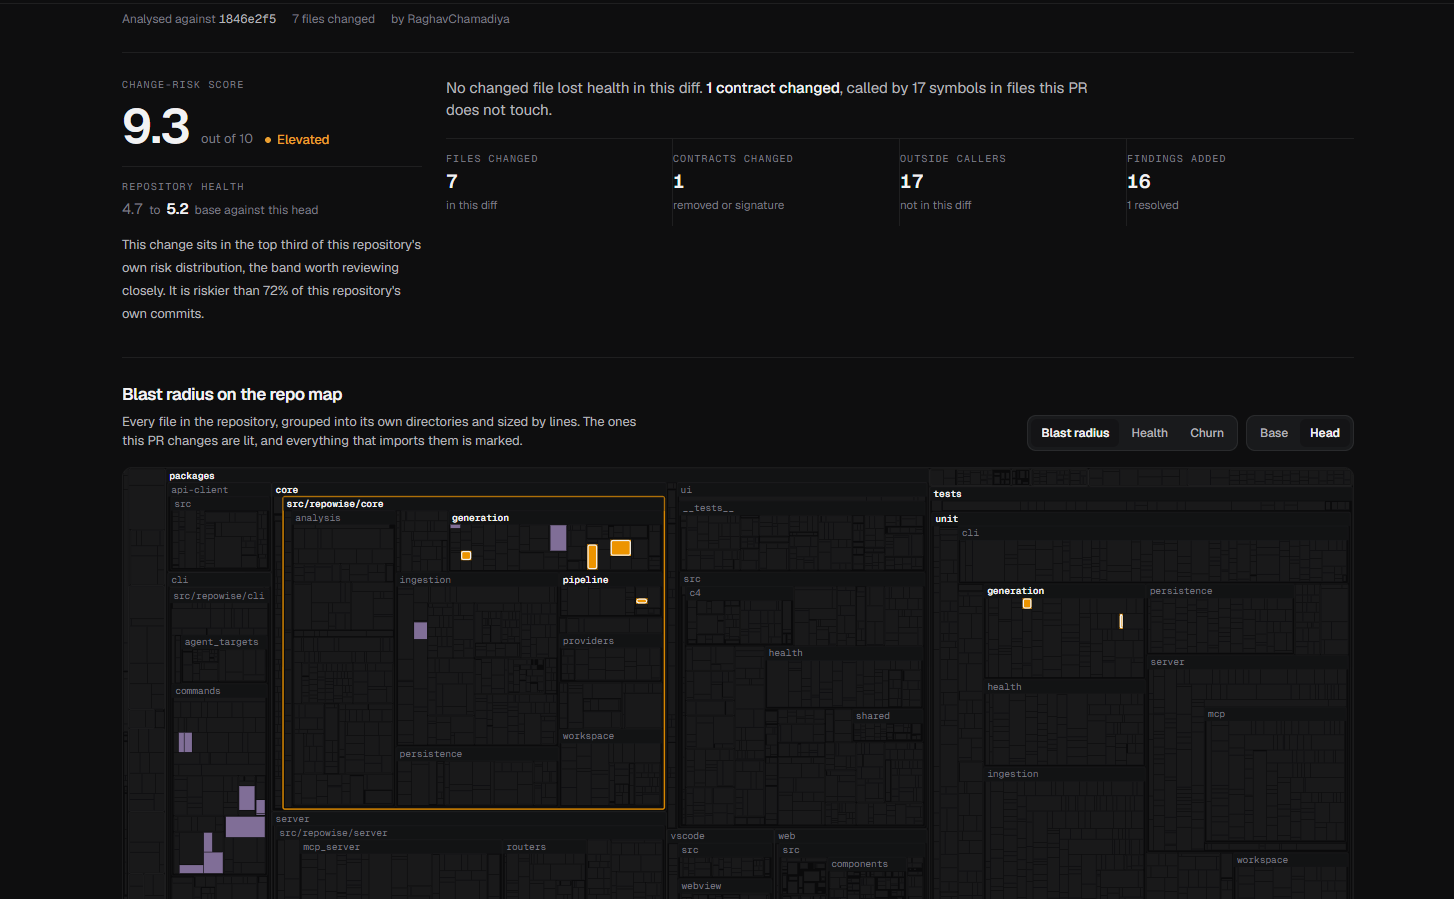
The page leads with change risk and newly introduced findings, then maps every
changed file and outside caller across the repository.
See it live →
Install the PR bot → ·
how it works →
★ Know exactly what to fix
A score that says "this file is risky" is where most tools stop. Repowise scores
every file, locates where the risk concentrates, and then names the specific fix.
Every file is scored 1-10 by 49 deterministic detectors (McCabe complexity, brain
methods, LCOM4 cohesion, god classes, native Rabin-Karp clone detection, untested
hotspots, change entropy, prior-defect history and more), split into three lenses:
defect risk, maintainability, and performance: static N+1 and I/O-in-loop
risk traced across files through the call graph, where file-local linters found 0
of the cross-function cases and repowise surfaced ~90. Only 26 of the 49 are
permitted to move the defect number, because that is the number carrying published
accuracy claims.
Zero LLM calls, zero cloud, zero new runtime dependencies. Pure Python over
tree-sitter and git data, under 30 seconds on a 3,000-file repo, a budget
enforced by a CI test, not an estimate. Marker weights are calibrated against a
real defect corpus, not hand-tuned: every file scored at a commit preceding the
bug window so nothing leaks backward, and an L2-logistic fit with file size as an
explicit control, so a marker only earns weight for defect lift beyond being big.
Only the learned constants ship.
It proves itself on your repo, not just on a benchmark. After every index,
Repowise checks its own flags against your git history and reports what it found:
"16 of the 20 lowest-health files had a bug fix in the last 6 months, 3.3x the 24%
baseline." If that number is bad on your codebase, you will see it. (It is an
association on your indexed history, not a forward prediction, the leakage-free
version is in the benchmarks.)
Then it names the fix. Not "this class is too big", but Extract Class, Extract
Helper, Move Method, Break Cycle, Split File, or Extract Method, with
the exact methods, edges and symbols that move, the blast radius of callers and
co-changing files that have to move with them, and a graph-aware ranking so a fix on a
central hub outranks the same fix on a leaf. Extract Method goes down to an
intra-procedural dataflow pass that lifts the exact span and infers a
behavior-preserving signature.
repowise health                        # KPIs and lowest-scoring files
repowise health --refactoring-targets  # ranked, concrete plans
repowise health --trend                # snapshots plus declining-health alerts
The dashboard renders each plan as a card with a copy-to-agent


 Repowise indexes a codebase once (code, dependency graph, git history, tests, docs, and architectural decisions) and then gives AI agents and developers cited answers, change-impact analysis, and concrete code-health fixes instead of making an agent rediscover the code every time.