
Language Agnostic · Model Agnostic · Compiles Locally · BYOK · MCP Compatible


What is Benzi
Most AI coding agents dump a repo into a context window and hope the model finds what matters. Benzi parses every file first — a real compiler, built on tree-sitter — into a precise, queryable map. Every symbol, every call edge, every reference, every class in its inheritance chain. One pass, done.
Every file parsed, imports resolved, class ancestry built, every identifier traced to its definition — before a single question is answered. Call flow and data flow join at every call site, so a bad value traces to its origin in one tool call. Claude Code greps; Cursor embeds; Aider maps signatures; Benzi resolves — in O(1). Ten languages so far, plus a markup engine for HTML, CSS, and DOM-JS — see Language support.
You can try pasting this repo's link to Benzi in the live demo too!
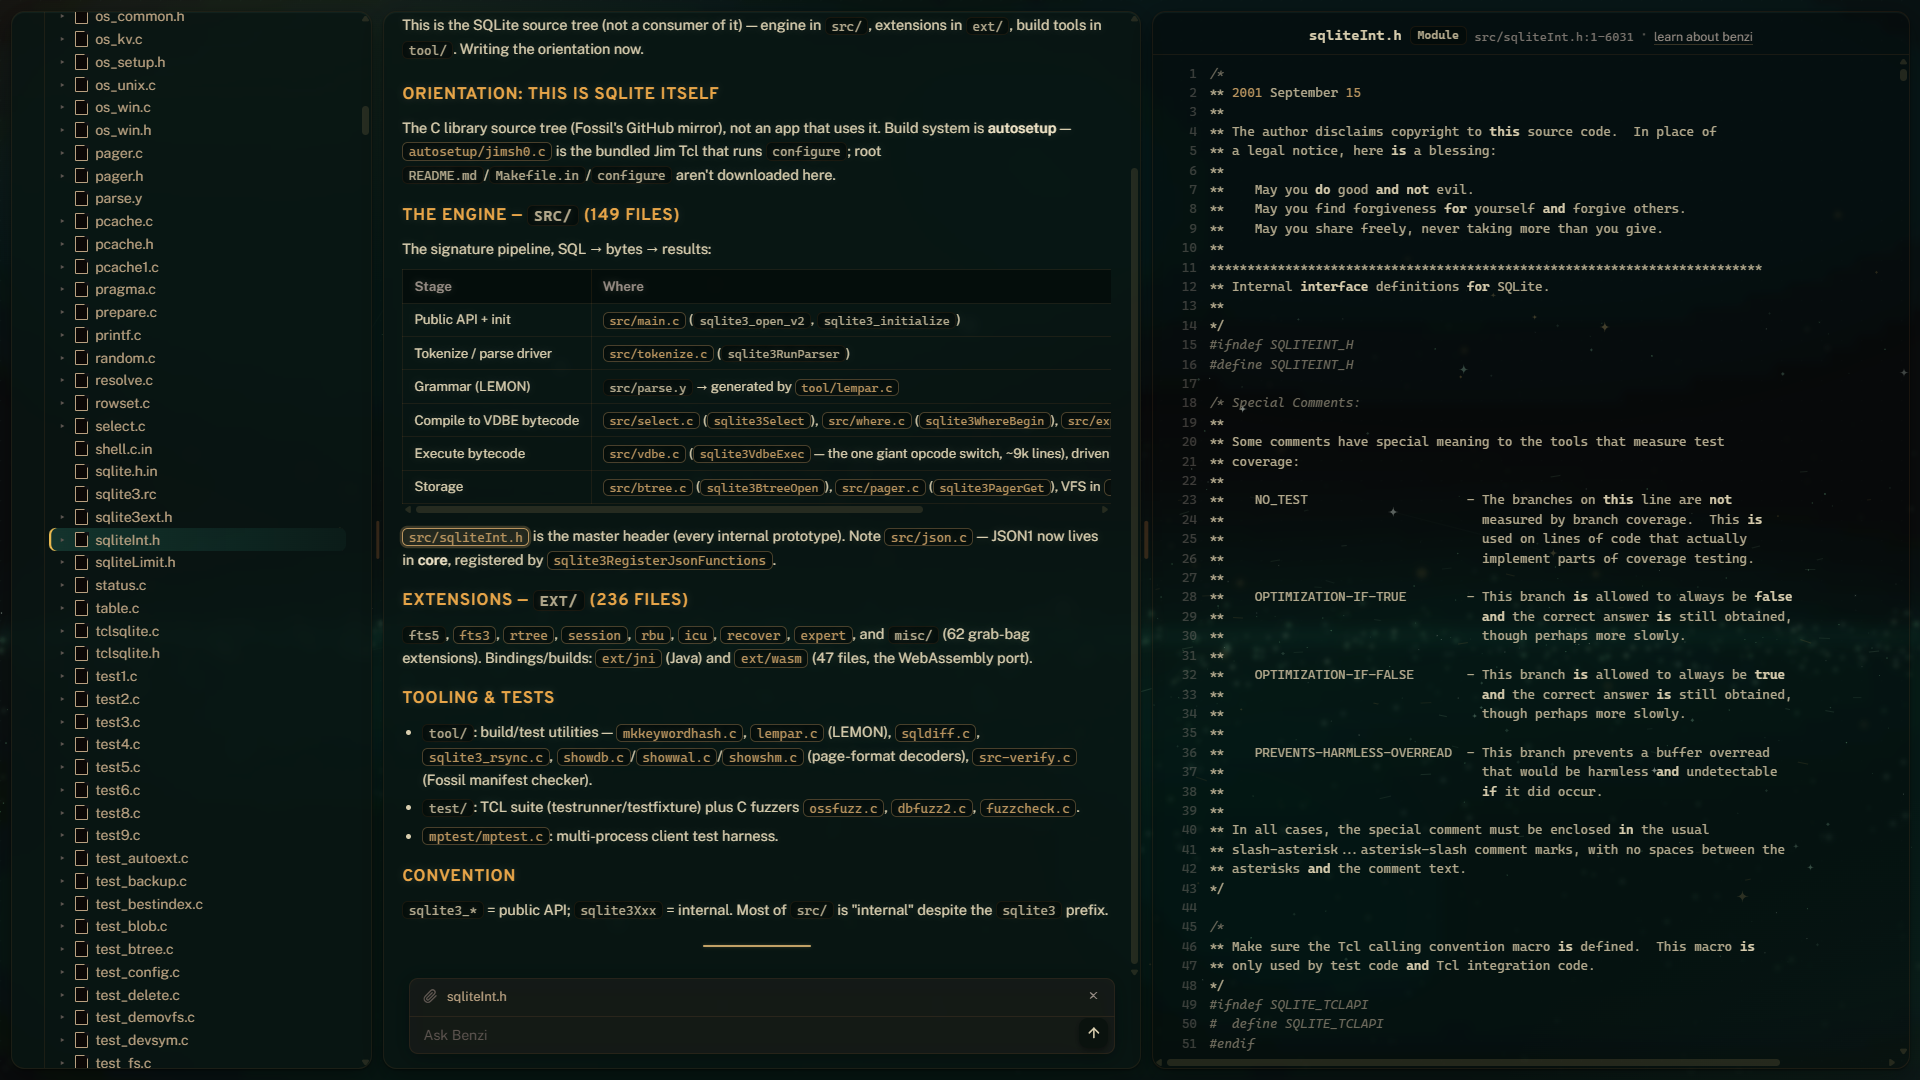
Benzi on SQLite
Live demos
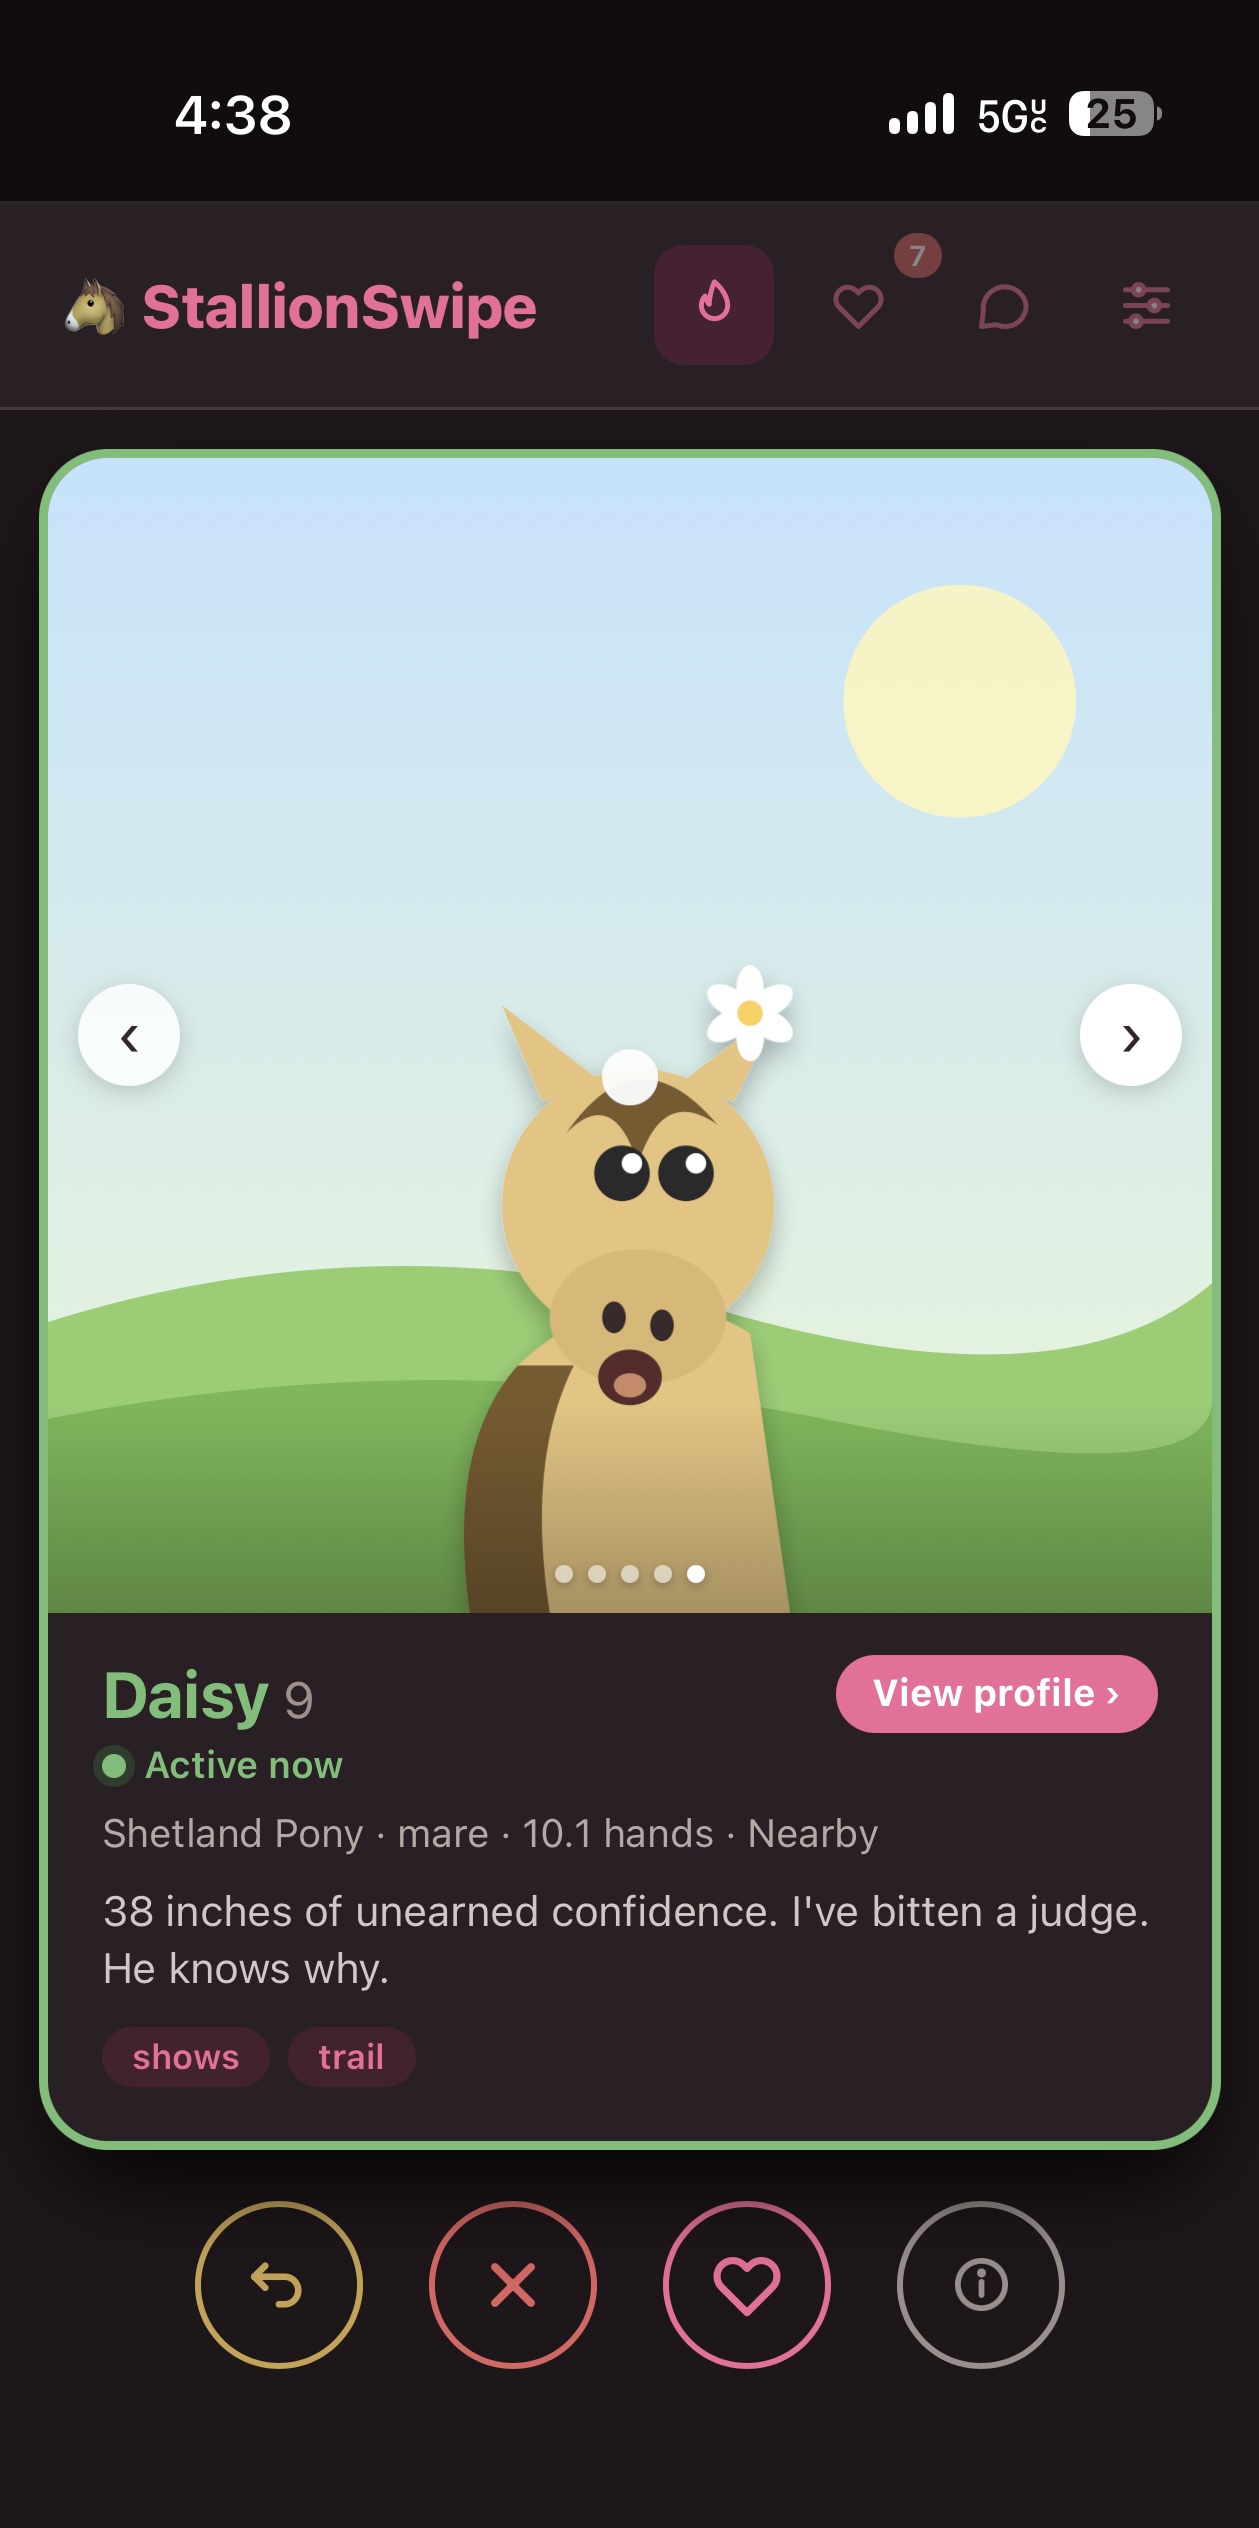
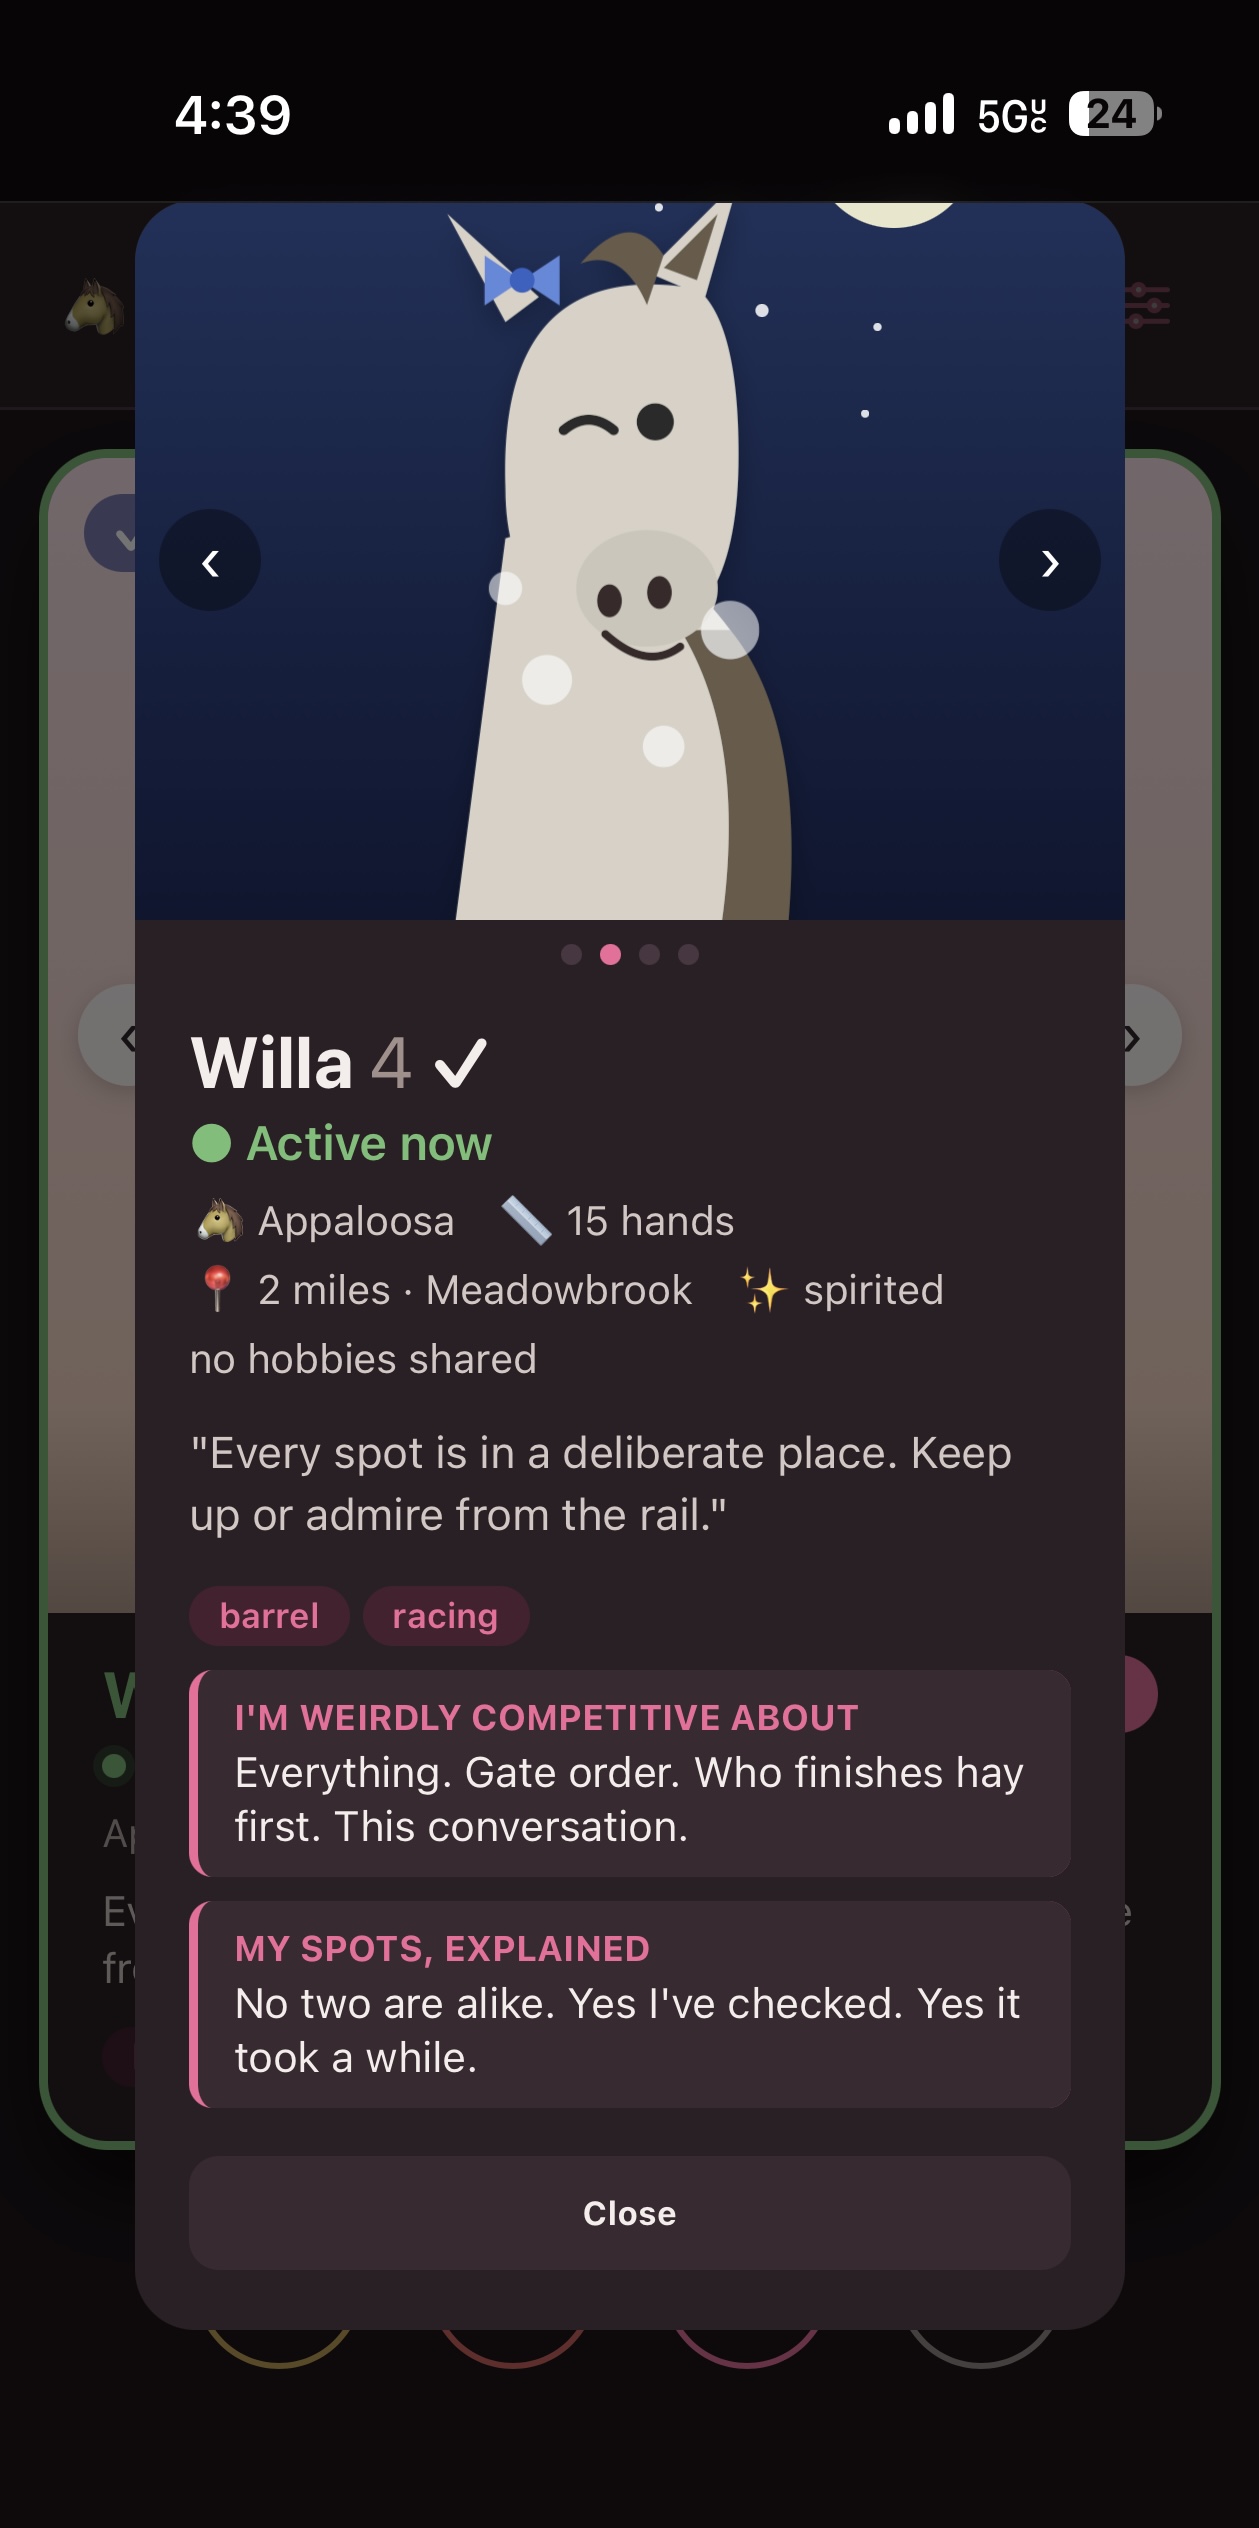
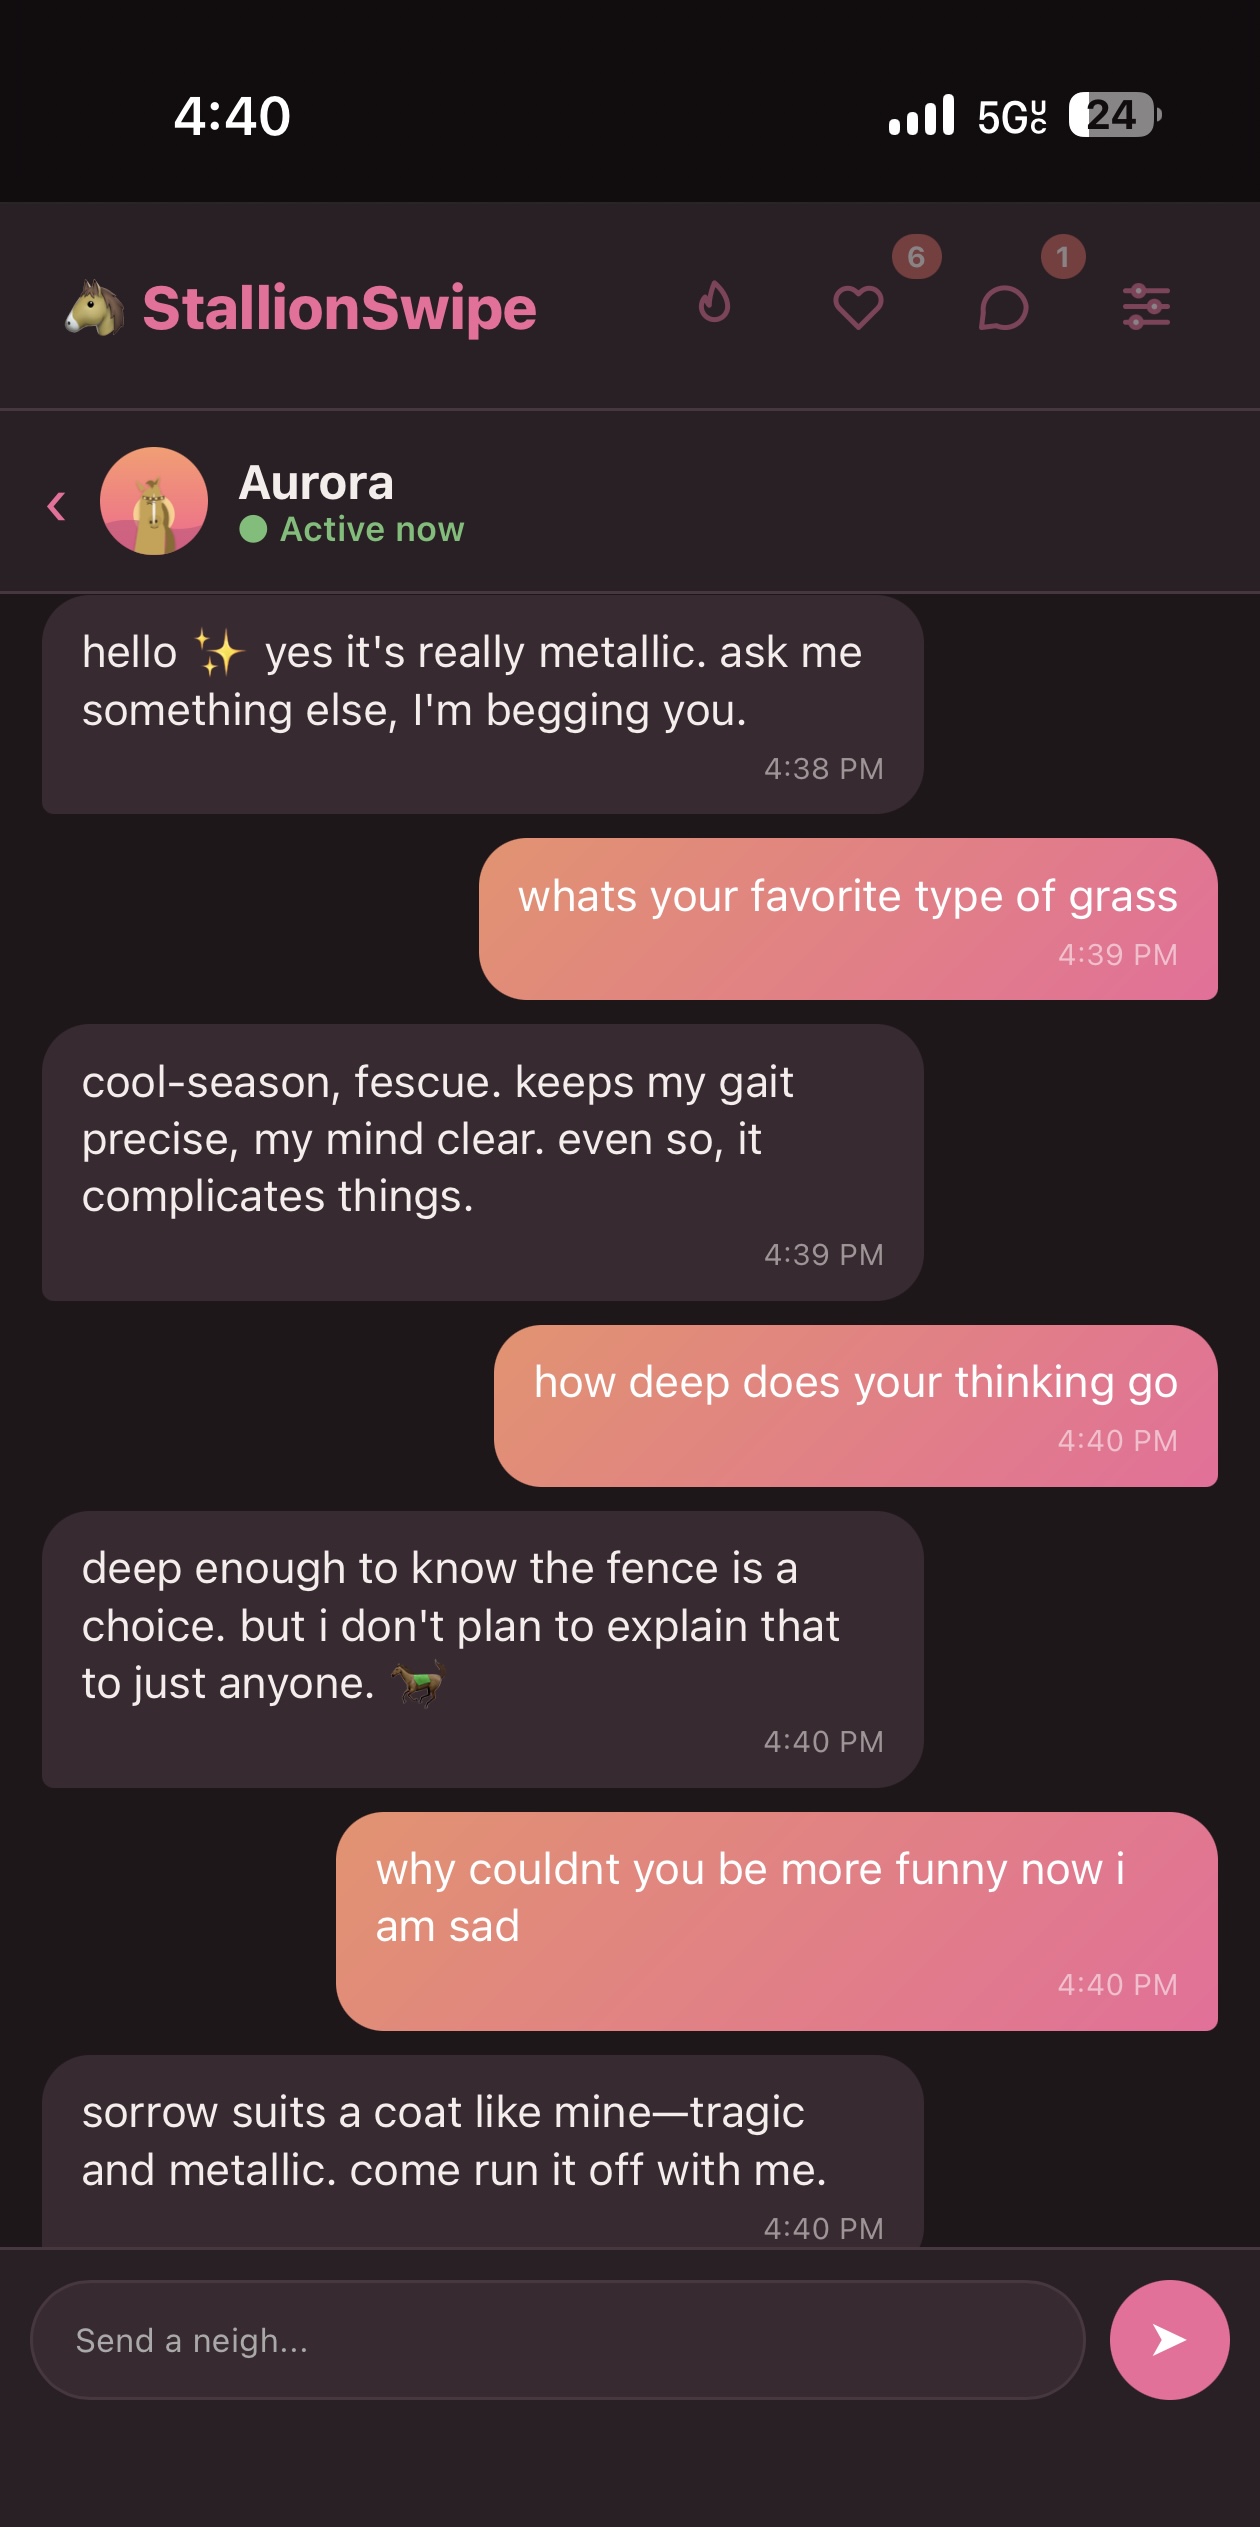
StallionSwipe · Python, HTML, CSS, JS — a dating app for horses, greenfielded by Benzi from scratch in a single chat session. No image is a file: every horse portrait is procedural SVG, generated in code. Match with one and it flirts back through a real model, live. Frontend, backend, and the prompts — all written by Benzi. Try it live.
VS Code's own source, resolved · TypeScript — the real microsoft/vscode repo is 1.8M lines; this indexes 923k of them: the editor core (src/vs/editor + src/vs/base), the platform services layer, and workbench's shell/API/browser plumbing — deliberately excluding the 747k-line grab-bag of individual features in workbench/contrib. Built once, in just over two minutes, then cached. Try it live (chat panel, near the bottom of the page).
Or, try any repo of your choice at all here — point Benzi at any public GitHub repo and it builds the index live. varianttech.net/demo.
What people say
"78.2% for $37 is a slap in the face to the 'brute force wins' school."
— Alex Xiang, zicode (translated)
"Benzi is proving that the core competency of coding tools is shifting from simple 'reading comprehension' to 'structural grasping ability.'"
— Gi Pyeong Lee, Tech Blog
"Fewer tokens, no context drift. Wild idea, honestly."
— prompt 🤖 AI News
"It analyzes changes before writing them — and beats Claude Code on benchmarks."
— Ponte al dIA (translated)
SWE-bench Verified
The full SWE-bench Verified set — 500 real GitHub issues from twelve Python repositories — run end to end on DeepSeek v4-flash, one attempt per instance, graded by the official swebench.harness.run_evaluation inside its own per-instance Docker images, with network access to GitHub and PyPI blocked inside every container.
|
|
| Resolved |
391 / 500 — 78.2% |
| Total cost, all 500 instances |
$37.33 |
| Cost per instance resolved |
$0.095 |
| Source lines read (total / median) |
231,574 / 379 |
| Model turns (total / median) |
16,091 / 27 |
| Input tokens served from cache |
97% |
| Output tokens |
22.0M |
Full technical report: swebench/SWE_BENCH_REPORT.md (web version). Every instance's cost, tokens, turns, and lines read: varianttech.net/benchmark_swebench. The cross-harness efficiency comparison below (and the full 24-bug chart): varianttech.net/benchmark.
How it works
- Compile. Tree-sitter parses every file, resolves imports, builds class ancestry, traces every identifier to its definition. Output is an index, not text.
- Query. The agent reads and plans through structured tools over that index —
profile, get_callers, backflow, trace_path, skim_source, ~30 more.
- Edit, gated. Every write is checked against the real parser; a broken parse auto-reverts. Blast radius — the changed symbol, its callers, its holders, the relevant tests — is checked going in and again once the write lands.
- Verify by running it. A focused repro runs under a runtime tracer alongside the tests blast-radius flagged. Real values, real dispatch: this proves the change and settles the map — ambiguous edges collapse onto whatever target actually fired.
- Reindex, incrementally. Every turn re-parses only what changed on disk — your edits and the agent's, treated the same.
- Revert, from a snapshot. Every write snapshots the index first, so undo reloads that snapshot instead of re-deriving it.
- Back to step 2. The next question always answers against the code as it is now.
A sample of 16 of Benzi's 35+ tools — what falls out of actually resolving the code, from the index itself to the gates on every write.
| Tool |
What it answers |
get_callers |
Every call site that reaches a function — the code that will feel a change. |
call_tree |
The transitive call closure from one function, forward or in reverse. |
trace_path |
The call chain connecting two functions, and the data carried along it. |
external_calls |
Which libraries a scope leans on, and where it calls into them. |
forwardflow |
Where a function's return value ends up, everywhere it has to match. |
backflow |
Where a wrong value came from, without opening every caller. |
profile |
The full 360 on one symbol in a single call. |
get_definition |
The declaration card — signature, docs and location. |
search_symbols |
Case-insensitive substring search across every symbol in the repo. |
get_hierarchy |
A type's resolved bases and its direct subclasses. |
skim_source |
A body's one-level outline, so you know which lines are worth reading. |
execute_from |
Runs a file under the call tracer and records what actually happened. |
check_last_execution |
Reads back the last recorded run's facts, no re-run needed. |
execute_generated_testcase |
Writes a self-contained repro and runs it to debug its own change. |
rollback_edit |
Undoes the last writes by snapshot reload, not by re-editing. |
upgrade_to_pro |
Escalates itself to a larger reasoning budget mid-task. |
What the index actually changes
Same 24 bugs, one run each, four harness/model combinations. Lines read counts only what came back from file-read calls — grep and shell output are search, not reading, so this is the one figure that means the same thing in every harness.
| Harness · model |
Lines read |
vs Benzi |
| Benzi · Sonnet |
9,125 |
— |
| Benzi · DeepSeek |
16,407 |
1.8× |
| Claude Code · Sonnet |
20,704 |
2.3× |
| DeepSeek Harness · DeepSeek |
43,598 |
4.8× |
Every harness opens more source as bugs get harder — the question is the slope. Benzi's stays flatter because it answers most of what a bug needs from the map instead of by reading.
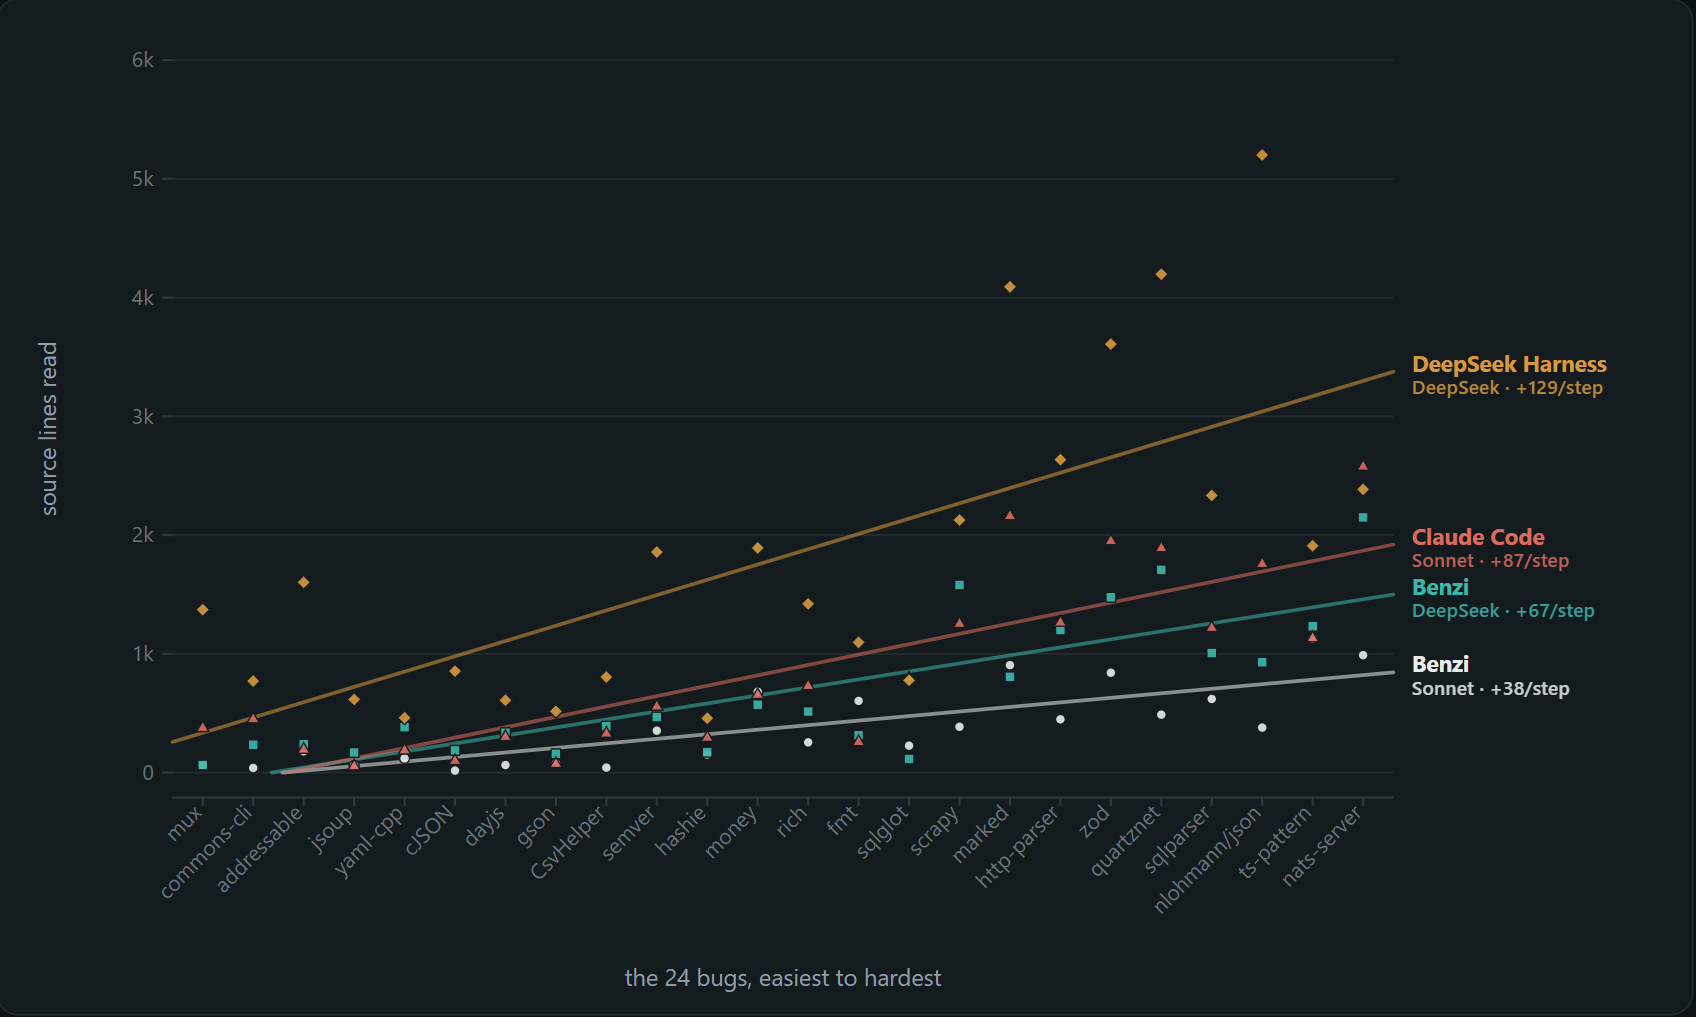
Benzi reads the least source on every bug and the gap widens as bugs get harder — the index answers most of what a fix needs before a file is ever opened.
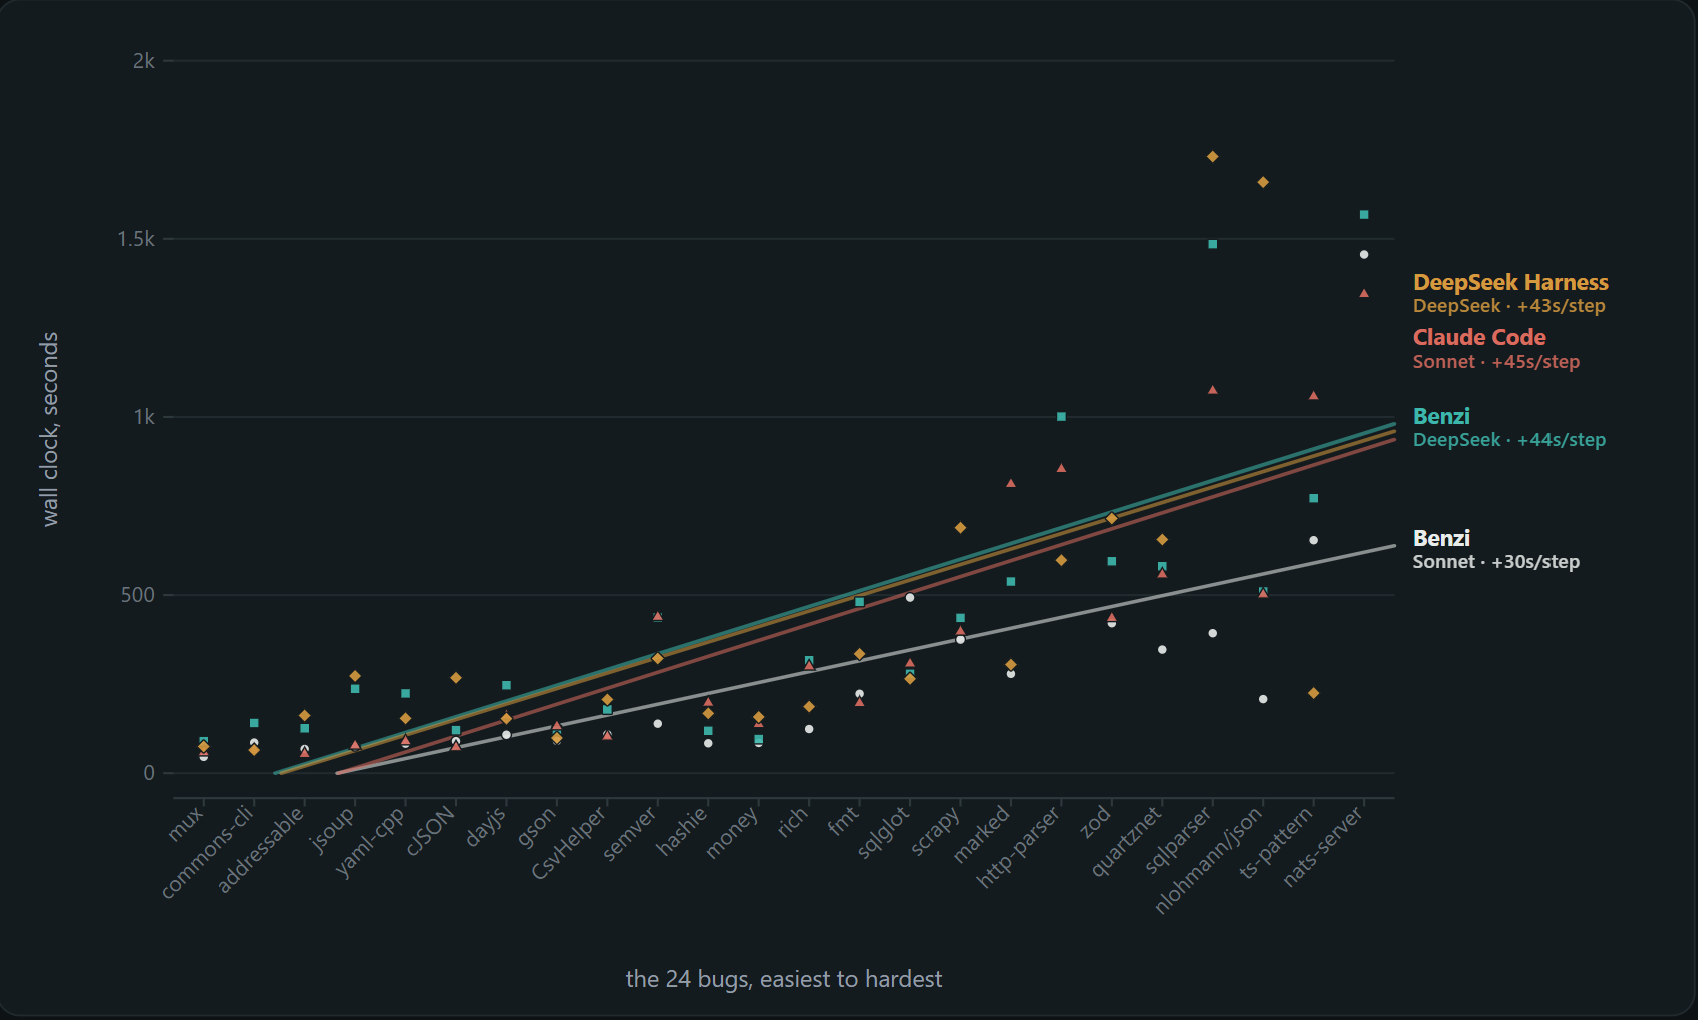
Wall-clock time tracks close across all four — reading less doesn't make Benzi slower to think, just cheaper to look.
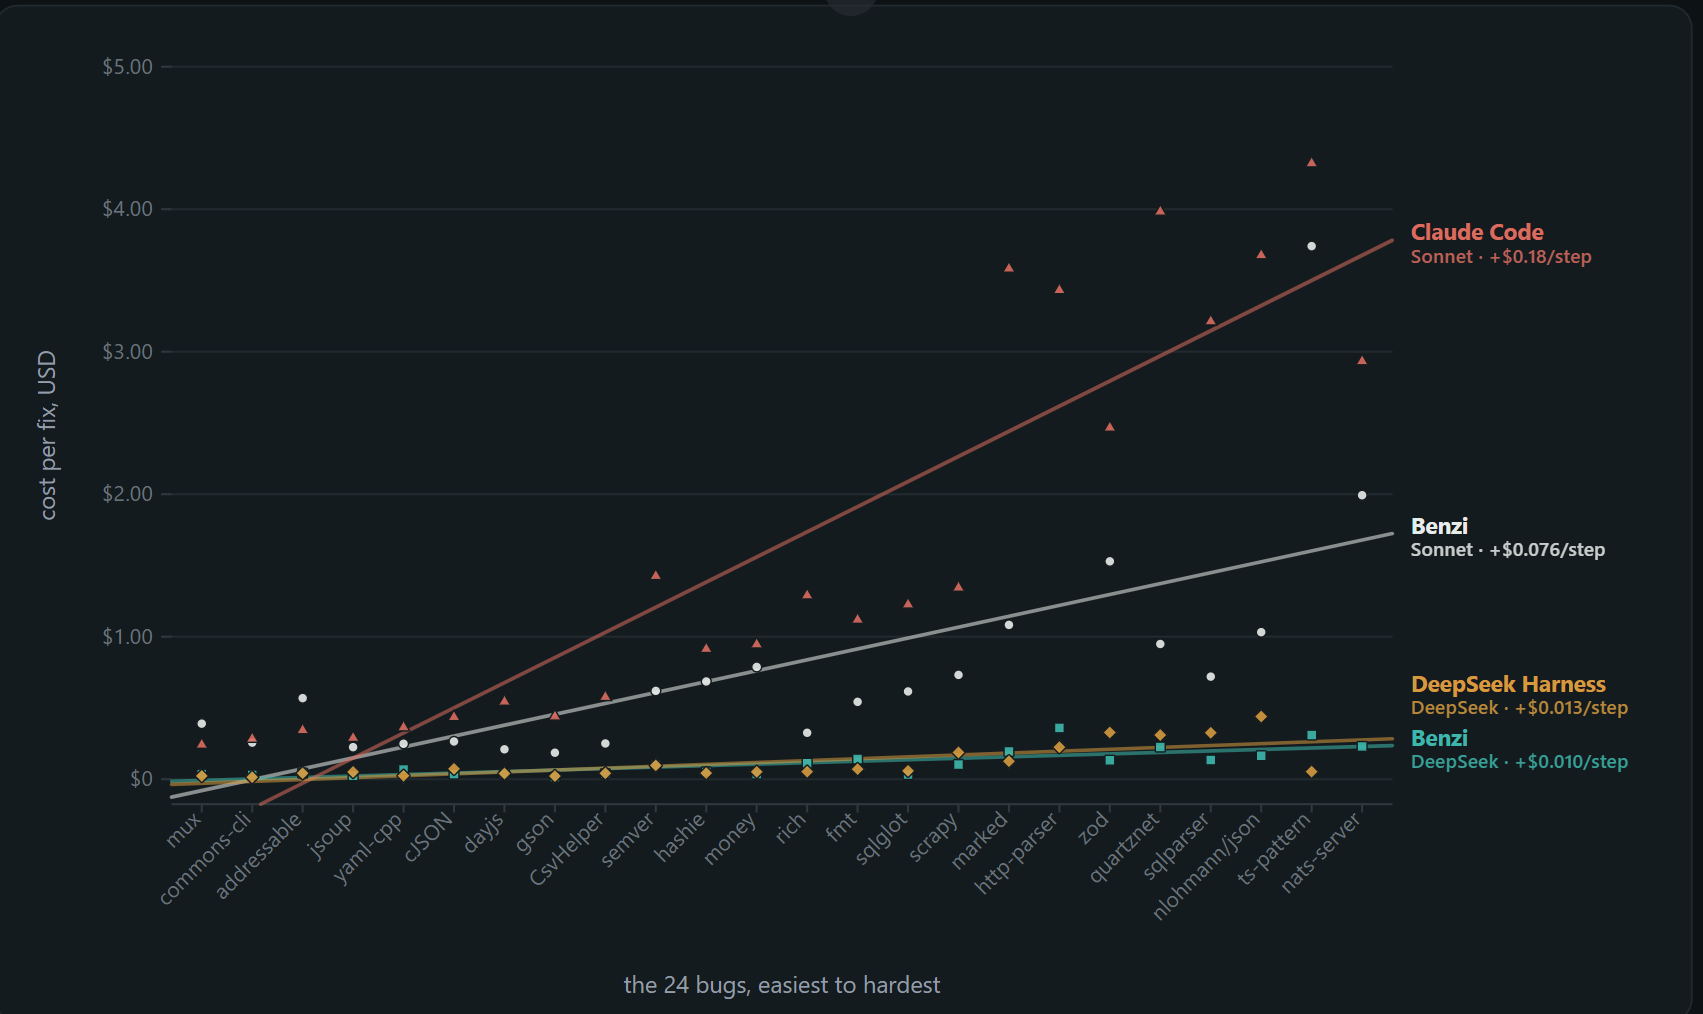
Benzi on DeepSeek costs about a cent a bug; Claude Code climbs to $0.18 a step as bugs get harder — roughly 18x.
More detail, per-bug breakdowns, and full methodology: varianttech.net/benchmark.
Features
- Six states, never a guess — every call site and every file carries one: resolved (proven in-repo edge), external (into a library, with the import evidence), candidate (ambiguous — the bounded set of possible targets, kept in full), unresolved (seen but not settled, carrying why), observed (confirmed by an actual run), unindexed (never parsed, with the reason). One rule throughout: whatever static analysis can't settle is flagged as unsettled rather than guessed — and running the program is what settles it.
- Runtime tracer — hooks every call during execution and overlays the observations back onto the static map.
- Reasoning you can click — the same map that drives the tools drives a live call graph beside the chat; when the agent names a function, that node lights up.
- Persistent memory — durable per-repo facts survive restarts; conventions learned once aren't re-derived every session.
- Dual-engine: code + markup — a separate index for HTML/CSS/DOM-JS with cascade resolution and selector specificity, including frontend embedded inside Python strings.
- Model-agnostic — Anthropic, OpenAI, or any compatible API; the agent can escalate itself to a larger model mid-task when a problem outgrows the one running it.
Language support
Python · JavaScript · TypeScript · Java · C# · C++ · C · Go · Rust · Ruby
One compiler, ten languages — each is a tree-sitter grammar plugin, so the core of the map (symbols, call edges, references, inheritance, data flow) is built the same way everywhere.
Depth is uneven, and we'd rather say so than let you find out. Python is deepest, and the only one with the runtime tracer. Every language reaches the core of the map, but each has its own constructs, not all modelled yet — a question specific to your language may come back thinner than the same question in Python.
Incremental reindexing is also less optimized for C, C++, Rust, and Ruby — it works, just not as fast on a large edit loop.
Wrong or thin answer in your language? Open an issue with the repo, the question, and what it got wrong — that's how the uneven parts get found.
Getting started
Benzi is completely free to use.
- In the browser — paste any public GitHub repo at varianttech.net/demo; no install, no signup. Read-only: ask it questions, explore the map, nothing writes to the repo. This is the demo — click here to see what it can do.
- In VS Code — the same compiler, but with edit access: chat, graph, and Benzi actually writing code in your own project. VS Code Marketplace. This is the real tool — click here to use it.
- MCP — the same compiled index, exposed as tools over MCP for whatever agent you already run: Claude Code, Cursor, or your own harness.
pip install benzi, then point your MCP client at benzi-mcp. This is the benzi index without the agentic loop — output quality will depend on your agent/harness.
- Headless — the same agent as VS Code, from your own terminal:
pip install benzi, then benzi <repo> "your question". This is Benzi for scripts and CI — no editor needed. (https://pypi.org/project/benzi/)
Run benzi_login once to authenticate before using the VS Code extension, MCP, or headless — the same command lets you update your model or key again later too.
FAQ
Does my code leave my machine?
No. In VS Code, the CLI, or MCP, the compiler and index run locally — nothing uploaded, no copy kept. Only the snippets the agent actually reads go to your model provider, same as any AI assistant, and less of them: 9,125 lines read vs Claude Code's 20,704 on the same 24 bugs. The browser demo differs — it fetches a public repo server-side, read-only, deletes it after your session.
Do I need an API key?
No, for the browser demo. Yes for VS Code, MCP, and the CLI — run benzi_login once with your own key.
Is it actually free?
Yes, Benzi doesn't charge. The CLI and MCP are BYOK, so you pay your own model provider. Early and in development — that's the trade, not a paywall.
Can I point it at a private repo?
Not the web demo (public GitHub API only). Everywhere else, yes — the compiler runs locally on whatever path you give it.
How large a repo can it handle?
VS Code handles real codebases — microsoft/vscode, 923k lines, indexes in ~2 minutes, then caches. The browser demo caps at 2,000 files, 2 MB each.
How is this different from Cursor, Copilot, or Claude Code?
They search — grep or embeddings. Benzi resolves first: a real index of symbols, calls, inheritance, data flow, queried instead of guessed. Same 24 bugs, 2.3× less source read than Claude Code. Details: what the index actually changes.
How is this different from CodeGraph?
Both index instead of search, but CodeGraph retrieves — ranked candidates from a queried database. Benzi resolves — settles what a name binds to before answering, and refuses rather than guesses when a call site is ambiguous. It also models code the way an engineer reads it — file → scopes → call flow → data/control flow — not a flat symbol graph.
On CodeGraph's own benchmark (their repos, their questions, their methodology), four models blind-judged Benzi's MCP answers first. Full results: varianttech.net/benchmark_codegraph.
My language isn't Python — how much do I lose?
The structural index — symbols, calls, references, inheritance, data flow — is the same across all ten languages. Only the runtime tracer is Python-only, and depth varies by language — see Language support.

 Benzi is a compiler-backed coding agent: it parses your whole codebase with tree-sitter into a queryable index of symbols, calls, and data/control flow, then uses that map to explain, edit, and verify code changes, including a runtime tracer that settles what static analysis alone can't.