OpenDataLoader PDF
PDF Parser for AI-ready data. Automate PDF accessibility. Open-source.





🔍 PDF parser for AI data extraction — Extract Markdown, JSON (with bounding boxes), and HTML from any PDF. #1 in benchmarks (0.907 overall). Deterministic local mode + AI hybrid mode for complex pages.
- How accurate is it? — #1 in benchmarks: 0.907 overall, 0.928 table accuracy across 200 real-world PDFs including multi-column and scientific papers. Deterministic local mode + AI hybrid mode for complex pages (benchmarks)
- Scanned PDFs and OCR? — Yes. Built-in OCR (80+ languages) in hybrid mode. Works with poor-quality scans at 300 DPI+ (hybrid mode)
- Tables, formulas, images, charts? — Yes. Complex/borderless tables, LaTeX formulas, and AI-generated picture/chart descriptions all via hybrid mode (hybrid mode)
- How do I use this for RAG? —
pip install opendataloader-pdf, convert in 3 lines. Outputs structured Markdown for chunking, JSON with bounding boxes for source citations, and HTML. LangChain integration available. Python, Node.js, Java SDKs (quick start | LangChain)
♿ PDF accessibility automation — Auto-tag untagged PDFs into screen-reader-ready Tagged PDFs at scale. First open-source tool to generate Tagged PDFs end-to-end.
- What's the problem? — Accessibility regulations are now enforced worldwide. Manual PDF remediation costs $50–200 per document and doesn't scale (regulations)
- What's free? — Layout analysis + auto-tagging (Apache 2.0). Untagged PDF in → Tagged PDF out. No proprietary SDK dependency (auto-tagging)
- What about PDF/UA compliance? — Converting Tagged PDF to PDF/UA-1 or PDF/UA-2 is an enterprise add-on. Auto-tagging generates the Tagged PDF; PDF/UA export is the final step (pipeline)
- Why trust this? — Built in collaboration with Dual Lab (veraPDF developers) based on PDF Association specifications, best practice guides and expertise of the PDF Community. Auto-tagging follows the Well-Tagged PDF specification, validated with veraPDF (collaboration)
Get Started in 30 Seconds
Requires: Java 11+ and Python 3.10+ (Node.js | Java also available)
Before you start: run java -version. If not found, install JDK 11+ from Adoptium.
pip install -U opendataloader-pdf
import opendataloader_pdf

# Batch all files in one call — each convert() spawns a JVM process, so repeated calls are slow
opendataloader_pdf.convert(
    input_path=["file1.pdf", "file2.pdf", "folder/"],
    output_dir="output/",
    format="markdown,json"
)
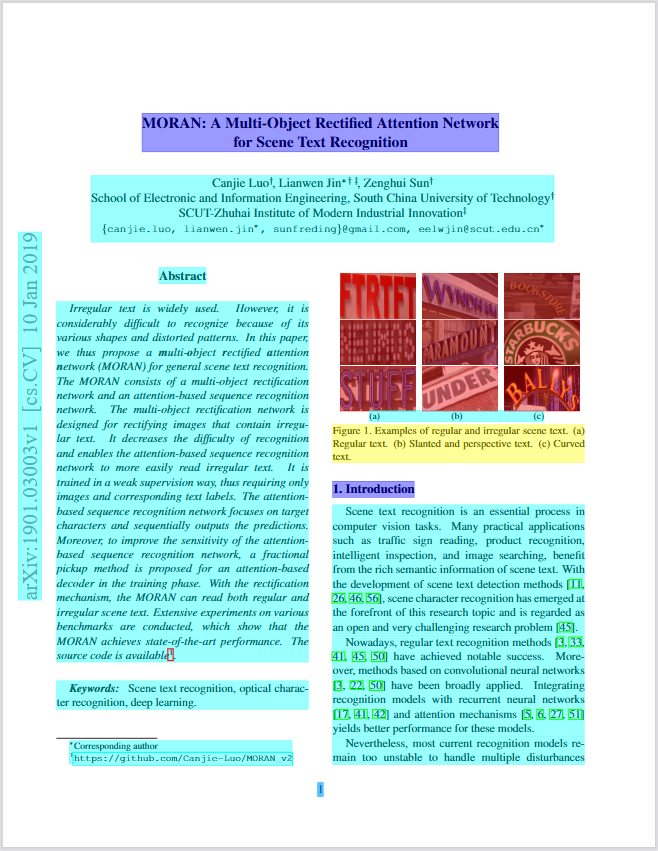
Annotated PDF output — each element (heading, paragraph, table, image) detected with bounding boxes and semantic type.
What Problems Does This Solve?
| Problem |
Solution |
Status |
| PDF structure lost during parsing — wrong reading order, broken tables, no element coordinates |
Deterministic local PDF to Markdown/JSON with bounding boxes, XY-Cut++ reading order |
Shipped |
| Complex tables, scanned PDFs, formulas, charts need AI-level understanding |
Hybrid mode routes complex pages to AI backend (#1 in benchmarks) |
Shipped |
| Manual PDF remediation cost — Accessibility regulations (EAA, ADA, Section 508) demand Tagged PDFs. Manual remediation costs $50–200/doc |
Auto-tag untagged PDFs into Tagged PDFs (free, Apache 2.0). Foundation for PDF/UA workflows; full PDF/UA-1/2 export is an enterprise add-on |
Auto-tag: Shipped. PDF/UA export: Enterprise |
Capability Matrix
| Capability |
Supported |
Tier |
| Data extraction |
|
|
| Extract text with correct reading order |
Yes |
Free |
| Bounding boxes for every element |
Yes |
Free |
| Table extraction (simple borders) |
Yes |
Free |
| Table extraction (complex/borderless) |
Yes |
Free (Hybrid) |
| Heading hierarchy detection |
Yes |
Free |
| List detection (numbered, bulleted, nested) |
Yes |
Free |
| Image extraction with coordinates |
Yes |
Free |
| AI chart/image description |
Yes |
Free (Hybrid) |
| OCR for scanned PDFs |
Yes |
Free (Hybrid) |
| Formula extraction (LaTeX) |
Yes |
Free (Hybrid) |
| Tagged PDF structure extraction |
Yes |
Free |
| AI safety (prompt injection filtering) |
Yes |
Free |
| Header/footer/watermark filtering |
Yes |
Free |
| Accessibility |
|
|
| Auto-tagging → Tagged PDF for untagged PDFs |
Yes |
Free (Apache 2.0) |
| PDF/UA-1, PDF/UA-2 export |
💼 Available |
Enterprise |
| Accessibility studio (visual editor) |
💼 Available |
Enterprise |
| Limitations |
|
|
| Process Word/Excel/PPT |
No |
— |
| GPU required |
No |
— |
opendataloader-pdf [hybrid] ranks #1 overall (0.907) across reading order, table, and heading extraction accuracy.
| Engine |
Overall |
Reading Order |
Table |
Heading |
Speed (s/page) |
License |
| opendataloader [hybrid] |
0.907 |
0.934 |
0.928 |
0.821 |
0.463 |
Apache-2.0 |
| nutrient |
0.885 |
0.925 |
0.708 |
0.819 |
0.008 |
Commercial |
| docling |
0.882 |
0.898 |
0.887 |
0.824 |
0.762 |
MIT |
| marker |
0.861 |
0.890 |
0.808 |
0.796 |
53.932 |
GPL-3.0 |
| unstructured [hi_res] |
0.841 |
0.904 |
0.588 |
0.749 |
3.008 |
Apache-2.0 |
| edgeparse |
0.837 |
0.894 |
0.717 |
0.706 |
0.036 |
Apache-2.0 |
| opendataloader |
0.831 |
0.902 |
0.489 |
0.739 |
0.015 |
Apache-2.0 |
| mineru |
0.831 |
0.857 |
0.873 |
0.743 |
5.962 |
AGPL-3.0 |
| pymupdf4llm |
0.732 |
0.885 |
0.401 |
0.412 |
0.091 |
AGPL-3.0 |
| unstructured |
0.686 |
0.882 |
0.000 |
0.388 |
0.077 |
Apache-2.0 |
| markitdown |
0.589 |
0.844 |
0.273 |
0.000 |
0.114 |
MIT |
| liteparse |
0.576 |
0.866 |
0.000 |
0.000 |
1.061 |
Apache-2.0 |
Scores normalized to [0, 1]. Higher is better for accuracy; lower is better for speed. Bold = best. Full benchmark details


Which Mode Should I Use?
| Your Document |
Mode |
Install |
Server Command |
Client Command |
| Standard digital PDF |
Fast (default) |
pip install opendataloader-pdf |
None needed |
opendataloader-pdf file1.pdf file2.pdf folder/ |
| Complex or nested tables |
Hybrid |
pip install "opendataloader-pdf[hybrid]" |
opendataloader-pdf-hybrid --port 5002 |
opendataloader-pdf --hybrid docling-fast file1.pdf file2.pdf folder/ |
| Scanned / image-based PDF |
Hybrid + OCR |
pip install "opendataloader-pdf[hybrid]" |
opendataloader-pdf-hybrid --port 5002 --force-ocr |
opendataloader-pdf --hybrid docling-fast file1.pdf file2.pdf folder/ |
| Non-English scanned PDF |
Hybrid + OCR |
pip install "opendataloader-pdf[hybrid]" |
opendataloader-pdf-hybrid --port 5002 --force-ocr --ocr-lang "ko,en" |
opendataloader-pdf --hybrid docling-fast file1.pdf file2.pdf folder/ |
| Mathematical formulas |
Hybrid + formula |
pip install "opendataloader-pdf[hybrid]" |
opendataloader-pdf-hybrid --enrich-formula |
opendataloader-pdf --hybrid docling-fast --hybrid-mode full file1.pdf file2.pdf folder/ |
| Charts needing description |
Hybrid + picture |
pip install "opendataloader-pdf[hybrid]" |
opendataloader-pdf-hybrid --enrich-picture-description |
opendataloader-pdf --hybrid docling-fast --hybrid-mode full file1.pdf file2.pdf folder/ |
| Nested sections for RAG chunking |
Hybrid + heading levels |
pip install "opendataloader-pdf[hybrid]" |
opendataloader-pdf-hybrid --port 5002 --heading-hierarchy |
opendataloader-pdf --hybrid docling-fast file1.pdf file2.pdf folder/ |
| Untagged PDFs needing accessibility |
Auto-tagging → Tagged PDF |
pip install opendataloader-pdf |
None needed |
opendataloader-pdf --format tagged-pdf file1.pdf file2.pdf folder/ |
Quick Start
Python
pip install -U opendataloader-pdf
import opendataloader_pdf

# Batch all files in one call — each convert() spawns a JVM process, so repeated calls are slow
opendataloader_pdf.convert(
    input_path=["file1.pdf", "file2.pdf", "folder/"],
    output_dir="output/",
    format="markdown,json"
)
Node.js
npm install @opendataloader/pdf
import { convert } from '@opendataloader/pdf';

await convert(['file1.pdf', 'file2.pdf', 'folder/'], {
  outputDir: 'output/',
  format: 'markdown,json'
});
Java
<dependency>
  <groupId>org.opendataloader</groupId>
  <artifactId>opendataloader-pdf-core</artifactId>
</dependency>
Python Quick Start | Node.js Quick Start | Java Quick Start
Hybrid Mode: #1 Accuracy for Complex PDFs
Hybrid mode combines fast local Java processing with AI backends. Simple pages stay local (0.02s); complex pages route to AI for +90% table accuracy.
Don't combine with --use-struct-tree on tagged PDFs. --use-struct-tree takes precedence, so the hybrid backend is not called (a warning is logged). If you want the hybrid backend, drop --use-struct-tree.
pip install -U "opendataloader-pdf[hybrid]"
Terminal 1 — Start the backend server:
opendataloader-pdf-hybrid --port 5002
Terminal 2 — Process PDFs:
# Batch all files in one call — each invocation spawns a JVM process, so repeated calls are slow
opendataloader-pdf --hybrid docling-fast file1.pdf file2.pdf folder/
Python:
# Batch all files in one call — each convert() spawns a JVM process, so repeated calls are slow
opendataloader_pdf.convert(
    input_path=["file1.pdf", "file2.pdf", "folder/"],
    output_dir="output/",
    hybrid="docling-fast"
)
OCR for Scanned PDFs
Start the backend with --force-ocr for image-based PDFs with no selectable text:
opendataloader-pdf-hybrid --port 5002 --force-ocr
For non-English documents, specify the language:
opendataloader-pdf-hybrid --port 5002 --force-ocr --ocr-lang "ko,en"
Supported languages: en, ko, ja, ch_sim, ch_tra, de, fr, ar, and more.
Extract mathematical formulas as LaTeX from scientific PDFs:
# Server: enable formula enrichment
opendataloader-pdf-hybrid --enrich-formula

# Batch all files in one call — each invocation spawns a JVM process, so repeated calls are slow
opendataloader-pdf --hybrid docling-fast --hybrid-mode full file1.pdf file2.pdf folder/
Output in JSON:
{
  "type": "formula",
  "page number": 1,
  "bounding box": [226.2, 144.7, 377.1, 168.7],
  "content": "\\frac{f(x+h) - f(x)}{h}"
}
Note: Formula and picture description enrichments require --hybrid-mode full on the client side.
Chart & Image Description
Generate AI descriptions for charts and images — useful for RAG search and accessibility alt text:
# Server
opendataloader-pdf-hybrid --enrich-picture-description

# Batch all files in one call — each invocation spawns a JVM process, so repeated calls are slow
opendataloader-pdf --hybrid docling-fast --hybrid-mode full file1.pdf file2.pdf folder/
Output in JSON:
{
  "type": "picture",
  "page number": 1,
  "bounding box": [72.0, 400.0, 540.0, 650.0],
  "description": "A bar chart showing waste generation by region from 2016 to 2030..."
}
Uses SmolVLM (256M), a lightweight vision model. Custom prompts supported via --picture-description-prompt.
Heading Hierarchy
The layout model labels a region as a section header without a depth, so by default every
heading comes back at level 1 and subsections sit at the same depth as the document title.
Flat headings make it hard to tell a section title from a document title when chunking for RAG.
--heading-hierarchy infers the depth — from the PDF outline first, then section numbering
(1. → 1.1 → 1.1.1), then visual style:
# Server
opendataloader-pdf-hybrid --port 5002 --heading-hierarchy

# Client — no extra flag needed
opendataloader-pdf --hybrid docling-fast file1.pdf file2.pdf folder/
  # 3. Methodology
- # 3.1. Multi-Object Rectification Network
+ ## 3.1. Multi-Object Rectification Network
- # Abstract
+ ## Abstract
Numbering covers numbered sections; style is what pulls an unnumbered Abstract or
References out from under the document title.
Off by default, so existing output is unchanged. Levels are capped at H6.
Enterprise-grade AI document analysis via Hancom Data Loader — customer-customized models trained on your domain-specific documents. 30+ element types (tables, charts, formulas, captions, footnotes, etc.), VLM-based image/chart understanding, complex table extraction (merged cells, nested tables), SLA-backed OCR for scanned documents, and native HWP/HWPX support. Supports PDF, DOCX, XLSX, PPTX, HWP, PNG, JPG. Live demo
Hybrid Mode Guide
| Format |
Use Case |
| JSON |
Structured data with bounding boxes, semantic types |
| Markdown |
Clean text for LLM context, RAG chunks |
| HTML |
Web display with styling |
| Annotated PDF |
Visual debugging — see detected structures (sample) |
| Text |
Plain text extraction |
Combine formats: format="json,markdown"
JSON Output Example
{
  "type": "heading",
  "id": 42,
  "level": "Title",
  "page number": 1,
  "bounding box": [72.0, 700.0, 540.0, 730.0],
  "heading level": 1,
  "font": "Helvetica-Bold",
  "font size": 24.0,
  "text color": "[0.0]",
  "content": "Introduction"
}
| Field |
Description |
type |
Element type: heading, paragraph, table, list, image, caption, formula |
id |
Unique identifier for cross-referencing |
page number |
1-indexed page reference |
bounding box |
[left, bottom, right, top] in PDF points (72pt = 1 inch) |
heading level |
Heading depth (1+) |
content |
Extracted text |
Full JSON Schema
Advanced Features
Tagged PDF Support
When a PDF has structure tags, OpenDataLoader extracts the exact layout the author intended — no guessing, no heuristics. Headings, lists, tables, and reading order are preserved from the source.
Output quality depends on tag quality. Not all tagged PDFs are well-tagged. For PDFs with sparse or incorrect tags, the default heuristic mode or --hybrid docling-fast often produces better results.
--use-struct-tree takes precedence over --hybrid. If both are set on a tagged PDF, the structure tree is used and the hybrid backend is not called (a well-tagged PDF already carries reading order and structure). Drop --use-struct-tree if you want the hybrid backend instead.
# Batch all files in one call — each convert() spawns a JVM process, so repeated calls are slow
opendataloader_pdf.convert(
    input_path=["file1.pdf", "file2.pdf", "folder/"],
    output_dir="output/",
    use_struct_tree=True           # Use native PDF structure tags
)
Most PDF parsers ignore structure tags entirely. Learn more
AI Safety: Prompt Injection Protection
PDFs can contain hidden prompt injection attacks. OpenDataLoader automatically filters:
- Hidden text (transparent, zero-size fonts)
- Off-page content
- Suspicious invisible layers
To sanitize sensitive data (emails, URLs, phone numbers → placeholders), enable it explicitly:
# Batch all files in one call — each invocation spawns a JVM process, so repeated calls are slow
opendataloader-pdf file1.pdf file2.pdf folder/ --sanitize
AI Safety Guide
LangChain Integration
pip install -U langchain-opendataloader-pdf
from langchain_opendataloader_pdf import OpenDataLoaderPDFLoader

loader = OpenDataLoaderPDFLoader(
    file_path=["file1.pdf", "file2.pdf", "folder/"],
    format="text"
)
documents = loader.load()
LangChain Docs | GitHub | [

 An open-source PDF parser built for AI pipelines: it turns PDFs into Markdown, JSON (with bounding boxes) and HTML, and can auto-tag untagged PDFs into screen-reader-ready Tagged PDFs.