Headroom compresses everything your AI agent reads — tool outputs, logs, RAG
chunks, files, and conversation history — before it reaches the LLM. Same
answers, fraction of the tokens. Compression runs on your machine; no prompt or
file content is sent anywhere to be compressed.
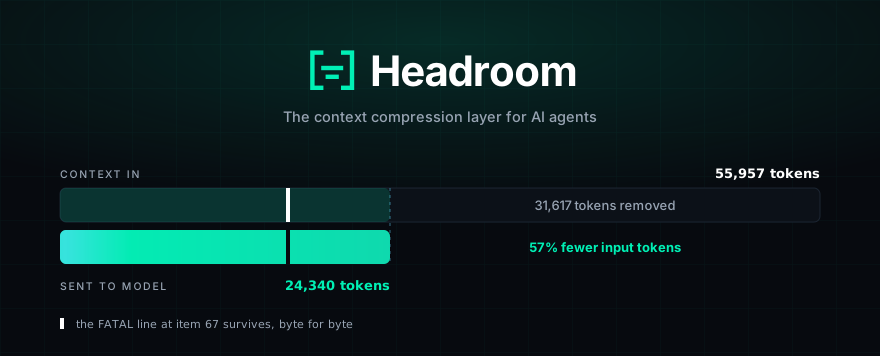
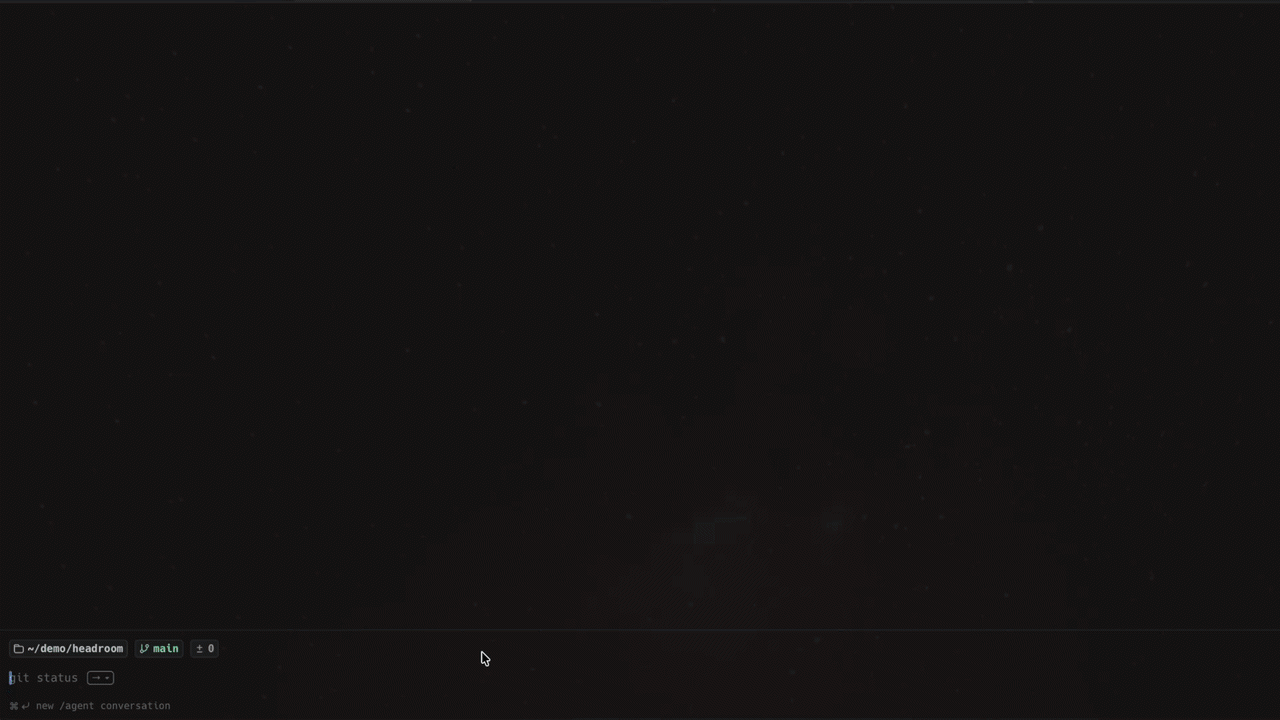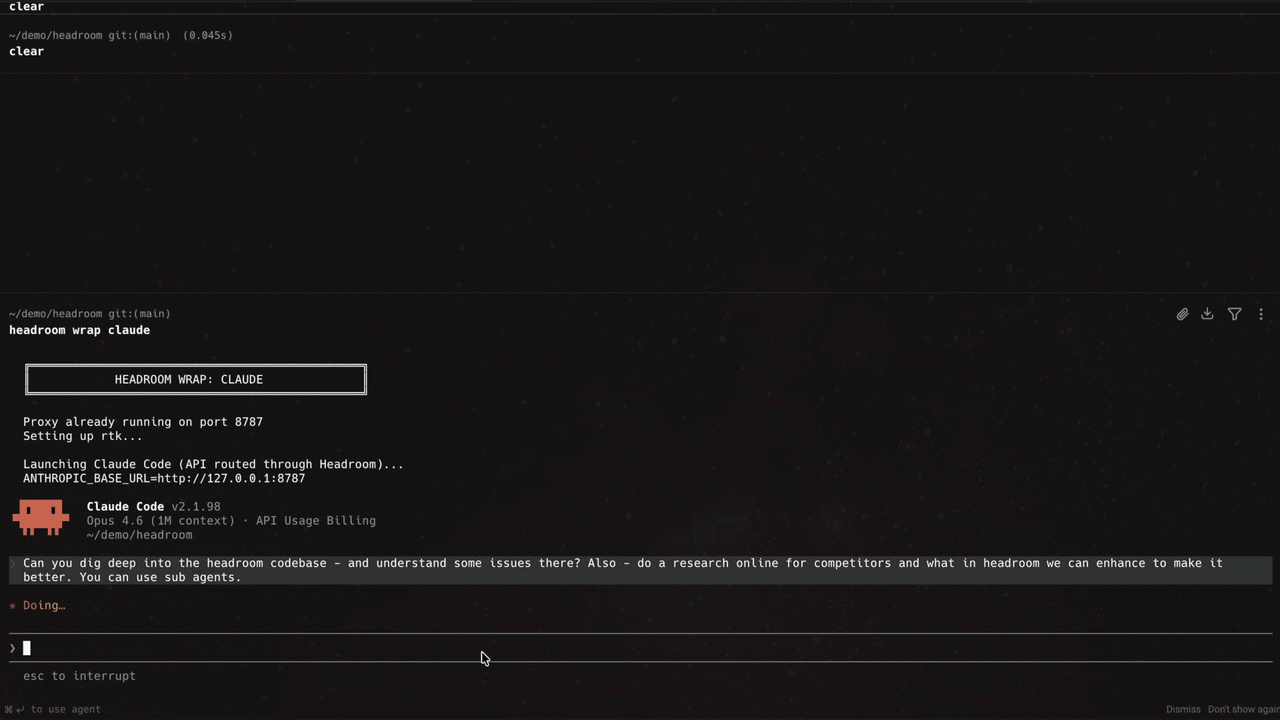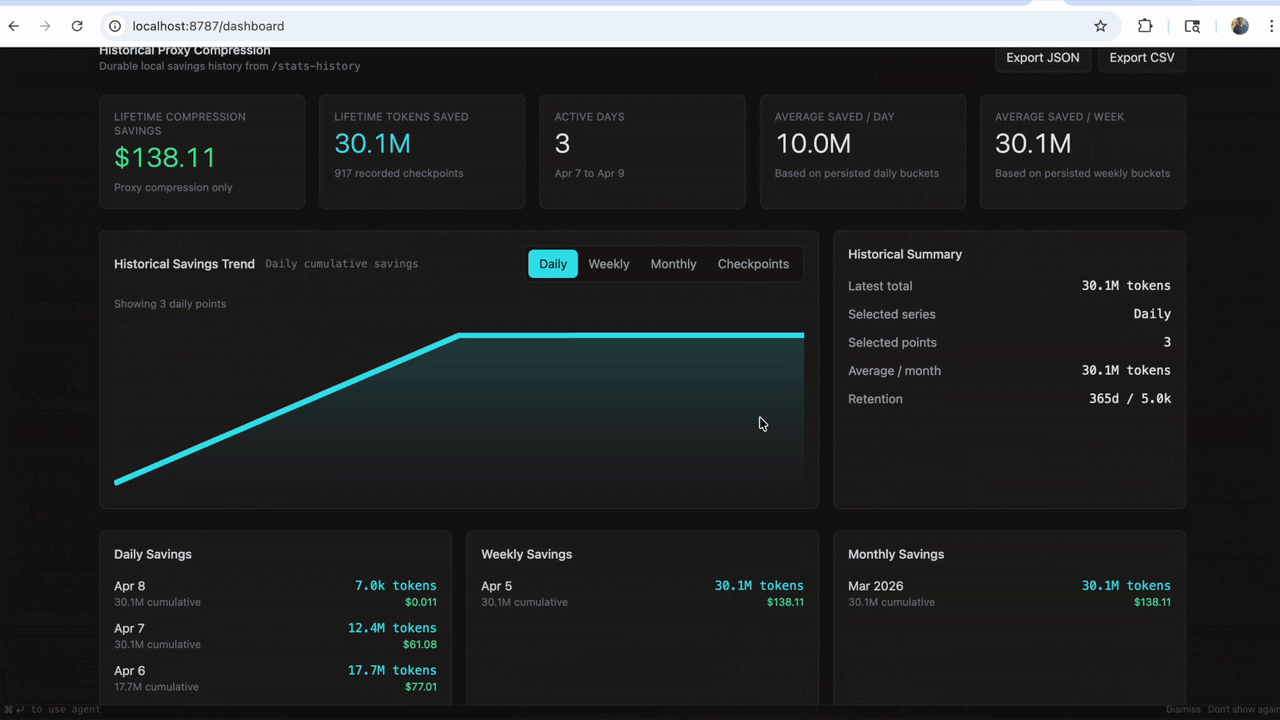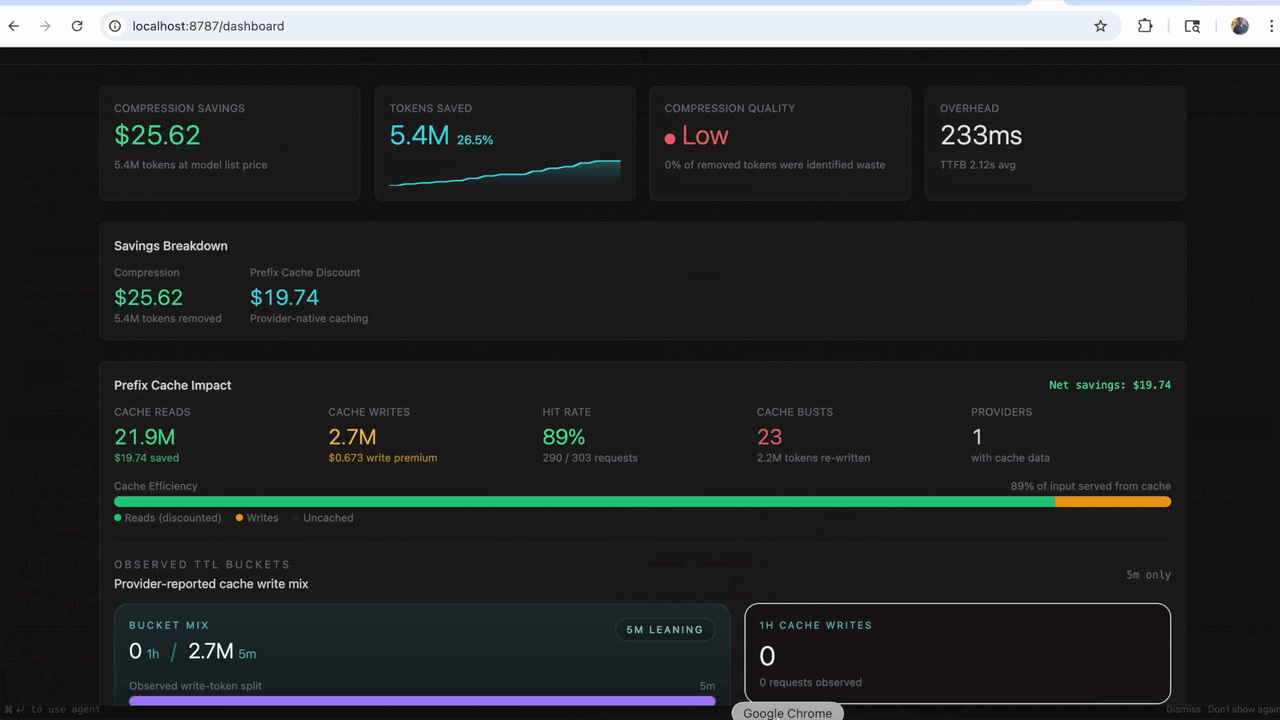 10,144 → 1,260 tokens. The same
FATAL found.
What it does
- Library —
compress(messages) in Python or TypeScript, inline in any app.
- Proxy —
headroom proxy --port 8787, zero code changes, any language.
- Agent wrap —
headroom wrap claude|codex|grok|copilot|cursor|aider|opencode|cline|continue|goose|openhands|openclaw|vibe|omp|zcode in one command; undo with headroom unwrap <tool>.
- MCP server —
headroom_compress, headroom_retrieve, headroom_stats for any MCP client.
- Cross-agent memory — one shared store across Claude, Codex, Gemini and Grok, with automatic dedup.
headroom learn — mines failed sessions and writes corrections to CLAUDE.local.md (default, gitignored), CLAUDE.md, AGENTS.md, GEMINI.md or GROK.md.- Output token reduction — trims what the model writes back, not only what you send. See below.
- Reversible (CCR) — originals are cached locally and retrieved on demand.
How it works
 Your agent / app
   (Claude Code, Cursor, Codex, LangChain, Agno, Strands, your own code…)
        │   prompts · tool outputs · logs · RAG results · files
        ▼
    ┌────────────────────────────────────────────────────┐
    │  Headroom   (runs locally — your data stays here)  │
    │  ────────────────────────────────────────────────  │
    │  CacheAligner  →  ContentRouter  →  CCR            │
    │                    ├─ SmartCrusher   (JSON)        │
    │                    ├─ CodeCompressor (AST)         │
    │                    └─ Kompress-v2-base (text, HF)  │
    │                                                    │
    │  Cross-agent memory  ·  headroom learn  ·  MCP     │
    └────────────────────────────────────────────────────┘
        │   compressed prompt  +  retrieval tool
        ▼
 LLM provider  (Anthropic · OpenAI · Bedrock · …)
- ContentRouter detects the content type and selects a compressor for it.
- SmartCrusher / CodeCompressor / Kompress-v2-base handle JSON, source code and prose respectively.
- CacheAligner flags volatile content that would bust a provider KV-cache prefix. It never rewrites prompts.
- CCR stores originals locally so the model can call
headroom_retrieve when it needs the full text.
→ Architecture ·
CCR ·
Kompress-v2-base model card
Get started (60 seconds)
# 1 — Install
uv tool install --python 3.13 "headroom-ai[all]"  # CLI in a self-contained env
pip install "headroom-ai[all]"                    # Python — ships the `headroom` CLI
npm install headroom-ai                           # TypeScript SDK only — no CLI

# 2 — Pick a mode
headroom deploy                         # turnkey local deployment + agent config
headroom wrap claude                    # wrap a coding agent
headroom proxy --port 8787              # drop-in proxy, zero code changes
# or: from headroom import compress     # inline library

# 3 — Check it and watch the savings
headroom doctor                         # health check — confirms routing works
headroom perf
headroom dashboard                      # live savings (proxy must be running)
Inline, in Python:
from headroom import compress
from openai import OpenAI

messages = [{"role": "user", "content": "Analyze these results"}]
result = compress(messages, model="gpt-4o")

client = OpenAI()
response = client.chat.completions.create(model="gpt-4o", messages=result.messages)
print(f"Saved {result.tokens_saved} tokens ({result.compression_ratio:.0%})")
Launch a wrapped agent session each time, so the setup runs. headroom wrap
starts a local proxy, installs Serena for
semantic code navigation, and launches the agent configured to route through
Headroom. Serena is registered at user scope (for Claude Code, in
~/.claude.json), so it stays available in your other projects until you run
headroom unwrap. Skip it with --code-memory none.
The headroom CLI ships only in the PyPI package. The npm headroom-ai package
is the TypeScript SDK — a library you import
(import { compress } from 'headroom-ai') — and provides no headroom command.
Proof
Four scenarios built from real MCP server output formats, measured with the
provider tokenizer and the shipped compress(). Seeded and offline, so you get
the same numbers we did:
uv run python benchmarks/index_proof_table.py --seed 20260902
| Scenario |
Before |
After |
Saved |
| Code search (100 results) |
17,199 |
13,597 |
21% |
| SRE incident debugging |
55,957 |
24,340 |
57% |
| Codebase exploration |
58,801 |
33,895 |
42% |
| GitHub issue triage |
46,067 |
32,429 |
30% |
Savings scale with how repetitive the payload is. Repeated JSON arrays and log
lines clear 90% in benchmarks/bench_latency.py; prose and already-dense output
compress very little. Run headroom savings against your own traffic for the
number that applies to you.
Compression costs well under a millisecond — 0.21 ms p50 on a 10K-token JSON
search result, 1.4 ms at 100K tokens — so it does not show up in agent latency.
Accuracy. python -m headroom.evals suite --tier 1:
| Benchmark |
Category |
N |
Baseline |
Headroom |
Delta |
| GSM8K |
Math |
100 |
0.870 |
0.870 |
±0.000 |
| TruthfulQA |
Factual |
100 |
0.530 |
0.560 |
+0.030 |
| SQuAD v2 |
QA |
100 |
— |
97% |
at 19% compression |
| BFCL |
Tools |
100 |
— |
97% |
at 32% compression |
At N=100 a delta of ±0.03 falls inside the confidence interval, so TruthfulQA
shows no detectable difference rather than an improvement.
Methodology →
Output token reduction
Everything above shrinks the prompt you send. You also pay for every token
the model writes back, and on Opus-class models output costs 5× input. Much
of that output is ceremony: "Great, let me…" preambles, code re-printed straight
back at you, and deep reasoning spent on routine steps like reading a file.
Headroom trims it from the proxy, with no change to your code:
- Verbosity steering appends a short "be terse, don't restate context" note to the end of the system prompt, so your prompt cache still hits.
- Effort routing dials thinking effort down when a turn is only the model resuming after a tool result — a file read, a passing test. New questions and errors keep full effort.
Both apply to Anthropic /v1/messages and to OpenAI-compatible
/v1/chat/completions and /v1/responses. Effort routing uses
reasoning_effort on OpenAI and thinking.budget_tokens / output_config.effort
on Anthropic, with the same clamp-only invariant and the same output_shaper:*
labels on both paths.
export HEADROOM_OUTPUT_SHAPER=1     # off by default
headroom proxy --port 8787
Already running a proxy? These switches are read live on every request, so
a proxy that headroom wrap reused rather than started would not see a value
you export afterwards — its environment was snapshotted at launch. headroom wrap hot-syncs your current settings to the running proxy over a loopback
POST /admin/runtime-env, so they take effect with no restart and no dropped
requests. On a shared proxy these overrides are global; the last explicit
setting wins.
Terseness you didn't have to configure. People rarely state how terse they
want answers — they show it, by interrupting long replies or moving on before
they could have read them. headroom learn --verbosity reads past sessions and
picks the level:
headroom learn --verbosity            # dry run — preview what it found
headroom learn --verbosity --apply    # save it; the proxy picks it up
Measuring it. Output savings are counterfactual — we never see what the model
would have written — so Headroom reports an estimate with a confidence range
and labels it as one:
headroom output-savings
# Reduction: 31.7%  (95% CI 27.7% … 35.7%)   [estimated]
For a measured number instead, hold out 10% of conversations as an unshaped
control: export HEADROOM_OUTPUT_HOLDOUT=0.1. The dashboard's Output Tokens
Saved card then reads measured rather than estimated, with the band.
→ Output token reduction
Agent compatibility
| Agent |
headroom wrap |
Notes |
| Claude Code |
✅ |
--memory · --code-graph · --1m · --tool-search |
| Codex |
✅ |
shares memory with Claude |
| Grok CLI |
✅ |
routes via GROK_MODELS_BASE_URL |
| Cursor |
Manual setup |
starts the proxy and prints base URLs for Cursor settings |
| Aider |
✅ |
starts proxy + launches |
| Copilot CLI |
✅ |
starts proxy + launches |
| VS Code Copilot |
✅ |
transparent proxy; keeps the selected model |
| OpenClaw |
✅ |
installs as a ContextEngine plugin |
| OpenCode |
✅ |
injects config · starts proxy + launches |
| Cline |
✅ |
starts proxy + injects config |
| Continue |
✅ |
starts proxy + injects config |
| Goose |
✅ |
starts proxy + launches |
| OpenHands |
✅ |
starts proxy + launches |
| Mistral Vibe |
✅ |
starts proxy + launches |
| Oh My Pi |
✅ |
injects config · starts proxy + launches |
| Cortex Code |
Library only |
60–65% savings in library mode; no wrap |
| Kimi CLI |
✅ |
OAuth bearer forwarded — log in once |
| ZCode |
✅ |
starts the proxy and prints base URLs for ZCode settings |
Any OpenAI-compatible client works through headroom proxy. MCP-native clients:
headroom mcp install. Undo durable wrapping with headroom unwrap <tool>
(claude, copilot, codex, grok, kimi, omp, opencode, openclaw,
zcode). Registry authors should use the canonical server.json
rather than reconstructing the headroom mcp serve contract from prose.
GitHub Copilot CLI subscription mode
Headroom can route Copilot CLI subscription traffic through the local proxy:
headroom copilot-auth login
headroom wrap copilot --subscription -- --model gpt-4o
The wrapper exchanges Headroom's reusable GitHub OAuth token for Copilot's
short-lived API token and prints the upstream endpoint as
COPILOT_PROVIDER_API_URL=... at launch. headroom copilot-auth login stores a
Headroom-specific Copilot OAuth token, rather than relying on generic GitHub or
Copilot CLI tokens that can read account metadata but are still rejected by
Copilot's token-exchange endpoint.
For GitHub Enterprise Server or a custom-domain Copilot deployment, set one of
these before launching. If both are set, the URL wins:
export GITHUB_COPILOT_ENTERPRISE_DOMAIN=ghe.example.com
export GITHUB_COPILOT_ENTERPRISE_URL=https://ghe.example.com
For GitHub.com Enterprise Cloud URLs such as
github.com/enterprises/your-enterprise, set neither — Headroom uses GitHub's
normal token-exchange endpoint and the Copilot API endpoint advertised for the
signed-in account.
Platform support. macOS auth reuse through Copilot CLI Keychain storage and
Windows device authentication are live-tested. Copilot CLI 1.0.81 does not expose
its Windows login through the legacy Credential Manager schema Headroom reads, so
run headroom copilot-auth login on Windows. Linux Secret Service /
secret-tool reuse is implemented but not yet validated on a real desktop. In
Docker and CI, pass an explicit GITHUB_COPILOT_TOKEN or
GITHUB_COPILOT_GITHUB_TOKEN instead of relying on host keychain access.
GitHub Copilot in VS Code
Headroom overrides Copilot's API proxy endpoint, so the VS Code model picker
stays authoritative. GPT-5.5, GPT-5.6 Luna/Sol/Terra, Claude Sonnet/Opus and
other Copilot models keep their original model IDs while traffic passes through
the local compression proxy. Headroom does not patch VS Code or change Codex
settings.
headroom copilot-auth login
headroom wrap vscode
Keep the command running and use Copilot normally. The short-lived upstream
Copilot token is held only in the proxy process.
Full guide →
Claude Code in VS Code
The official Claude Code extension embeds Claude Code and reads the same user
settings as the CLI. Install the proxy extra, then run the wrapper from the
project you will open in VS Code:
pip install "headroom-ai[proxy]"
headroom wrap vscode-claude
Reload the VS Code window on first run. Keep the wrapper terminal running while
you use the Claude Code panel; the dashboard or proxy log printed at startup
shows requests and savings. Your Anthropic authentication and selected model are
preserved. Ctrl+C stops the proxy; headroom unwrap vscode-claude restores the
settings that existed before setup.
Full guide →
When to use · when to skip
Good fit if you run coding agents daily and want savings without touching
your code, work across several agents and want one shared memory, or need
compression that is reversible — originals stay retrievable through CCR for the
configured TTL.
Skip it if you only use one provider's native compaction and don't need
cross-agent memory, or work in a sandbox where local processes can't run.
Headroom pays off on long agent sessions with heavy tool output. Short
conversational exchanges, prose, and already-dense payloads see little or no
reduction, and blocks under min_input_words come back byte-identical.
Limitations has the full list.
Integrations — drop Headroom into any stack
| Your setup |
Hook in with |
| Any Python app |
compress(messages, model=…) |
| Any TypeScript app |
await compress(messages, { model }) |
| Anthropic / OpenAI SDK |
withHeadroom(new Anthropic()) · withHeadroom(new OpenAI()) |
| Vercel AI SDK |
wrapLanguageModel({ model, middleware: headroomMiddleware() }) |
| LiteLLM |
litellm.callbacks = [HeadroomCallback()] |
| LangChain |
HeadroomChatModel(your_llm) |
| Agno |
HeadroomAgnoModel(your_model) |
| Strands |
Strands guide |
| ASGI apps |
app.add_middleware(CompressionMiddleware) |
| Multi-agent |
SharedContext().put / .get |
| MCP clients |
headroom mcp install |
What's inside
- SmartCrusher — universal JSON: arrays of dicts, nested objects, mixed types. It keeps error items, values outside the normal statistical range, and first/last boundaries, selected from field-variance statistics rather than a keyword list.
- CodeCompressor — AST-aware for Python, JS/TS, Go, Rust, Java, C/C++ and Perl.
- Kompress-v2-base — our HuggingFace model, trained on agentic traces.
- Image compression — 40–90% reduction through a trained ML router.
- CacheAligner — flags volatile content that would bust a provider KV-cache prefix; never rewrites prompts.
- Live-zone compression — only new bytes are compressed (fresh tool output, the latest turn). The frozen prefix stays byte-identical, so the provider cache survives, and history is never dropped.
- CCR — reversible compression; the model retrieves originals on demand.
- Cross-agent memory — shared store with agent provenance and auto-dedup.
- SharedContext — compressed context passing across multi-agent workflows.
headroom learn — plugin-based failure mining for Claude, Codex and Gemini.
Pipeline internals
One request lifecycle is shared by compress(), the SDKs and the proxy:
Setup → Pre-Start → Post-Start → Input Received → Input Cached →
Input Routed → Input Compressed → Input Remembered → Pre-Send →
Post-Send → Response Received
- Transforms do the work: CacheAligner → ContentRouter → SmartCrusher / CodeCompressor / Kompress-base, live-zone only. IntelligentContext and RollingWindow were retired in PR-B1.
- Pipeline extensions observe or customise lifecycle stages through
on_pipeline_event(...).
- Compression hooks sit alongside the lifecycle as an additional extension seam.
- Proxy extensions are the integration seam for ASGI middleware, routes and startup policy.
Provider- and tool-specific behaviour lives under headroom/providers/, so core




 Headroom compresses everything an AI agent reads - tool outputs, logs, RAG chunks, files, and conversation history - before it reaches the LLM, cutting tokens while keeping the same answers. It ships as a library, a local proxy, and an MCP server.