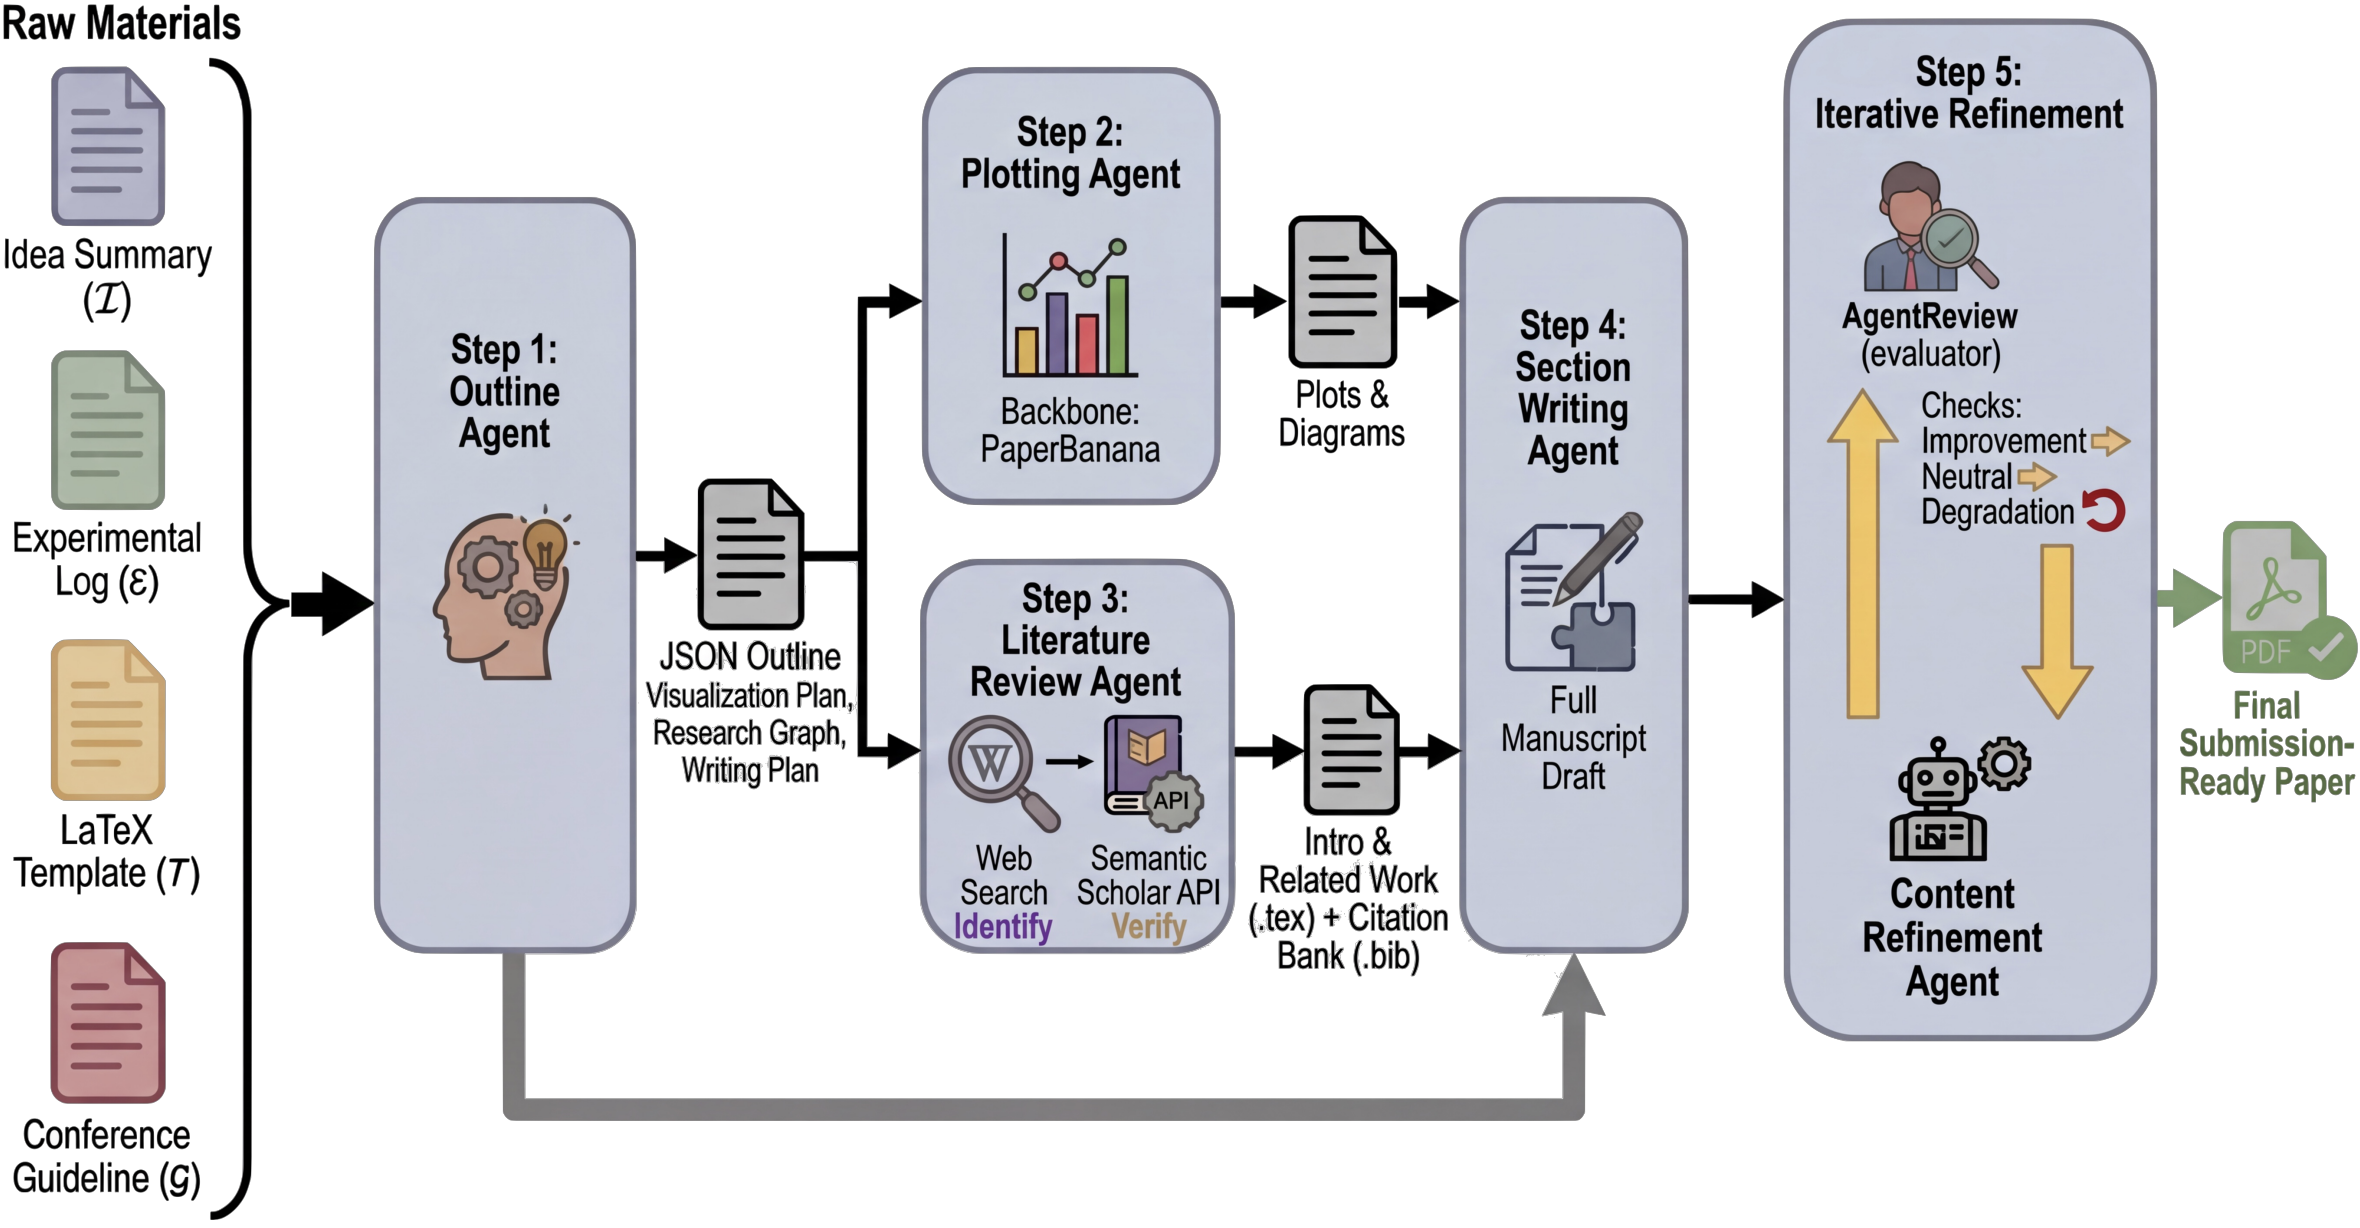
Что это?
 PaperOrchestra — это фреймворк с несколькими агентами, который превращает ваши сырые исследовательские материалы (идеи и журналы экспериментов) в готовую к подаче статью в LaTeX, включая обзор литературы и сгенерированные графики.
Это готовая статья или инструмент, который её пишет?Это инструмент. Команда специализированных агентов (план, обзор литературы, написание разделов, доработка, построение графиков) работает с вашими материалами и создаёт черновик.
Это инструмент. Команда специализированных агентов (план, обзор литературы, написание разделов, доработка, построение графиков) работает с вашими материалами и создаёт черновик.Как это запустить?Создайте среду Conda с именем paperorchestra и Python 3.11, установите зависимости, добавьте ваши API-ключи в файл .env в корне проекта, а затем запустите bash-скрипт или Python CLI, указав папку с сырыми материалами и папку с шаблоном LaTeX.
Создайте среду Conda с именем paperorchestra и Python 3.11, установите зависимости, добавьте ваши API-ключи в файл .env в корне проекта, а затем запустите bash-скрипт или Python CLI, указав папку с сырыми материалами и папку с шаблоном LaTeX.Что нужно до начала работы?Conda, Python 3.11 и API-ключи провайдеров LLM, которыми вы пользуетесь, сохранённые в файле .env.
Conda, Python 3.11 и API-ключи провайдеров LLM, которыми вы пользуетесь, сохранённые в файле .env.Входит ли в репозиторий набор данных?Нет. Набор данных для генерации статей не входит в этот репозиторий и будет опубликован отдельно позже. Когда он станет доступен, его нужно будет поместить в каталог datasets/.
Нет. Набор данных для генерации статей не входит в этот репозиторий и будет опубликован отдельно позже. Когда он станет доступен, его нужно будет поместить в каталог datasets/.Есть ли визуальный интерфейс, а не только CLI?Да, есть интерактивная демо-версия конвейера на Streamlit. Инструкции по запуску находятся в README в каталоге frontend.
Да, есть интерактивная демо-версия конвейера на Streamlit. Инструкции по запуску находятся в README в каталоге frontend.Есть ли способ оценить результат?Да, папка autoraters/ содержит скрипты для автоматической оценки сгенерированных статей.
Да, папка autoraters/ содержит скрипты для автоматической оценки сгенерированных статей.Это официальный продукт Google?Авторы из Google Cloud AI Research, однако в README указано, что это не официально поддерживаемый продукт Google.
Авторы из Google Cloud AI Research, однако в README указано, что это не официально поддерживаемый продукт Google.Какие есть похожие проекты?modex-mh-agent, claude-scholar, hive, PaperBanana, adk-python, DeLM, cumcm-step-review, SwarmLab
modex-mh-agent, claude-scholar, hive, PaperBanana, adk-python, DeLM, cumcm-step-review, SwarmLabВ каких он темах?research-assistant, paper-writing, streamlit, academic-writing, latex, multi-agent-systems, google, academic-research, agent-orchestration, agents, automation, apache-2.0
research-assistant, paper-writing, streamlit, academic-writing, latex, multi-agent-systems, google, academic-research, agent-orchestration, agents, automation, apache-2.0