What is this?
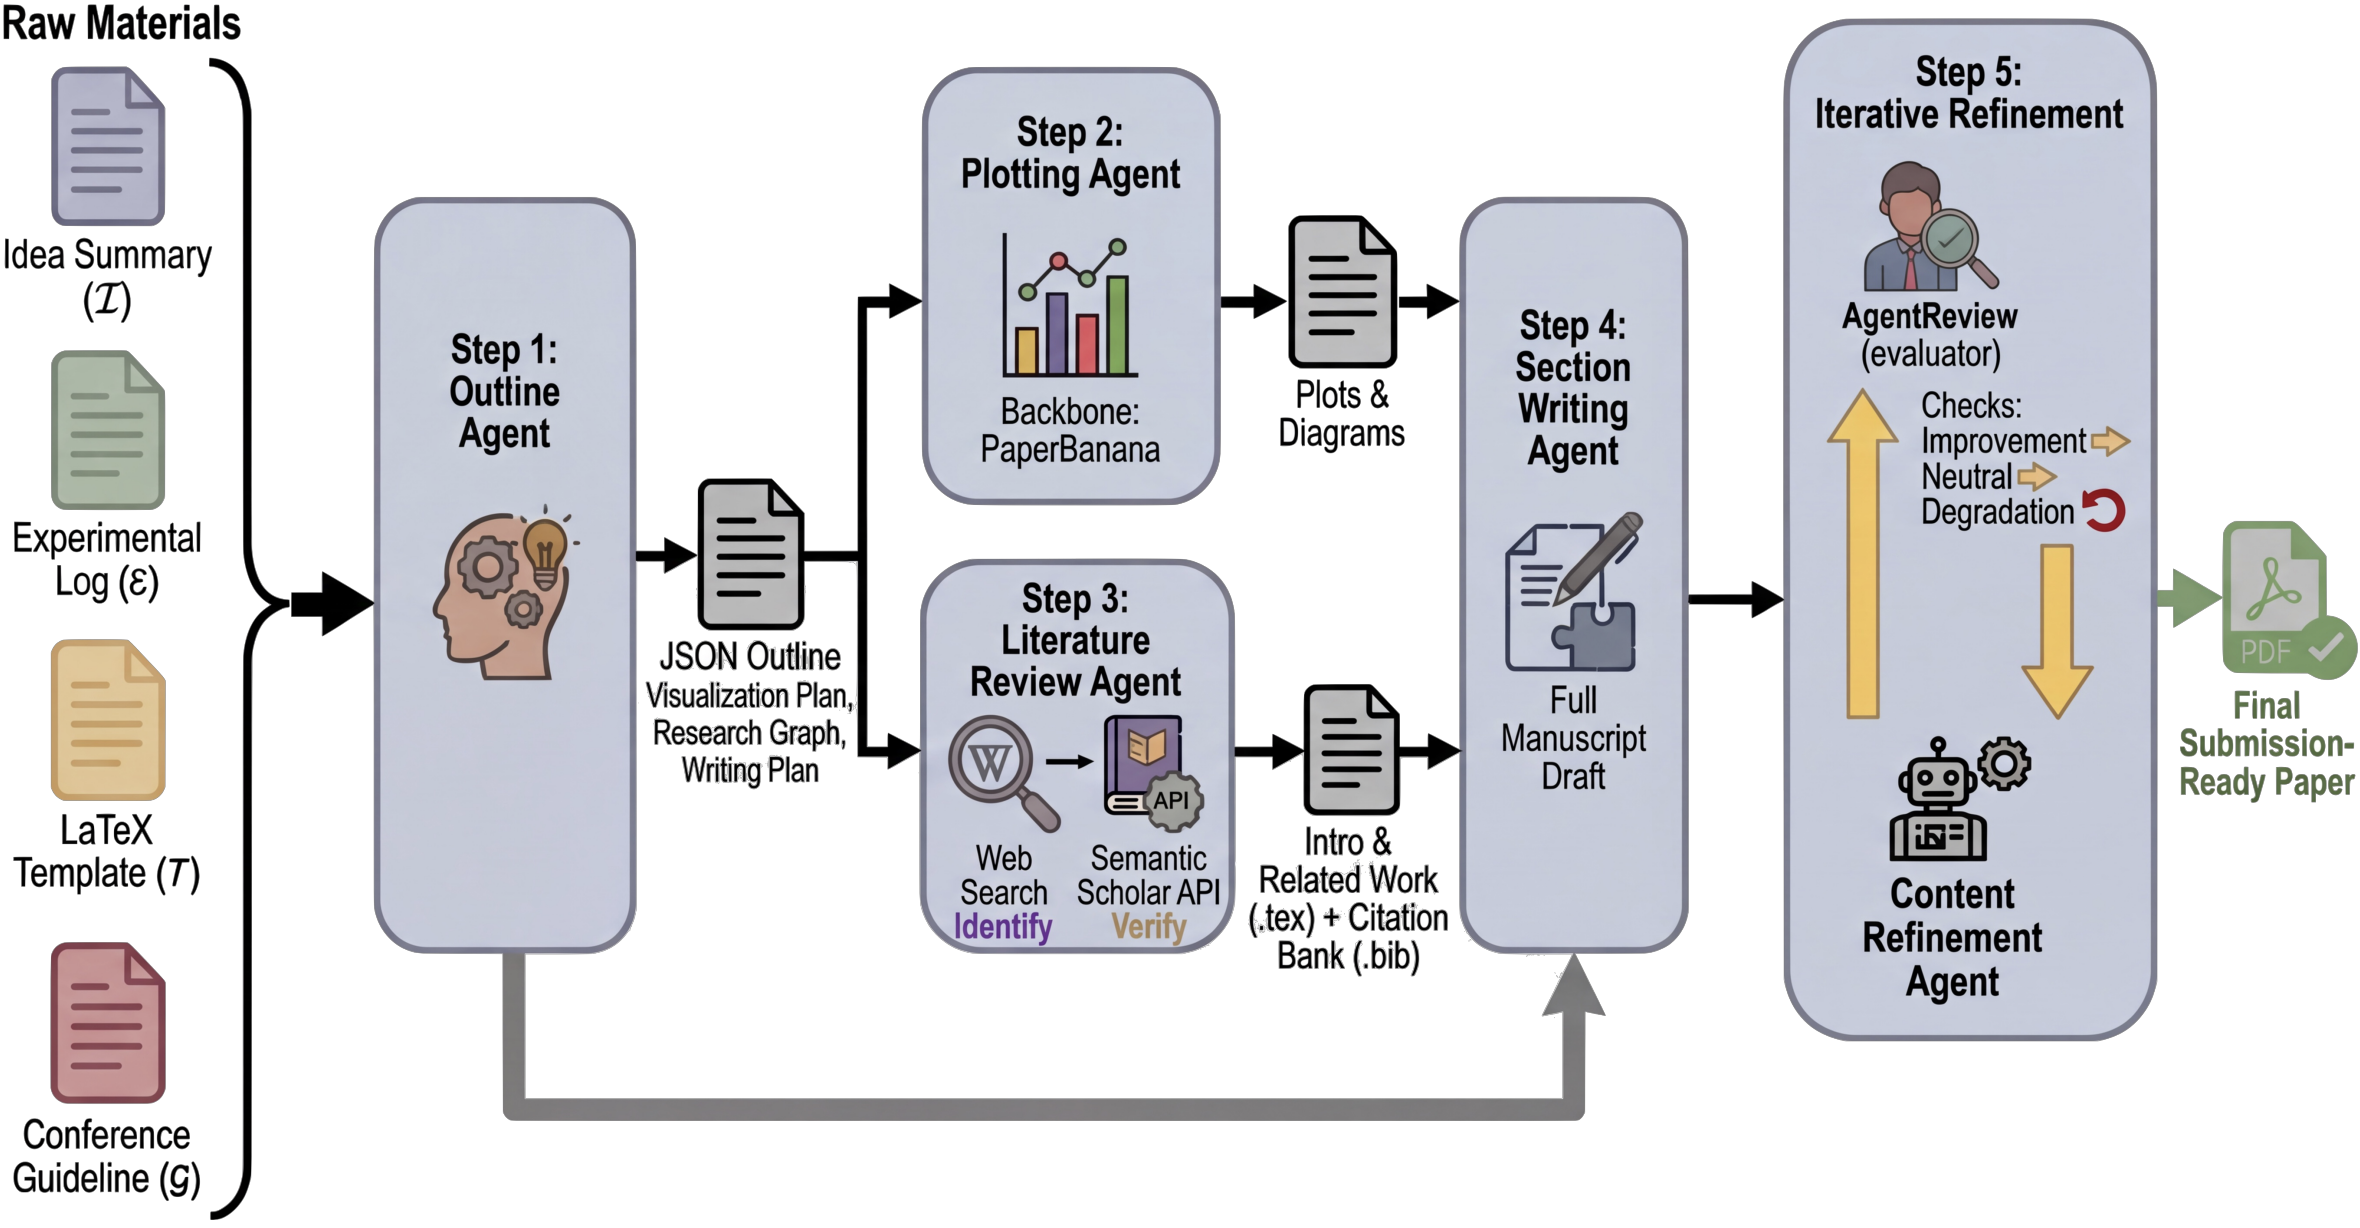
 PaperOrchestra is a multi-agent framework that turns your raw research materials (ideas and experiment logs) into a submission-ready LaTeX paper, including literature synthesis and generated figures.
Is it a finished paper or a tool that writes one?It is a tool. A team of specialized agents (outline, literature review, section writing, refinement, plotting) runs on your own materials and produces the draft.
It is a tool. A team of specialized agents (outline, literature review, section writing, refinement, plotting) runs on your own materials and produces the draft.How do I get it running?Create a Conda env named paperorchestra with Python 3.11 and install the dependencies, add your API keys to a .env file in the project root, then run the bash script or the Python CLI with the raw materials dir and the LaTeX template dir.
Create a Conda env named paperorchestra with Python 3.11 and install the dependencies, add your API keys to a .env file in the project root, then run the bash script or the Python CLI with the raw materials dir and the LaTeX template dir.What do I need before starting?Conda, Python 3.11, and API keys for the LLM providers you use, stored in the .env file.
Conda, Python 3.11, and API keys for the LLM providers you use, stored in the .env file.Does the repo include the dataset?No. The dataset used for paper generation is not in this repository and will be released separately later. You would place it under the datasets/ directory once it is available.
No. The dataset used for paper generation is not in this repository and will be released separately later. You would place it under the datasets/ directory once it is available.Is there a visual interface, not just the CLI?Yes, there is an interactive Streamlit demo of the pipeline. Its run instructions are in the README inside the frontend directory.
Yes, there is an interactive Streamlit demo of the pipeline. Its run instructions are in the README inside the frontend directory.Does it include a way to evaluate the output?Yes, the autoraters/ folder contains scripts for automated evaluation of the generated papers.
Yes, the autoraters/ folder contains scripts for automated evaluation of the generated papers.Is it an official Google product?The authors are from Google Cloud AI Research, but the README states it is not an officially supported Google product.
The authors are from Google Cloud AI Research, but the README states it is not an officially supported Google product.What are similar projects?modex-mh-agent, claude-scholar, hive, PaperBanana, adk-python, DeLM, cumcm-step-review, SwarmLab
modex-mh-agent, claude-scholar, hive, PaperBanana, adk-python, DeLM, cumcm-step-review, SwarmLabWhich topics is it in?research-assistant, paper-writing, streamlit, academic-writing, latex, multi-agent-systems, google, academic-research, agent-orchestration, agents, automation, apache-2.0
research-assistant, paper-writing, streamlit, academic-writing, latex, multi-agent-systems, google, academic-research, agent-orchestration, agents, automation, apache-2.0