



What is this?
 Dagster is a cloud-native data pipeline orchestrator covering the whole development lifecycle: it builds, runs, and observes data assets like tables, datasets, ML models, and reports, with built-in lineage and observability.
Is it a code framework or a service I run?Both: you declare data assets as Python functions, Dagster runs them at the right time, keeps them up to date, and shows the asset graph in a web UI.
Both: you declare data assets as Python functions, Dagster runs them at the right time, keeps them up to date, and shows the asset graph in a web UI.How do I get it running?Install it from PyPI with pip install dagster; it officially supports Python 3.9 through 3.14, and the docs include a quickstart guide plus a hands-on tutorial.
Install it from PyPI with pip install dagster; it officially supports Python 3.9 through 3.14, and the docs include a quickstart guide plus a hands-on tutorial.Does it plug into the data tools I already use?Yes — Dagster ships a growing library of integrations for popular data tools, and you deploy it to your own infrastructure.
Yes — Dagster ships a growing library of integrations for popular data tools, and you deploy it to your own infrastructure.Is it production-ready or mainly for local experimentation?It's built for the entire lifecycle — local development, unit tests, integration tests, staging environments, all the way up to production.
It's built for the entire lifecycle — local development, unit tests, integration tests, staging environments, all the way up to production.What kind of data work is it built for?Developing and maintaining data assets — tables, datasets, machine learning models, and reports — so it targets data engineering, analytics, and MLOps work.
Developing and maintaining data assets — tables, datasets, machine learning models, and reports — so it targets data engineering, analytics, and MLOps work.Do I have to pay for it?No — Dagster is open source under the Apache 2.0 license.
No — Dagster is open source under the Apache 2.0 license.What does the code look like?You define data assets as ordinary Python functions; the README shows a graph of three assets defined in Python, and that same graph loads straight into Dagster's web UI for visualization.
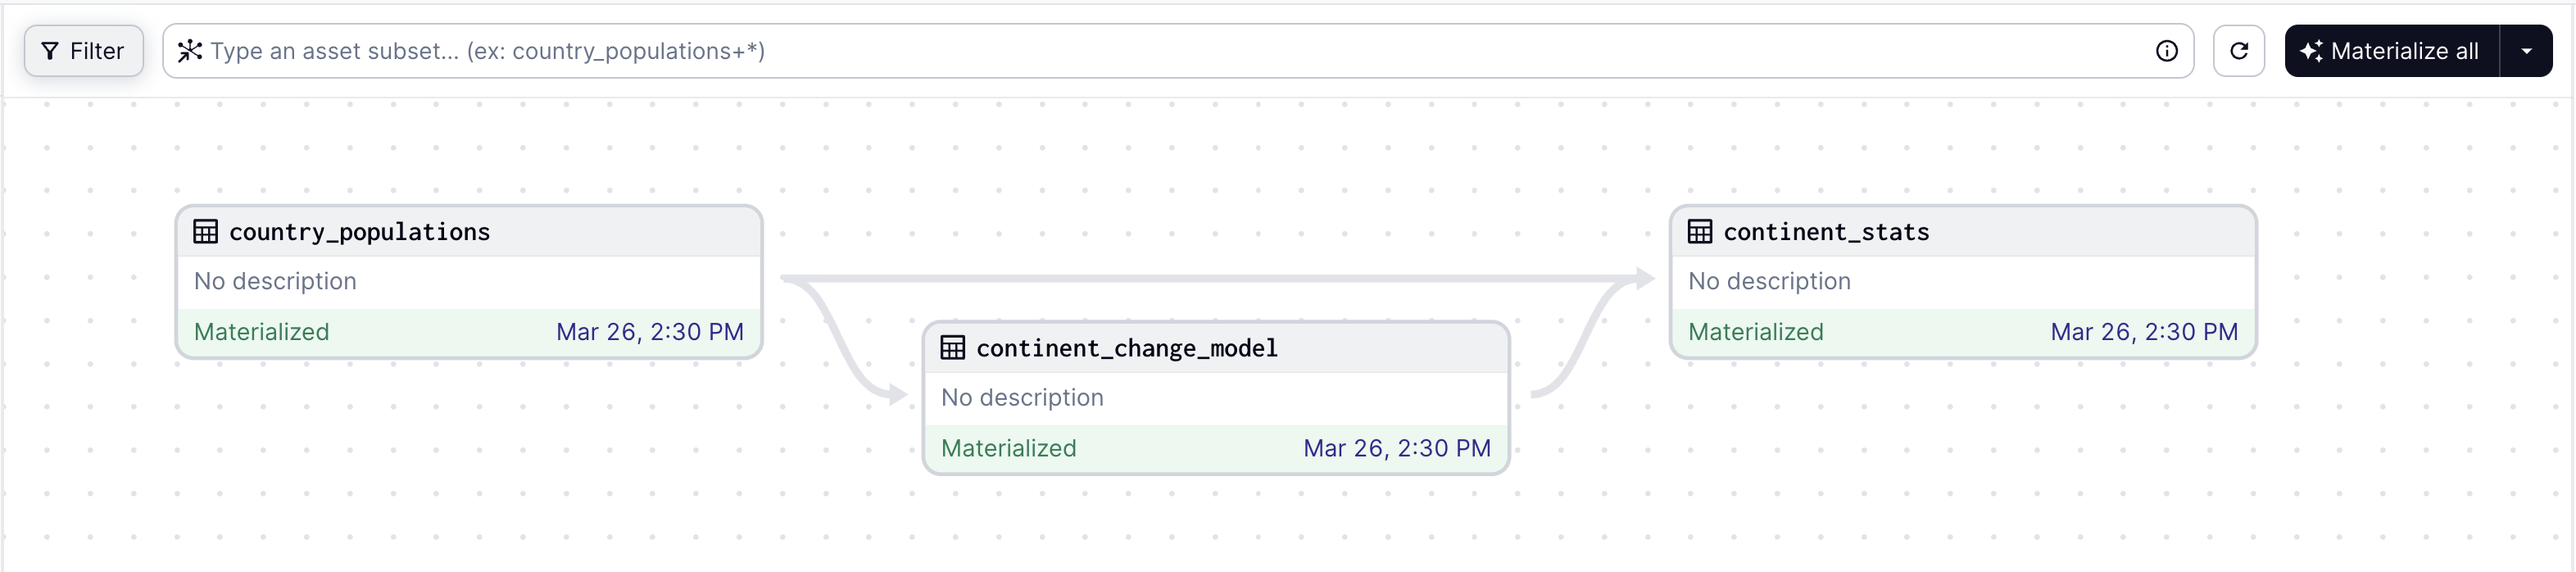
You define data assets as ordinary Python functions; the README shows a graph of three assets defined in Python, and that same graph loads straight into Dagster's web UI for visualization.How do I keep track of pipeline health?Dagster acts as a unified control plane: metadata is centralized in one tool with built-in observability, diagnostics, cataloging, and lineage, so you can spot issues and find performance improvements as complexity scales.
Dagster acts as a unified control plane: metadata is centralized in one tool with built-in observability, diagnostics, cataloging, and lineage, so you can spot issues and find performance improvements as complexity scales.Can it scale beyond one person's scripts?Yes — the orchestration engine is multi-tenant and multi-tool, built to scale both technically and organizationally, with reusable components and CI/CD practices encouraged from the start.
Yes — the orchestration engine is multi-tenant and multi-tool, built to scale both technically and organizationally, with reusable components and CI/CD practices encouraged from the start.Where should someone new begin?The README points to the documentation and a hands-on tutorial; the quickstart guide is the fastest route to a first running pipeline.
The README points to the documentation and a hands-on tutorial; the quickstart guide is the fastest route to a first running pipeline.What are similar projects?airflow, kestra, taipy, prefect, dolphinscheduler, full-stack-data-engineering, kedro, OpenMetadata
airflow, kestra, taipy, prefect, dolphinscheduler, full-stack-data-engineering, kedro, OpenMetadataWhich topics is it in?data-integration, data-pipelines, etl, metadata, mlops, scheduler, data-engineering, cloud-native, analytics, workflow, workflow-automation, orchestration
data-integration, data-pipelines, etl, metadata, mlops, scheduler, data-engineering, cloud-native, analytics, workflow, workflow-automation, orchestration