DeepEval is a simple-to-use, open-source LLM evaluation framework, for evaluating large-language model systems. It is similar to Pytest but specialized for unit testing LLM apps. DeepEval incorporates the latest research to run evals via metrics such as G-Eval, task completion, answer relevancy, hallucination, etc., which use LLM-as-a-judge and other NLP models that run locally on your machine.
Whether you're building AI agents, voice agents, multi-turn chatbots, RAG pipelines, or anything else, implemented via LangChain or OpenAI, DeepEval has you covered. With it, you can easily evaluate:
LLM apps end-to-end as black boxes
Complete AI agent trajectories across every decision and action
Individual AI agent steps such as LLM calls, tool use, retrieval, and sub-agent handoffs
Use these evaluations to determine the optimal models, prompts, and architecture to improve your AI quality, prevent prompt drifting, or even transition from OpenAI to Claude with confidence.
Jev is now available in DeepEval, both in existing metrics and the latest JevEval.
[!IMPORTANT]
If you're already in production, Confident AI surfaces failing traces before anyone has written an eval for them, clusters them into failure modes, and turns them into your next eval.
🔥 Metrics and Features
📐 Large variety of ready-to-use LLM eval metrics (all with explanations) powered by ANY LLM of your choice, statistical methods, or NLP models that run locally on your machine covering all use cases:
Custom, All-Purpose Metrics:
JevEval — a custom metric scored by Jev, a System One model that answers your questions with calibrated probabilities instead of generated text
G-Eval — a research-backed LLM-as-a-judge metric for evaluating on any custom criteria with human-like accuracy
DAG — DeepEval's graph-based deterministic LLM-as-a-judge metric builder
AI Agent Metrics
Task Completion — evaluate whether an AI agent accomplished its goal
Tool Correctness — check if the right tools were called with the right arguments
Goal Accuracy — measure how accurately the agent achieved the intended goal
Step Efficiency — evaluate whether the agent took unnecessary steps
Plan Adherence — check if the agent followed the expected plan
Plan Quality — evaluate the quality of the agent's plan
JSON Correctness — check whether the output matches an expected JSON schema
Prompt Alignment — measure whether the output aligns with instructions in the prompt template
🎯 Supports both end-to-end and component-level LLM evaluation.
🧩 Build your own custom metrics that are automatically integrated with DeepEval's ecosystem.
🔮 Generate single and multi-turn synthetic datasets, and simulate live voice calls against your voice agent.
🔗 Integrates seamlessly with ANY CI/CD environment.
🧬 Optimize prompts automatically based on evaluation results.
🏆 Easily benchmark ANY LLM on popular LLM benchmarks in under 10 lines of code., including MMLU, HellaSwag, DROP, BIG-Bench Hard, TruthfulQA, HumanEval, GSM8K.
🔌 Integrations
DeepEval plugs into any LLM framework — OpenAI Agents, LangChain, CrewAI, and more — and into voice stacks like Vapi, ElevenLabs, LiveKit, and Pipecat. The same traces can go to Confident AI once you're live, where evals run on every production trace.
Frameworks
LangChain — evaluate LangChain applications with a callback handler
LangGraph — evaluate LangGraph agents with a callback handler
Pydantic AI — evaluate Pydantic AI agents with type-safe validation
Anthropic — evaluate and trace Claude applications via a client wrapper
AWS AgentCore — evaluate agents deployed on Amazon AgentCore
Google ADK — evaluate Google ADK agents and multi-agent workflows
AI SDK — evaluate AI SDK generations and tool-loop trajectories
Mastra — evaluate Mastra agents and workflows with native tracing
OpenAI — evaluate and trace OpenAI applications via a client wrapper
OpenAI Agents — evaluate OpenAI Agents end-to-end in under a minute
LlamaIndex — evaluate AI agents and RAG applications built with LlamaIndex
Voice Agent Connectors
Vapi — simulate calls to a Vapi assistant over its WebSocket transport
ElevenLabs — simulate calls to an ElevenLabs conversational agent
LiveKit — join your agent's LiveKit room and trade audio over WebRTC
Pipecat — connect to your Pipecat pipeline over its WebSocket transport
☁️ Platform + Ecosystem
Confident AI is AI monitoring for applications in production. DeepEval tests what you know to test before you ship; Confident AI finds what you didn't, and it's model- and framework-agnostic.
Failing traces surface before anyone has written an eval for them, clustered into failure modes, with user sentiment and behavior across traces.
Failing traces route to the right annotators and become goldens, so production issues turn into your next eval.
For enterprise teams, one system for AI quality: evals, monitoring, human annotation, and voice-native observability, with governance as release gates.
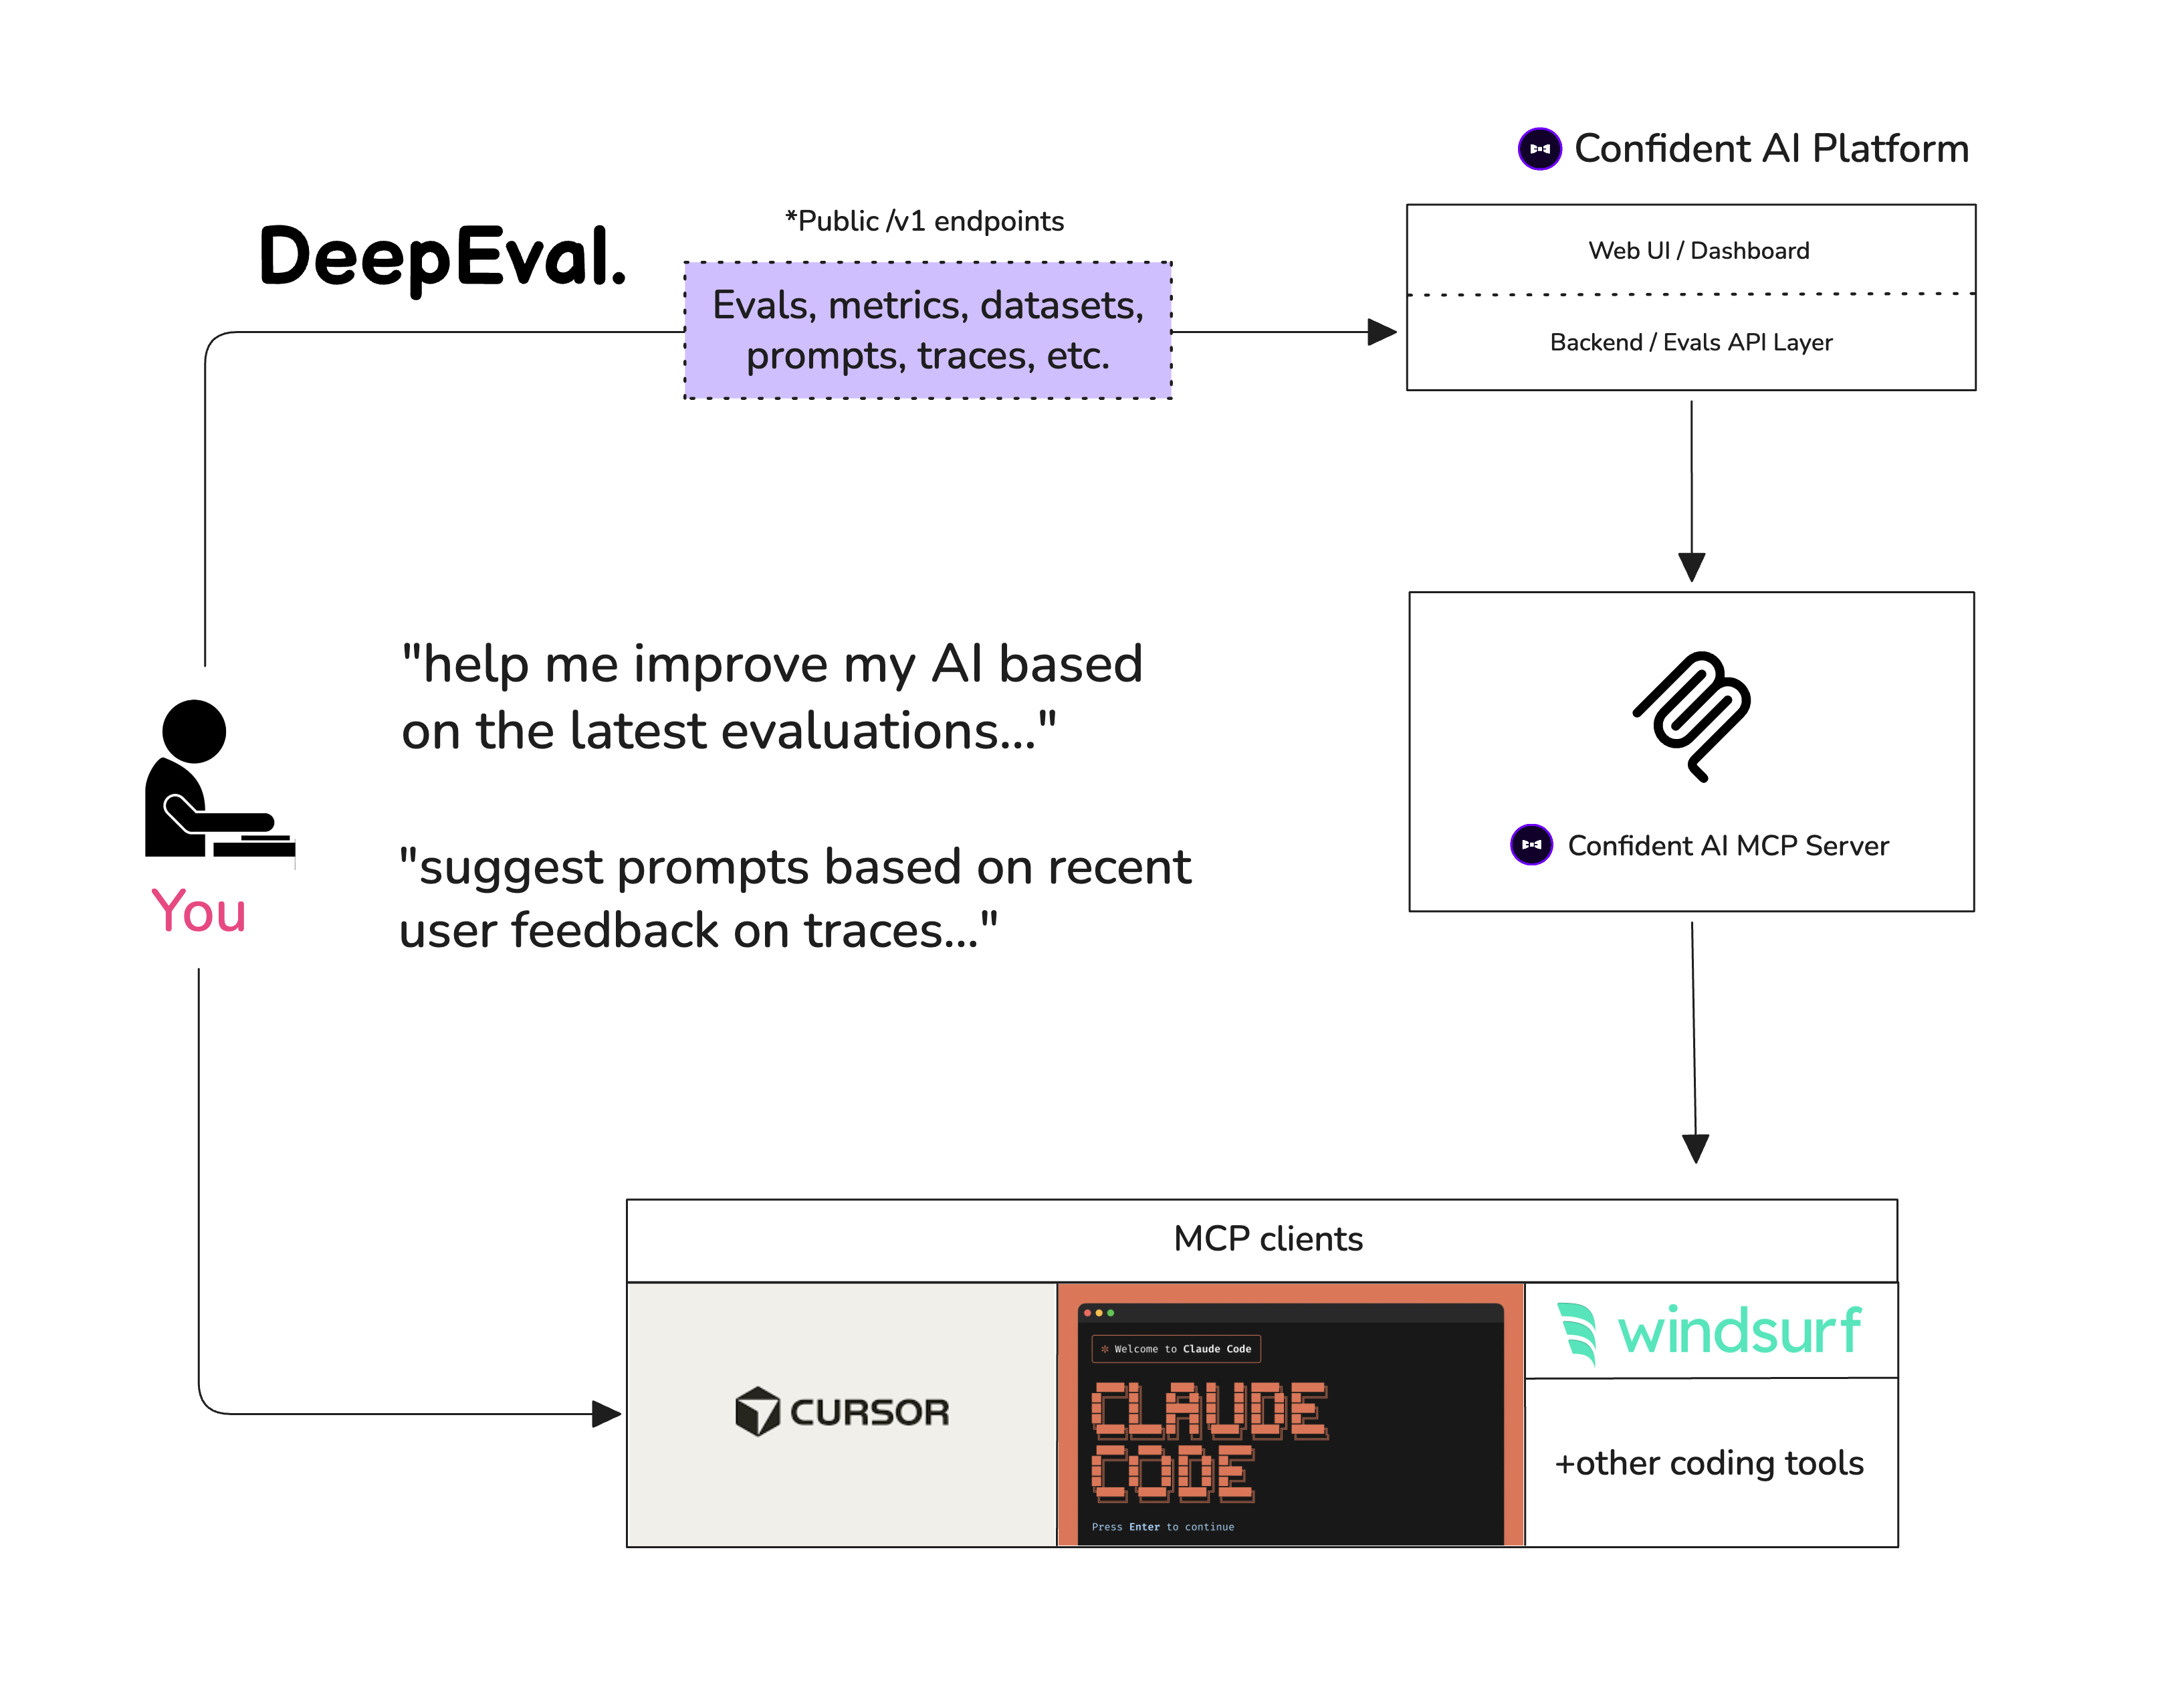
Prefer to stay in your editor? Inspect failing traces and pull the datasets built from them in Claude Code or Cursor through Confident AI's MCP server.
🤖 Vibe-Coder QuickStart
Want your coding agent to add evals and fix failures for you? Install the DeepEval skill, point it at your AI agent, voice agent, multi-turn chatbot, RAG pipeline, or any other LLM app, and ask it to generate a dataset, write the eval suite, run deepeval test run, and iterate on the failing metrics.
Let's pretend your LLM application is a customer support AI agent; here's how DeepEval can help test what you've built.
Installation
Deepeval works with Python>=3.9+.
pip install -U deepeval
Create an account (highly recommended)
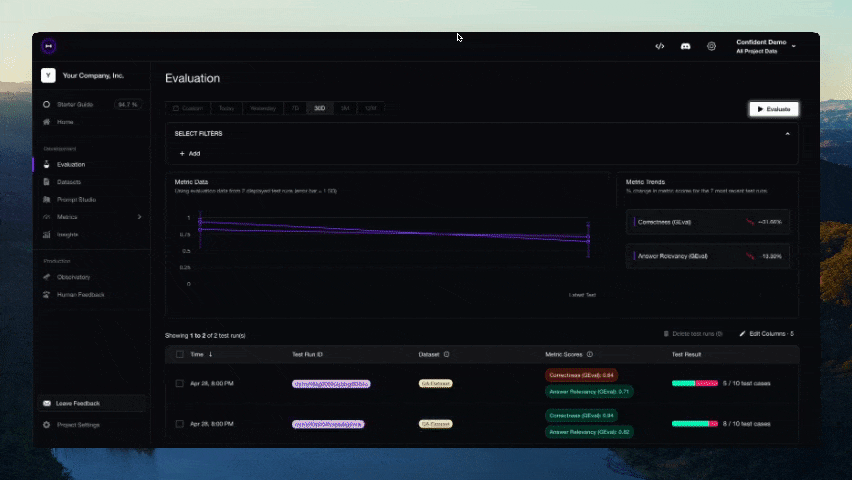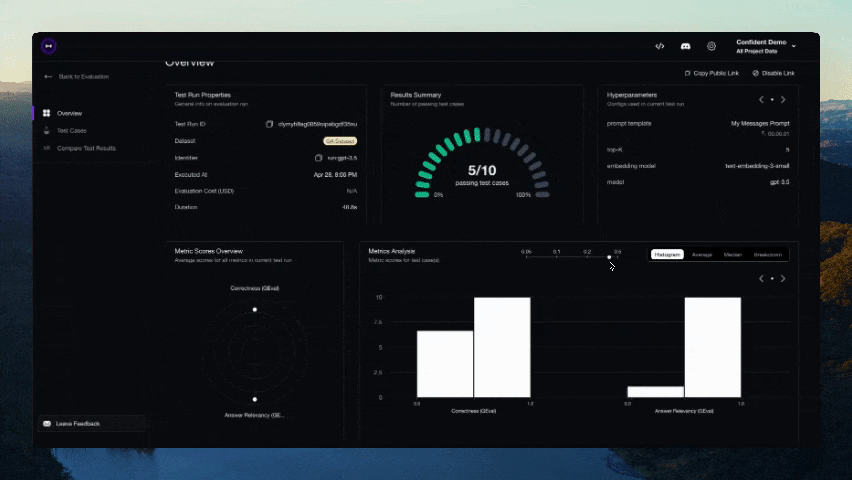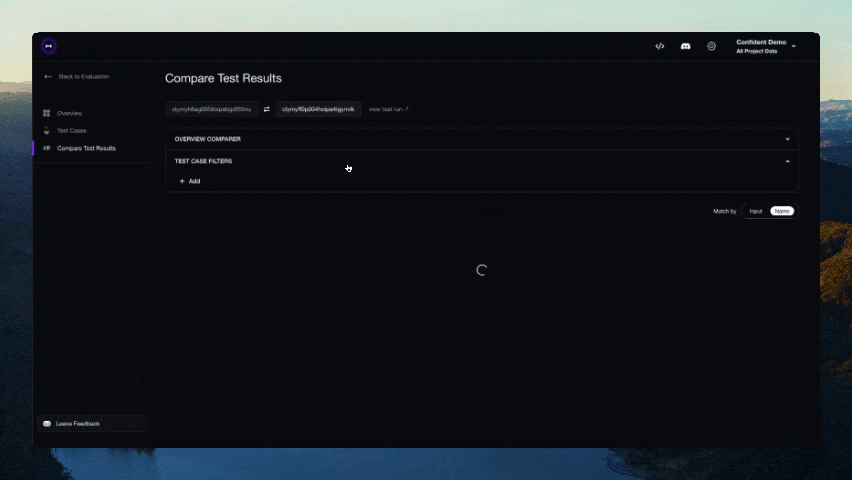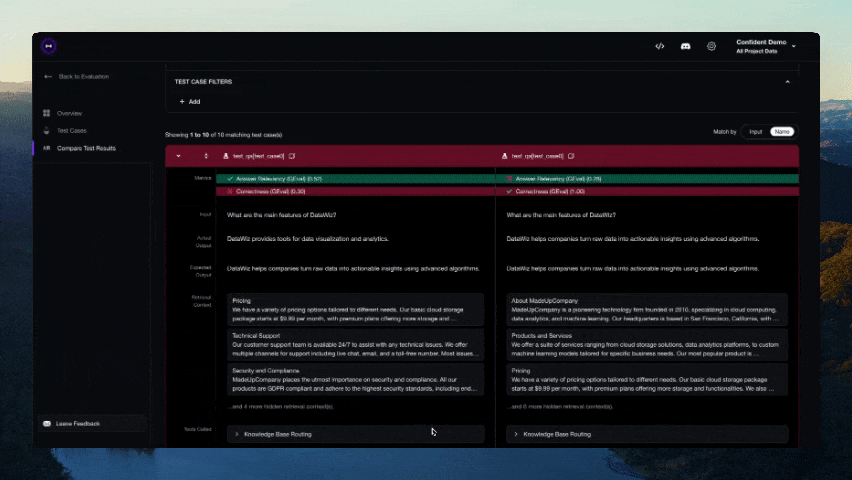
Using the deepeval platform will allow you to generate sharable testing reports on the cloud. It is free, takes no additional code to setup, and we highly recommend giving it a try.
To login, run:
deepeval login
Follow the instructions in the CLI to create an account, copy your API key, and paste it into the CLI. All test cases will automatically be logged (find more information on data privacy here).
Write your first test case
Create a test file:
touch test_ai_agent.py
Open test_ai_agent.py and write your first test case to run an end-to-end evaluation using DeepEval, which treats your LLM app as a black-box:
import pytest
from deepeval import assert_test
from deepeval.metrics import GEval
from deepeval.test_case import LLMTestCase, SingleTurnParams

def test_case():
    correctness_metric = GEval(
        name="Correctness",
        criteria="Determine if the 'actual output' is correct based on the 'expected output'.",
        evaluation_params=[SingleTurnParams.ACTUAL_OUTPUT, SingleTurnParams.EXPECTED_OUTPUT],
        threshold=0.5
    )
    test_case = LLMTestCase(
        input="What if these shoes don't fit?",
        # Replace this with the actual output from your LLM application
        actual_output="You have 30 days to get a full refund at no extra cost.",
        expected_output="We offer a 30-day full refund at no extra costs.",
    )
    assert_test(test_case, [correctness_metric])
Set your OPENAI_API_KEY as an environment variable (you can also evaluate using your own custom model, for more details visit this part of our docs):
export OPENAI_API_KEY="..."
And finally, run test_ai_agent.py in the CLI:
deepeval test run test_ai_agent.py
Congratulations! Your test case should have passed ✅ Let's break down what happened.
The variable input mimics a user input, and actual_output is a placeholder for what your application's supposed to output based on this input.
The variable expected_output represents the ideal answer for a given input, and GEval is a research-backed metric provided by deepeval for you to evaluate your LLM outputs on any custom criteria with human-like accuracy.
In this example, the metric criteria is correctness of the actual_output based on the provided expected_output.
All metric scores range from 0 - 1, which the threshold=0.5 ultimately determines if your test has passed or not.
Use evals_iterator() to run the same dataset through your app, whether you instrument it manually or through one of DeepEval's framework integrations. Because tracing captures the ordered sequence of model decisions, tool calls, and intermediate steps, you can run trajectory-based evaluations over the complete path your AI agent takes.
Here's an example of manual instrumentation:
from deepeval.tracing import observe, update_current_span
from deepeval.test_case import LLMTestCase
from deepeval.metrics import TaskCompletionMetric

@observe()
def inner_component(input: str):
    output = "result"
    update_current_span(test_case=LLMTestCase(input=input, actual_output=output))
    return output

@observe()
def app(input: str):
    return inner_component(input)

# This metric evaluates the complete trajectory captured for this run.
for golden in dataset.evals_iterator(metrics=[TaskCompletionMetric()]):
    app(golden.input)
OpenAI
from deepeval.openai import OpenAI
from deepeval.tracing import trace
from deepeval.metrics import TaskCompletionMetric

client = OpenAI()

# This metric evaluates the complete trajectory captured for this run.
for golden in dataset.evals_iterator():
    with trace(metrics=[TaskCompletionMetric()]):
        client.chat.completions.create(
            model="gpt-4o",
            messages=[{"role": "user", "content": golden.input}],
        )
OpenAI Agents
from agents import Runner
from deepeval.metrics import TaskCompletionMetric

# This metric evaluates the complete trajectory captured for this run.
for golden in dataset.evals_iterator(metrics=[TaskCompletionMetric()]):
    Runner.run_sync(agent, golden.input)
AI SDK (TypeScript)
import { generateText } from "ai";
import { configureAiSdkTracing } from "deepeval/integrations/ai-sdk";
import { TaskCompletionMetric } from "deepeval/metrics";

const tracer = configureAiSdkTracing({ name: "my-agent" });

const ask = (input: string) =>
  generateText({
    model,
    prompt: input,
    experimental_telemetry: { isEnabled: true, tracer },
  });

// This metric evaluates the complete trajectory captured for this run.
for await (const golden of dataset.evalsIterator({
  metrics: [new TaskCompletionMetric()],
})) {
  await ask(golden.input);
}
Mastra (TypeScript)
import { Mastra } from "@mastra/core/mastra";
import { Observability } from "@mastra/observability";
import { DeepEvalExporter } from "deepeval/integrations/mastra";
import { TaskCompletionMetric } from "deepeval/metrics";

const mastra = new Mastra({
  agents: { agent },
  observability: new Observability({
    configs: {
      deepeval: { exporters: [new DeepEvalExporter()] },
    },
  }),
});

// This metric evaluates the complete trajectory captured for this run.
for await (const golden of dataset.evalsIterator({
  metrics: [new TaskCompletionMetric()],
})) {
  await mastra.getAgent("agent").generate(golden.input);
}
Anthropic
from deepeval.anthropic import Anthropic
from deepeval.tracing import trace
from deepeval.metrics import TaskCompletionMetric

client = Anthropic()

# This metric evaluates the complete trajectory captured for this run.
for golden in dataset.evals_iterator():
    with trace(metrics=[TaskCompletionMetric()]):
        client.messages.create(
            model="claude-sonnet-4-5",
            max_tokens=1024,
            messages=[{"role": "user", "content": golden.input}],
        )
LangChain
from deepeval.integrations.langchain import CallbackHandler
from deepeval.metrics import TaskCompletionMetric

# This metric evaluates the complete trajectory captured for this run.
for golden in dataset.evals_iterator():
    llm.invoke(
        golden.input,
        config={"callbacks": [CallbackHandler(metrics=[TaskCompletionMetric()])]},
    )
LangGraph
from deepeval.integrations.langchain import CallbackHandler
from deepeval.metrics import TaskCompletionMetric

# This metric evaluates the complete trajectory captured for this run.
for golden in dataset.evals_iterator():
    agent.invoke(
        {"messages": [{"role": "user", "content": golden.input}]},
        config={"callbacks": [CallbackHandler(metrics=[TaskCompletionMetric()])]},
    )
Pydantic AI
from deepeval.metrics import TaskCompletionMetric

# This metric evaluates the complete trajectory captured for this run.
for golden in dataset.evals_iterator(metrics=[TaskCompletionMetric()]):
    agent.run_sync(golden.input)
CrewAI
from deepeval.integrations.crewai import instrument_crewai
from deepeval.metrics import TaskCompletionMetric

instrument_crewai()

# This metric evaluates the complete trajectory captured for this run.
for golden in dataset.evals_iterator(metrics=[TaskCompletionMetric()]):
    crew.kickoff({"input": golden.input})
AWS AgentCore
from deepeval.integrations.agentcore import instrument_agentcore
from deepeval.metrics import TaskCompletionMetric

instrument_agentcore()

# This metric evaluates the complete trajectory captured for this run.
for golden in dataset.evals_iterator(metrics=[TaskCompletionMetric()]):
    invoke({"prompt": golden.input})
LlamaIndex
import asyncio
from deepeval.evaluate.configs import AsyncConfig
from deepeval.metrics import TaskCompletionMetric

# This metric evaluates the complete trajectory captured for this run.
for golden in dataset.evals_iterator(
    async_config=AsyncConfig(run_async=True),
    metrics=[TaskCompletionMetric()],
):
    task = asyncio.create_task(agent.run(golden.input))
    dataset.evaluate(task)
Google ADK
import asyncio
from deepeval.evaluate.configs import AsyncConfig
from deepeval.integrations.google_adk import instrument_google_adk
from deepeval.metrics import TaskCompletionMetric

instrument_google_adk()

# This metric evaluates the complete trajectory captured for this run.
for golden in dataset.evals_iterator(
    async_config=AsyncConfig(run_async=True),
    metrics=[TaskCompletionMetric()],
):
    task = asyncio.create_task(run_agent(golden.input))
    dataset.evaluate(task)
Strands
from deepeval.integrations.strands import instrument_strands
from deepeval.metrics import TaskCompletionMetric

instrument_strands()

# This metric evaluates the complete trajectory captured for this run.
for golden in dataset.evals_iterator(metrics=[TaskCompletionMetric()]):
    agent(golden.input)
Learn more about component-level evaluations here.
Evaluate Without Pytest Integration
Alternatively, you can evaluate without Pytest, which is more suited for a notebook environment.
from deepeval import evaluate
from deepeval.metrics import AnswerRelevancyMetric
from deepeval.test_case import LLMTestCase

answer_relevancy_metric = AnswerRelevancyMetric(threshold=0.7)
test_case = LLMTestCase(
    input="What if these shoes don't fit?",
    # Replace this with the actual output from your LLM application
    actual_output="We offer a 30-day full refund at no extra costs.",
    retrieval_context=["All customers are eligible for a 30 day full refund at no extra costs."]
)
evaluate([test_case], [answer_relevancy_metric])
Using Standalone Metrics
DeepEval is extremely modular, making it easy for anyone to use any of our metrics. Continuing from the previous example:
from deepeval.metrics import AnswerRelevancyMetric
from deepeval.test_case import LLMTestCase

answer_relevancy_metric = AnswerRelevancyMetric(threshold=0.7)
test_case = LLMTestCase(
    input="What if these shoes don't fit?",
    # Replace this with the actual output from your LLM application
    actual_output="We offer a 30-day full refund at no extra costs.",
    retrieval_context=["All customers are eligible for a 30 day full refund at no extra costs."]
)

answer_relevancy_metric.measure(test_case)
print(answer_relevancy_metric.score)
# All metrics also offer an explanation
print(answer_relevancy_metric.reason)
Note that some metrics are built for specific use cases, such as AI agents, voice agents, multi-turn chatbots, RAG, and more. Make sure to use our docs to pick the right one for your use case.
A Note on Env Variables (.env / .env.local)
DeepEval auto-loads .env.local then .env from the current working directory at import time.
Precedence: process env -> .env.local -> .env.
Opt out with DEEPEVAL_DISABLE_DOTENV=1.
cp .env.example .env.local
# then edit .env.local (ignored by git)
DeepEval With Confident AI
Confident AI monitors AI applications in production. Evals run on every production trace, failing traces are clustered into failure modes, and each one can be routed to the right annotators — engineers, QA, domain experts or PMs — and turned into a golden for your next eval. The traces your app already produces with DeepEval stream to it with no code changes.
Log in from the CLI to connect:
deepeval login
Test runs also appear on the platform once you're logged in.
Prefer to stay in your IDE? Inspect failing traces and pull the datasets built from them through Confident AI's MCP server without leaving your editor.
What is this?DeepEval is an open-source LLM evaluation framework: a simple-to-use way to evaluate large-language model systems with research-backed metrics like G-Eval, answer relevancy, and hallucination checks.
How is it different from just using pytest?It mirrors pytest's unit-testing style but is purpose-built for LLM apps — test cases are Python objects combining inputs, outputs, and eval metrics instead of generic asserts, and you run them with DeepEval's own CLI.
How do I get started testing my own app?pip install the package (Python 3.9+), write a test file with an input, your app's actual_output and a metric like GEval at a threshold, then run 'deepeval test run' in the CLI. Scores range 0-1 and the threshold decides pass or fail.
Do I need an OpenAI API key to run the evals?The quickstart sets an OPENAI_API_KEY environment variable, but you're not locked in: metrics can be powered by any LLM of your choice or by NLP models running locally, and you can evaluate with your own custom model.
Do I have to sign up for the Confident AI cloud?No — the framework is open-source and runs locally on its own. The Confident AI platform is an optional free signup that adds sharable cloud testing reports on top of your runs.
Who is it built for — agents, RAG apps, chatbots?Developers building AI agents, RAG pipelines, or chatbots — it evaluates apps end-to-end as black boxes or at component level, down to individual agent steps like tool calls, retrieval, and sub-agent handoffs.
Does it work on Windows, or is it Mac and Linux only?It's a pip-installable Python package with a CLI, so it runs anywhere Python 3.9+ does — Windows, macOS, and Linux.
Does it send my test data anywhere?Only if you opt in: once you log in to the Confident AI platform, all your test cases are automatically logged to the cloud, and data privacy is documented separately.
Can it generate evaluation datasets for me?Yes — it can generate both single-turn and multi-turn synthetic datasets, so you don't have to hand-write every test input.
What is G-Eval?A research-backed LLM-as-a-judge metric for scoring outputs on any custom criteria you define, with human-like accuracy — the quickstart uses it to check correctness against an expected answer.
Can it benchmark raw LLMs, not just my app?Yes — it can benchmark any LLM on popular benchmarks like MMLU, HellaSwag, DROP, BIG-Bench Hard, TruthfulQA, HumanEval, and GSM8K in under 10 lines of code.
Does it help improve my app, or only score it?It optimizes prompts automatically based on evaluation results, so beyond pass/fail verdicts it helps you iterate toward better outputs.




 DeepEval is an open-source LLM evaluation framework: a simple-to-use way to evaluate large-language model systems with research-backed metrics like G-Eval, answer relevancy, and hallucination checks.