




 한국어
 English
 中文简体
 中文繁體
 日本語
 Deutsch
 Español
 Português

 Finnish:
 French:
 Hindi:
 Italian:
 Russian:


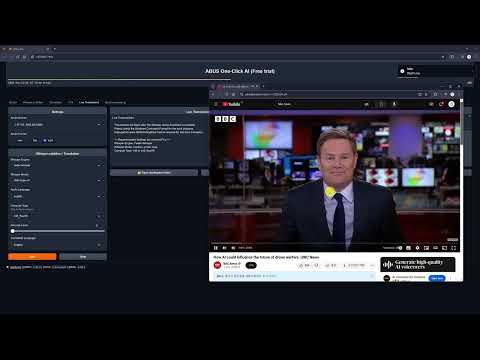


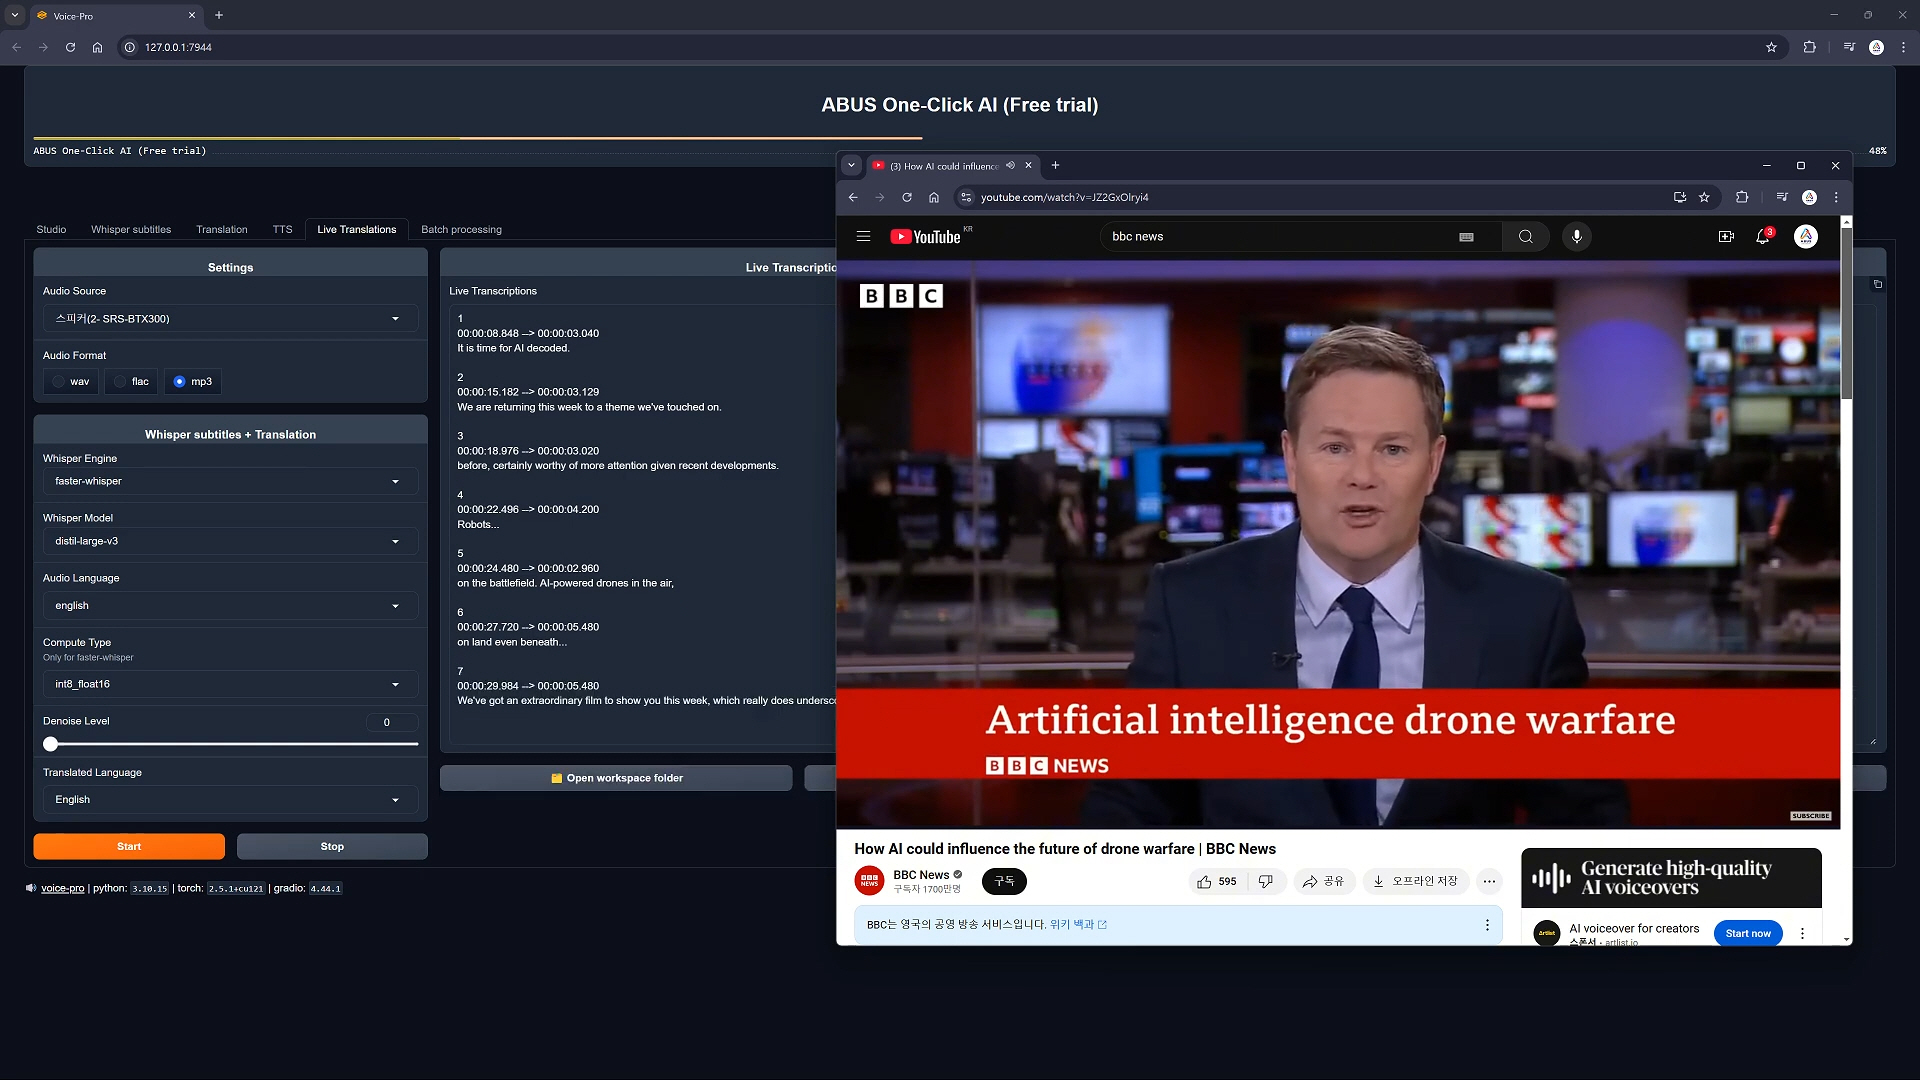
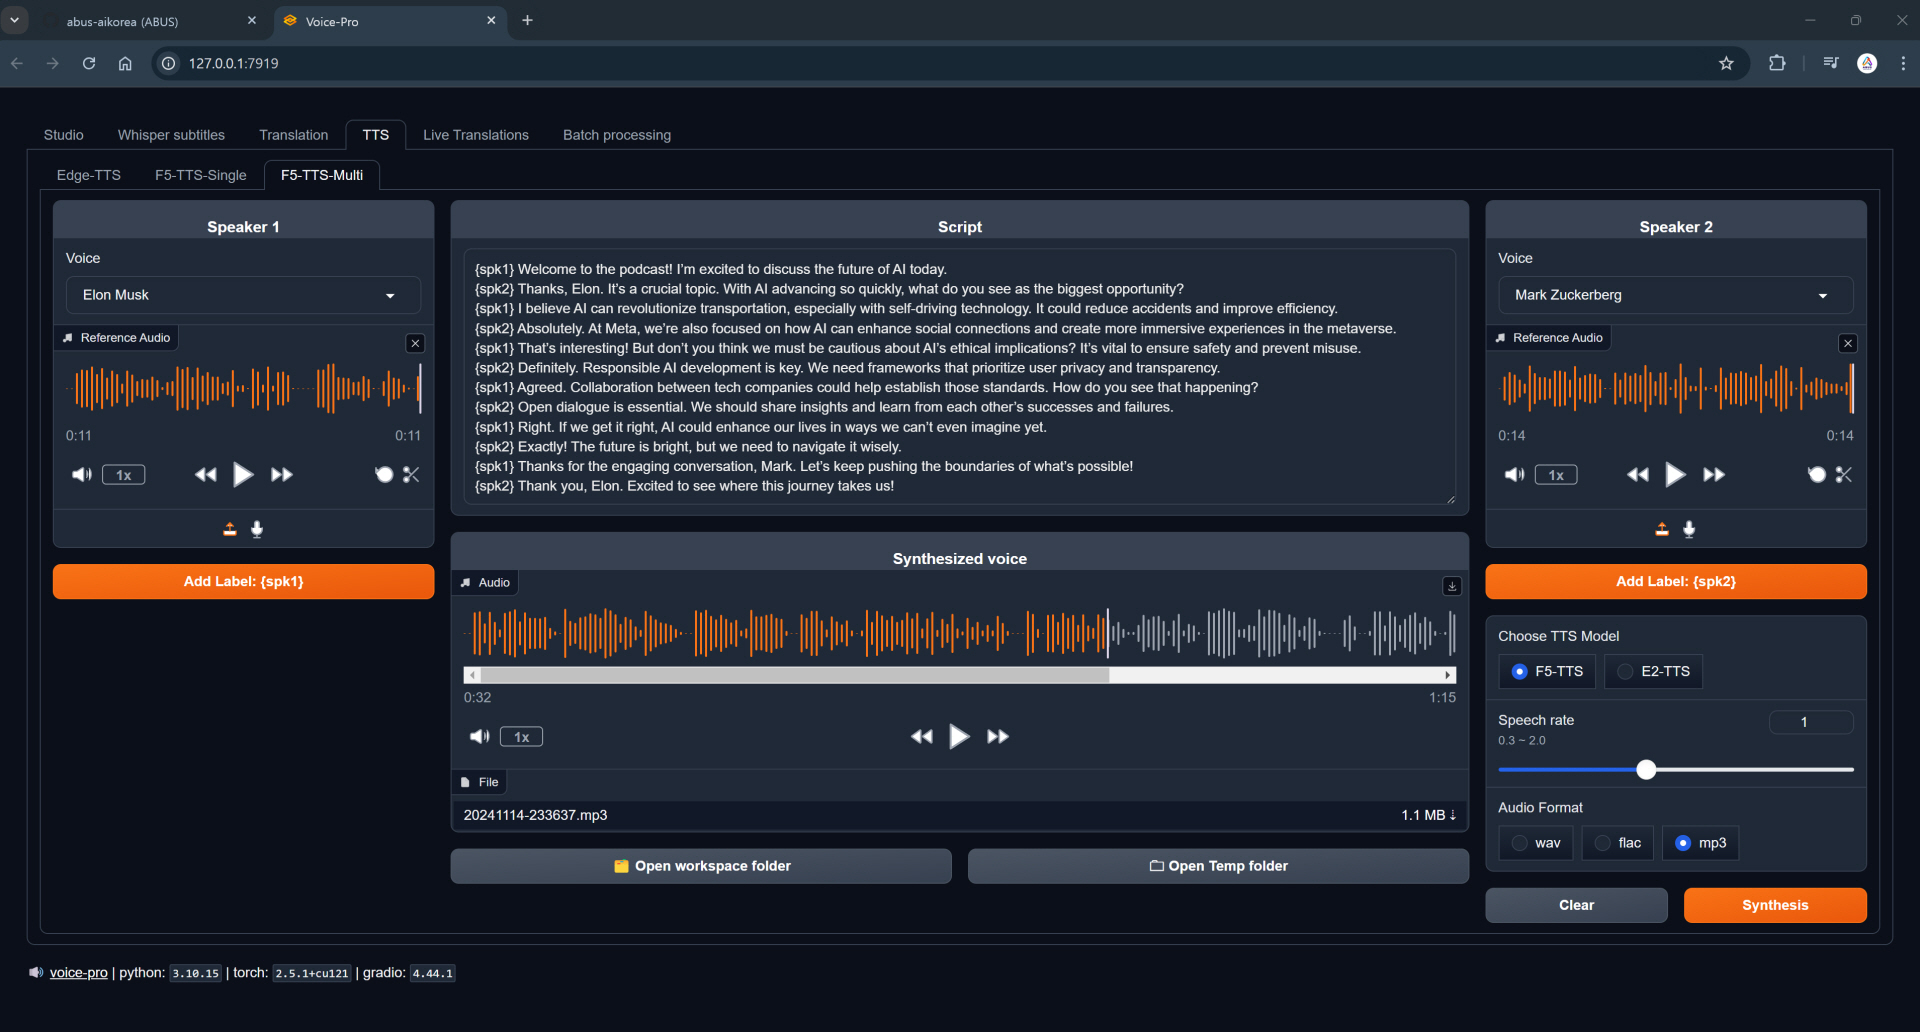


What is this?
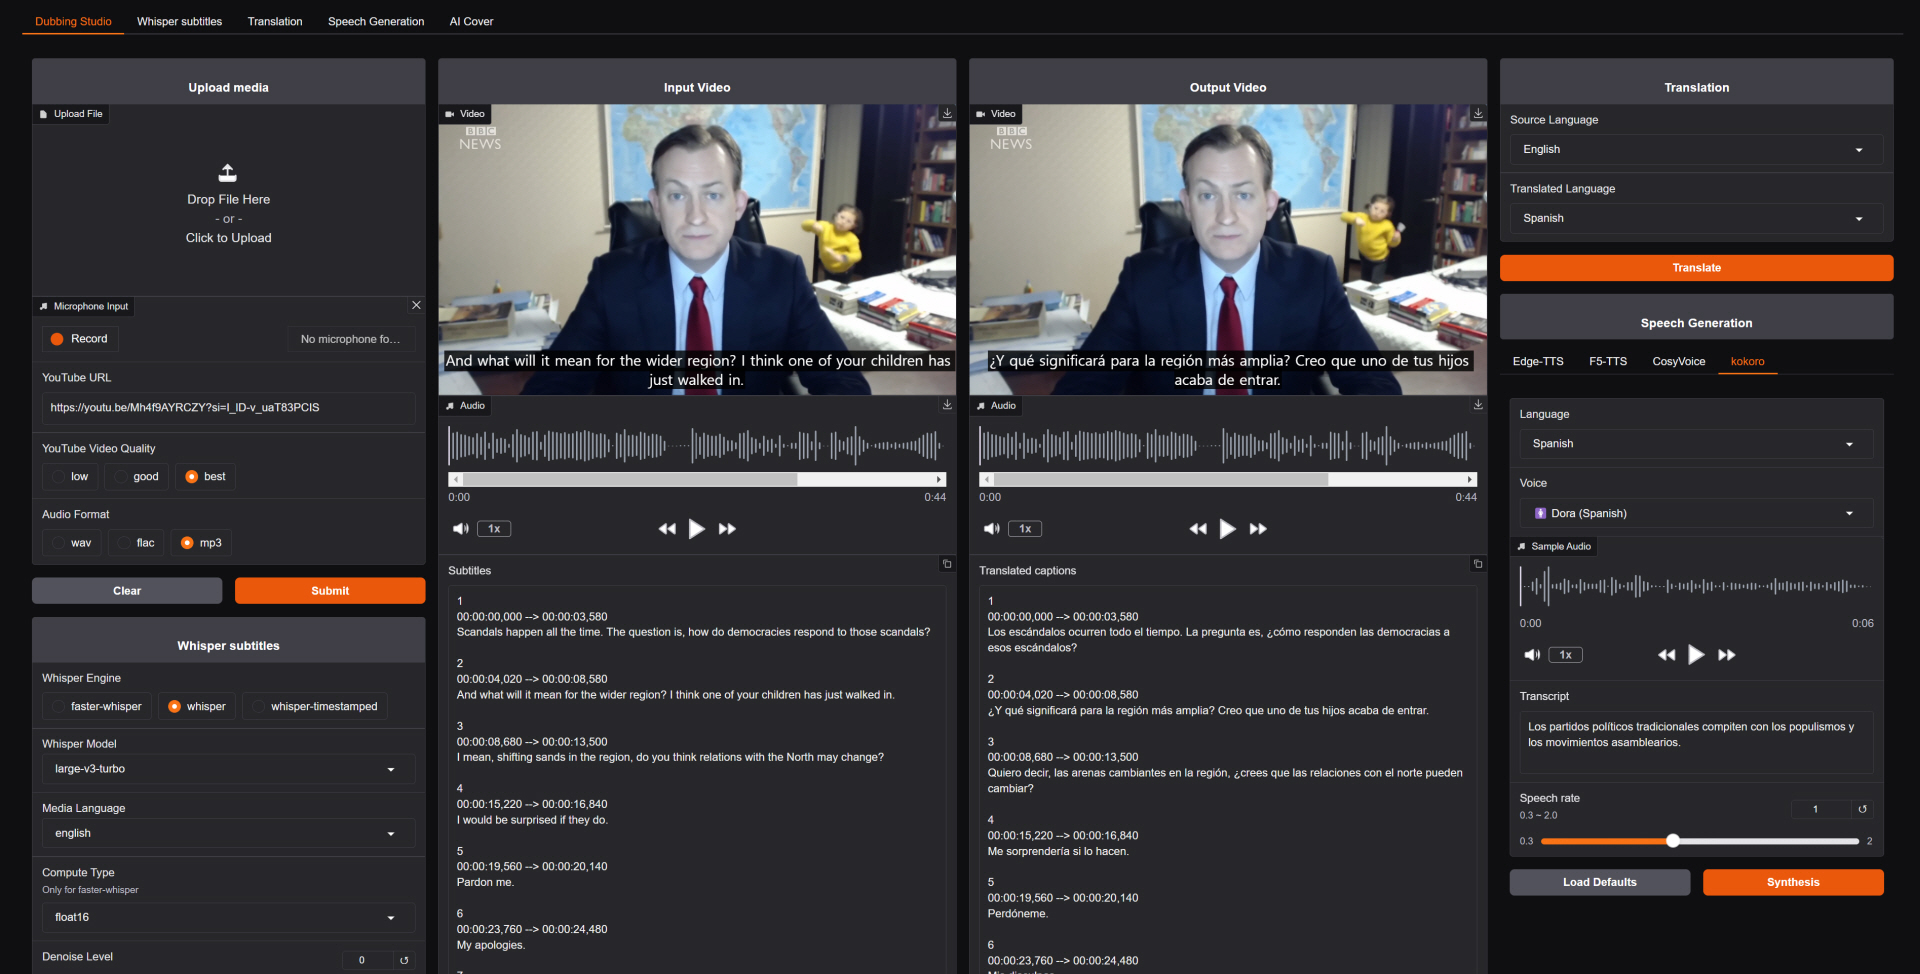
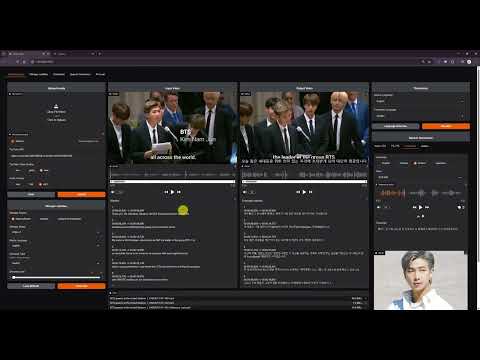
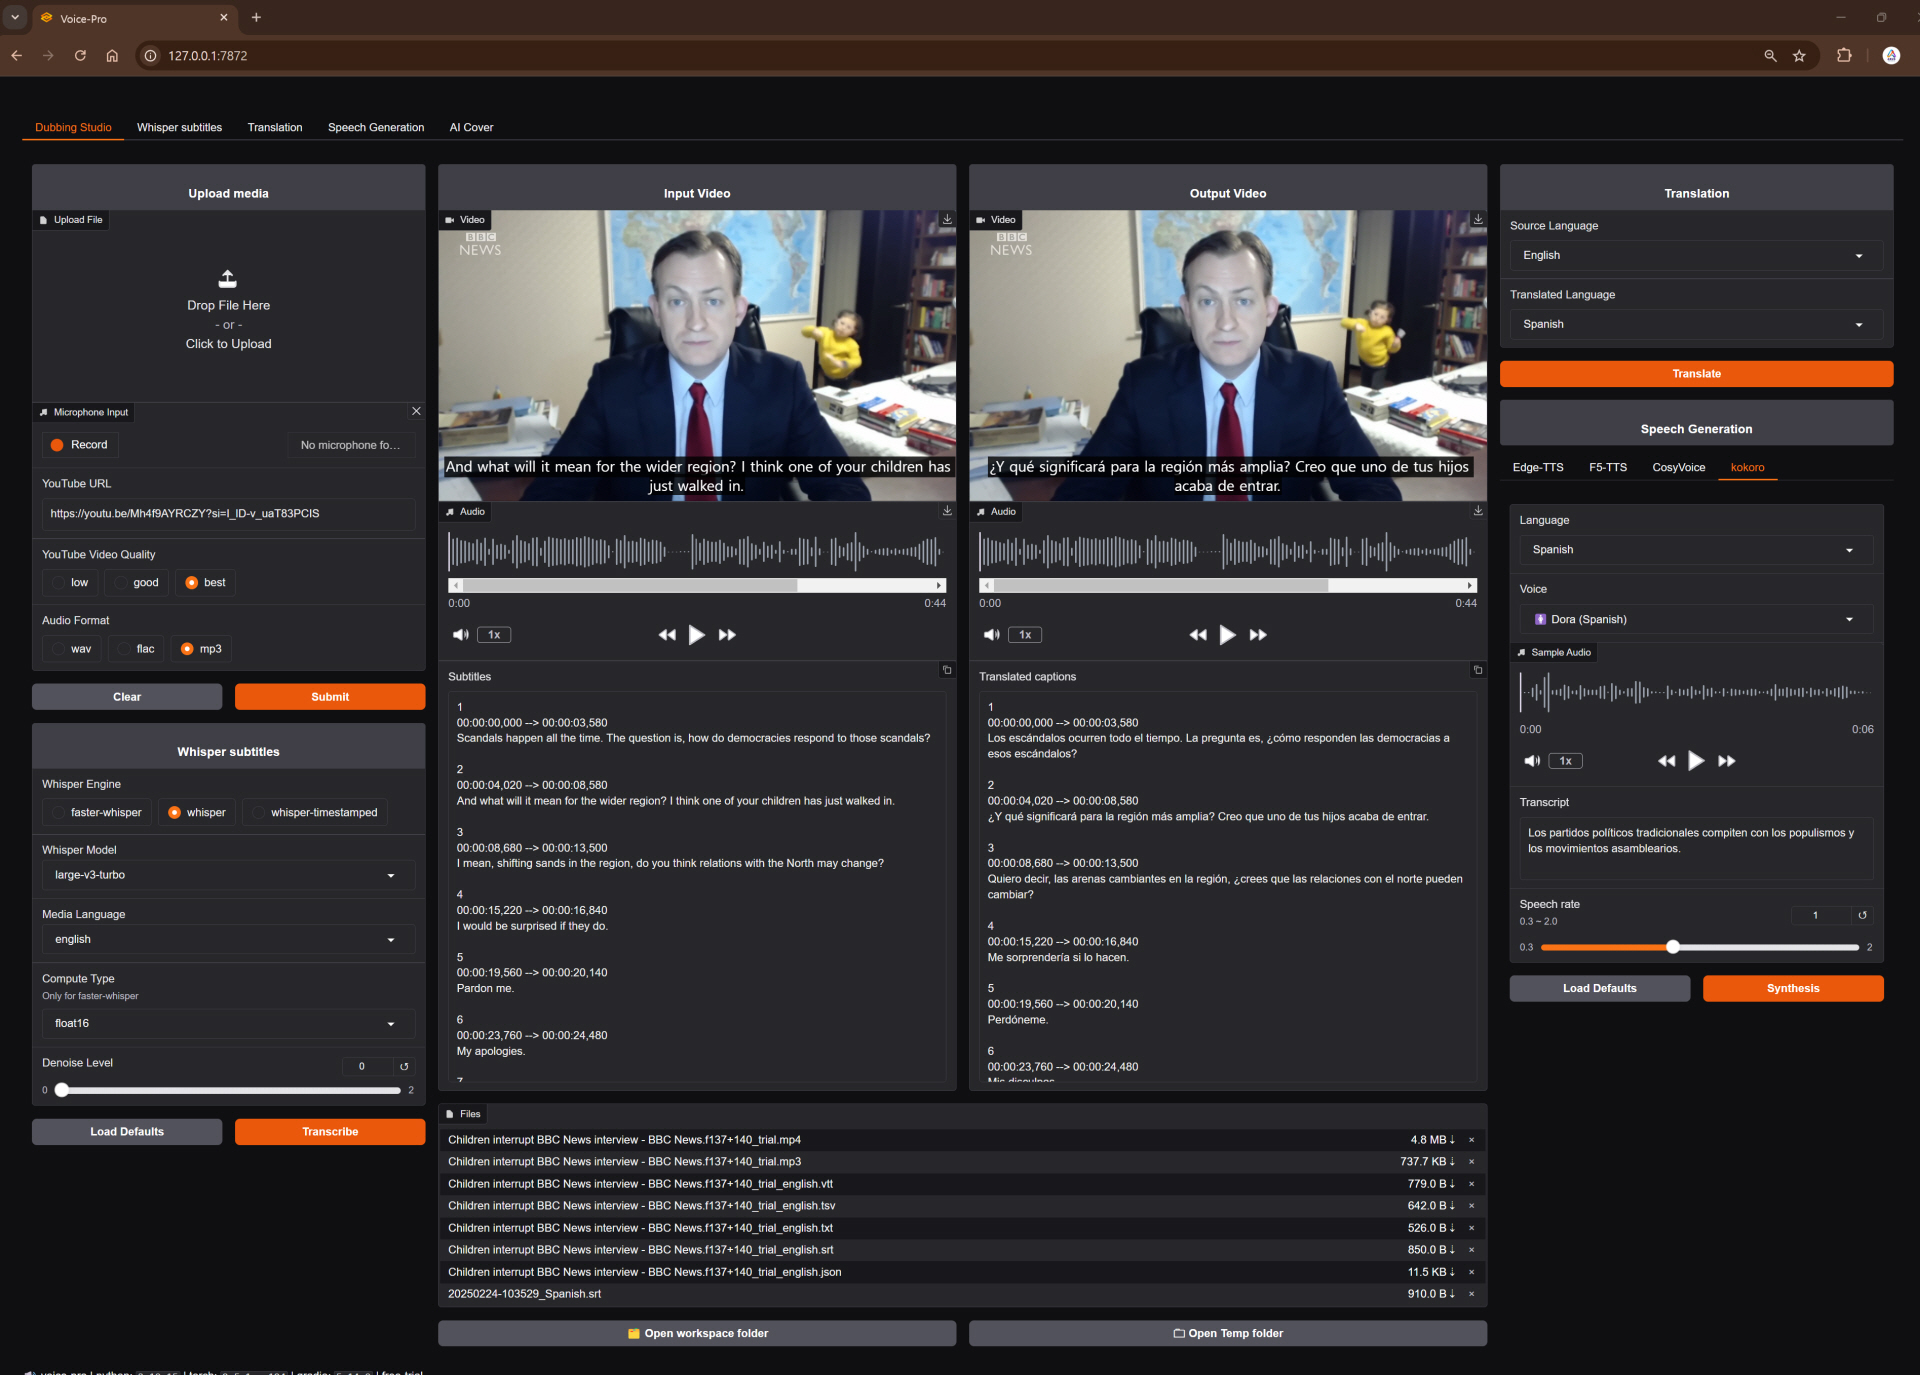
 Voice-Pro is a free, open-source AI web app (built with Gradio) that combines speech recognition, zero-shot voice cloning, text-to-speech, YouTube downloading, vocal isolation, and multilingual translation into one tool for creators and researchers.
Is this a cloud service or do I run it myself?You run it yourself: download the repo, launch start.bat, and it opens as a local Gradio web page on your own PC — there's no hosted cloud version.
You run it yourself: download the repo, launch start.bat, and it opens as a local Gradio web page on your own PC — there's no hosted cloud version.How do I get it running?On Windows, download the repo and run start.bat — it uses uv to automatically install Python, PyTorch, and all other dependencies into an isolated installerfiles/ folder, with no manual setup needed.
On Windows, download the repo and run start.bat — it uses uv to automatically install Python, PyTorch, and all other dependencies into an isolated installerfiles/ folder, with no manual setup needed.Do I need an NVIDIA GPU to run this?Yes — it's built on CUDA-accelerated PyTorch (2.8.0+cu128) and is confirmed to run well on Windows with an NVIDIA GPU. CUDA Toolkit and Visual Studio Build Tools are no longer required since all dependencies now ship as prebuilt wheels.
Yes — it's built on CUDA-accelerated PyTorch (2.8.0+cu128) and is confirmed to run well on Windows with an NVIDIA GPU. CUDA Toolkit and Visual Studio Build Tools are no longer required since all dependencies now ship as prebuilt wheels.Is active development still happening?No — the maintainers paused Voice-Pro development to focus on another project (WeConnect), though they open-sourced the whole codebase and made it free. Also note that only Windows + NVIDIA GPU is verified; Mac and Linux behavior is unconfirmed.
No — the maintainers paused Voice-Pro development to focus on another project (WeConnect), though they open-sourced the whole codebase and made it free. Also note that only Windows + NVIDIA GPU is verified; Mac and Linux behavior is unconfirmed.Does it work on Mac or Linux, or only Windows?It's confirmed to work well on Windows with an NVIDIA GPU; running it on Mac or Linux has not been verified.
It's confirmed to work well on Windows with an NVIDIA GPU; running it on Mac or Linux has not been verified.Is it really free to use?Yes, the entire codebase is open source under GPL-3.0 and can be freely used, distributed, and modified by anyone.
Yes, the entire codebase is open source under GPL-3.0 and can be freely used, distributed, and modified by anyone.What speech and voice features does it pack into one app?It covers ASR with Whisper/Faster-Whisper, zero-shot voice cloning via F5-TTS, E2-TTS and CosyVoice, TTS through Edge-TTS and kokoro, Demucs vocal isolation, YouTube downloading via yt-dlp, and translation for 100+ languages.
It covers ASR with Whisper/Faster-Whisper, zero-shot voice cloning via F5-TTS, E2-TTS and CosyVoice, TTS through Edge-TTS and kokoro, Demucs vocal isolation, YouTube downloading via yt-dlp, and translation for 100+ languages.What is kokoro?kokoro is one of the built-in TTS engines, ranked #2 in the HuggingFace TTS Arena, used for generating natural-sounding speech in the app.
kokoro is one of the built-in TTS engines, ranked #2 in the HuggingFace TTS Arena, used for generating natural-sounding speech in the app.Can it dub or subtitle a YouTube video automatically?Yes — the Dubbing Studio tab downloads a YouTube video, isolates vocals with Demucs, transcribes and translates the speech, and generates dubbed audio with TTS, all in one workflow.
Yes — the Dubbing Studio tab downloads a YouTube video, isolates vocals with Demucs, transcribes and translates the speech, and generates dubbed audio with TTS, all in one workflow.Were there paid tiers before it went open source?Earlier versions had a subscription tier with Azure TTS/Translator and unlimited usage versus a 60-second free trial cap, but since the open-source release everything is free with no usage limits.
Earlier versions had a subscription tier with Azure TTS/Translator and unlimited usage versus a 60-second free trial cap, but since the open-source release everything is free with no usage limits.What are similar projects?pyvideotrans, VideoLingo, Retrieval-based-Voice-Conversion-WebUI, ebook2audiobook, autoclip, GPT-SoVITS, VoiceStudio, fish-speech
pyvideotrans, VideoLingo, Retrieval-based-Voice-Conversion-WebUI, ebook2audiobook, autoclip, GPT-SoVITS, VoiceStudio, fish-speechWhich topics is it in?karaoke, podcasts, audiobook, voice-conversion, translator, podcast, yt-dlp, transcription, subtitles, voice-cloning, speech-synthesis, gradio
karaoke, podcasts, audiobook, voice-conversion, translator, podcast, yt-dlp, transcription, subtitles, voice-cloning, speech-synthesis, gradio