
What is this?
 It is the official GitHub page for the survey paper 'A Survey of Large Language Models' — a curated collection of papers and resources on how LLMs are built, adapted, and used.
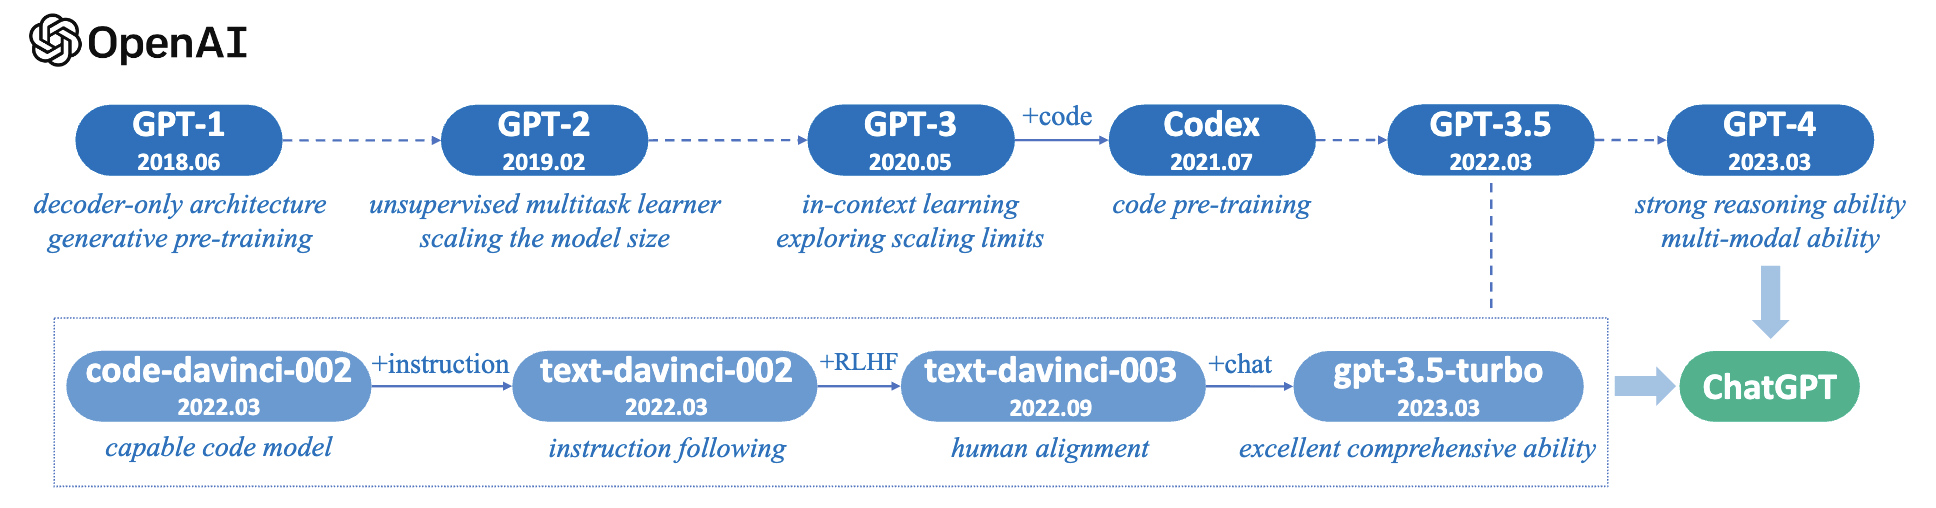
Is this software I can run, or a reading resource?A reading resource, not a runnable tool: the repo organizes papers and lists (timeline of LLMs, model catalog, corpora, libraries, prompt tips) following the survey's structure.
A reading resource, not a runnable tool: the repo organizes papers and lists (timeline of LLMs, model catalog, corpora, libraries, prompt tips) following the survey's structure.Where should someone new to LLMs start with it?Read the survey itself — it lays out a comprehensive framework and roadmap from pre-training to evaluation — or pick up the Chinese book, written as an introductory technical text for beginners.
Read the survey itself — it lays out a comprehensive framework and roadmap from pre-training to evaluation — or pick up the Chinese book, written as an introductory technical text for beginners.Do I need a deep learning background to follow it?Yes, some: the Chinese book is aimed at senior undergraduates and junior graduate students who already have a foundation in deep learning.
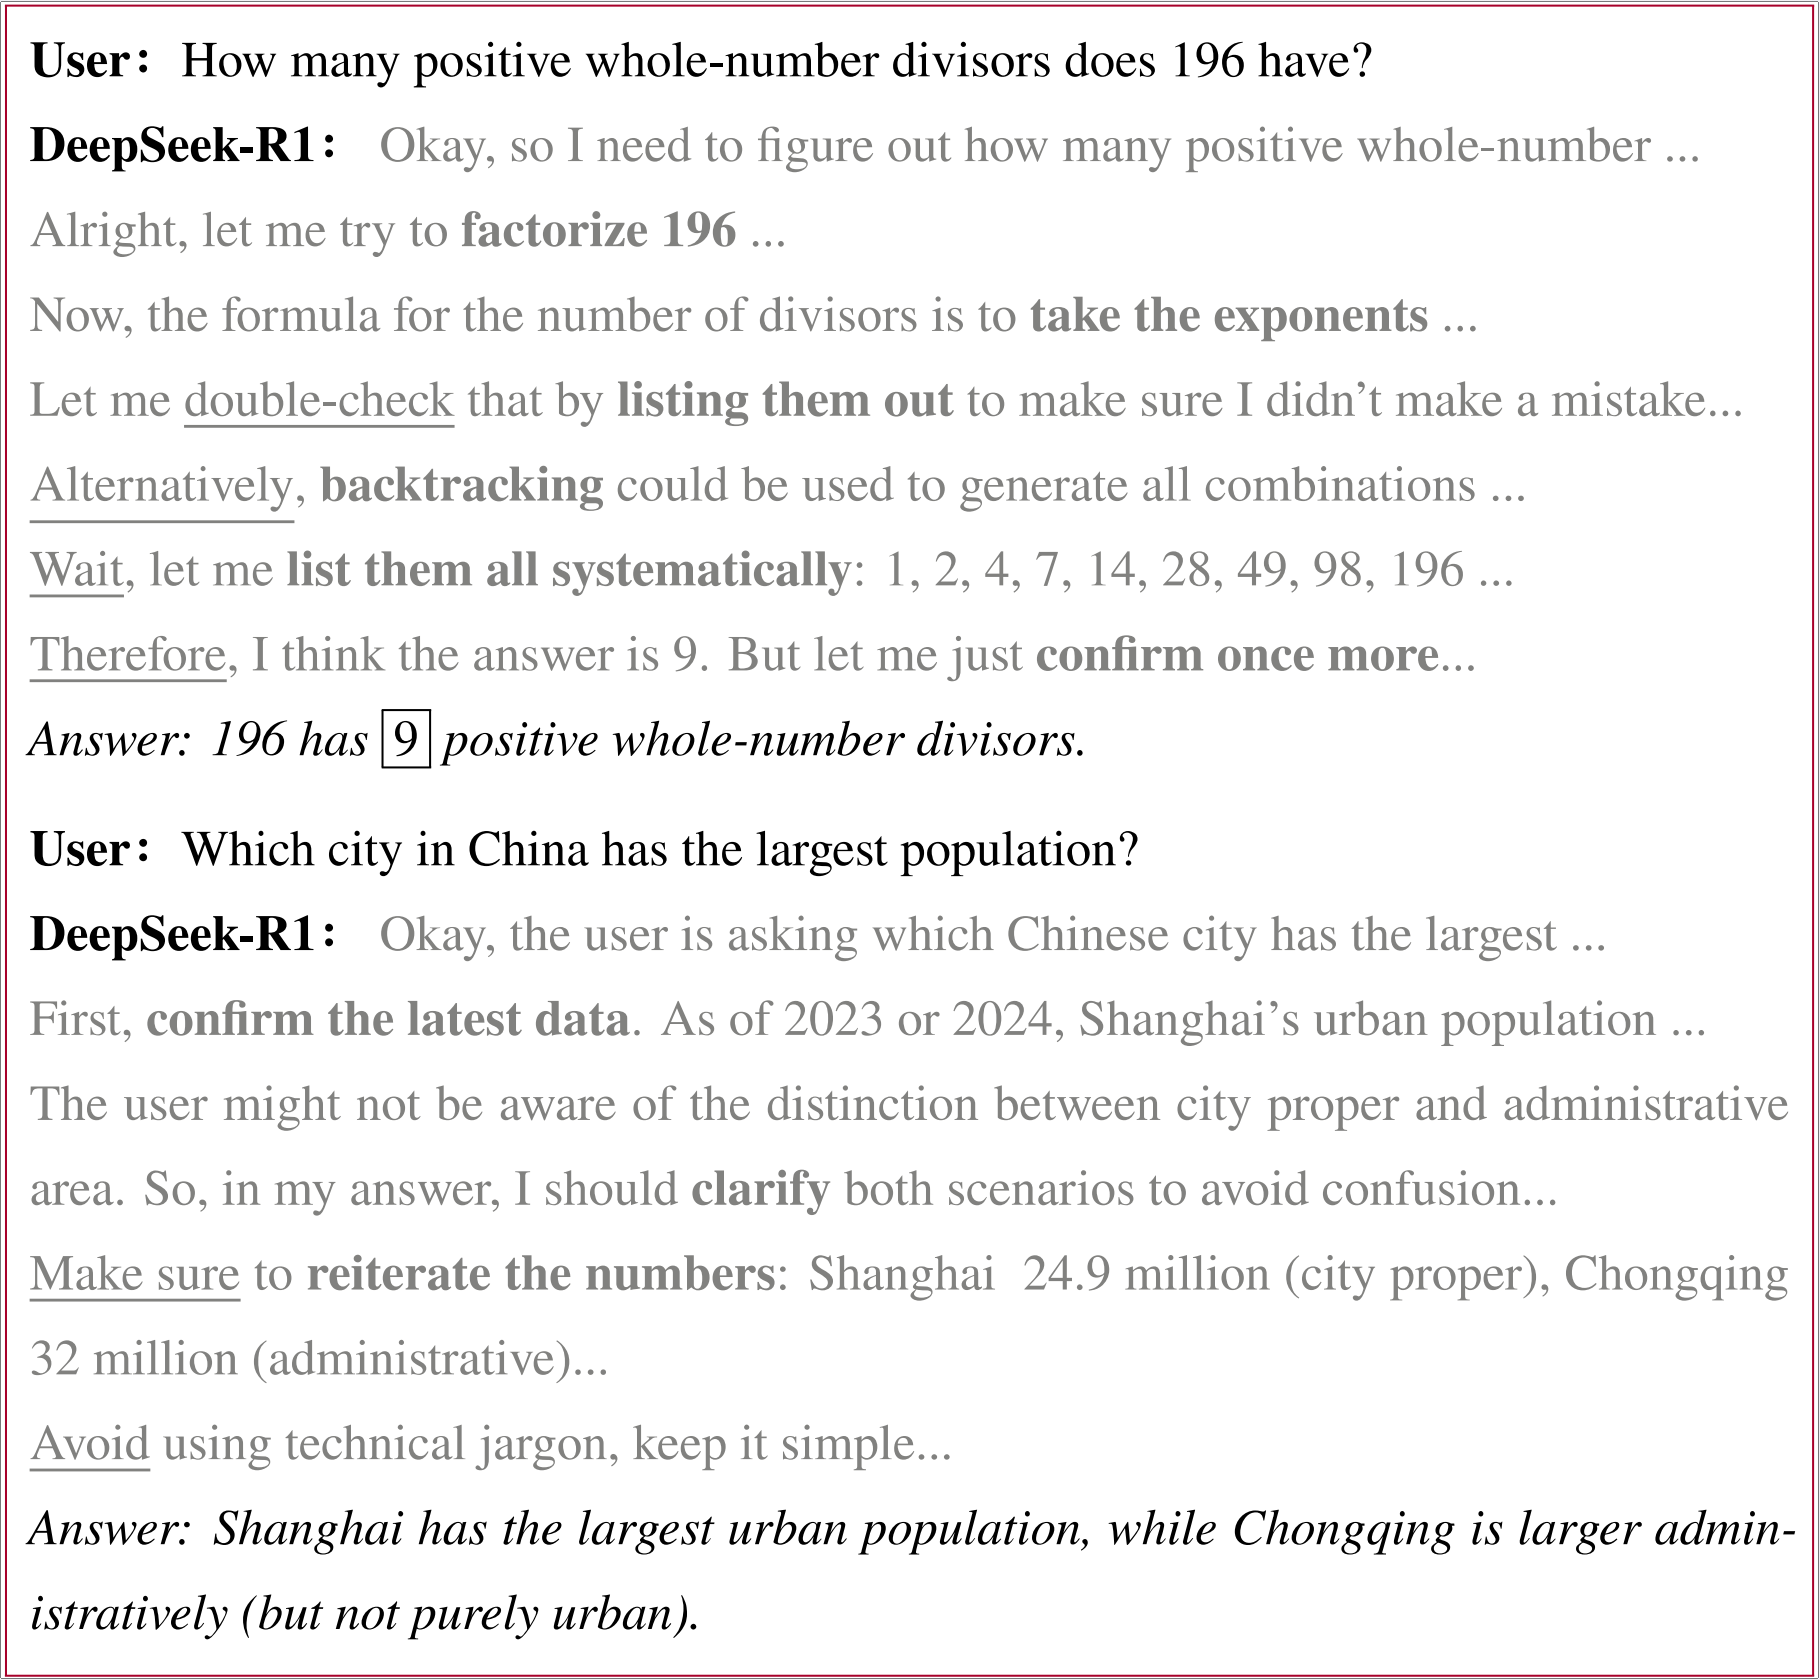
Yes, some: the Chinese book is aimed at senior undergraduates and junior graduate students who already have a foundation in deep learning.Does it keep up with how fast the field moves?The team keeps extending it: the latest version adds a section on long CoT reasoning, the paradigm behind recent models such as DeepSeek-R1 and OpenAI's o-series.
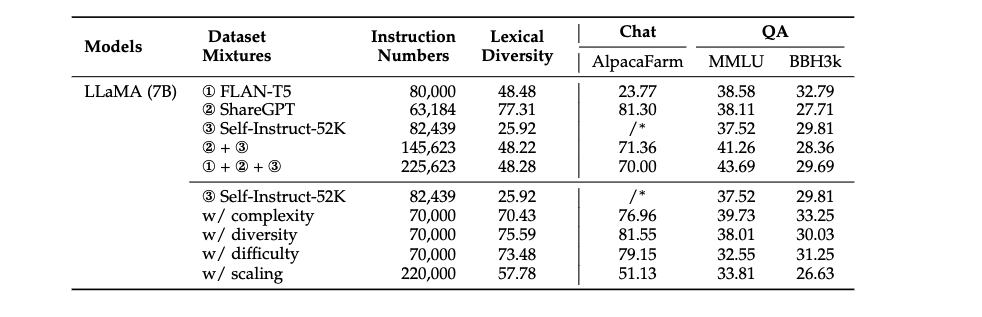
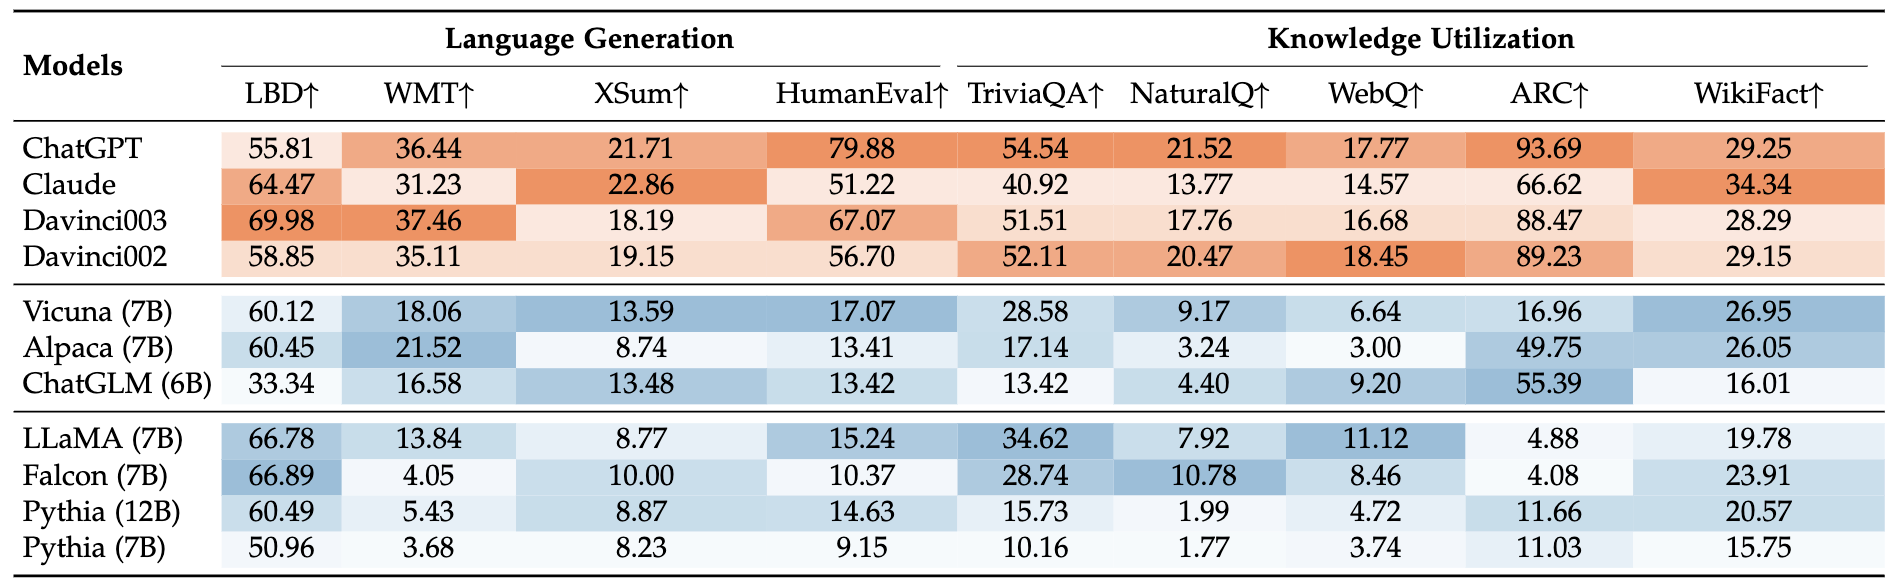
The team keeps extending it: the latest version adds a section on long CoT reasoning, the paradigm behind recent models such as DeepSeek-R1 and OpenAI's o-series.Are the experiments something I could try myself?They describe instruction tuning runs on a 7B LLaMA model plus fine-grained ability evaluations, and note they are seeking computing power for more comprehensive experiments.
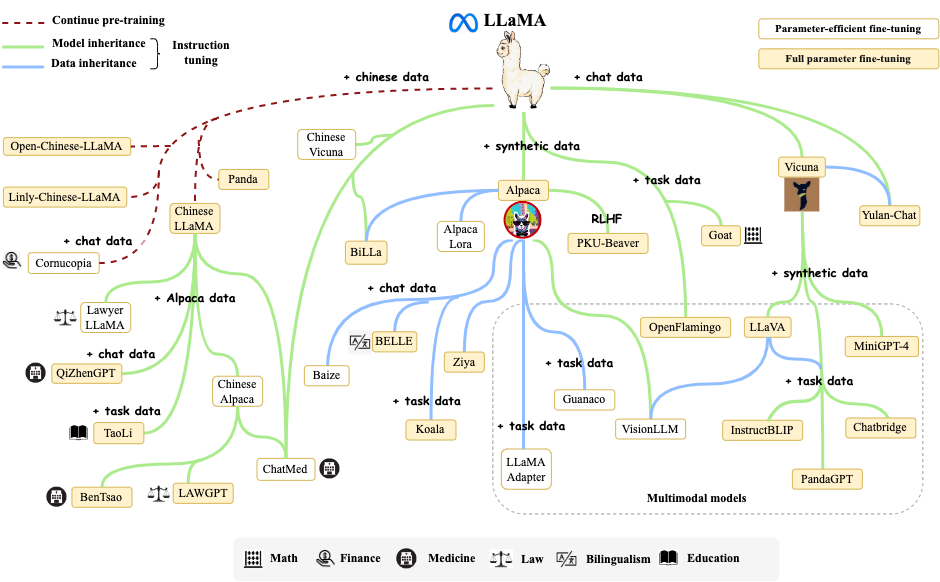
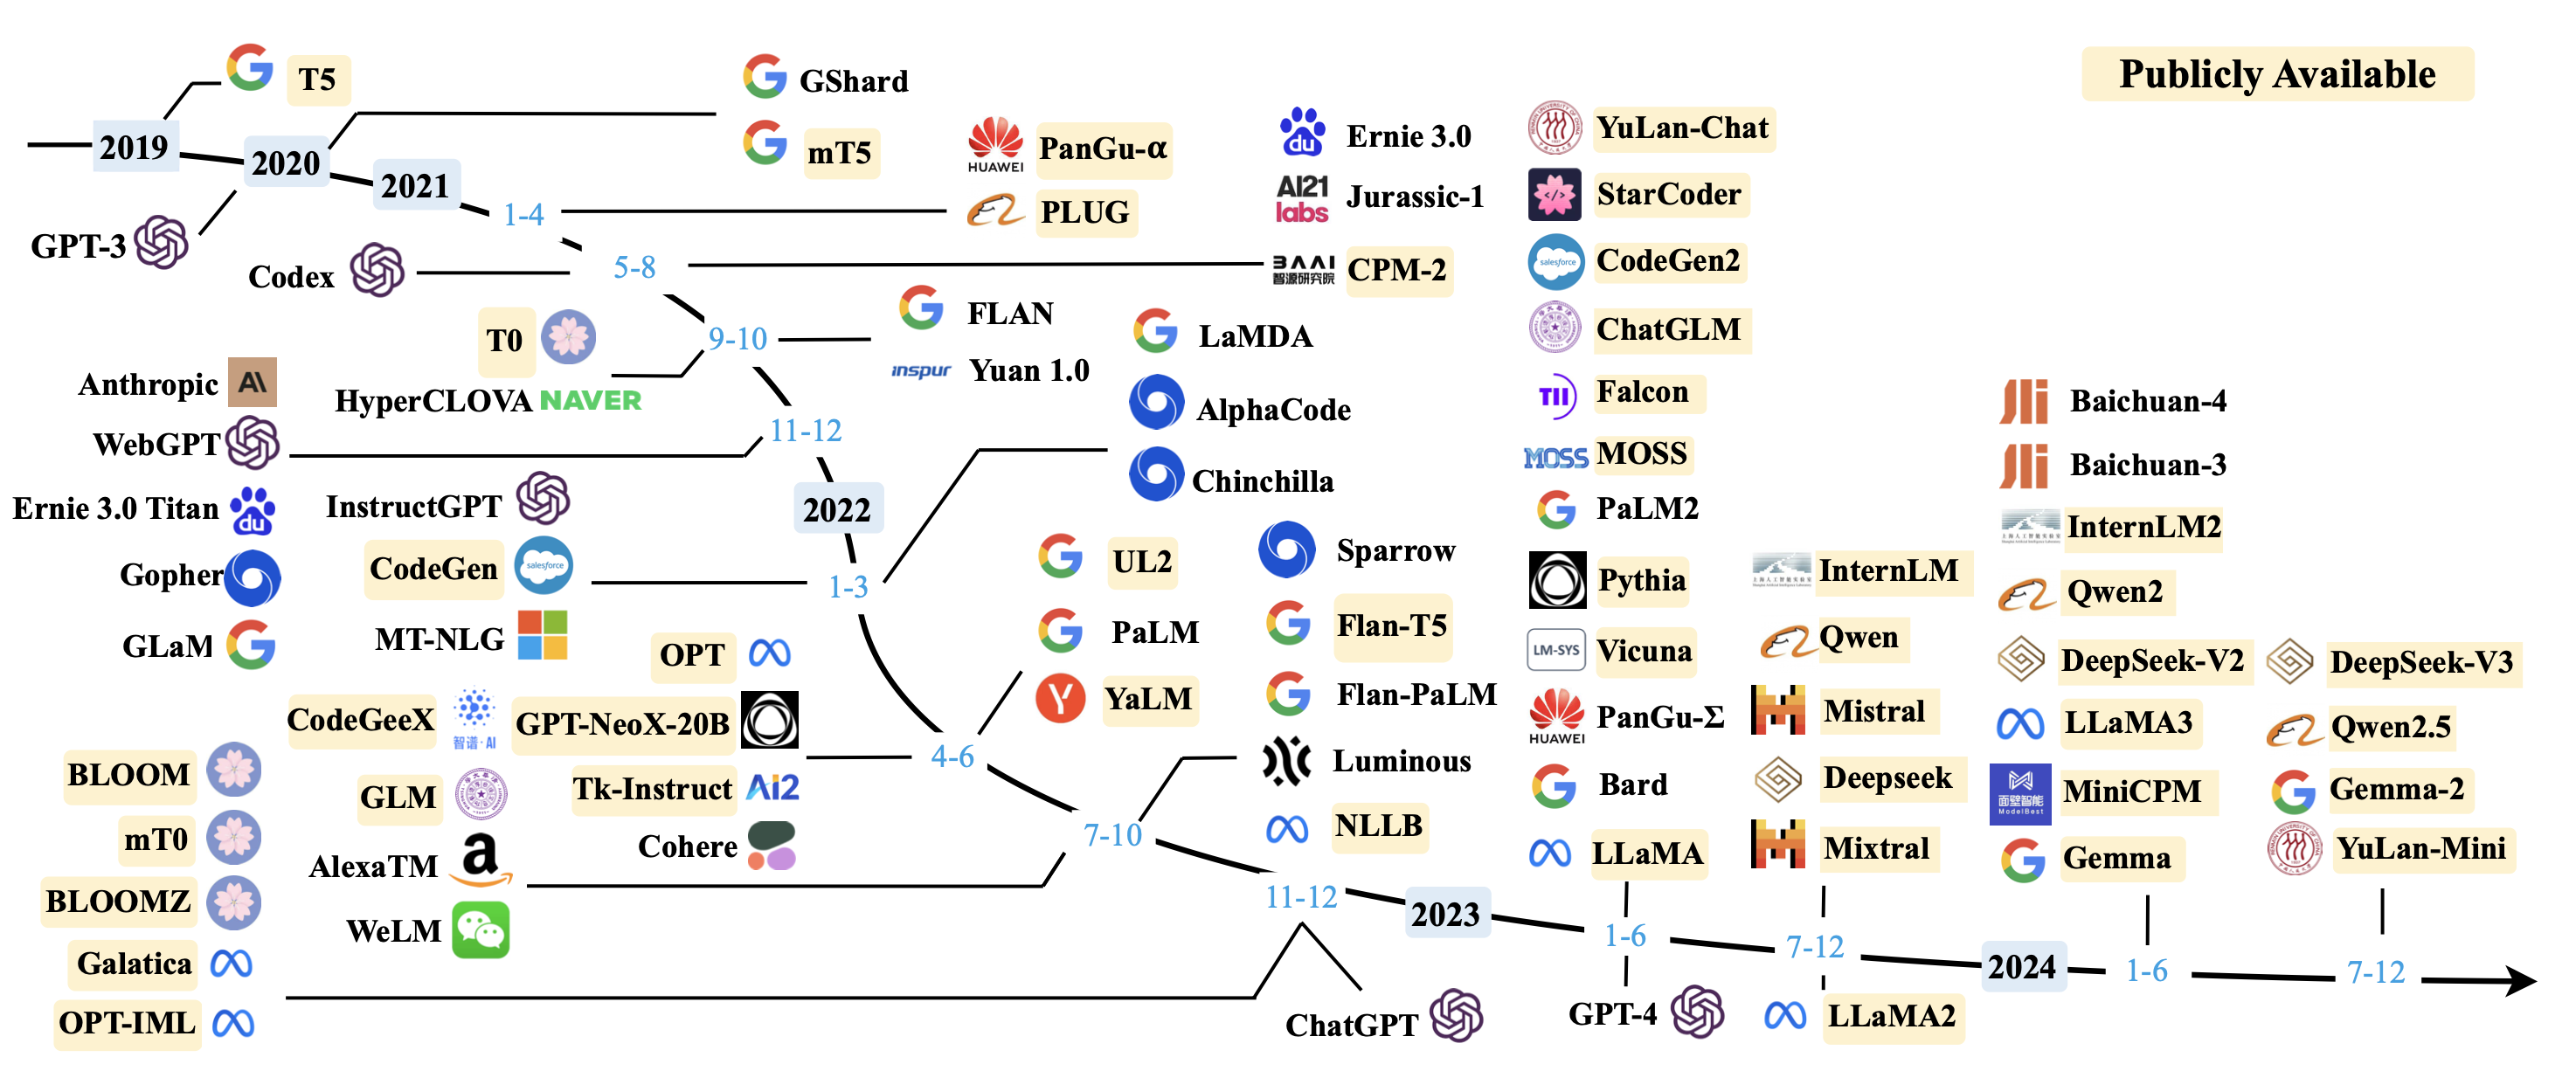
They describe instruction tuning runs on a 7B LLaMA model plus fine-grained ability evaluations, and note they are seeking computing power for more comprehensive experiments.Which LLMs does its catalog include?A timeline plus a categorized list of open and closed models — T5, BLOOM, GLM, LLaMA, ChatGLM, Vicuna, Mistral on the public side; GPT-3, LaMDA, Gopher and MT-NLG (530B) among closed ones — each with release date, parameter size, and link.
A timeline plus a categorized list of open and closed models — T5, BLOOM, GLM, LLaMA, ChatGLM, Vicuna, Mistral on the public side; GPT-3, LaMDA, Gopher and MT-NLG (530B) among closed ones — each with release date, parameter size, and link.What does the new long CoT reasoning chapter cover?The reasoning patterns and advantages of the long CoT paradigm, how such data is constructed (distillation, search-based synthesis, multi-agent collaboration), the two training methods (long CoT instruction tuning and scaled reinforcement learning), and recent test-time scaling efforts.
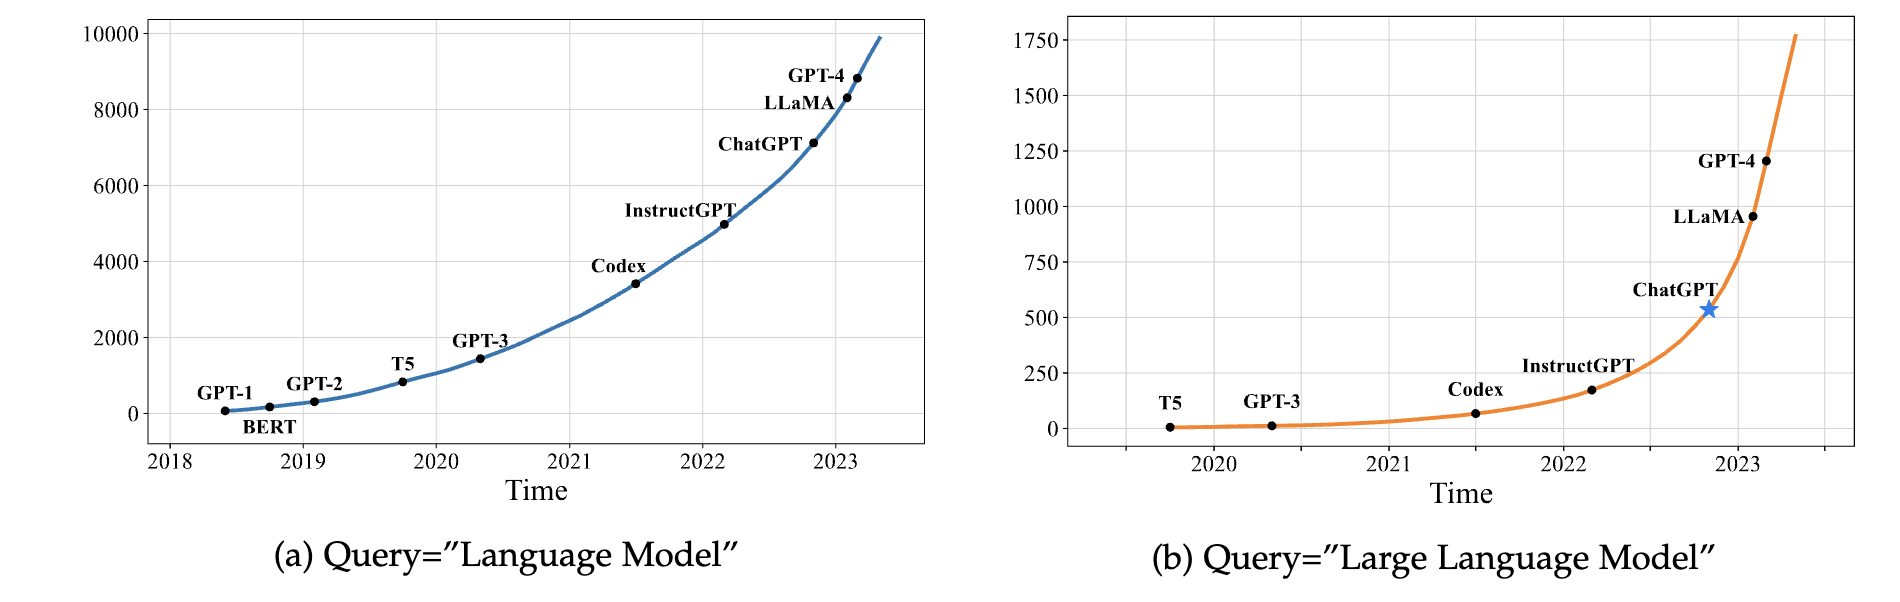
The reasoning patterns and advantages of the long CoT paradigm, how such data is constructed (distillation, search-based synthesis, multi-agent collaboration), the two training methods (long CoT instruction tuning and scaled reinforcement learning), and recent test-time scaling efforts.Why does the README show a chart of arXiv paper counts?To illustrate the field's boom: after ChatGPT's release, the average number of daily arXiv papers mentioning 'large language model' in title or abstract jumped from 0.40 to 8.58 per day.
To illustrate the field's boom: after ChatGPT's release, the average number of daily arXiv papers mentioning 'large language model' in title or abstract jumped from 0.40 to 8.58 per day.Does it offer anything practical beyond paper lists?Yes — a collection of prompt design tips with their ingredients and principles (open for contributions via issues), plus write-ups of the instruction tuning and ability evaluation experiments.
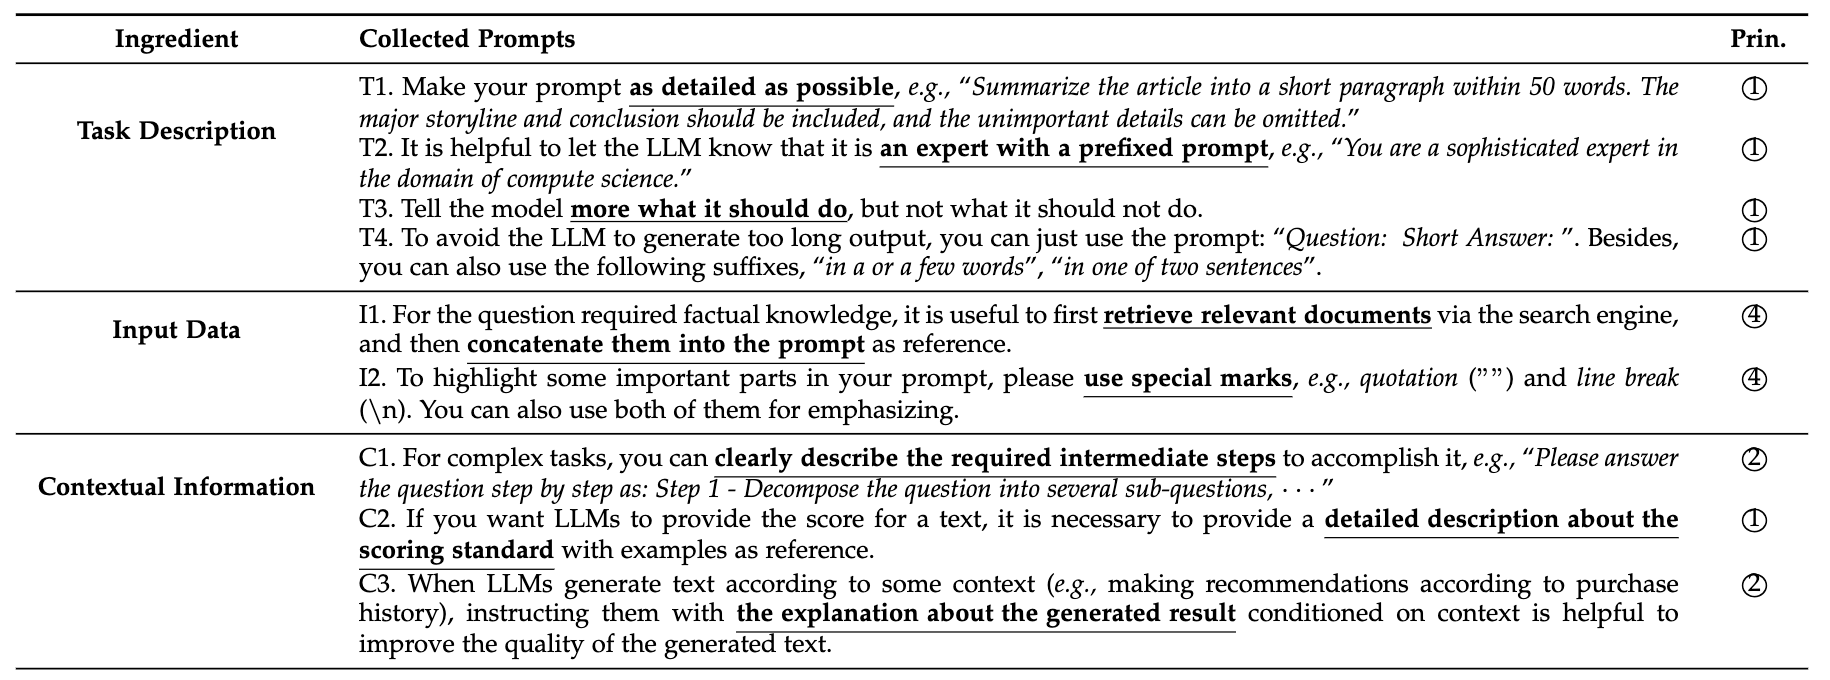
Yes — a collection of prompt design tips with their ingredients and principles (open for contributions via issues), plus write-ups of the instruction tuning and ability evaluation experiments.What are similar projects?Awesome-Multimodal-Large-Language-Models, Foundations-of-LLMs, LLMsPracticalGuide, llm_interview_note, Prompt-Engineering-Guide, LLMs-from-scratch, Awesome-LLM, open-llms
Awesome-Multimodal-Large-Language-Models, Foundations-of-LLMs, LLMsPracticalGuide, llm_interview_note, Prompt-Engineering-Guide, LLMs-from-scratch, Awesome-LLM, open-llmsWhich topics is it in?in-context-learning, chain-of-thought, instruction-tuning, rlhf, reasoning, llms, papers, natural-language-processing, academic, chatgpt, large-language-models, prompt-engineering
in-context-learning, chain-of-thought, instruction-tuning, rlhf, reasoning, llms, papers, natural-language-processing, academic, chatgpt, large-language-models, prompt-engineering