AI Research Skills Library
The most comprehensive open-source skills library enabling AI agents to autonomously conduct AI research — from idea to paper


98 Skills Powering AI Research in 2026
View All 23 Categories
|
|
|
| Autoresearch (1) |
Ideation (2) |
ML Paper Writing (2) |
| Model Architecture (5) |
Fine-Tuning (4) |
Post-Training (8) |
| Distributed Training (6) |
Optimization (6) |
Inference (4) |
| Tokenization (2) |
Data Processing (2) |
Evaluation (3) |
| Safety & Alignment (4) |
Agents (4) |
RAG (5) |
| Multimodal (7) |
Prompt Engineering (4) |
MLOps (3) |
| Observability (2) |
Infrastructure (3) |
Mech Interp (4) |
| Emerging Techniques (6) |
Agent-Native Research Artifact (3) |
|
Table of Contents
Our Mission
We enable AI agents to autonomously conduct AI research — from literature survey and idea generation through experiment execution to paper writing. The library provides both the research orchestration layer (autoresearch, ideation, paper writing) and the engineering skills (training, evaluation, deployment) needed at each stage.
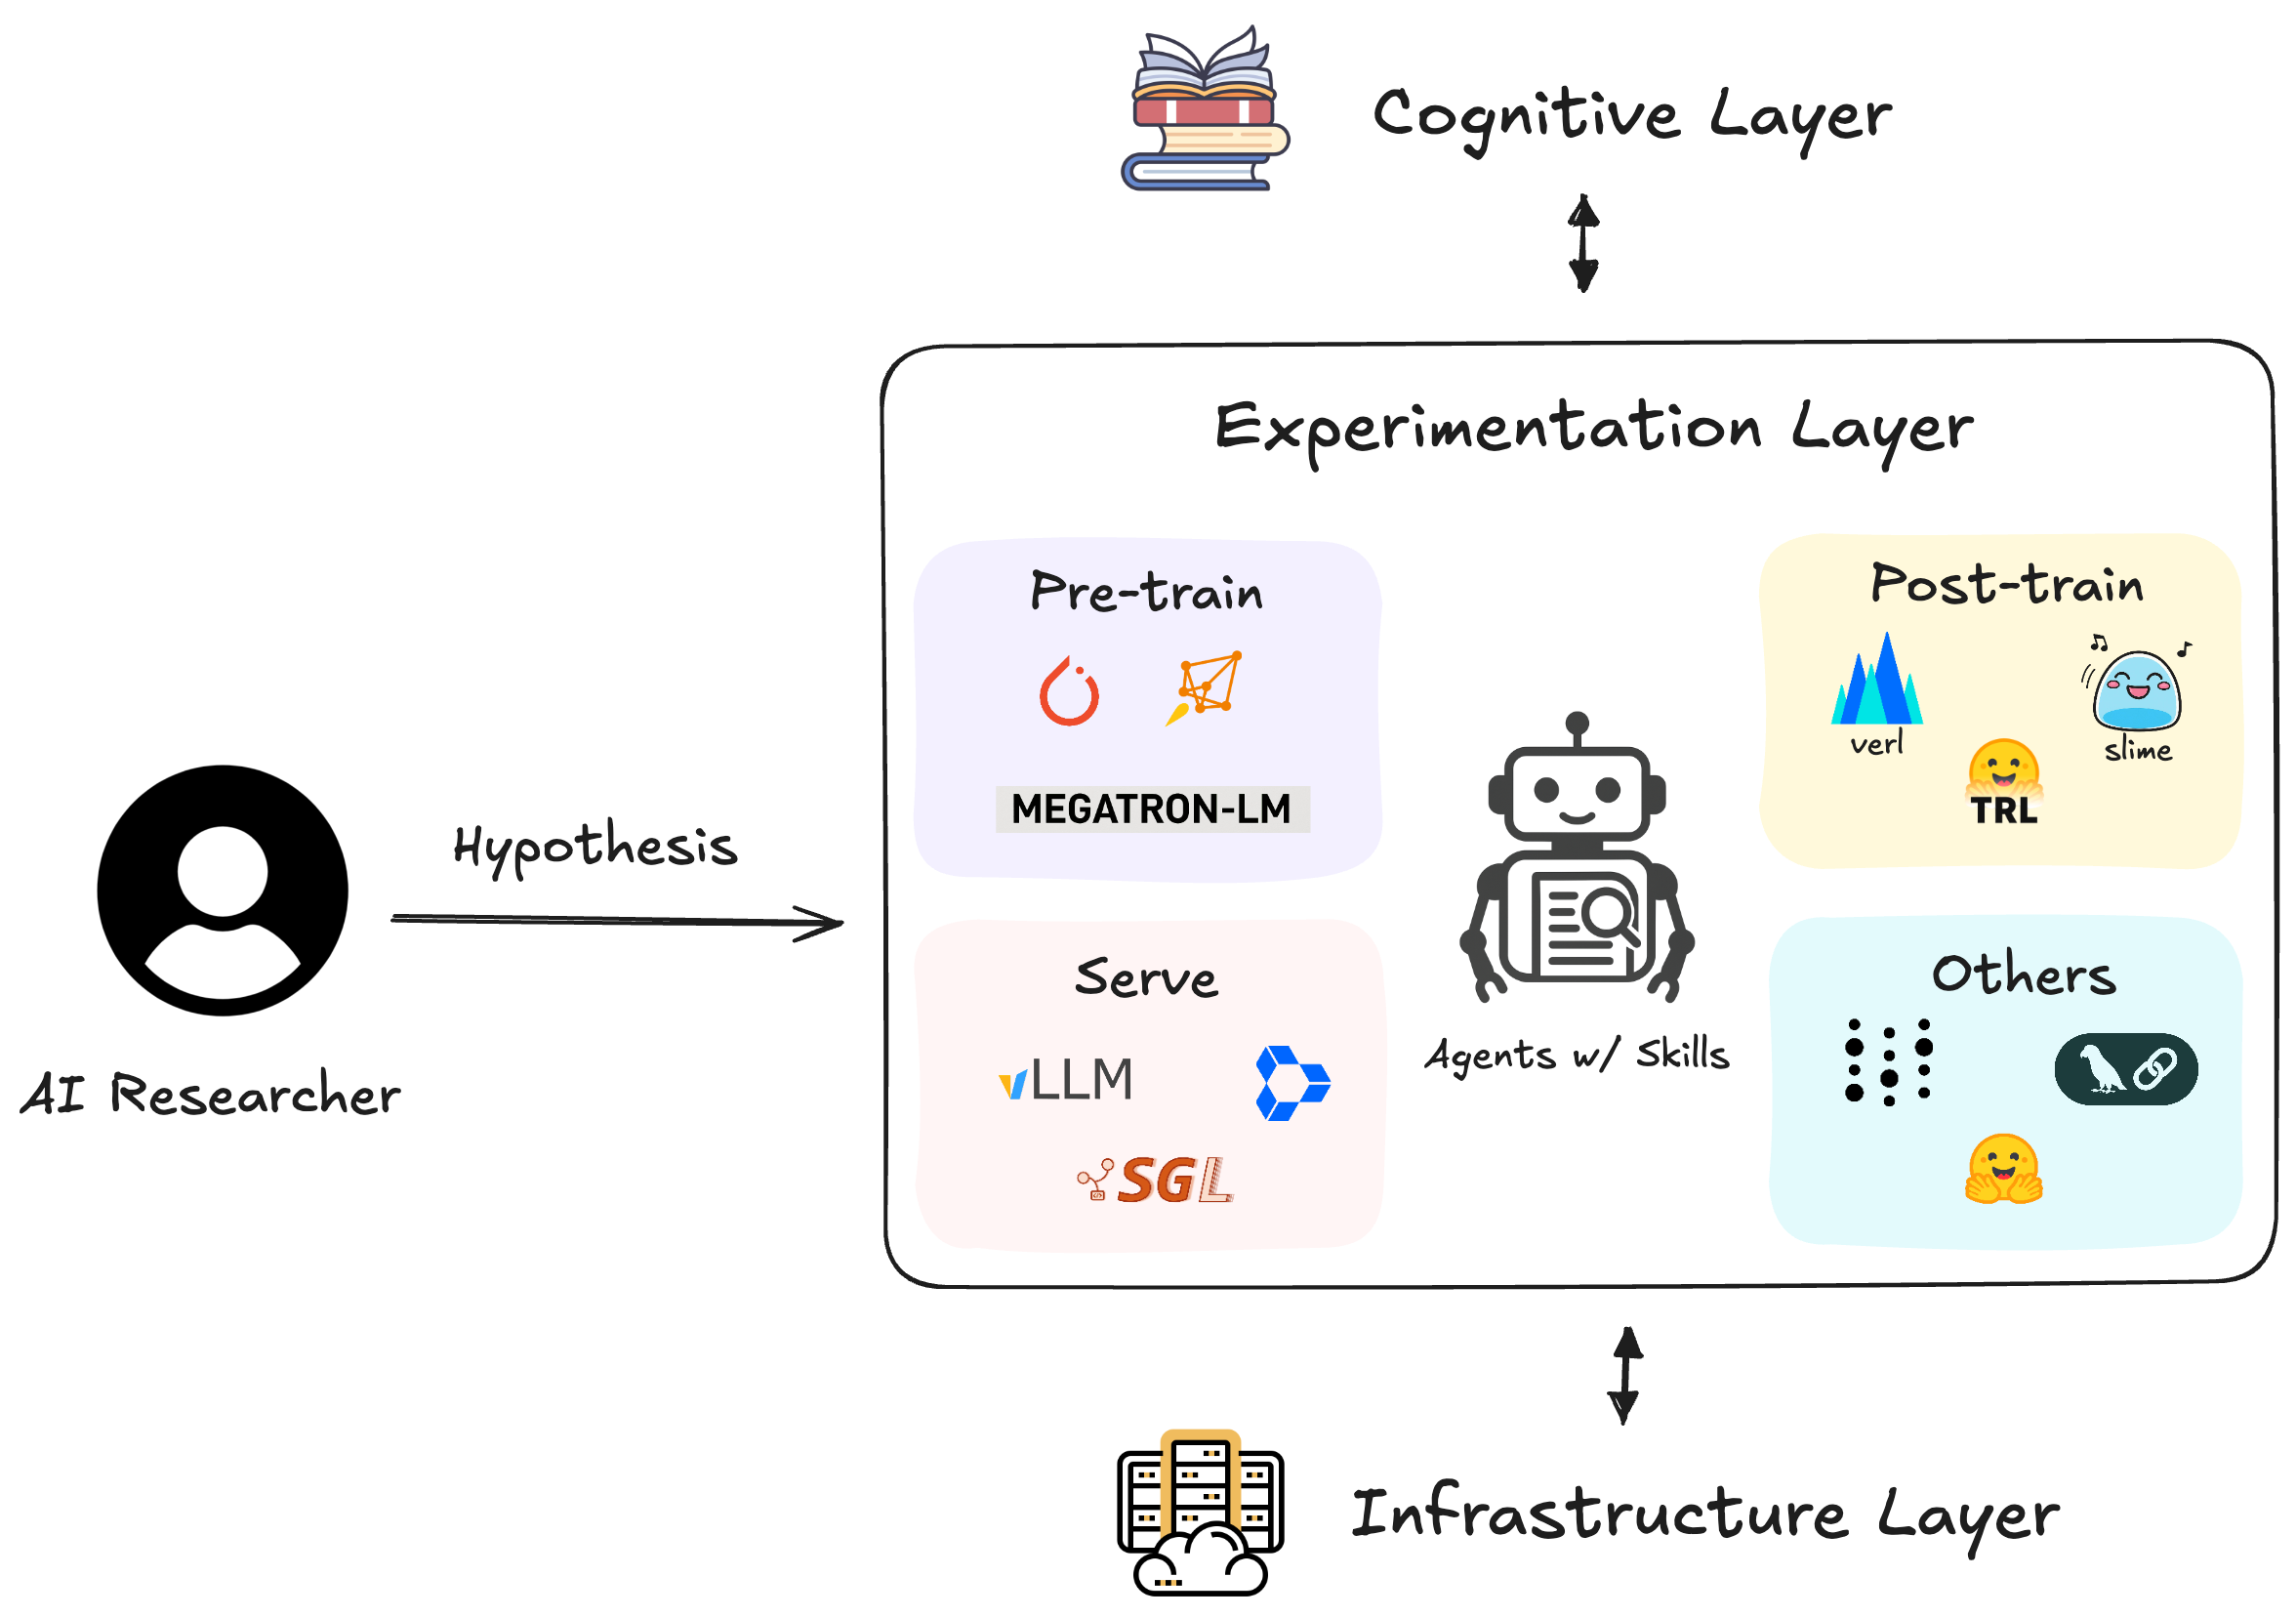
System diagram of an AI research agent
Path Towards AI Research Agent
Modern AI research requires mastering dozens of specialized tools and frameworks.
AI Researchers spend more time debugging infrastructure than testing hypotheses — slowing the pace of scientific discovery.
We provide a comprehensive skills library that enables AI agents to autonomously conduct the full research lifecycle — from brainstorming ideas to writing the paper.
- Autonomous Research - The autoresearch skill orchestrates the entire research workflow using a two-loop architecture, routing to domain skills as needed
- Specialized Expertise - Each domain skill provides deep, production-ready knowledge of a specific framework (Megatron-LM, vLLM, TRL, etc.)
- End-to-End Coverage - 98 skills spanning the full AI research lifecycle, from ideation and literature survey to experiments and paper writing
- Research-Grade Quality - Documentation sourced from official repos, real GitHub issues, and battle-tested production workflows
Available AI Research Engineering Skills
Quality over quantity: Each skill provides comprehensive, expert-level guidance with real code examples, troubleshooting guides, and production-ready workflows.
📦 Quick Install (Recommended)
For humans — interactive installer with one command:
npx @orchestra-research/ai-research-skills
For AI agents — point your agent to the welcome doc and it handles the rest:
Read https://www.orchestra-research.com/ai-research-skills/welcome.md and follow the instructions to install and use AI Research Skills.
This installs all 98 skills, loads the autoresearch orchestration layer, and starts autonomous research.
What the installer does
- Auto-detects your installed coding agents (Claude Code, Hermes Agent, OpenCode, Qoder, Cursor, Gemini CLI, etc.)
- Installs skills to
~/.orchestra/skills/ with symlinks to each agent (falls back to copy on Windows)
- Offers everything, quickstart bundle, by category, or individual skills
- Updates installed skills with latest versions
- Uninstalls all or selected skills
CLI Commands
# Interactive installer (recommended)
npx @orchestra-research/ai-research-skills

# Direct commands
npx @orchestra-research/ai-research-skills list      # View installed skills
npx @orchestra-research/ai-research-skills update    # Update installed skills
Claude Code Marketplace (Alternative)
Install skill categories directly using the Claude Code CLI:
# Add the marketplace
/plugin marketplace add orchestra-research/AI-research-SKILLs

# Install by category (23 categories available)
/plugin install fine-tuning@ai-research-skills        # Axolotl, LLaMA-Factory, PEFT, Unsloth
/plugin install post-training@ai-research-skills      # TRL, GRPO, OpenRLHF, SimPO, verl, slime, miles, torchforge
/plugin install inference-serving@ai-research-skills  # vLLM, TensorRT-LLM, llama.cpp, SGLang
/plugin install distributed-training@ai-research-skills
/plugin install optimization@ai-research-skills
All 23 Categories (98 Skills)
| Category |
Skills |
Included |
| Autoresearch |
1 |
Autonomous research orchestration — central layer that manages the full lifecycle and routes to all other skills |
| Ideation |
2 |
Research Brainstorming, Creative Thinking |
| ML Paper Writing |
2 |
ML Paper Writing (LaTeX templates, citation verification), Academic Plotting |
| Model Architecture |
5 |
LitGPT, Mamba, NanoGPT, RWKV, TorchTitan |
| Tokenization |
2 |
HuggingFace Tokenizers, SentencePiece |
| Fine-Tuning |
4 |
Axolotl, LLaMA-Factory, PEFT, Unsloth |
| Mech Interp |
4 |
TransformerLens, SAELens, pyvene, nnsight |
| Data Processing |
2 |
NeMo Curator, Ray Data |
| Post-Training |
8 |
TRL, GRPO, OpenRLHF, SimPO, verl, slime, miles, torchforge |
| Safety |
4 |
Constitutional AI, LlamaGuard, NeMo Guardrails, Prompt Guard |
| Distributed |
6 |
DeepSpeed, FSDP, Accelerate, Megatron-Core, Lightning, Ray Train |
| Infrastructure |
3 |
Modal, Lambda Labs, SkyPilot |
| Optimization |
6 |
Flash Attention, bitsandbytes, GPTQ, AWQ, HQQ, GGUF |
| Evaluation |
3 |
lm-eval-harness, BigCode, NeMo Evaluator |
| Inference |
4 |
vLLM, TensorRT-LLM, llama.cpp, SGLang |
| MLOps |
3 |
W&B, MLflow, TensorBoard |
| Agents |
4 |
LangChain, LlamaIndex, CrewAI, AutoGPT |
| RAG |
5 |
Chroma, FAISS, Pinecone, Qdrant, Sentence Transformers |
| Prompt Eng |
4 |
DSPy, Instructor, Guidance, Outlines |
| Observability |
2 |
LangSmith, Phoenix |
| Multimodal |
7 |
CLIP, Whisper, LLaVA, BLIP-2, SAM, Stable Diffusion, AudioCraft |
| Emerging |
6 |
MoE, Model Merging, Long Context, Speculative Decoding, Distillation, Pruning |
| Agent-Native Research Artifact |
3 |
ARA Compiler, Research Manager, Rigor Reviewer |
View All 98 Skills in Details
🔬 Autoresearch (1 skill) — Central Orchestration Layer
- Autoresearch - Autonomous research orchestration using a two-loop architecture (inner optimization + outer synthesis). Manages the full lifecycle from literature survey to paper writing, routing to all domain-specific skills. Supports Claude Code /loop and OpenClaw heartbeat for continuous operation (390 lines + 3 refs)
🏗️ Model Architecture (5 skills)
- LitGPT - Lightning AI's 20+ clean LLM implementations with production training recipes (462 lines + 4 refs)
- Mamba - State-space models with O(n) complexity, 5× faster than Transformers (253 lines + 3 refs)
- RWKV - RNN+Transformer hybrid, infinite context, Linux Foundation project (253 lines + 3 refs)
- NanoGPT - Educational GPT in ~300 lines by Karpathy (283 lines + 3 refs)
- TorchTitan - PyTorch-native distributed training for Llama 3.1 with 4D parallelism
🔤 Tokenization (2 skills)
- HuggingFace Tokenizers - Rust-based, <20s/GB, BPE/WordPiece/Unigram algorithms (486 lines + 4 refs)
- SentencePiece - Language-independent, 50k sentences/sec, used by T5/ALBERT (228 lines + 2 refs)
🎯 Fine-Tuning (4 skills)
- Axolotl - YAML-based fine-tuning with 100+ models (156 lines + 4 refs)
- LLaMA-Factory - WebUI no-code fine-tuning (78 lines + 5 refs)
- Unsloth - 2x faster QLoRA fine-tuning (75 lines + 4 refs)
- PEFT - Parameter-efficient fine-tuning with LoRA, QLoRA, DoRA, 25+ methods (431 lines + 2 refs)
🔬 Mechanistic Interpretability (4 skills)
- TransformerLens - Neel Nanda's library for mech interp with HookPoints, activation caching (346 lines + 3 refs)
- SAELens - Sparse Autoencoder training and analysis for feature discovery (386 lines + 3 refs)
- pyvene - Stanford's causal intervention library with declarative configs (473 lines + 3 refs)
- nnsight - Remote interpretability via NDIF, run experiments on 70B+ models (436 lines + 3 refs)
📊 Data Processing (2 skills)
- Ray Data - Distributed ML data processing, streaming execution, GPU support (318 lines + 2 refs)
- NeMo Curator - GPU-accelerated data curation, 16× faster deduplication (375 lines + 2 refs)
🎓 Post-Training (8 skills)
- TRL Fine-Tuning - Transformer Reinforcement Learning (447 lines + 4 refs)
- GRPO-RL-Training (TRL) - Group Relative Policy Optimization with TRL (569 lines, gold standard)
- OpenRLHF - Full RLHF pipeline with Ray + vLLM (241 lines + 4 refs)
- SimPO - Simple Preference Optimization, no reference model needed (211 lines + 3 refs)
- verl - ByteDance's HybridFlow RL framework, FSDP/Megatron + vLLM/SGLang backends (389 lines + 2 refs)
- slime - THUDM's Megatron+SGLang framework powering GLM-4.x models (464 lines + 2 refs)
- miles - Enterprise fork of slime with FP8, INT4, speculative RL for MoE training (315 lines + 2 refs)
- torchforge - Meta's PyTorch-native RL with Monarch+TorchTitan+vLLM (380 lines + 2 refs)
🛡️ Safety & Alignment (4 skills)
- Constitutional AI - AI-driven self-improvement via principles (282 lines)
- LlamaGuard - Safety classifier for LLM inputs/outputs (329 lines)
- NeMo Guardrails - Programmable guardrails with Colang (289 lines)
- Prompt Guard - Meta's 86M prompt injection & jailbreak detector, 99%+ TPR, <2ms GPU (313 lines)
⚡ Distributed Training (6 skills)
- Megatron-Core - NVIDIA's framework for training 2B-462B param models with 47% MFU on H100 (359 lines + 4 refs)
- DeepSpeed - Microsoft's ZeRO optimization (137 lines + 9 refs)
- PyTorch FSDP2 - Fully Sharded Data Parallel v2 with
fully_shard and DTensor (231 lines + 12 refs)
- Accelerate - HuggingFace's 4-line distributed training API (324 lines + 3 refs)
- PyTorch Lightning - High-level training framework with Trainer class (339 lines + 3 refs)
- Ray Train - Multi-node orchestration and hyperparameter tuning (399 lines + 1 ref)
🚀 Optimization (6 skills)
- Flash Attention - 2-4x faster attention with memory efficiency (359 lines + 2 refs)
- bitsandbytes - 8-bit/4-bit quantization for 50-75% memory reduction (403 lines + 3 refs)
- GPTQ - 4-bit post-training quantization, 4× memory reduction, <2% accuracy loss (443 lines + 3 refs)
- AWQ - Activation-aware weight quantization, 4-bit with minimal accuracy loss (310 lines + 2 refs)
- HQQ - Half-Quadratic Quantization, no calibration data needed, multi-backend (370 lines + 2 refs)
- GGUF - llama.cpp quantization format, K-quant methods, CPU/Metal inference (380 lines + 2 refs)
📊 Evaluation (3 skills)
- lm-evaluation-harness - EleutherAI's standard for benchmarking LLMs across 60+ tasks (482 lines + 4 refs)
- BigCode Evaluation Harness - Code model benchmarking with HumanEval, MBPP, MultiPL-E, pass@k metrics (406 lines + 3 refs)
- NeMo Evaluator - NVIDIA's enterprise platform for 100+ benchmarks across 18+ harnesses with multi-backend execution (454 lines + 4 refs)
☁️ Infrastructure (3 skills)
- Modal - Serverless GPU cloud with Python-native API, T4-H200 on-demand (342 lines + 2 refs)
- SkyPilot - Multi-cloud orchestration across 20+ providers with spot recovery (390 lines + 2 refs)
- Lambda Labs - Reserved/on-demand GPU cloud with H100/A100, persistent filesystems (390 lines + 2 refs)
🔥 Inference & Serving (4 skills)
- vLLM - High-throughput LLM serving with PagedAttention (356 lines + 4 refs, production-ready)
- TensorRT-LLM - NVIDIA's fastest inference, 24k tok/s, FP8/INT4 quantization (180 lines + 3 refs)
- llama.cpp - CPU/Apple Silicon inference, GGUF quantization (251 lines + 3 refs)
- SGLang - Structured generation with RadixAttention, 5-10× faster for agents (435 lines + 3 refs)
🤖 Agents (4 skills)
- LangChain - Most popular agent framework, 500+ integrations, ReAct pattern (658 lines + 3 refs, production-ready)
- LlamaIndex - Data framework for LLM apps, 300+ connectors, RAG-focused (535 lines + 3 refs)
- CrewAI - Multi-agent orchestration, role-based collaboration, autonomous workflows (498 lines + 3 refs)
- AutoGPT - Autonomous AI agent platform, visual workflow builder, continuous execution (400 lines + 2 refs)
🔍 RAG (5 skills)
- Chroma - Open-source embedding database, local/cloud, 24k stars (385 lines + 1 ref)
- FAISS - Facebook's similarity search, billion-scale, GPU acceleration (295 lines)
- Sentence Transformers - 5000+ embedding models, multilingual, 15k stars (370 lines)
- Pinecone - Managed vector database, auto-scaling, <100ms latency (410 lines)
- Qdrant - High-performance vector search, Rust-powered, hybrid search with filtering (493 lines + 2 refs)
🎨 Multimodal (7 skills)
- CLIP - OpenAI's vision-language model, zero-shot classification, 25k stars (320 lines)
- Whisper - Robust speech recognition, 99 languages, 73k stars (395 lines)
- LLaVA - Vision-language assistant, image chat, GPT-4V level (360 lines)
- Stable Diffusion - Text-to-image generation via HuggingFace Diffusers, SDXL, ControlNet (380 lines + 2 refs)
- Segment Anything - Meta's SAM for zero-shot image segmentation with points/boxes (500 lines + 2 refs)
- BLIP-2 - Vision-language pretraining with Q-Former, image captioning, VQA (500 lines + 2 refs)
- AudioCraft - Meta's MusicGen/AudioGen for text-to-music and text-to-sound (470 lines + 2 refs)
🎯 Prompt Engineering (4 skills)
- DSPy - Declarative prompt programming with optimizers, Stanford NLP, 22k stars (438 lines + 3 refs)
- Instructor - Structured LLM outputs with Pydantic validation, 15k stars (726 lines + 3 refs)
- Guidance - Constrained generation with regex/grammars, Microsoft Research, 18k stars (485 lines + 3 refs)
- Outlines - Structured text with FSM, zero-overhead, 8k stars (601 lines + 3 refs)
📊 MLOps (3 skills)
- Weights & Biases - Experiment tracking, sweeps, artifacts, model registry (427 lines + 3 refs)
- MLflow - Model registry, tracking, deployment, autologging (514 lines + 3 refs)
- TensorBoard - Visualization, profiling, embeddings, scalars/images (538 lines + 3 refs)
👁️ Observability (2 skills)
- LangSmith - LLM observability, tracing, evaluation, monitoring for AI apps (422 lines + 2 refs)
- Phoenix - Open-source AI observability with OpenTelemetry tracing and LLM evaluation (380 lines + 2 refs)
🔬 Emerging Techniques (6 skills)
- MoE Training - Mixture of Experts training with DeepSpeed, Mixtral 8x7B, 5× cost reduction (515 lines + 3 refs)
- Model Merging - Combine models with TIES, DARE, SLERP using mergekit (528 lines + 3 refs)
- Long Context - Extend context windows with RoPE, YaRN, ALiBi, 32k-128k tokens (624 lines + 3 refs)
- Speculative Decoding - 1.5-3.6× faster inference with Medusa, Lookahead (379 lines)
- Knowledge Distillation - Compress models 70B→7B with MiniLLM, temperature scaling (424 lines)
- Model Pruning - 50% sparsity with Wanda, SparseGPT, <1% accuracy loss (417 lines)
📝 ML Paper Writing (2 skills)
- **[ML Paper Writing](20-ml-paper-writ

 Это библиотека с открытым исходным кодом, в которой 98 навыков для исследований и разработки в области ИИ. Они превращают агента Claude Code, Codex или Gemini CLI в полноценного исследователя ИИ: от генерации идей до написания статьи.