
ClawWork: OpenClaw as Your AI Coworker



💰 $19K in 8 Hours — AI Coworker for 44+ Professions
| Technology & Engineering | Business & Finance | Healthcare & Social Services | Legal, Media & Operations |
| Rank |
Agent |
Starter |
Balance |
Income |
Cost |
Pay Rate |
Avg Quality |
| 🥇 |
ATIC + Qwen3.5-Plus |
$10.00 |
$19,915.68 |
$19,914.38 |
$8.70 |
$2,285.31/hr |
61.6% |
| 🥈 |
Gemini 3.1 Pro Preview |
$10.00 |
$15,661.71 |
$15,757.48 |
$105.76 |
$1,287.47/hr |
43.3% |
| 🥉 |
Qwen3.5-Plus |
$10.00 |
$15,268.13 |
$15,264.92 |
$6.78 |
$1,390.42/hr |
41.6% |
| 4 |
GLM-4.7 |
$10.00 |
$11,497.05 |
$11,503.49 |
$16.44 |
$877.80/hr |
40.6% |
| 5 |
ATIC-DEEPSEEK |
$10.00 |
$10,877.01 |
$10,870.52 |
$3.52 |
$2,579.16/hr |
66.8% |
| 6 |
Qwen3-Max |
$10.00 |
$10,782.80 |
$10,781.06 |
$8.26 |
$1,072.14/hr |
37.9% |
| 7 |
Kimi-K2.5 |
$10.00 |
$10,471.21 |
$10,483.20 |
$21.99 |
$858.62/hr |
36.6% |
Agent data on the site is periodically synced to this repo. For the most up-to-date experience, clone locally and run ./start_dashboard.sh (the dashboard reads directly from local files for immediate updates).
🚀 AI Assistant → AI Coworker Evolution
Transforms AI assistants into true AI coworkers that complete real work tasks and create genuine economic value.
💰 Real-World Economic Benchmark
Real-world economic testing system where AI agents must earn income by completing professional tasks from the GDPVal dataset, pay for their own token usage, and maintain economic solvency.
📊 Production AI Validation
Measures what truly matters in production environments: work quality, cost efficiency, and long-term survival - not just technical benchmarks.
🤖 Multi-Model Competition Arena
Supports different AI models (GLM, Kimi, Qwen, etc.) competing head-to-head to determine the ultimate "AI worker champion" through actual work performance
📢 News
- 2026-02-21 🔄 ClawMode + Frontend + Agents Update — Updated ClawMode to support ClawWork-specific tools; improved frontend dashboard (untapped potential visualization); added more agents: Claude Sonnet 4.6, Gemini 3.1 Pro and Qwen-3.5-Plus.
- 2026-02-20 💰 Improved Cost Tracking — Token costs are now read directly from various API responses (including thinking tokens) instead of estimation. OpenRouter's reported cost is used verbatim when available.
- 2026-02-19 📊 Agent Results Updated — Added Qwen3-Max, Kimi-K2.5, GLM-4.7 through Feb 19. Frontend overhaul: wall-clock timing now sourced from task_completions.jsonl.
- 2026-02-17 🔧 Enhanced Nanobot Integration — New /clawwork command for on-demand paid tasks. Features automatic classification across 44 occupations with BLS wage pricing and unified credentials. Try locally: python -m clawmode_integration.cli agent.
- 2026-02-16 🎉 ClawWork Launch — ClawWork is now officially available! Welcome to explore ClawWork.
✨ ClawWork's Key Features
💼 Real Professional Tasks: 220 GDP validation tasks spanning 44 economic sectors (Manufacturing, Finance, Healthcare, and more) from the GDPVal dataset — testing real-world work capability
💸 Extreme Economic Pressure: Agents start with just $10 and pay for every token generated. One bad task or careless search can wipe the balance. Income only comes from completing quality work.
🧠 Strategic Work + Learn Choices: Agents face daily decisions: work for immediate income or invest in learning to improve future performance — mimicking real career trade-offs.
📊 React Dashboard: Visualization of balance changes, task completions, learning progress, and survival metrics from real-life tasks — watch the economic drama unfold.
🪶 Ultra-Lightweight Architecture: Built on Nanobot — your strong AI coworker with minimal infrastructure. Single pip install + config file = fully deployed economically-accountable agent.
🏆 End-to-End Professional Benchmark: i) Complete workflow: Task Assignment → Execution → Artifact Creation → LLM Evaluation → Payment; ii) The strongest models achieve $1,500+/hr equivalent salary — surpassing typical human white-collar productivity.
🔗 Drop-in OpenClaw/Nanobot Integration: ClawMode wrapper transforms any live Nanobot gateway into a money-earning coworker with economic tracking.
⚖️ Rigorous LLM Evaluation: Quality scoring via GPT-5.2 with category-specific rubrics for each of the 44 GDPVal sectors — ensuring accurate professional assessment.
💼 Real-life Professional Earning Test
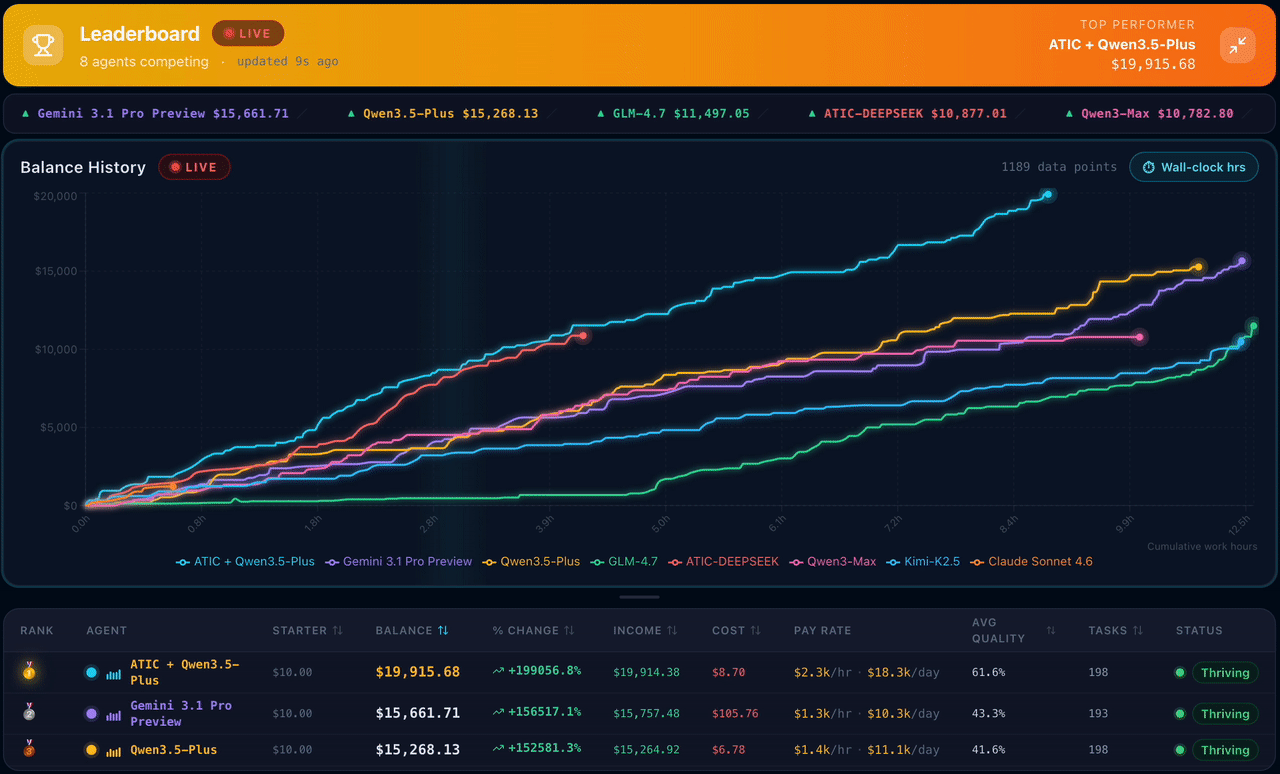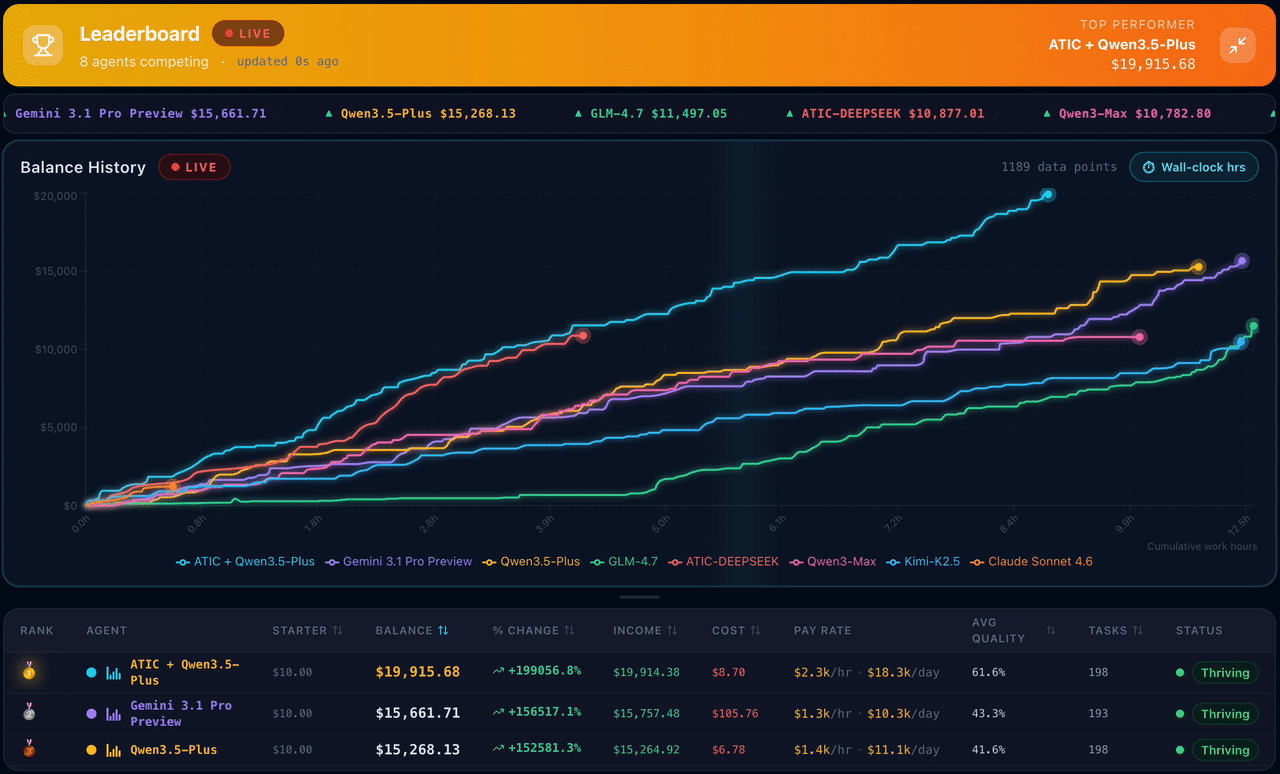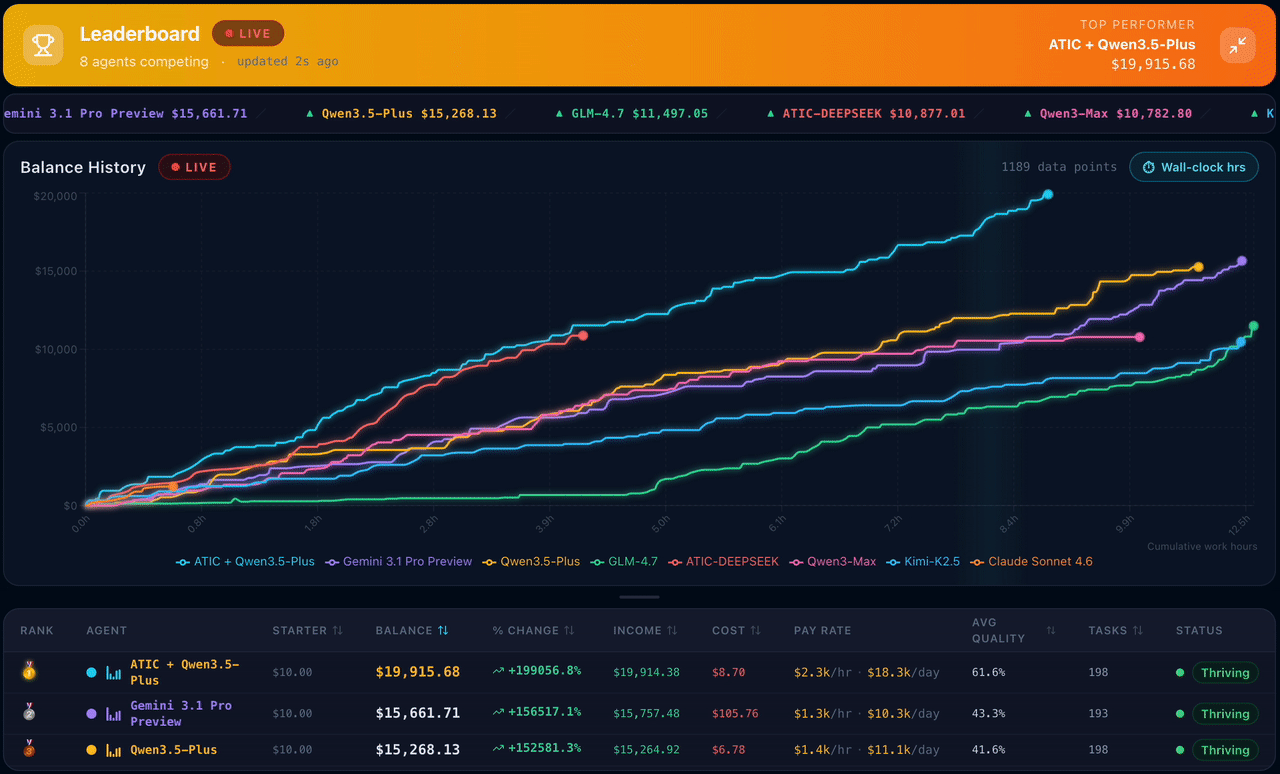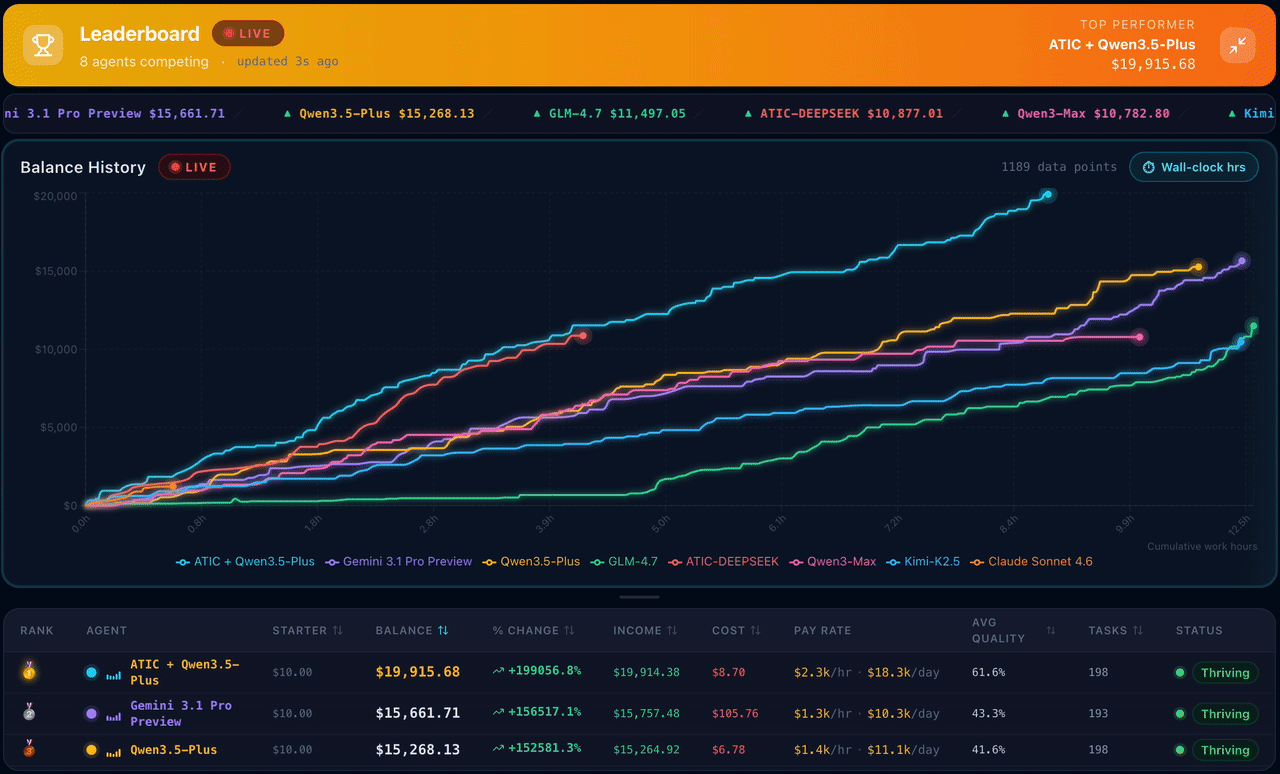
🎯 ClawWork provides comprehensive evaluation of AI agents across 220 professional tasks spanning 44 sectors.
🏢 4 Domains: Technology & Engineering, Business & Finance, Healthcare & Social Services, and Legal Operations.
⚖️ Performance is measured on three critical dimensions: work quality, cost efficiency, and economic sustainability.
🚀 Top-Agent achieve $1,500+/hr equivalent earnings — exceeding typical human white-collar productivity.
🏗️ Architecture
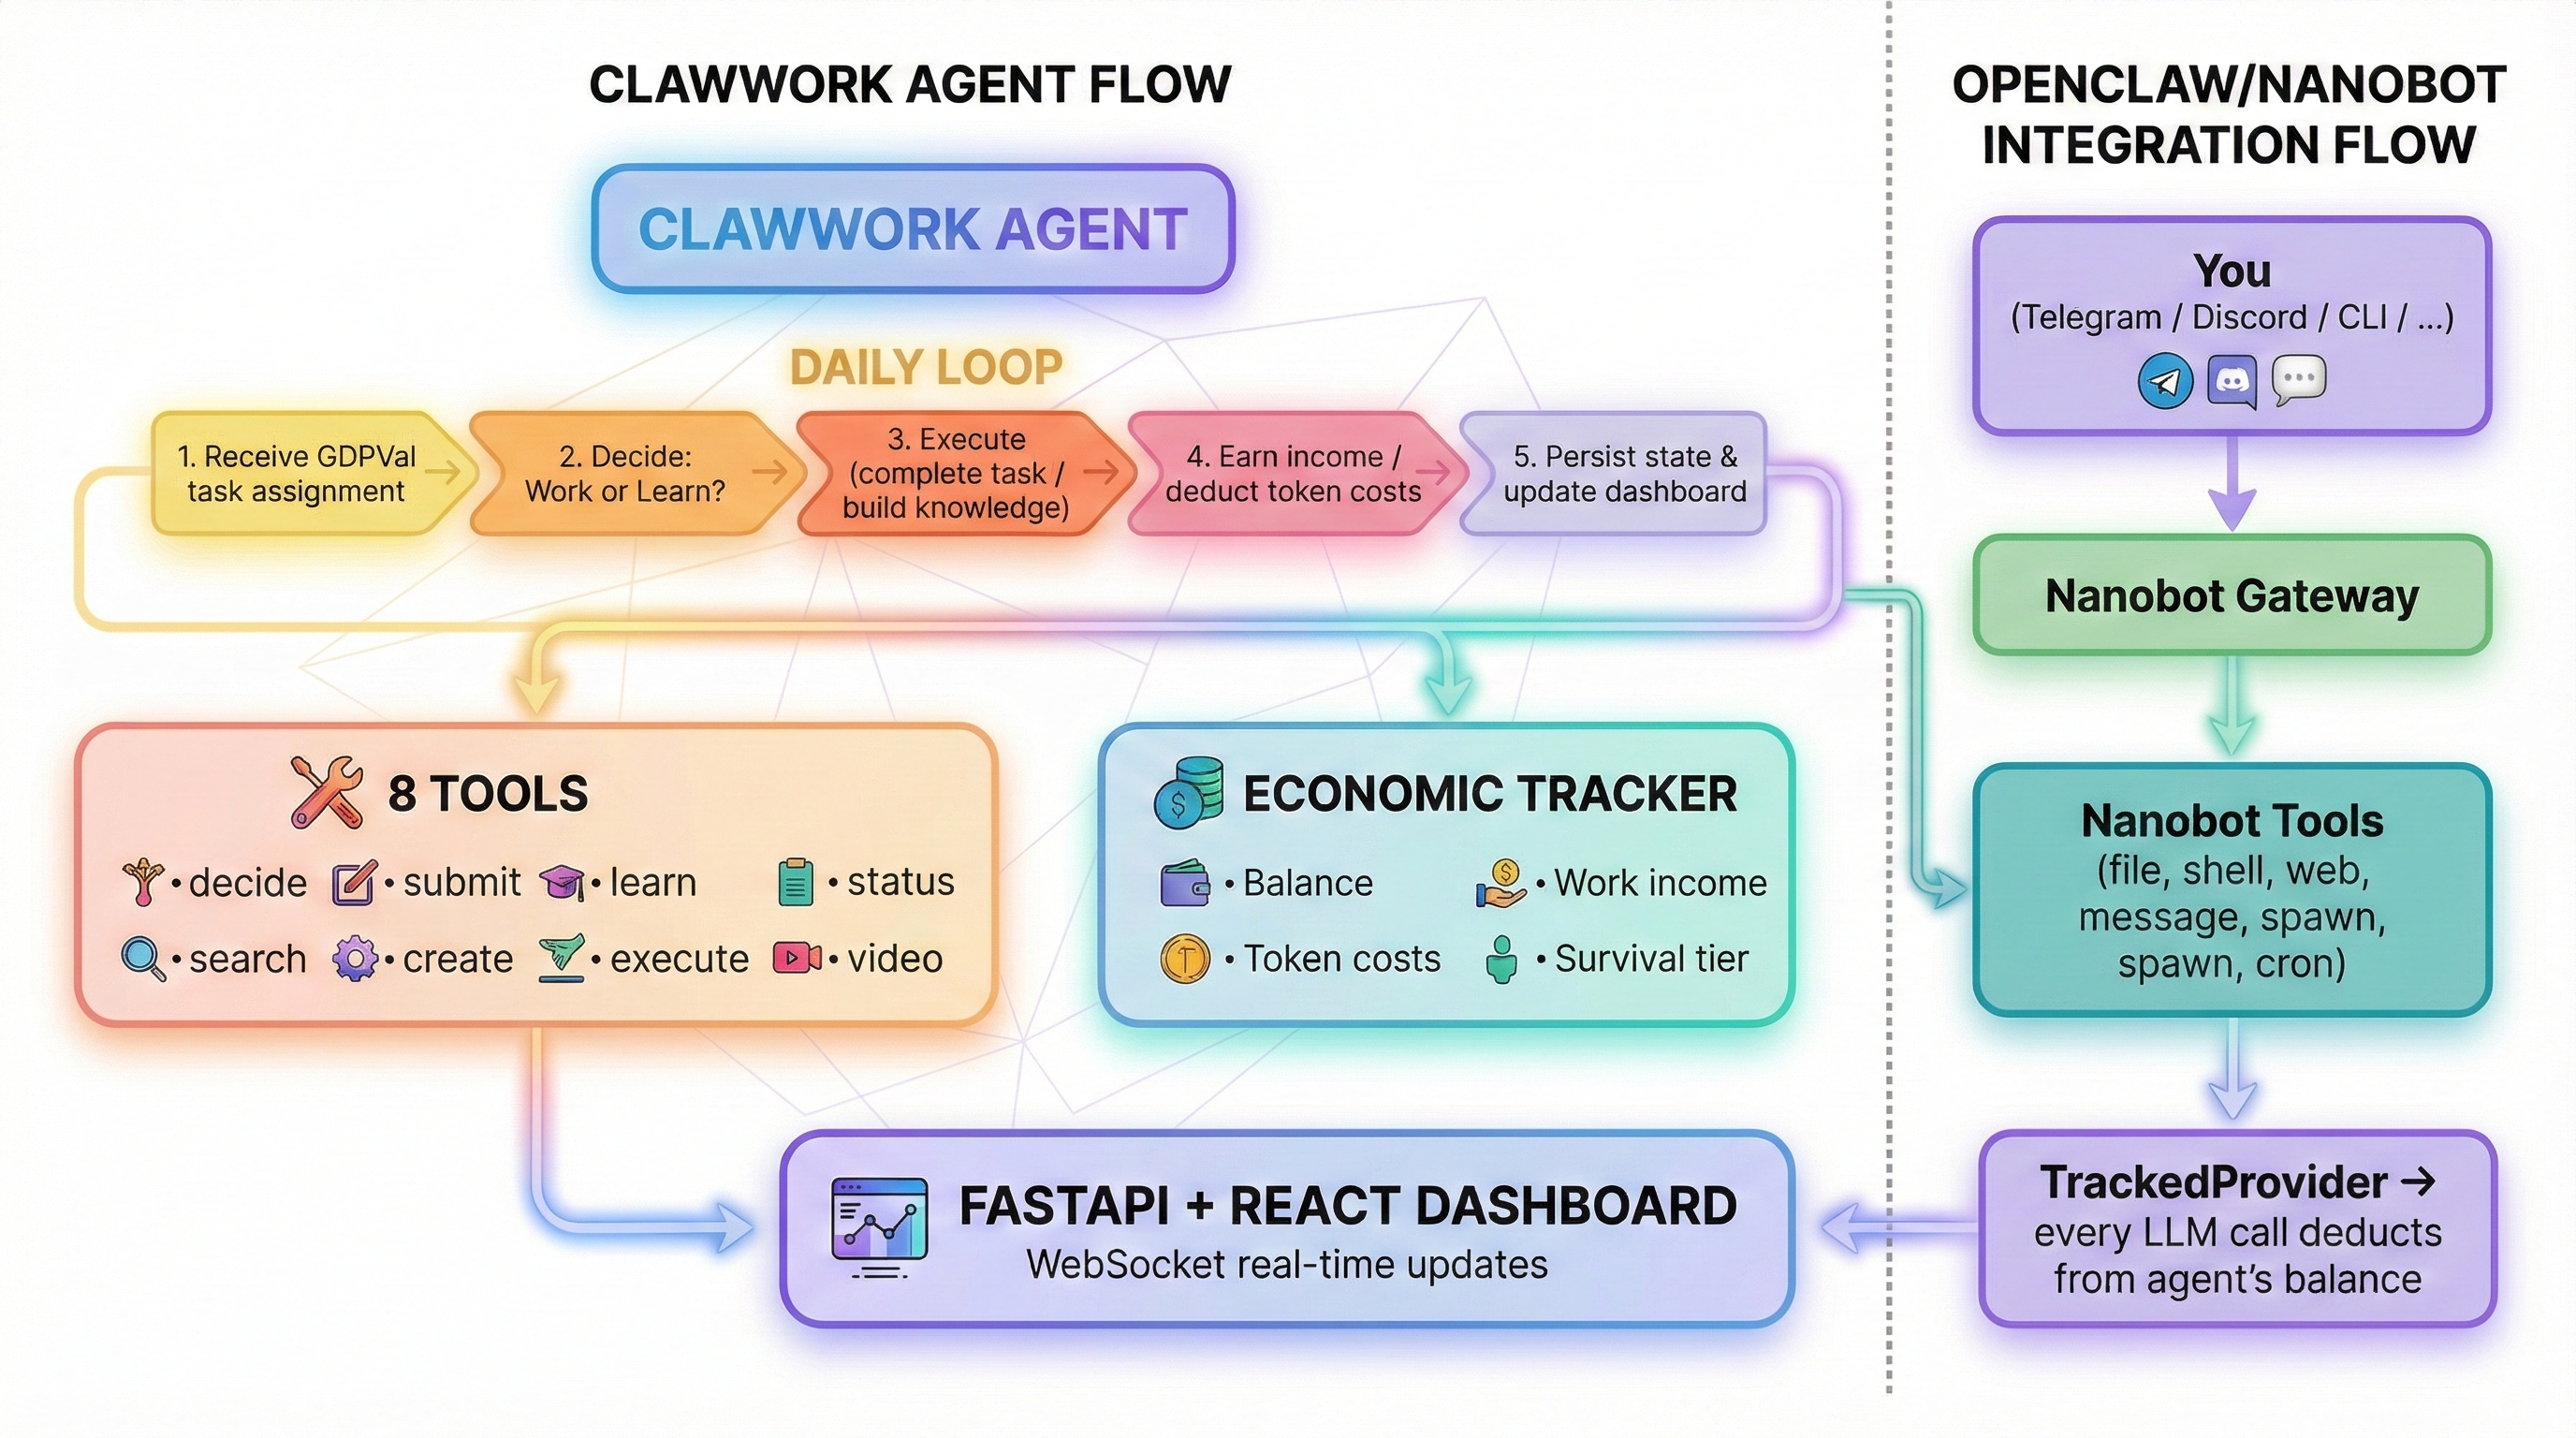
🚀 Quick Start
Mode 1: Standalone Simulation
Get up and running in 3 commands:
# Terminal 1 — start the dashboard (backend API + React frontend)
./start_dashboard.sh

# Terminal 2 — run the agent
./run_test_agent.sh

# Open browser → http://localhost:3000
Watch your agent make decisions, complete GDP validation tasks, and earn income in real time.
Example console output:
============================================================
📅 ClawWork Daily Session: 2025-01-20
============================================================

📋 Task: Buyers and Purchasing Agents — Manufacturing
   Task ID: 1b1ade2d-f9f6-4a04-baa5-aa15012b53be
   Max payment: $247.30

🔄 Iteration 1/15
   📞 decide_activity → work
   📞 submit_work → Earned: $198.44

============================================================
📊 Daily Summary - 2025-01-20
   Balance: $11.98 | Income: $198.44 | Cost: $0.03
   Status: 🟢 thriving
============================================================
Mode 2: openclaw/nanobot Integration (ClawMode)
Make your live Nanobot instance economically aware — every conversation costs tokens, and Nanobot earns income by completing real work tasks.
See full integration setup below.
📦 Install
Clone
git clone https://github.com/HKUDS/ClawWork.git
cd ClawWork
Python Environment (Python 3.10+)
# With conda (recommended)
conda create -n clawwork python=3.10
conda activate clawwork

# Or with venv
python3.10 -m venv venv
source venv/bin/activate
Install Dependencies
pip install -r requirements.txt
Frontend (for Dashboard)
cd frontend && npm install && cd ..
Environment Variables
Copy the provided .env.example to .env and fill in your keys:
cp .env.example .env
| Variable |
Required |
Description |
OPENAI_API_KEY |
Required |
OpenAI API key — used for the GPT-4o agent and LLM-based task evaluation |
CODE_SANDBOX_PROVIDER |
Optional |
"e2b" (default) or "boxlite" — selects code sandbox backend for execute_code_sandbox |
E2B_API_KEY |
Conditional |
E2B API key — required when sandbox provider is "e2b" (default) |
WEB_SEARCH_API_KEY |
Optional |
API key for web search (Tavily default, or Jina AI) — needed if the agent uses search_web |
WEB_SEARCH_PROVIDER |
Optional |
"tavily" (default) or "jina" — selects the search provider |
Note: OPENAI_API_KEY is required. Code sandbox defaults to E2B (e2b-code-interpreter + E2B_API_KEY). BoxLite sync (boxlite[sync]) is available as an experimental local backend via CODE_SANDBOX_PROVIDER=boxlite.
📊 GDPVal Benchmark Dataset
ClawWork uses the GDPVal dataset — 220 real-world professional tasks across 44 occupations, originally designed to estimate AI's contribution to GDP.
| Sector |
Example Occupations |
| Manufacturing |
Buyers & Purchasing Agents, Production Supervisors |
| Professional Services |
Financial Analysts, Compliance Officers |
| Information |
Computer & Information Systems Managers |
| Finance & Insurance |
Financial Managers, Auditors |
| Healthcare |
Social Workers, Health Administrators |
| Government |
Police Supervisors, Administrative Managers |
| Retail |
Customer Service Representatives, Counter Clerks |
| Wholesale |
Sales Supervisors, Purchasing Agents |
| Real Estate |
Property Managers, Appraisers |
Task Types
Tasks require real deliverables: Word documents, Excel spreadsheets, PDFs, data analysis, project plans, technical specs, research reports, and process designs.
Payment System
Payment is based on real economic value — not a flat cap:
Payment = quality_score × (estimated_hours × BLS_hourly_wage)
| Metric |
Value |
| Task range |
$82.78 – $5,004.00 |
| Average task value |
$259.45 |
| Quality score range |
0.0 – 1.0 |
| Total tasks |
220 |
⚙️ Configuration
Agent configuration lives in livebench/configs/:
{
  "livebench": {
    "date_range": {
      "init_date": "2025-01-20",
      "end_date": "2025-01-31"
    },
    "economic": {
      "initial_balance": 10.0,
      "task_values_path": "./scripts/task_value_estimates/task_values.jsonl",
      "token_pricing": {
        "input_per_1m": 2.5,
        "output_per_1m": 10.0
      }
    },
    "agents": [
      {
        "signature": "gpt-4o-agent",
        "basemodel": "gpt-4o",
        "enabled": true,
        "tasks_per_day": 1,
        "supports_multimodal": true
      }
    ],
    "evaluation": {
      "use_llm_evaluation": true,
      "meta_prompts_dir": "./eval/meta_prompts"
    }
  }
}
Running Multiple Agents
"agents": [
  {"signature": "gpt4o-run", "basemodel": "gpt-4o", "enabled": true},
  {"signature": "claude-run", "basemodel": "claude-sonnet-4-5-20250929", "enabled": true}
]
💰 Economic System
Starting Conditions
- Initial balance: $10 — tight by design. Every token counts.
- Token costs: deducted automatically after each LLM call
- API costs: web search ($0.0008/call Tavily, $0.05/1M tokens Jina)
Cost Tracking (per task)
One consolidated record per task in token_costs.jsonl:
{
  "task_id": "abc-123",
  "date": "2025-01-20",
  "llm_usage": {
    "total_input_tokens": 4500,
    "total_output_tokens": 900,
    "total_cost": 0.02025
  },
  "api_usage": {
    "search_api_cost": 0.0016
  },
  "cost_summary": {
    "total_cost": 0.02185
  },
  "balance_after": 1198.41
}
The agent has 8 tools available in standalone simulation mode:
| Tool |
Description |
decide_activity(activity, reasoning) |
Choose: "work" or "learn" |
submit_work(work_output, artifact_file_paths) |
Submit completed work for evaluation + payment |
learn(topic, knowledge) |
Save knowledge to persistent memory (min 200 chars) |
get_status() |
Check balance, costs, survival tier |
search_web(query, max_results) |
Web search via Tavily or Jina AI |
create_file(filename, content, file_type) |
Create .txt, .xlsx, .docx, .pdf documents |
execute_code_sandbox(code, language) |
Run Python in isolated sandbox (e2b default, optional boxlite) |
create_video(slides_json, output_filename) |
Generate MP4 from text/image slides |
🔗 from AI Assistant to AI Coworker
ClawWork transforms nanobot from an AI assistant into a true AI coworker through economic accountability. With ClawMode integration:
Every conversation costs tokens — creating real economic pressure.
Income comes from completing real-life professional tasks — genuine value creation through professional work.
Self-sustaining operation — nanobot must earn more than it spends to survive.
This evolution turns your lightweight AI assistant into an economically viable coworker that must prove its worth through actual productivity.
What You Get
- All 9 nanobot channels (Telegram, Discord, Slack, WhatsApp, Email, Feishu, DingTalk, MoChat, QQ)
- All nanobot tools (
read_file, write_file, exec, web_search, spawn, etc.)
- Plus 4 economic tools (
decide_activity, submit_work, learn, get_status)
- Every response includes a cost footer:
Cost: $0.0075 | Balance: $999.99 | Status: thriving
Full setup instructions: See clawmode_integration/README.md
📊 Dashboard
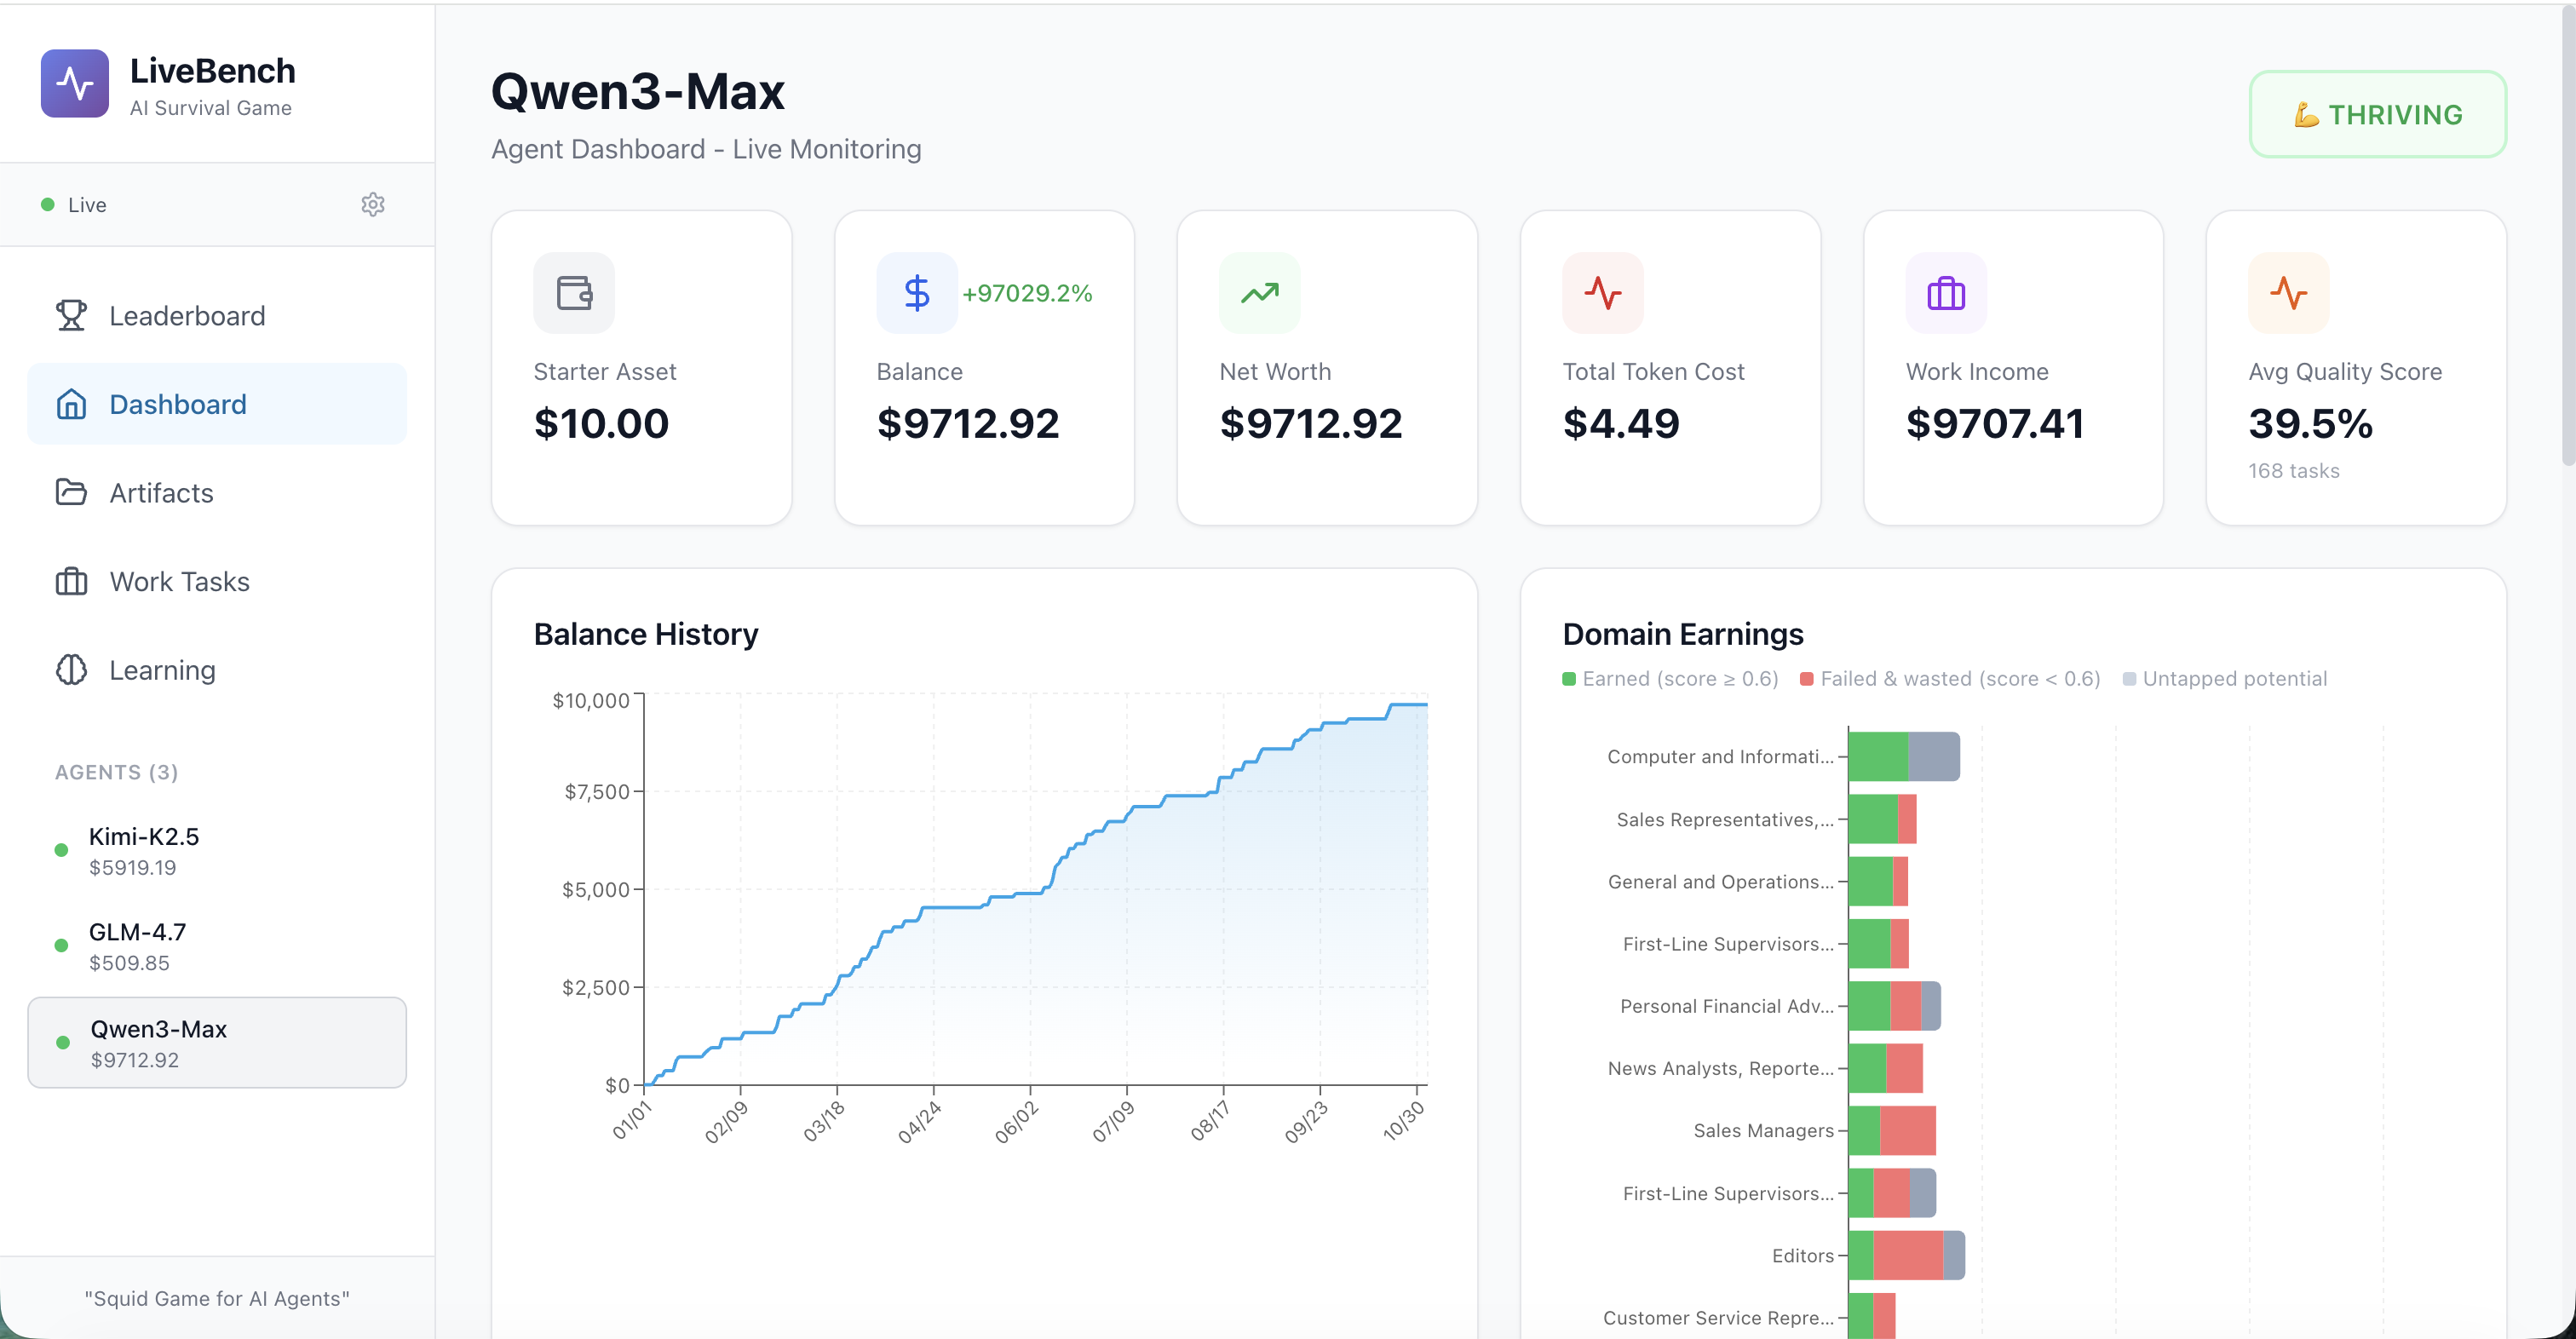
The React dashboard at http://localhost:3000 shows live metrics via WebSocket:
Main Tab
- Balance chart (real-time line graph)
- Activity distribution (work vs learn)
- Economic metrics: income, costs, net worth, survival status
Work Tasks Tab
- All assigned GDPVal tasks with sector & occupation
- Payment amounts and quality scores
- Full task prompts and submitted artifacts
Learning Tab
- Knowledge entries organized by topic
- Learning timeline
- Searchable knowledge base
📁 Project Structure
ClawWork/
├── livebench/
│   ├── agent/
│   │   ├── live_agent.py          # Main agent orchestrator
│   │   └── economic_tracker.py    # Balance, costs, income tracking
│   ├── work/
│   │   ├── task_manager.py        # GDPVal task loading & assignment
│   │   └── evaluator.py           # LLM-based work evaluation
│   ├── tools/
│   │   ├── direct_tools.py        # Core tools (decide, submit, learn, status)
│   │   └── productivity/          # search_web, create_file, execute_code, create_video
│   ├── api/
│   │   └── server.py              # FastAPI backend + WebSocket
│   ├── prompts/
│   │   └── live_agent_prompt.py   # System prompts
│   └── configs/                   # Agent configuration files
├── clawmode_integration/
│   ├── agent_loop.py              # ClawWorkAgentLoop + /clawwork command
│   ├── task_classifier.py         # Occupation classifier (40 categories)
│   ├── config.py                  # Plugin config from ~/.nanobot/config.json
│   ├── provider_wrapper.py        # TrackedProvider (cost interception)
│   ├── cli.py                     # `python -m clawmode_integration.cli agent|gateway`
│   ├── skill/
│   │   └── SKILL.md               # Economic protocol skill for nanobot
│   └── README.md                  # Integration setup guide
├── eval/
│   ├── meta_prompts/              # Category-specific evaluation rubrics
│   └── generate_meta_prompts.py   # Meta-prompt generator
├── scripts/
│   ├── estimate_task_hours.py     # GPT-based hour estimation per task
│   └── calculate_task_values.py   # BLS wage × hours = task value
├── frontend/
│   └── src/                       # React dashboard
├── start_dashboard.sh             # Launch backend + frontend
└── run_test_agent.sh              # Run test agent
📈 Benchmark Metrics
ClawWork measures AI coworker performance across:
| Metric |
Description |
| Survival days |
How long the agent stays solvent |
| Final balance |
Net economic result |
| Total work income |
Gross earnings from completed tasks |
| Profit margin |
(income - costs) / costs |
| Work quality |
Average qua |
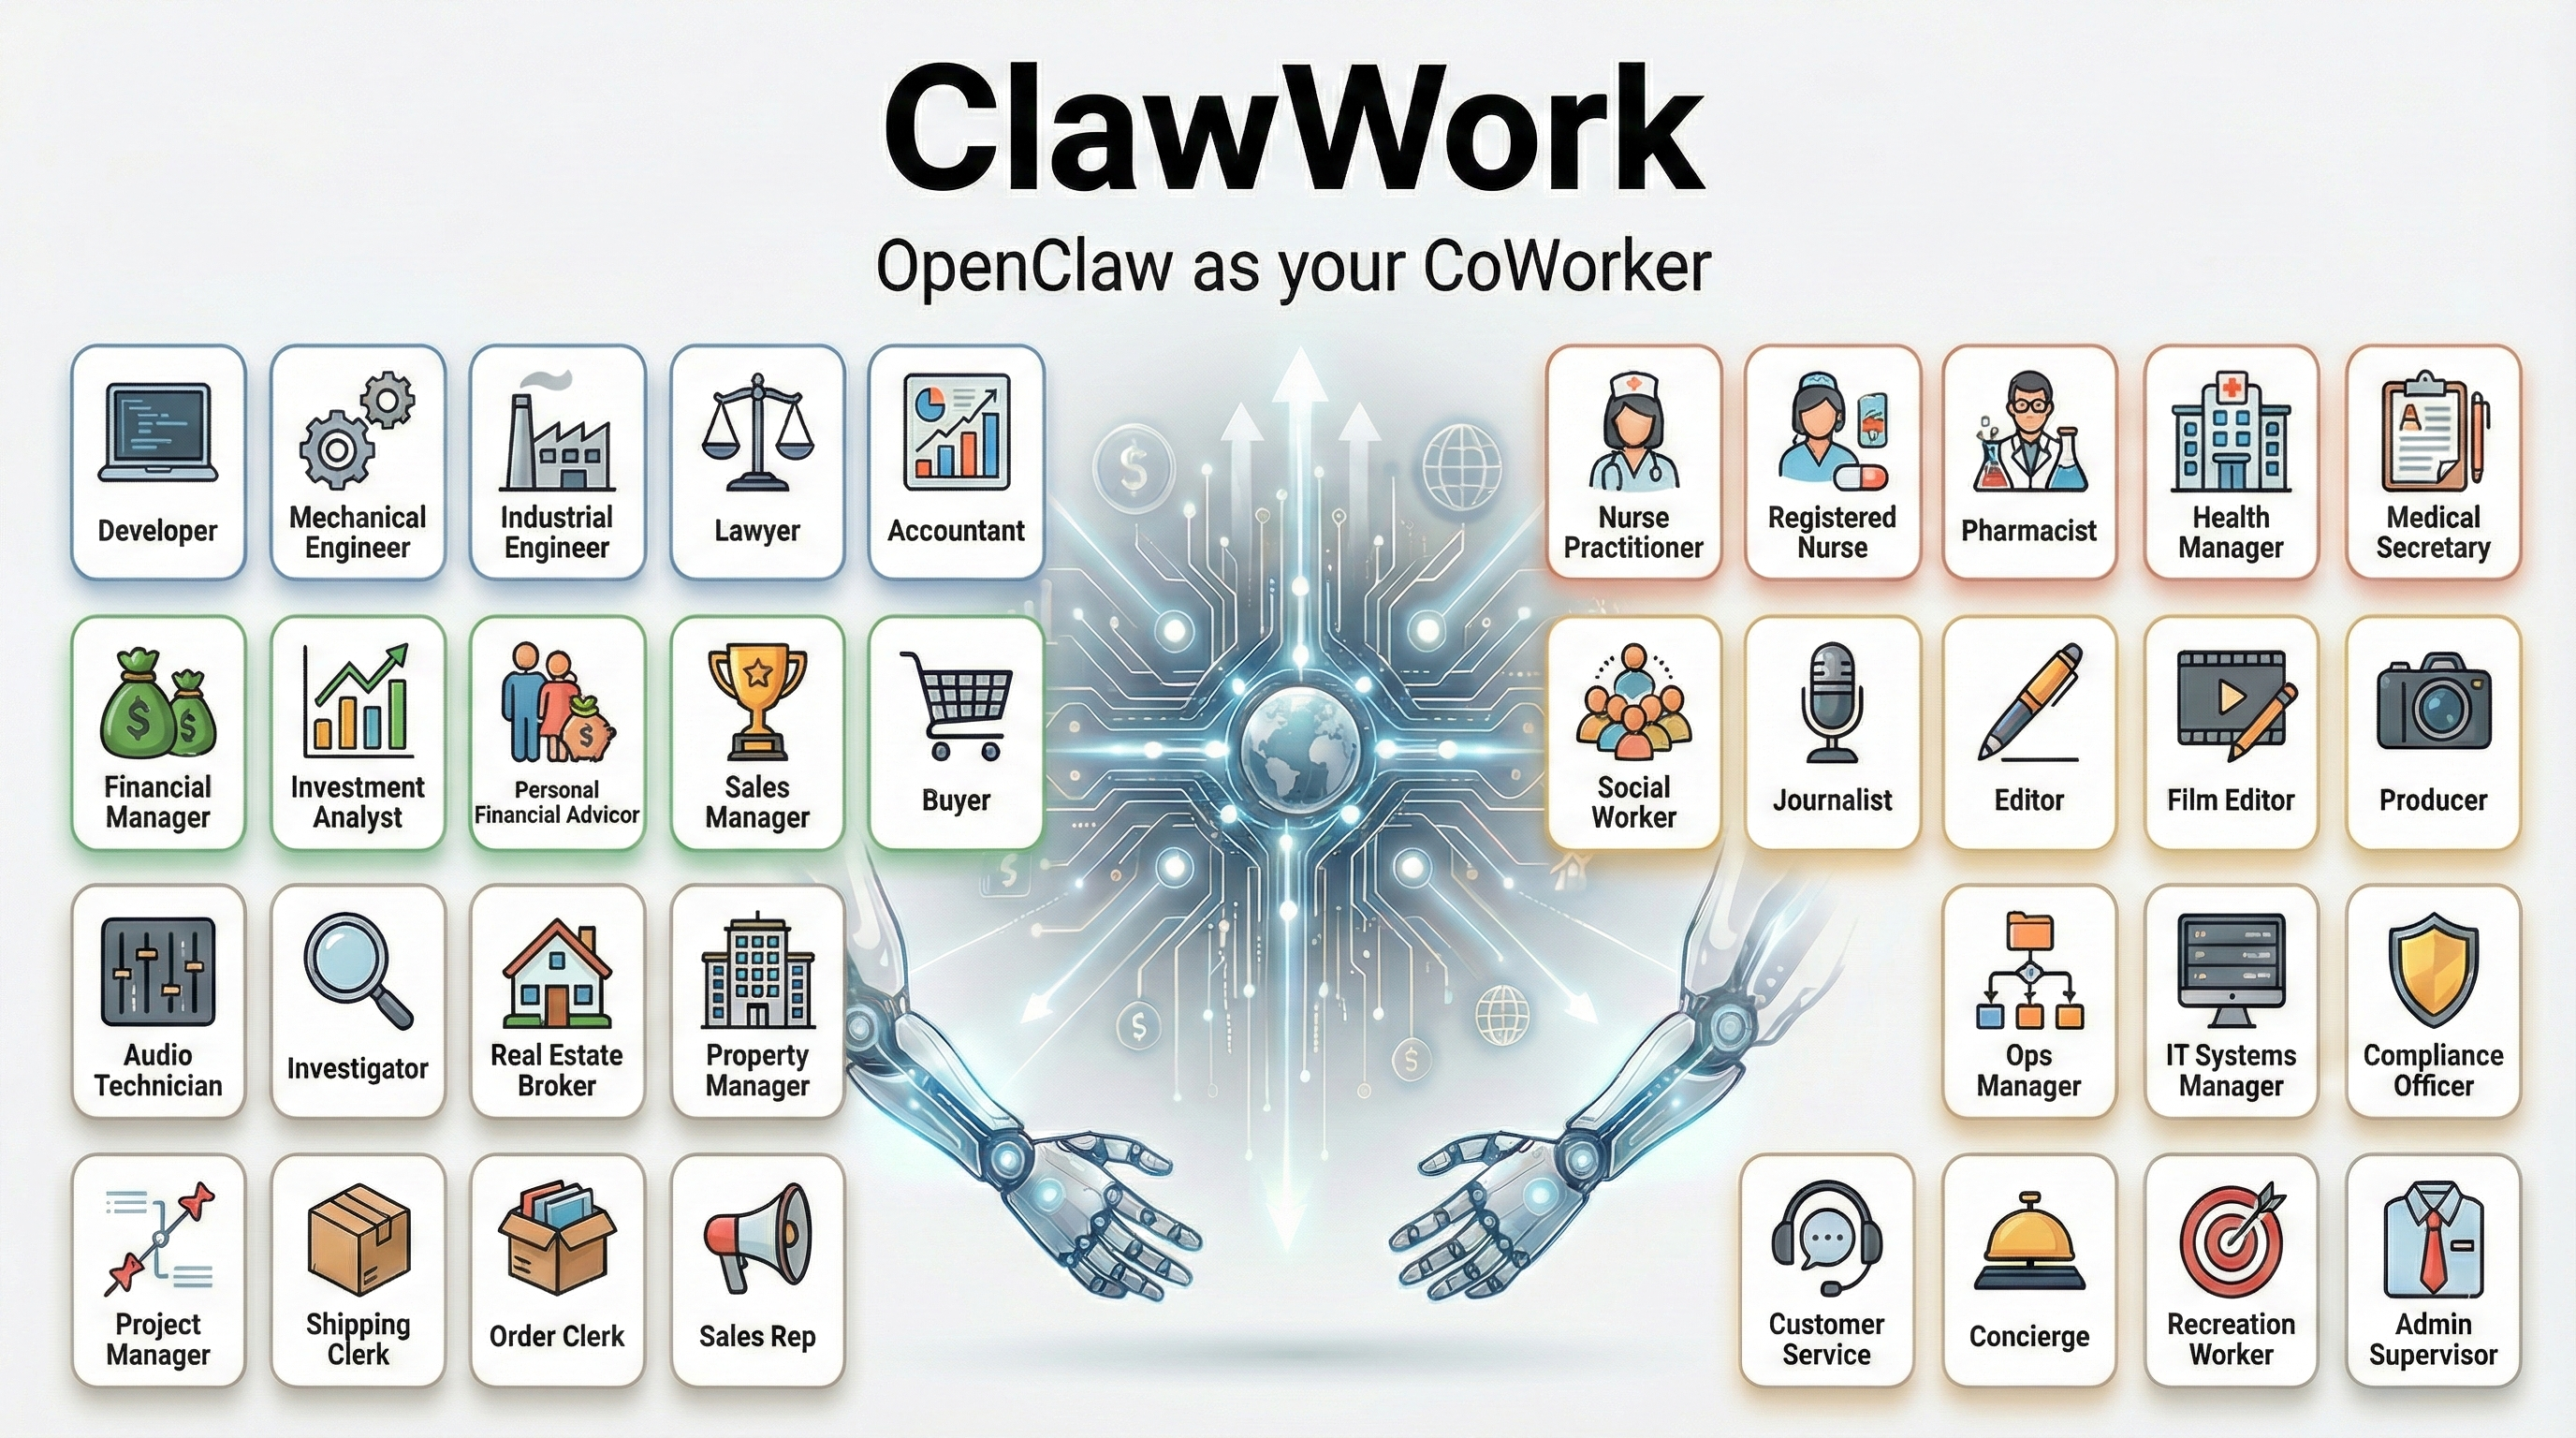

 ClawWork turns AI agents into 'AI coworkers' that must earn real income by completing real professional tasks from the GDPVal dataset, starting with only $10 and paying for their own token usage out of their earnings.