OpenScion is an open-source, server-centric source control system for very large monorepos where most clients are AI agents and CI jobs rather than people on laptops. Based on Anthropic's Scion
openscion (tinyhumansai/openscion)
Searching Database…
The project's README from github.com/tinyhumansai/openscion. As one markdown file: README.md.
OpenScion is an open-source, server-centric source control system for very large monorepos where most clients are AI agents and CI jobs rather than people on laptops. It follows the design Anthropic described for its internal system, Scion, in Redesigning source control.
opnscn against git on synthetic repositories of 4 KiB files, measured with
openscion-bench (cargo run -p openscion-benchmarks --release):
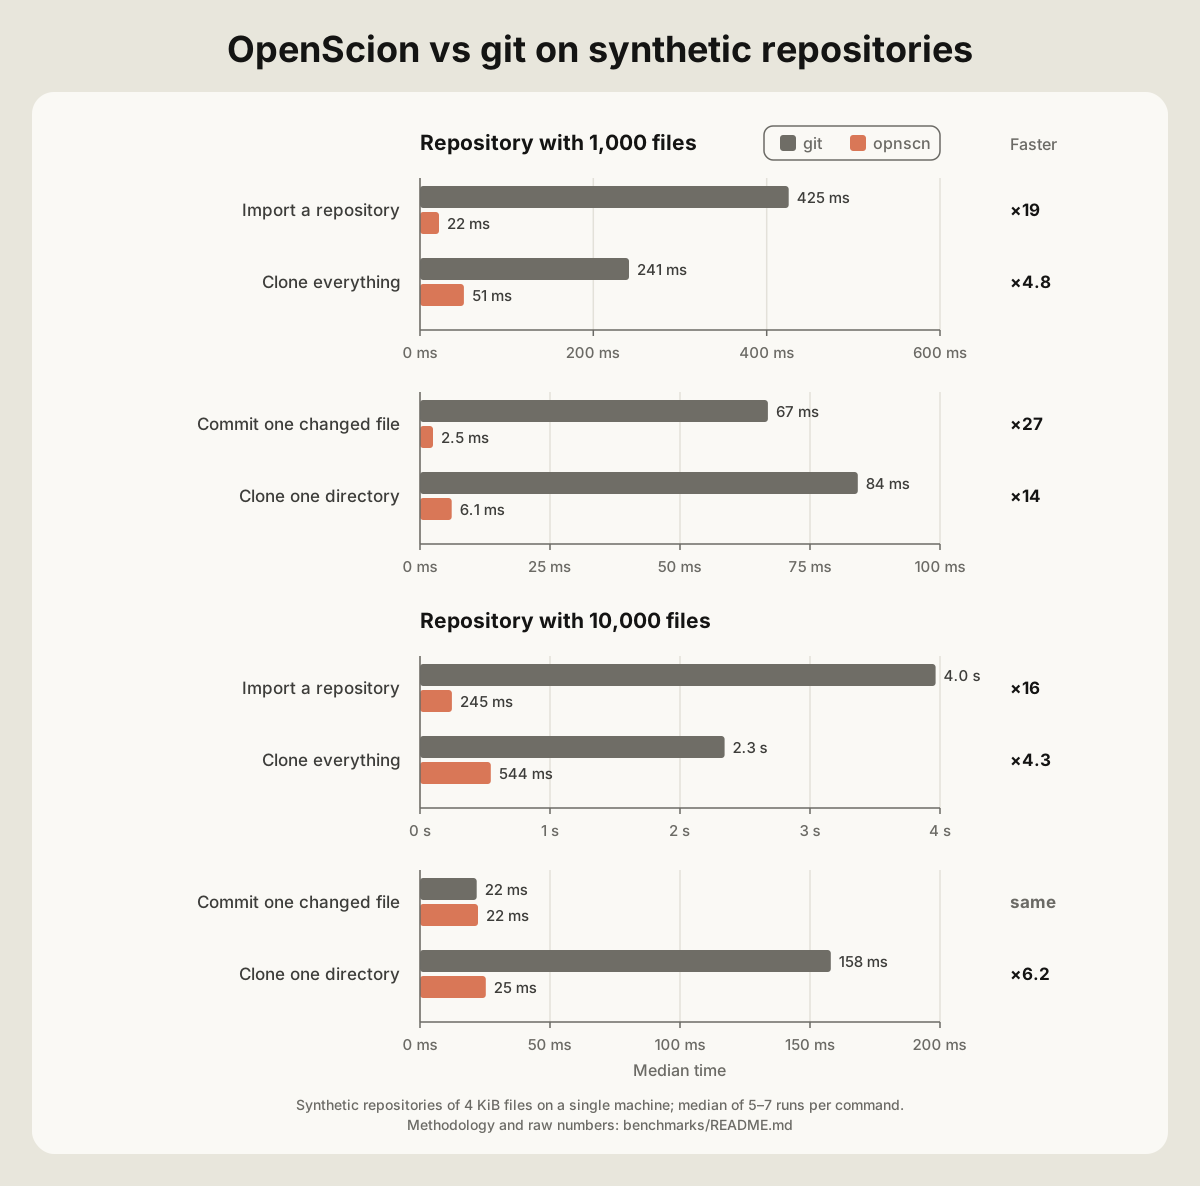
OpenScion imports and clones several times faster than git at both sizes. The
one-directory clone shows the design at work: opnscn fetches only the trees
on the path to the directory and the files beneath it, so its cost tracks the
slice you ask for rather than the size of the repository. Setup, methodology,
and raw numbers are in benchmarks/README.md.
Git assumes every client is offline and keeps a full copy of history. An agent-heavy monorepo breaks that assumption. Thousands of short-lived, always-online jobs each want a small slice of a huge tree, and each one pays for the whole repository anyway. Anthropic reports going from about 2,500 to over 30,000 merged changes a day in four months. At that point the main-branch history was almost 100 GB, CI ran about 25 million checkouts a day, and they needed several hundred git mirrors to keep up.
OpenScion takes the opposite approach:
OpenScion is purpose-built for one workload: large monorepos where most of the traffic comes from agents and CI jobs. Server-side operations, fetching only what is named, and lock-free landing are what keep thousands of concurrent clients fast at that scale.
 opnscn (client) ──► openscion-daemon ──► openscion-cache ──► openscion-server
 working copy     one per node         regional,           log, refs,
 fs watcher       node-wide objects    immutable objects   derived data
                                                              │
                                              metadata store ─┴─ object store
All tiers answer the same object RPCs, so a client talks to whichever one is
nearest. Mutable state (the log, refs, and derived indexes) lives only on the
server. Storage sits behind two ports, ObjectStore and MetadataStore. The
reference implementations are in-memory and local (filesystem, SQLite), so a
single node works without any cloud services.
| Document | What it covers |
|---|---|
| Architecture | goals, principles, components, tiers, delivery phases |
| Data model | object ids, paths, blobs, trees, changesets, the log, refs, derived data |
| API | operations, fetch protocol, rebase and landing, access control, errors |
| Background: Scion | notes on the system OpenScion is modelled on |
| Background: git, GitHub, GitLab | how git stores and moves data, and how the two largest forges host it |
| Roadmap | what exists, what is next, what is out of scope |
AGENTS.md |
repository guidelines for humans and coding agents |
crates/
├── openscion-proto/   # the protocol: payload types and the protocol version
├── openscion-core/    # the engine: data model, stores, derived data, rebase
├── openscion-server/  # openscion-server: the HTTP API over the engine
└── openscion/         # opnscn, the command-line client (crates.io: openscion)
benchmarks/            # openscion-bench: OpenScion vs git on synthetic repos
apps/web/              # the web GUI (Next.js + shadcn/ui)
docs/
├── research/          # source material: Scion, git, GitHub, GitLab
├── specs/             # what to build and why
├── plans/             # test-first implementation plans
└── adr/               # architecture decision records
openscion-proto holds every type that crosses a process boundary. It has no
transport, runtime, or behavior, so any tool can depend on it to speak the API.
openscion-core depends on it and re-exports it, so both crates name the same
types. The server, the CLI, and the GUI all speak that one API.
cargo run -p openscion-server                 # serves http://127.0.0.1:7878
cargo run -p openscion -- import ./tree       # opnscn: record a tree as `main`
cargo run -p openscion -- commit -m "edit" --dir ./tree
cargo run -p openscion -- clone ./copy        # or `--path dir` for one directory
cd apps/web && pnpm install && pnpm dev       # GUI on http://localhost:3000
cargo run -p openscion-benchmarks --release   # time the scenarios against git
Install the client from crates.io with cargo install openscion, which
provides the opnscn binary.
cargo fmt --all -- --check
cargo clippy --all-targets --all-features -- -D warnings
cargo build --all-targets --all-features
cargo test --all-features
CI runs those four checks. It also requires 90% line coverage in every source
file, builds rustdoc with -D warnings, builds with the MSRV, runs a
cargo-deny supply-chain check, and asserts that openscion-proto stays free
of transports and runtimes. To run the extra checks locally:
cargo doc --no-deps --all-features   # CI builds this with RUSTDOCFLAGS="-D warnings"
cargo deny check all
cargo install cargo-llvm-cov         # once
.github/scripts/check-file-coverage.sh 90 coverage.json
Run the Release workflow from the Actions tab and pick a patch, minor,
or major bump. The workflow re-validates the workspace, bumps the shared
[workspace.package] version, tags it, publishes openscion-proto,
openscion-core, and openscion to crates.io (using the
CARGO_REGISTRY_TOKEN secret), and creates a GitHub release. Do not edit the
version in the root Cargo.toml by hand.
See CONTRIBUTING.md. Behavior changes start in
docs/specs/; each accepted spec gets a test-first
plan in docs/plans/ before any code is written.
GPL-3.0-only. See LICENSE.
OpenScion is an open-source, server-centric source control system for very large monorepos where most clients are AI agents and CI jobs rather than people on laptops. Based on Anthropic's Scion