Straight from the source. Every listing is crawled directly from a company's
own ATS — Workday, Greenhouse, Lever, Ashby, iCIMS and a long tail of others — and
links to the original posting. No recruiter reposts, no aggregator middlemen, no
dead links.
One schema, deduplicated. The same role posted to three boards collapses into
one entry: every posting is normalized into a single shape and deduplicated on a
stable key.
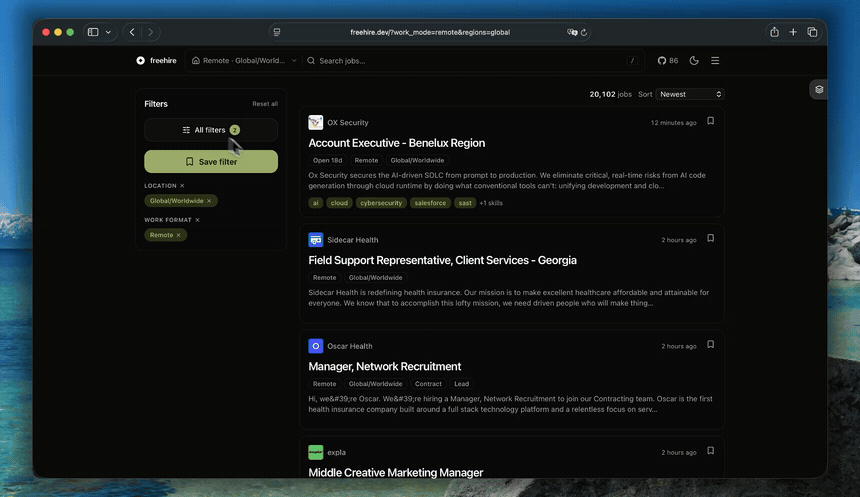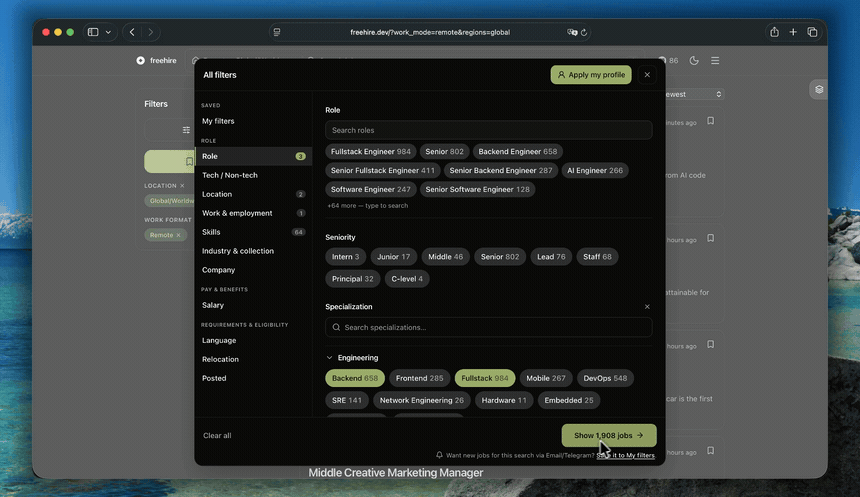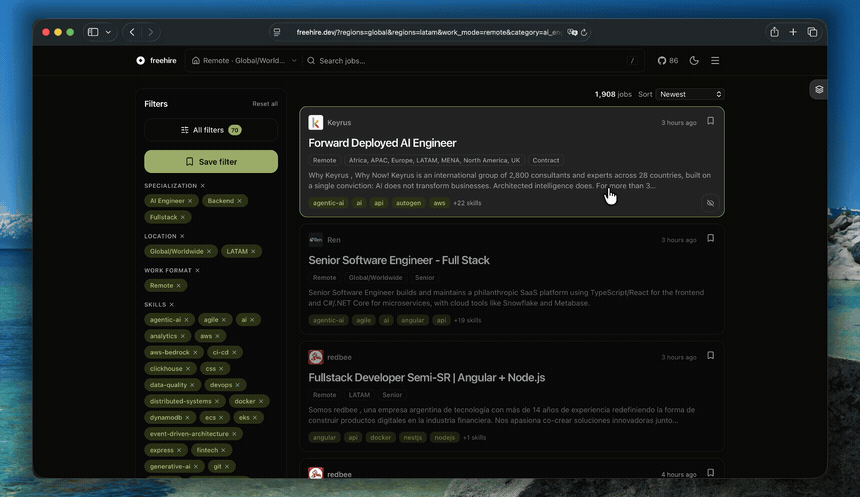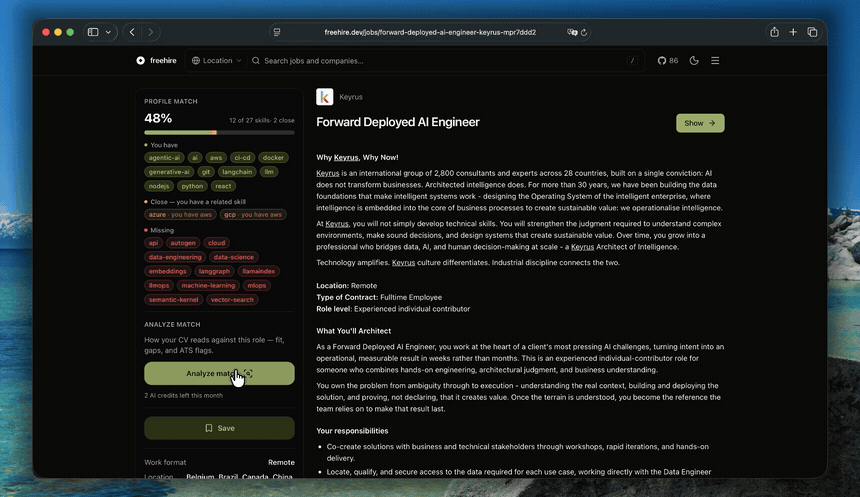
Search that understands jobs. Faceted full-text search over region, work mode,
seniority, skills and salary — derived from curated dictionaries, never guessed.
Actually open. MIT-licensed and self-hostable, pipeline and data both in the
open. Adding a company is one row in the board catalog
(how).
Yours to build on. A clean HTTP API, a CLI, Telegram digests, and a whole
workspace on top of the catalogue — see Beyond the catalogue.
Use the hosted site, run your own, or build on top.
Aggregating 4.9M+ unique live postings from 700,000+ companies across
168 ATS platforms, a long tail of aggregators and direct feeds, and 97
Telegram channels — 437 sources in all, see Sources for the full
breakdown. Reposts of one job across boards are collapsed, so every figure here is
what freehire.me/jobs actually shows.
Free and Pro
freehire.me is free for finding and tracking a job,
for good: every posting and every filter, AI search, alerts by email, Telegram and
push, the application board, the inbox that sorts employer replies, and search from
ChatGPT, Claude or any agent over MCP.
Pro — $5/month adds the AI that does the applying with you:
CV tailoring for each vacancy, with a cover letter — it invents nothing
The AI assistant, unlimited
The browser extension fills application forms for you
Auto-apply in the background, within a daily limit
Members-only channels on the community Discord
Cancel any time; not what you expected — email within 14 days for a refund.
See plans →
If freehire saves you time — or you just like the idea of jobs straight from the
source — a ⭐ helps other people find it.
Beyond the catalogue
Finding the posting is half the problem. The other half — writing the CV,
sending it, and knowing what happened to it — is built on the same data, in the
same repository, under the same licence.
Find
Faceted search, curated collections, saved searches with email/Telegram digests, shared boards, market analytics, the ghost-job signal
Apply
CV builder with ATS-safe PDF templates, deterministic CV↔vacancy scoring, AI fit analysis, CV tailoring that invents nothing, tracer links, referrals
Track
An application board with stages, a mail inbox that links recruiter replies to the application they answer, an append-only event ledger, reminders
Ask
An in-process agent with five presets — chat, browse, profile, CV tailoring, interview rehearsal — with no shell and no minted credential
Build on
A keyless public API, a CLI, an MCP server for Claude Desktop and Claude Code, a form-filling browser extension, ChatGPT Actions
Prometheus (via the node_exporter textfile collector) + Grafana — metrics and dashboards for the ingest/LLM infrastructure
Docker Compose — local development
Quick start
make up        # build + start the whole stack in Docker:
               # api, web, postgres, meilisearch, redis, s3
curl localhost:8080/health
curl localhost:8080/api/v1/jobs
Migrations are applied automatically on first Postgres volume init
(the migrations/ folder is mounted into /docker-entrypoint-initdb.d).
Changing a migration does not re-apply to an existing volume — recreate it with
docker compose down -v && make up, or apply pending files manually with
make migrate.
If port 8080 is already taken, pick another host port:
HIRE_HOST_PORT=8090 make up
Local development
docker compose up -d db   # database only
make run                  # server on host, reads DATABASE_URL
Copy .env.example to .env and adjust as needed. JWT_SECRET is required for
the server to start; OAuth and LLM credentials are optional (the features they
gate stay disabled when unset).
Commands
make help      # list all commands
make sqlc      # regenerate code from SQL (via Docker, no local sqlc needed)
make tidy      # go mod tidy
make psql      # psql inside the DB container
make reindex   # rebuild the Meilisearch index from Postgres
make migrate   # apply migrations manually to an existing DB volume
Workers
The server only serves the API. Everything else — crawling, enrichment, indexing,
notifications — is a standalone, run-once worker meant for cron: it crawls or
drains its queue and exits. ls cmd/ for the full list; the ones you are most
likely to run:
go run ./cmd/migrate       # apply pending migrations (run before deploying code that reads new schema)
go run ./cmd/ingest greenhouse  # crawl one provider's catalog boards and upsert jobs (also via INGEST_PROVIDER)
go run ./cmd/enrich        # drain the enrichment queue (LLM); needs LLM_* config
go run ./cmd/embed         # drain the semantic queue into pgvector chunks
go run ./cmd/search-drain  # push queued job writes into the live search index (run every 1-2 min)
go run ./cmd/reindex       # rebuild the Meilisearch index from Postgres (full swap)
go run ./cmd/tg-ingest     # crawl the active channels in telegram_channels
go run ./cmd/tg-extract    # LLM-extract vacancies from crawled Telegram posts
go run ./cmd/capture-apply-form  # fetch queued postings' ATS application forms
go run ./cmd/backfill-derive     # re-derive every deterministic column — facets, fingerprints,
                                 # slugs — in one keyset pass (follow with make reindex)
Every worker needs DATABASE_URL and exits non-zero on failure. No worker
hard-deletes jobs; the lifecycle only soft-closes them.
Layout
cmd/                 entry points: server + the standalone workers above
migrations/          SQL schema (source for both sqlc and initdb)
web/                 the SvelteKit frontend
extension/           the Chrome side-panel extension
design-system/       shared tokens and components, linked into web/ and extension/
internal/            ~130 domain packages; the load-bearing ones:
  config/            env configuration
  database/ db/      pgxpool pool; generated sqlc code + queries/*.sql
  handler/           HTTP handlers
  auth/              auth primitives (JWT cookie, API keys) + OAuth sign-in
  sources/           source adapters (greenhouse / lever / adzuna / …) + registry
  boardcatalog/      the board catalog: which company crawls on which ATS, under what board id
  pipeline/          ingest runner (fetch → normalize → dedup → upsert)
  linksource/        resolves outbound job links found in Telegram posts
  telegram/          Telegram-channel crawl + LLM vacancy extraction
  enrich/            typed AI-enrichment contract + queue-draining runner
  search/ searchdrain/  Meilisearch indexing and query; incremental drain of the write queue
  embed/             semantic chunk embeddings into pgvector
  location/ classify/ skilltag/  the curated facet dictionaries — never guess, emit nothing
  ghost/             the posting-reality signal behind "is this job real?"
  jobview/           the single public wire shape of a job
  cv/ cvedit/        structured CVs + PDF rendering; cvedit is their only writer
  experience/        durable employments + evidence atoms behind every CV claim
  cvmatch/ matchanalysis/  deterministic CV↔vacancy score; the LLM fit analysis on top
  applyform/         captured ATS application forms, in the platform's own vocabulary
  userjob/ appevent/ per-user tracking (view / apply / save / stages) + the event ledger
  inbox/             recruiter mail → classify → link to an application
  assistant/         the in-process agent: turn loop, tools, transcripts
  browsertools/      relays tool frames between the agent and the browser extension
  referral/ collections/  employee referrals; curated company tags
  llm/ llmkey/       provider-agnostic LLM client + per-user spend attribution
Architecture
How the pieces fit together — the crawl-to-search topology, what each directory
above is for, and walkthroughs of the three main flows (finding a job, tailoring a
CV, the in-app assistant), plus the auth model, notifications and the job
lifecycle: docs/architecture.md.
It is the map; the per-package AGENTS.md files it links to are the territory.
API
The catalogue is served over a public, keyless HTTP API — GET https://freehire.me/api/v1/jobs needs no credential. All responses use
{"data": ...} (single), {"data": ..., "meta": {...}} (lists), or
{"error": msg}; jobs and companies are addressed by their public slug.
Full reference — every endpoint, its parameters, auth mode and the whole
search-filter vocabulary: freehire.me/docs/api.
Sources
Snapshot of 2026-10-30 — 4,785,488 unique open postings across 701,972
companies, from 421 sources; 400 of them carry a posting today. Counts are
unique open postings: a job reposted on several boards is counted once (the
per-kind sums below run slightly higher, since a posting two sources carry is
counted under each). Every source is one of three kinds:
ATS platforms — one adapter per multi-tenant applicant-tracking system,
each serving many companies (Workday, Greenhouse, Lever, iCIMS…).
160 platforms with postings · 3,827,693 open postings.
Aggregators & job boards — third-party feeds that republish many
companies' postings (Adzuna, trudvsem, himalayas, 97 Telegram channels…).
179 with postings · 937,728 open postings.
Company career sites — direct single-company feeds crawled from a
company's own careers page (Amazon, Apple, Google, Yandex, Sber…).
58 feeds with postings · 25,350 open postings.
A source's kind is not configuration but a property of the adapter's own Go type,
so internal/ingest/sources classifies every provider without a network call.
Full per-source breakdown — every source with its own open-jobs count — lives on
its own page: docs/sources.md, and always current at
freehire.me/sources.
Adding a source
Adding a company is one row in the boards catalog — company + provider +
board — added through the "contribute a board" form on the site, or by a curator
with go run ./cmd/add-board --provider=… --board=… --company=… --apply. Adding an
ATS platform is a new adapter in internal/ingest/sources plus one line in
sources.All — every adapter speaks the same Source interface, and a board is
validated against the registry when it enters the catalog, before any crawl.
For most companies the platform is already supported, so adding them is just one
catalog row. Only when a company runs on an ATS we don't cover yet does it need a
new provider (a new adapter). Either way, if you want a source added,
start by opening an issue — name
the company and its careers URL, and we'll confirm whether it's a one-line add or a
new provider before any code.
Frontend
A server-rendered SvelteKit 2 app (Svelte 5 runes, Tailwind 4, adapter-node)
lives under web/ and consumes the API same-origin; a dev Vite proxy forwards
/api to the backend. Shared tokens and components come from the sibling
design-system/ package — install it before building web/ or extension/,
since it is symlinked, not copied. See web/AGENTS.md.
Browser extension
A Chrome extension puts the job-application agent in a side panel next to
whatever posting you're on: it reads the page when you ask it something, shows
a deterministic skill-coverage match against your freehire profile, and can
fill the application form for you. Source lives under extension/
(extension/AGENTS.md).
Contributions are welcome, and issues and PRs are open to everyone. No
allowlist, no approval step — open one.
The easiest way to help is to add a source: submit a board through the
"contribute a board" form on the site, or send a new adapter in
internal/ingest/sources. Missing a company you would apply to? Contributing its
board takes a URL, and it is the single most useful thing you can send.
Questions and half-formed ideas are equally welcome in
Discussions — no need to
polish them into an issue first. For anything large, an issue up front saves you
from building the wrong thing, but nothing stops you from just opening the PR.








 freehire 是一个面向求职者的开源搜索引擎,它直接从企业的 ATS 平台(Workday、Greenhouse、Lever、Ashby、iCIMS 等)抓取职位信息,去重后统一为同一种数据结构,并在此基础上提供搜索、简历工具和投递跟踪功能。