Watch the video: KSoR Introduction
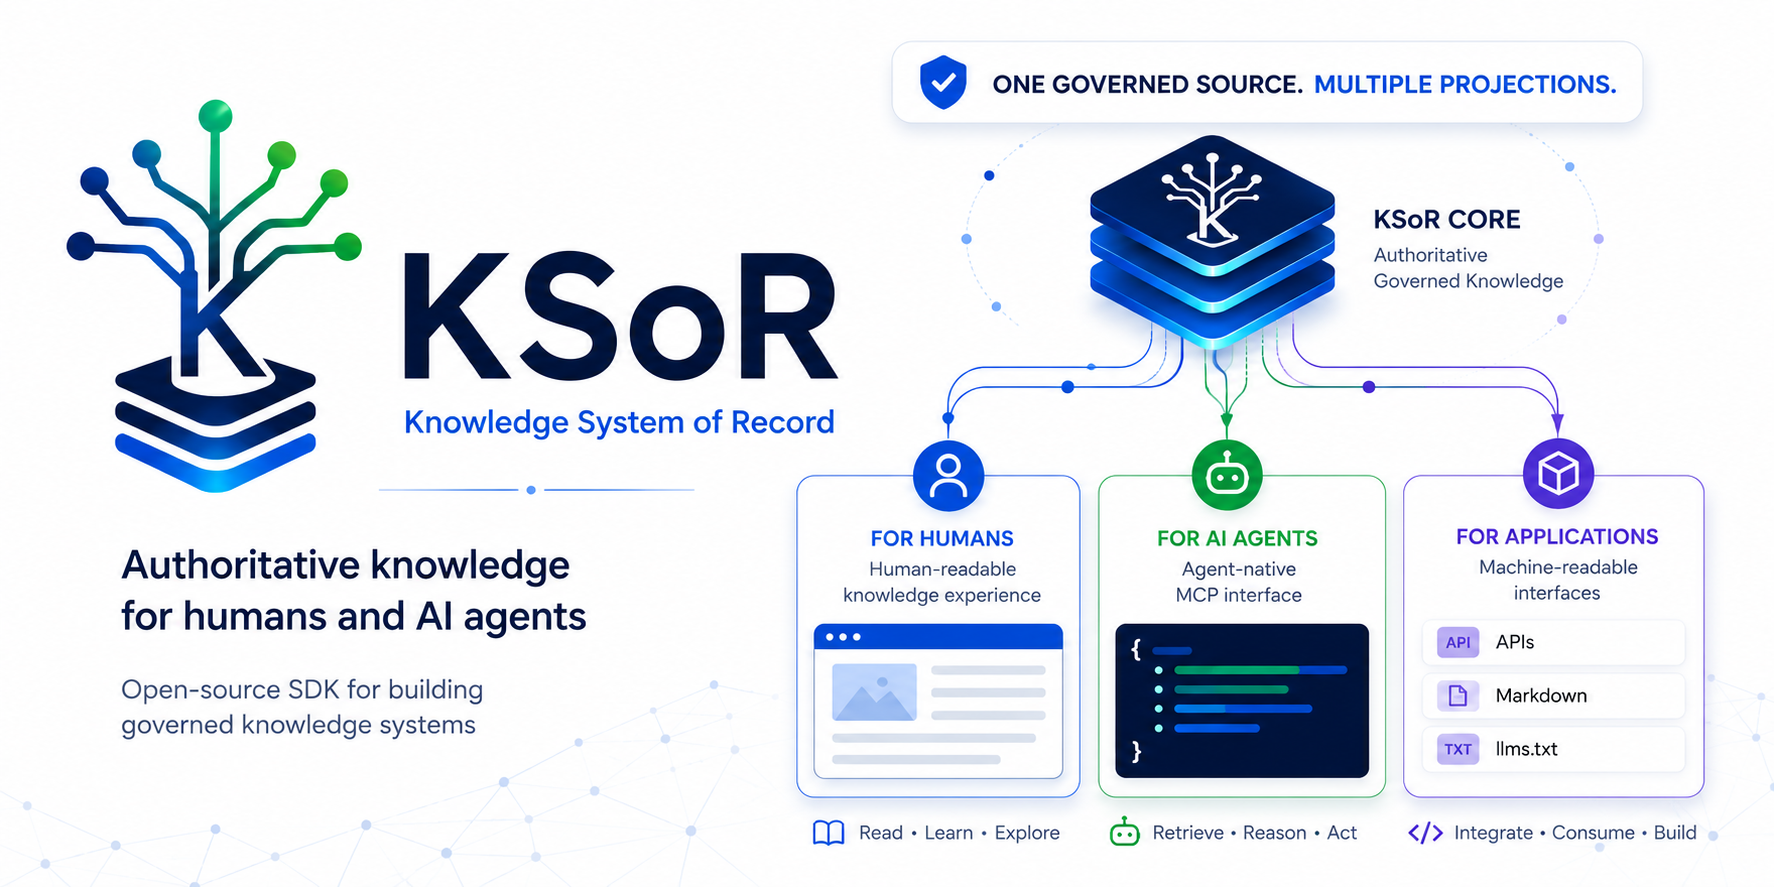
KSoR
Open, vendor-neutral knowledge infrastructure for predictable enterprise and education agentic systems.
A company cannot expect predictable AI-agent behavior if its agents operate from scattered, conflicting, or outdated knowledge.
An education institution cannot deliver an organized AI-assisted course if its tutors, teaching assistants, and assessment agents operate from different curricula, sources, or rules.
You cannot build predictable AI systems on an undefined source of truth.
A Knowledge System of Record (KSoR) solves that problem by giving an organization one governed, authoritative knowledge record that humans and AI agents operate from.
For an enterprise, that record can contain approved:
- policies,
- procedures,
- rules,
- methods,
- standards,
- definitions,
- controls,
- decision criteria,
- and institutional knowledge.
For an education institution, it can contain approved:
- curriculum,
- learning objectives,
- concepts and definitions,
- pedagogy,
- course sequence,
- source material,
- assessment rules,
- grading criteria,
- and the current course version.
The AI can still reason, explain, personalize, and adapt. What it should not have to invent is which institutional or academic knowledge is authoritative.
Enterprise agents need a KSoR so they operate from the same governed institutional truth.
Education agents need a KSoR so they teach from the same governed academic truth.
KSoR does not make a probabilistic language model deterministic. It makes the knowledge environment governed, bounded, traceable, and testable: which source is authoritative, which version is current, who approved it, who may see it, which knowledge may be retrieved, and when an agent must abstain instead of improvising.
The framework reduces to three commitments:
One authoritative record.
One governance boundary.
Many open projections.
And one operating principle:
Govern knowledge once. Project it many ways.
The result is not merely a documentation site, knowledge base, vector database, RAG system, or MCP wrapper.
KSoR is an open knowledge infrastructure framework that makes governed knowledge usable by people, AI agents, and other knowledge systems without giving any one vendor ownership of the record.
KSoR in eight concepts →
17 slides, one hospital, plain language, no code. One authoritative record, what belongs in it, provenance, the governance boundary, abstention, citation, how new knowledge gets approved, and the many open projections that read it — the deck to open when you are introducing KSoR to a team.
Start here
All you need is Node 24 or newer. Use whichever package manager you already
have — npm, pnpm, or bun — and the project it creates will use that same
manager everywhere:
npm
npx @panaversity/ksor@latest init my-knowledge-sor
cd my-knowledge-sor && npm install && npm run dev
pnpm
pnpm dlx @panaversity/ksor@latest init my-knowledge-sor
cd my-knowledge-sor && pnpm install && pnpm dev
bun
bunx @panaversity/ksor@latest init my-knowledge-sor
cd my-knowledge-sor && bun install && bun run dev
Open http://localhost:3000. The site is running, and it reloads as you edit
the Markdown files in knowledge/. What you have is a complete, ordinary
project — a working website, a CI workflow, and instructions for coding agents
— and it is entirely yours: nothing is downloaded at build time, and nothing
phones home. The five documents in it are KSoR's own starters, there to be
deleted as your knowledge arrives.
Ask it to publish and you meet the point of all this:
$ pnpm exec ksor build
ksor build: 6 document(s), 5 admitted to a machine surface
Six documents, five admitted. The one you just wrote is a draft, so it
reaches no surface an AI agent reads — not llms.txt, not the markdown twins,
nothing — until a human approves it. Approve it and the count moves.
Hello world walks that end to end in
about fifteen minutes, from an empty directory to your own coding agent
answering from your own document and naming which document and which
publication it came from. Every command and output in it was run and pasted as
it appeared.
The five so far, in reading order — pick by what you want from it:
|
read this if |
| 00 · Introduction |
you want to understand why this exists — no technical background needed |
| 01 · Hello world |
you want to see it work in fifteen minutes — Part 1 needs only Node; Part 2 adds a free Postgres and a free embedding key |
| 02 · Make it yours |
you finished hello world and want a record that is only yours — a file in, a person's knowledge in, the samples out |
| 03 · Governance in practice |
you have a record of your own and want to govern it — a second audience, a review, an effective date, a takedown and the refusals that fire |
| 04 · Serve it — with a floor |
you want the headline claim by hand — measure the line under which your record declines, then watch an agent be refused |
Next, open the project in the coding agent you already use (Claude Code,
Cursor, Copilot — any of them) and tell it what this knowledge base is
for. That is how you work with KSoR day to day: you write plain Markdown,
in whatever language you write in, and the agent handles the checks and
structure around it. The project ships AGENTS.md with the working rules,
and the agent will interview you to replace the placeholder in instance.md
— the file that says what this knowledge base covers.
Later, when you want AI agents to query your knowledge directly, you add
a Postgres database and an embedding API key, then run three commands:
pnpm provision once, pnpm refresh to publish, and pnpm serve. The full
path is in Serve to AI Agents below.
The rest of this page explains why KSoR is built this way. To go straight
to the practical reference, jump to Requirements.
Why KSoR Exists
Organizations already understand the value of a System of Record.
An accounting system is authoritative for financial transactions. A CRM is authoritative for customer records. An HRIS is authoritative for employee records.
When a spreadsheet disagrees with the accounting ledger, the ledger wins.
These systems answer:
What is the authoritative operational state of the organization?
AI agents create a second requirement:
What is the authoritative knowledge the organization allows them to operate from?
That includes questions such as:
- What policies apply?
- What rules govern this decision?
- Which procedure should be followed?
- What does this organization mean by this term?
- Which thresholds are approved?
- Which methodology should be used?
- What exceptions exist?
- What sources support this answer?
- What should the agent do when the answer is not known?
In education, the same authority problem appears in a different form:
- What curriculum is current?
- Which learning objectives govern this course?
- Which definitions and explanations are canonical?
- Which sequence should be taught?
- Which sources are approved?
- Which assessment and grading rules apply?
- What may an AI tutor personalize, and what must remain fixed?
Without a KSoR, this knowledge is commonly fragmented across documents, wikis, PDFs, slide decks, websites, instructor notes, repositories, prompts, RAG indexes, model context, and human memory.
A model can rank what looks relevant. It cannot reliably manufacture organizational or academic authority when the institution itself has not defined it.
The problem is not simply finding knowledge. The problem is establishing which knowledge wins.
KSoR exists to establish that authority and make it usable across human, AI, agent, and machine-facing surfaces.
Predictable AI Needs a Knowledge System of Record
The more autonomy an AI agent receives, the more important its knowledge boundary becomes.
KSoR separates two things that are often confused: model variability and knowledge authority. Models may vary in wording, reasoning paths, explanations, and personalization. The authoritative knowledge they are permitted to use should not vary arbitrarily.
KSoR makes that knowledge environment controlled and testable:
- which knowledge is authoritative,
- which version is in force,
- who owns and approved it,
- which audience may see it,
- which sources support it,
- what retrieval is permitted,
- and when the system must abstain.
That distinction matters in both enterprises and education.
In an enterprise
Without a Knowledge System of Record, an agent may encounter several plausible sources:
                          AI Agent
                             │
        ┌────────────┬───────┼────────┬─────────────┐
        ▼            ▼       ▼        ▼             ▼
     old wiki     current   Slack    stale RAG   model memory
                  policy   message    chunks
        │            │       │        │             │
        └────────────┴───────┼────────┴─────────────┘
                             ▼
                  Which source should win?
The agent can rank relevance. It cannot manufacture organizational authority.
With a KSoR:
                    Governed KSoR
                         │
              authoritative knowledge
                         │
                 governance boundary
                         │
                         ▼
                      AI Agent
                         │
                         ▼
             predictable, bounded action
The agent may still reason probabilistically, but it reasons from a controlled institutional truth rather than choosing among conflicting versions of that truth.
A company cannot build predictable agentic operations on unpredictable knowledge.
In education
The same problem appears when AI agents become tutors, teaching assistants, assessment agents, or curriculum assistants.
Without an authoritative academic record, two students in the same course can be taught from different model memory, different web sources, different editions of course material, or outdated instructor notes. Personalization then becomes curricular inconsistency.
An education KSoR can govern the academic truth:
                       Education KSoR
                            │
          ┌─────────────────┼─────────────────┐
          ▼                 ▼                 ▼
      Curriculum         Pedagogy         Assessment
          │                 │                 │
          └─────────────────┼─────────────────┘
                            ▼
                    governed course record
                            │
              ┌─────────────┼─────────────┐
              ▼             ▼             ▼
           AI Tutor      Teacher AI    Assessment AI
The AI can still adapt:
- explanation,
- examples,
- pacing,
- language,
- difficulty,
- practice,
- and remediation.
But the KSoR can keep stable:
- learning objectives,
- canonical concepts and definitions,
- prerequisites,
- approved source material,
- course sequence,
- assessment rules,
- grading criteria,
- and the current course version.
Personalization should vary the teaching path, not the authoritative curriculum.
An education institution cannot run an organized AI-assisted class if every tutor or teaching agent is free to choose a different source of truth.
So the same architectural principle applies in both settings:
Enterprise agents need a KSoR so they operate from the same governed institutional truth.
Education agents need a KSoR so they teach from the same governed academic truth.
The KSoR Framework: Nine Responsibilities
The product idea is simple:
- one place defines the knowledge,
- governance decides what is authoritative and who may use it,
- open interfaces make the same governed truth available wherever it is needed.
The technical architecture implements that idea through an open, vendor-neutral knowledge infrastructure framework, built around three commitments:
One authoritative record.
One governance boundary.
Many open projections.
That model in one picture:
                      KSoR FRAMEWORK
      open, vendor-neutral knowledge infrastructure
                             │
                    AUTHORITATIVE CORE
                     Governed Markdown
                   (KSoR Profile of OKF)
                             │
                    GOVERNANCE BOUNDARY
                             │
      ┌──────────────┬───────┴───────┬──────────────┐
      │              │               │              │
      ▼              ▼               ▼              ▼
  Human site    AI discovery   Agent surface    Exchange
   Fumadocs       llms.txt          MCP       governed OKF
                                     │           bundles
                                     ▼
                              Retrieval layer
                            Postgres + pgvector
Identity (OAuth/OIDC) cuts across every surface. Publication integrity
(SLSA/Sigstore) covers the published PACKAGE and not yet the record's own lock,
and observability (OpenTelemetry) is bound and unbuilt — see below, where both
are stated exactly.
The nine responsibilities
The framework separates nine responsibilities, so that no single product
becomes the knowledge authority. Wherever an open format, convention, or
protocol already owns a boundary, KSoR adopts it rather than competing with
it:
| Responsibility |
Open standard / reference binding |
What it means |
| Authoritative record |
Markdown in the KSoR Profile of OKF |
Markdown is the durable medium; the profile gives it open, portable structure |
| Retrieval |
Postgres + pgvector |
structured, lexical, and semantic search over the governed record |
| Human publication |
Fumadocs |
the reference human-readable site |
| AI discovery |
llms.txt |
tells AI systems what knowledge exists and where machine-readable pages are |
| Agent interaction |
MCP |
search, retrieval, citation, and abstention for agents |
| Knowledge exchange |
OKF |
the same native representation moves governed knowledge between systems |
| Identity |
OAuth / OIDC |
who is asking — KSoR governance then decides what they may see |
| Publication integrity |
SLSA / Sigstore (package only) |
proof of which source and build produced a published artifact |
| Observability |
OpenTelemetry (not yet emitted) |
what the infrastructure did, without becoming another knowledge store |
One of the nine is a binding with nothing behind it yet, and one is half
built — both say so here. ksor build
writes build.lock.json but signs nothing — SLSA/Sigstore attestation of that
lock is out of scope in specs/ksor/build/spec.md §6 and will land separately.
No telemetry is emitted today either: there is no OpenTelemetry code in the
tree, and the row above records which standard owns that boundary rather than a
surface that runs. When it does land, one constraint is already decided by the
row's own wording — without becoming another knowledge store. Default
auto-instrumentation would break it immediately, because pg captures statement
text and a trace backend is a different security boundary from the MCP response;
for a non-public audience that is a governance bypass through the observability
layer. What would survive careless instrumentation added later is an allowlist
span processor — attributes not explicitly permitted are dropped, so traces
would carry decisions and counts and never content.
The same architecture can be explained as a dependency stack. This is not a second list of responsibilities; it shows how the pieces relate, and why OKF sits under KSoR rather than beside it:
Markdown is the authoritative medium.
OKF makes that record open and portable.
KSoR governance makes it authoritative.
Postgres + pgvector make it retrievable.
Fumadocs serves humans.
llms.txt lets AI discover it.
MCP lets agents interact with it.
OAuth/OIDC establishes identity; KSoR governs access.
SLSA/Sigstore proves what package was published; the record's lock is next.
OpenTelemetry will tell us what happened.
Governance is deliberately not one of the nine. It is the boundary the
nine are arranged around: no knowledge crosses a serving or publication
boundary without first passing the applicable governance decision. For a
static build that decision runs once per audience-specific build; for dynamic
retrieval it runs per request; the policy is the same either way.
The governance boundary is what turns a set of useful technologies into a
Knowledge System of Record. Without it, the components above would merely
form another knowledge stack.
And the boundaries — not the products — are the standard. Postgres + pgvector
and Fumadocs are reference implementation choices; a conformant alternative
may replace them. What may not vary is the governance semantics: one policy,
every surface.
The full specification — the profile, the conformance classes, the
governance requirements — is the KSoR Standard Proposal
(KSP-001), an open
standard written so that anyone can implement a conformant KSoR. It defines
five conformance classes — a corpus (A), a publisher (B), a retrieval layer
(C), an agent surface (D), and exchange (E) — plus optional profiles for
identity, publication integrity, and computation attestation. A complete
KSoR im

 KSoR 是一个开源框架/SDK,用于构建单一的、受治理的权威知识记录,供人类和 AI 智能体共同读取,从而让智能体不再基于零散或冲突的信息即兴发挥。它同时面向企业(政策、流程)和教育机构(课程、评分规则)。