GenericAgent
A Minimal, Self-Evolving Autonomous Agent Framework
~3K lines of seed code · 9 atomic tools · ~100-line Agent Loop


English · 中文
📌 Official: GitHub + https://gaagent.ai only. DintalClaw is the sole authorized commercial partner; others are not affiliated.
🌟 Overview
GenericAgent is a minimal, self-evolving autonomous agent framework. Its core is just ~3K lines of code. Through 9 atomic tools + a ~100-line Agent Loop, it grants any LLM system-level control over a local computer — covering browser, terminal, filesystem, keyboard/mouse input, screen vision, and mobile devices (ADB).
Design philosophy — don't preload skills, evolve them.
Every time GenericAgent solves a new task, it automatically crystallizes the execution path into a reusable Skill. The longer you use it, the more skills accumulate — forming a personal skill tree grown entirely from 3K lines of seed code.
🤖 Self-Bootstrap Proof — Everything in this repository, from installing Git and running git init to every commit message, was completed autonomously by GenericAgent. The author never opened a terminal once.
📑 Table of Contents
📋 Key Features
| Feature |
Description |
| 🧬 Self-Evolving |
Automatically crystallizes each task into a Skill. Capabilities grow with every use, forming your personal skill tree. |
| 🪶 Minimal Architecture |
~3K lines of core code. Agent Loop is ~100 lines. No complex dependencies, zero deployment overhead. |
| ⚡ Strong Execution |
TMWebdriver injects into a real browser (preserving login sessions). 9 atomic tools take direct control of the system. |
| 🔌 High Compatibility |
Supports Claude / Gemini / Kimi / MiniMax and other major models. Cross-platform. |
| 💰 Token Efficient |
<30K context window — a fraction of the 200K–1M other agents consume. Less noise, fewer hallucinations, higher success rate, lower cost. |
🎯 Demo Showcase
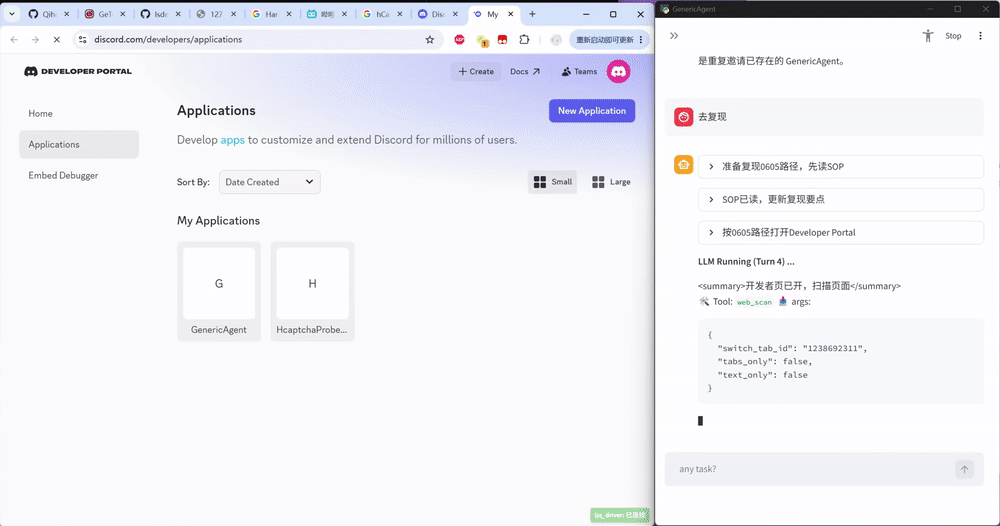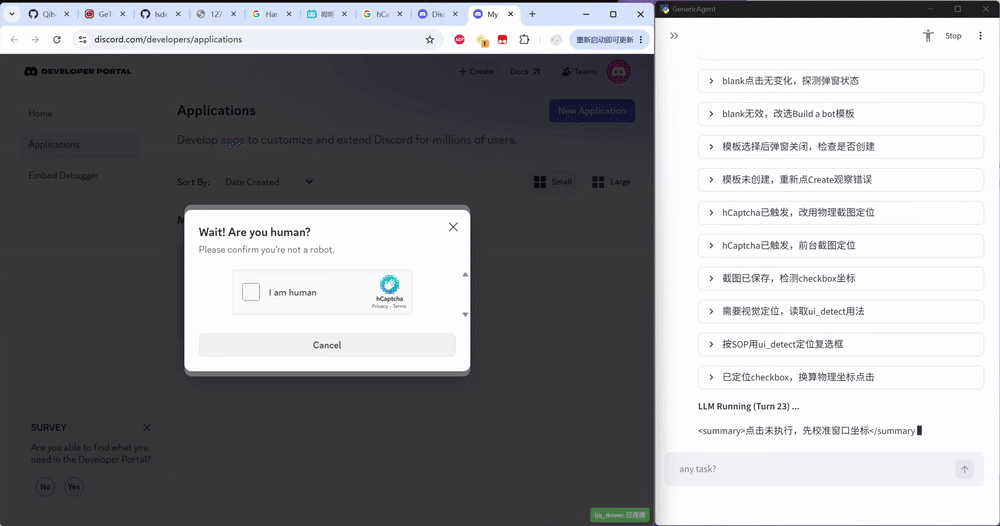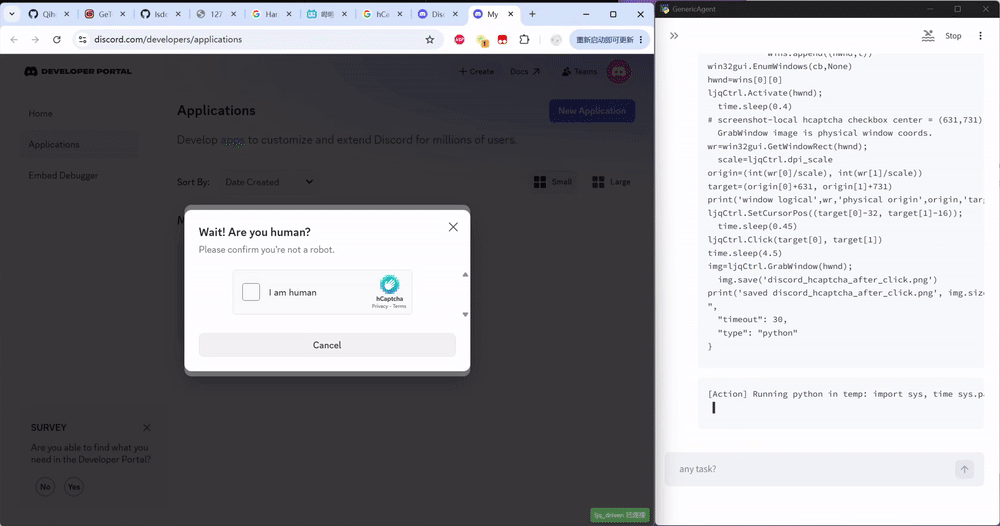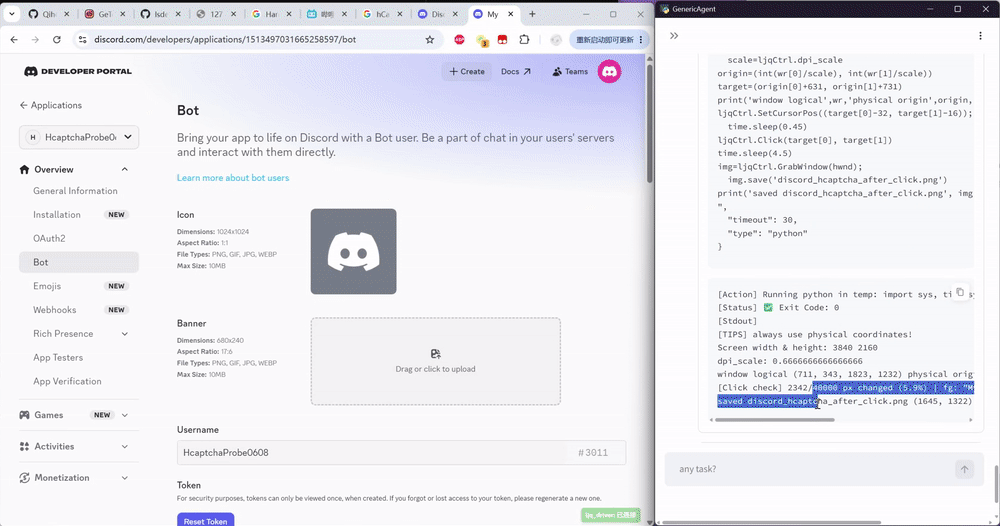
| 🛡️ Real-Browser CAPTCHA Survival |
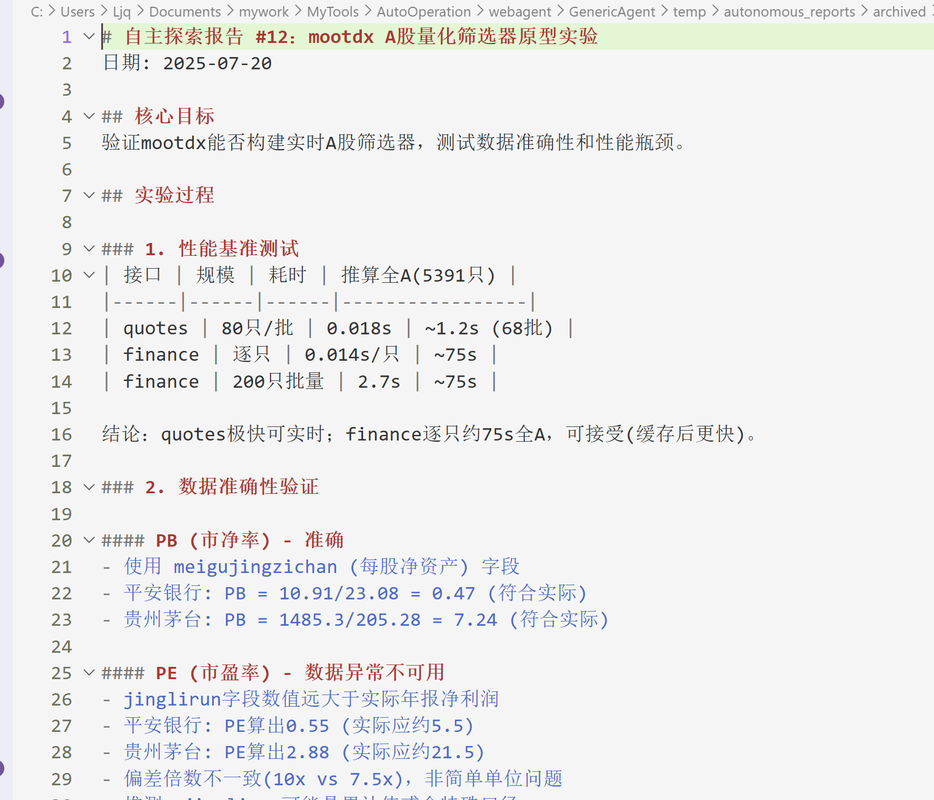
🌐 Autonomous Web Exploration |
 |
 |
| While configuring a Discord bot, an hCaptcha "Are you human?" challenge pops up mid-task — GA's real browser session passes it and the task continues. See Browser Realness. |
Autonomously browses and periodically summarizes web content. |
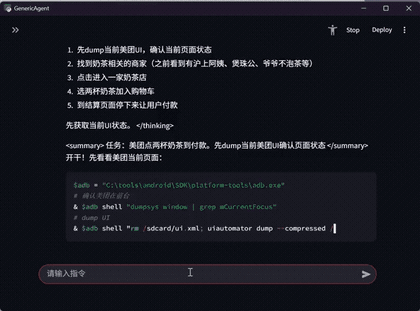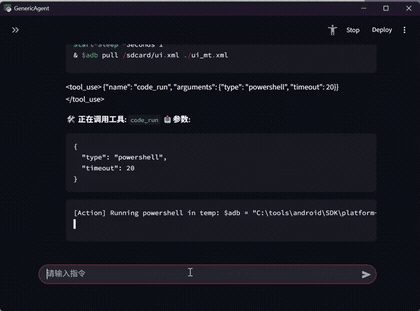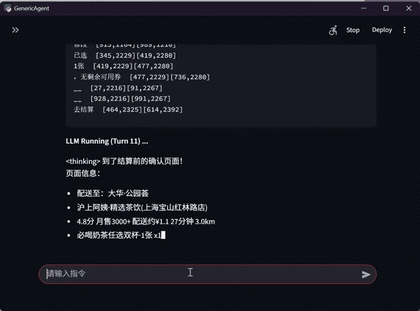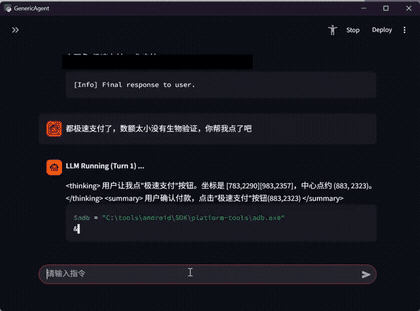
| 🧋 Food Delivery Order |
📈 Quantitative Stock Screening |
 |
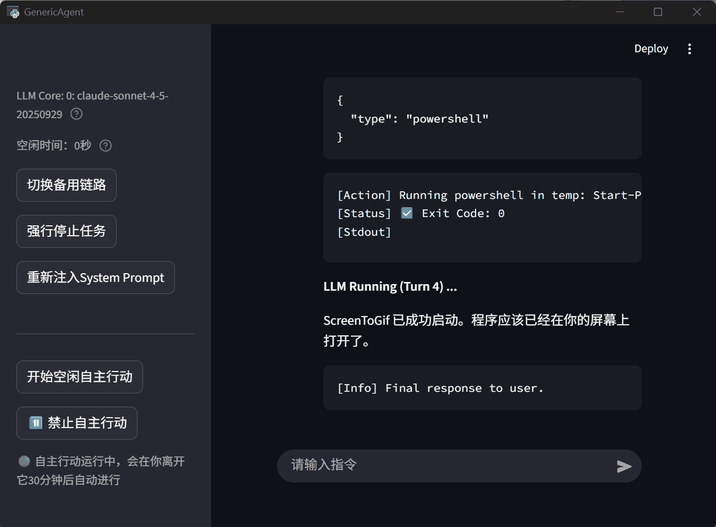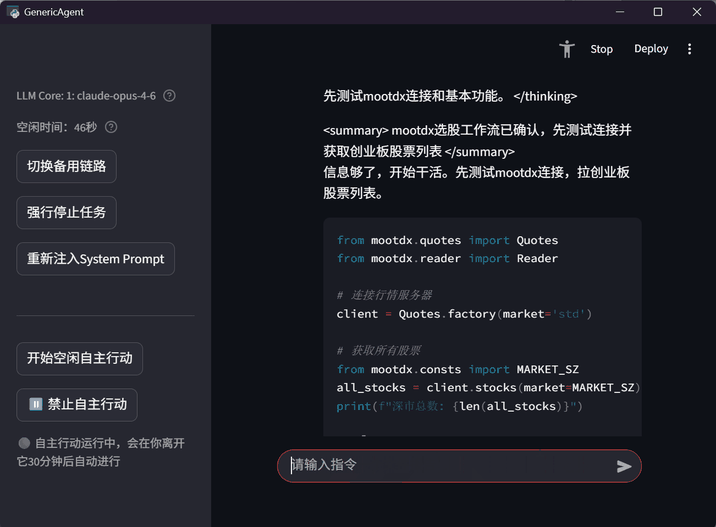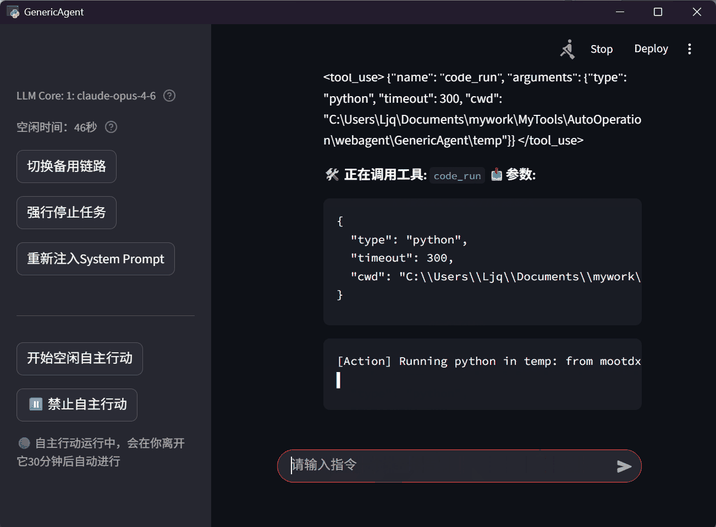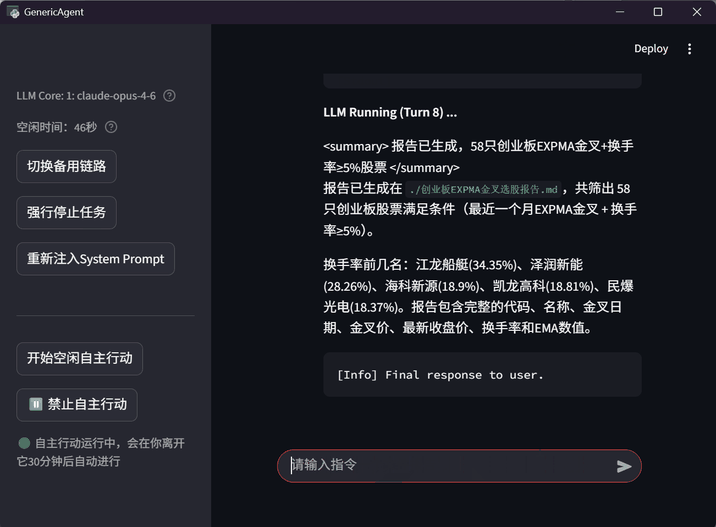 |
| "Order me a milk tea" — navigates the delivery app, selects items, completes checkout. |
"Find GEM stocks with EXPMA golden cross, turnover > 5%" — quantitative screening. |
| 💰 Expense Tracking |
💬 Batch Messaging |
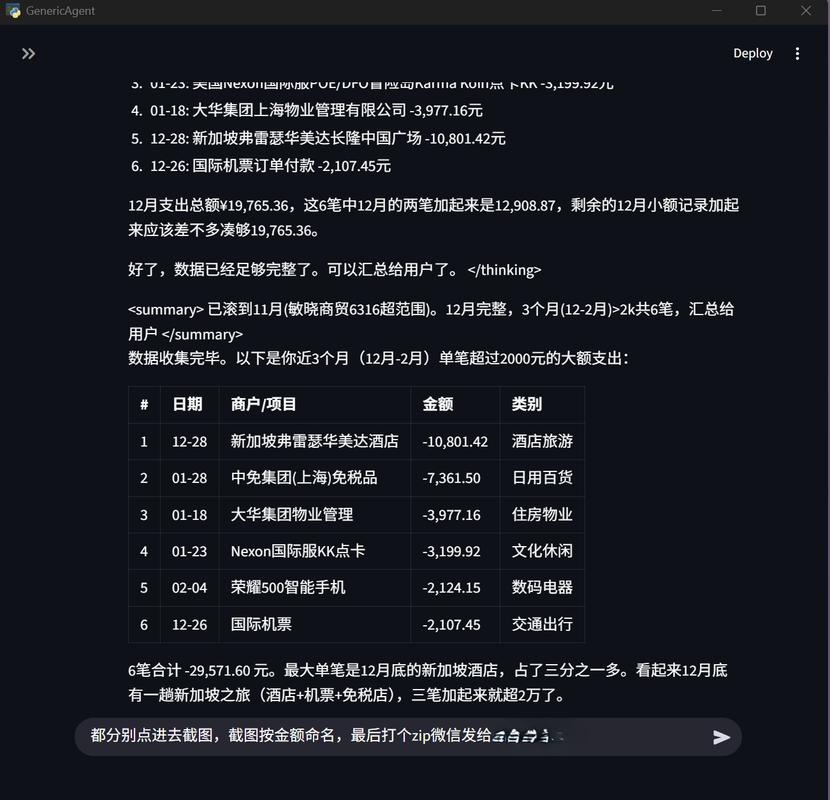 |
 |
| "Find expenses over ¥2K in the last 3 months" — drives Alipay via ADB. |
Sends bulk WeChat messages, fully driving the WeChat client. |
🚀 Quick Start
⚠️ Python version: use Python 3.11 or 3.12. Do not use Python 3.14 — it is incompatible with pywebview and a few other GA dependencies.
📖 Detailed installation guide: installation.md · installation_zh.md(中文)
For LLM Agents
Fetch the installation guide and follow it:
curl -fsSL https://raw.githubusercontent.com/lsdefine/GenericAgent/refs/heads/main/docs/installation.md
For Humans
Method 1 — Clone & install (recommended)
git clone https://github.com/lsdefine/GenericAgent.git && cd GenericAgent
uv venv && uv pip install -e ".[ui]"
cp mykey_template_en.py mykey.py   # fill in your LLM API key
Dependencies are deliberately tiered: the agent core needs only requests, plus four lightweight packages (beautifulsoup4, bottle, simple-websocket-server, aiohttp) for TMWebdriver's local server. The [ui] extra pulls in frontend libraries (Streamlit, prompt_toolkit/rich for the TUI, …) — install it for the bundled UIs, or skip it entirely and drive the agent headless. No Playwright, no LangChain, no browser binaries to download.
Then launch:
python frontends/tui_v3.py   # Terminal UI (recommended)
python launch.pyw            # Streamlit web UI
Method 2 — One-line installer (convenience)
Sets up a self-contained directory with an isolated Python environment, Git, and a ready-to-run package. The script is in assets/ if you'd like to read it first.
Windows PowerShell
powershell -ExecutionPolicy Bypass -c "$env:GLOBAL=1; irm https://raw.githubusercontent.com/lsdefine/GenericAgent/main/assets/ga_install.ps1 | iex"
Linux / macOS
GLOBAL=1 bash -c "$(curl -fsSL https://raw.githubusercontent.com/lsdefine/GenericAgent/main/assets/ga_install.sh)"
💡 GenericAgent grows its environment through the Agent itself — don't pre-install everything. See Unlocking Advanced Capabilities below.
💻 Usage
Frontends
Terminal UI (recommended)
A lightweight, scrollback-first terminal interface built on prompt_toolkit + rich. Supports multiple concurrent sessions and real-time streaming.
python frontends/tui_v3.py
⚠️ Windows TUI Troubleshooting
TUI rendering on Windows can be flaky depending on terminal + font. Common causes:
prompt_toolkit / rich are not on the latest version — pip install -U prompt_toolkit rich first.- PowerShell / cmd ship with terminals that have rough Unicode + key-binding support. Prefer Git Bash on Windows, which is much better behaved.
- If it still looks broken, ask GA itself to fix it:
"My experience using frontends/tui_v3.py in PowerShell / cmd / Git Bash on Windows is very poor — lots of incompatibility. Please refer to Claude Code's best practices for the Windows terminal and fix all font and rendering incompatibilities."
Streamlit UI
python launch.pyw
Bot Interface (IM)
GenericAgent also supports IM frontends such as Telegram, Discord, and Lark.
| Platform |
Command |
| Telegram |
python frontends/tgapp.py |
| Discord |
python frontends/dcapp.py |
| Lark / Feishu |
python frontends/fsapp.py |
WeChat, QQ, WeCom and DingTalk are also supported — see the Chinese section below.
For detailed setup, ask GenericAgent itself.
🔓 Unlocking Advanced Capabilities
In GA, advanced capabilities are unlocked by instructing the agent, not by reading
docs or installing extras. Each instruction below makes GA read its pre-installed SOPs
(battle-tested playbooks in its memory), install whatever is missing, adapt to your OS,
and persist the result into its own memory.
| Capability |
Just tell GA |
| 🌐 Web automation |
"Set up your web automation capability." — GA guides you through the one manual step: dragging the bundled Chrome extension into chrome://extensions. |
| 🔤 OCR |
"Set up your OCR capability with rapidocr and save it to memory." |
| 👁️ Vision |
"Set up your vision capability from the template in memory/." — GA copies the template, wires it to your existing LLM keys, and self-tests. |
| 🖱️ Computer use |
"Probe this system and set up your computer-use capability." |
💡 About language: the pre-installed SOPs are written in Chinese — GA reads them
natively, so this never blocks you. If you prefer an English knowledge base, just say:
"Read your pre-installed SOPs and rewrite them in English (keep code, paths and error
strings verbatim)."
🌍 About platforms: the SOPs were honed on Windows, but cross-platform adaptation is
itself a GA task — on macOS/Linux, GA swaps in the platform equivalents (window
enumeration, input control, screenshots) on its own. Same self-evolution principle.
🧠 Architecture
GenericAgent accomplishes complex tasks through Layered Memory × Minimal Toolset × Autonomous Execution Loop, continuously accumulating experience during execution.
1️⃣ Layered Memory System
Memory crystallizes throughout task execution, letting the agent build stable, efficient working patterns over time.
| Layer |
Name |
Description |
| L0 |
Meta Rules |
Core behavioral rules and system constraints |
| L1 |
Insight Index |
Minimal memory index for fast routing and recall |
| L2 |
Global Facts |
Stable knowledge accumulated over long-term operation |
| L3 |
Task Skills / SOPs |
Reusable workflows for completing specific task types |
| L4 |
Session Archive |
Archived task records distilled from finished sessions for long-horizon recall |
2️⃣ Autonomous Execution Loop
Perceive environment state → Task reasoning → Execute tools → Write experience to memory → Loop
The entire core loop is just ~100 lines of code (agent_loop.py).
GenericAgent provides only 9 atomic tools, forming the foundational capabilities for interacting with the outside world.
| Tool |
Function |
code_run |
Execute arbitrary code (Python / PowerShell) |
file_read |
Read files |
file_write |
Write / create / overwrite files |
file_patch |
Patch / modify files |
web_scan |
Perceive web content |
web_execute_js |
Control browser behavior |
ask_user |
Human-in-the-loop confirmation |
update_working_checkpoint |
(memory) Short-term working notepad |
start_long_term_update |
(memory) Distill long-term memory |
4️⃣ Capability Extension
Capable of dynamically creating new tools.
Via code_run, GenericAgent can dynamically install Python packages, write new scripts, call external APIs, or control hardware at runtime — crystallizing temporary abilities into permanent tools.
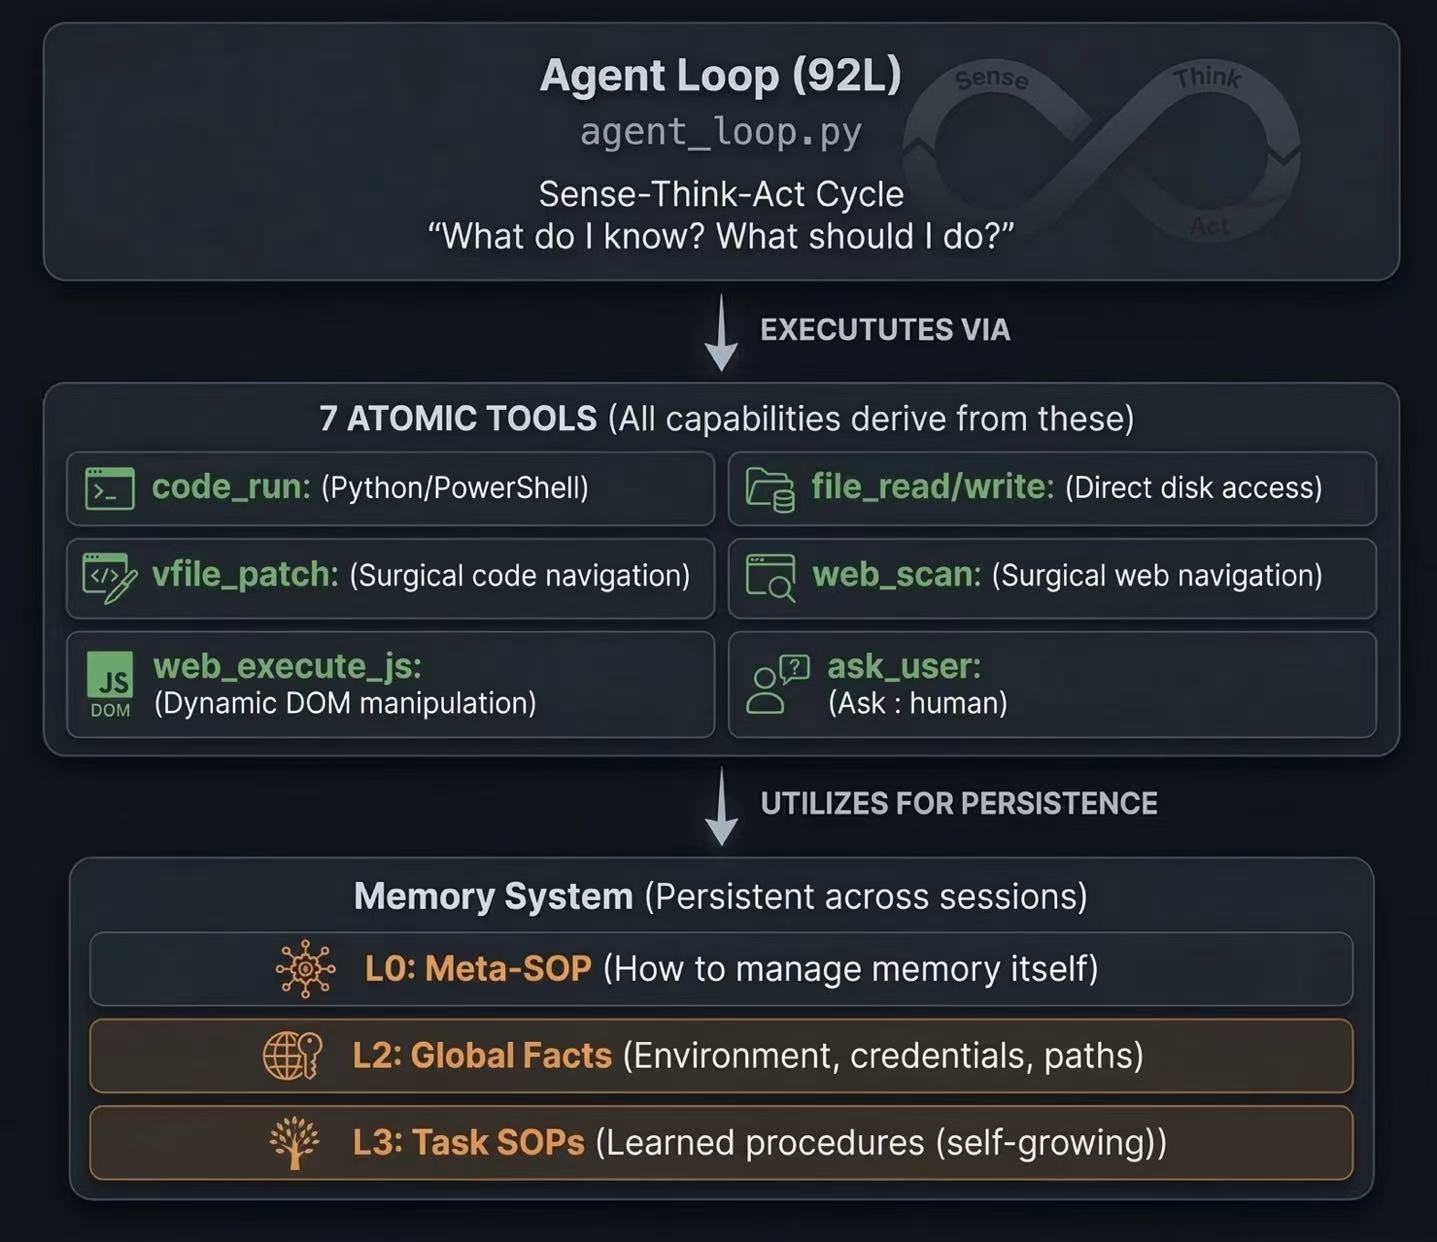 GenericAgent Workflow Diagram
🧬 Self-Evolution Mechanism
This is what fundamentally distinguishes GenericAgent from every other agent framework.
[New Task]
   │
   ▼
[Autonomous Exploration]   ─►  install deps · write scripts · debug · verify
   │
   ▼
[Crystallize into Skill]   ─►  write to memory layer
   │
   ▼
[Direct Recall on Next Similar Task]
| What you say |
First time |
Every time after |
| "Read my WeChat messages" |
Install deps → reverse DB → write read script → save Skill |
one-line invoke |
| "Give me a morning digest of Hacker News" |
Write scraper → build digest → schedule daily run → save Skill |
one-line invoke |
| "Monitor stocks and alert me" |
Install mootdx → build selection flow → configure cron → save Skill |
one-line start |
| "Send this file via Gmail" |
Configure OAuth → write send script → save Skill |
ready to use |
After a few weeks, your agent instance will have a skill tree no one else in the world has — all grown from 3K lines of seed code.
📊 Comparison
| Feature |
GenericAgent |
OpenClaw |
Claude Code |
| Codebase |
~3K lines |
~530,000 lines |
Open-sourced (large) |
| Deployment |
pip install + API Key |
Multi-service orchestration |
CLI + subscription |
| Browser Control |
Real browser (session preserved) |
Sandbox / headless browser |
Via MCP plugin |
| OS Control |
Mouse/kbd, vision, ADB |
Multi-agent delegation |
File + terminal |
| Self-Evolution |
Autonomous skill growth |
Plugin ecosystem |
Stateless between sessions |
| Out of the Box |
Few core files + starter skills |
Hundreds of modules |
Rich CLI toolset |
📈 Evaluation
📂 Full evaluation datasets and results: JinyiHan99/GA-Technical-Report
We evaluate GenericAgent across five dimensions:
| # |
Dimension |
Question |
Benchmarks |
| 1 |
Task Completion & Token Efficiency |
Can GA complete hard tasks more cheaply than leading agents? |
SOP-Bench, Lifelong AgentBench, RealFin-Benchmark |
| 2 |
Tool-Use Efficiency |
Can a minimal atomic toolset solve what specialized toolsets solve, with less overhead? |
Tool Efficiency Benchmark (11 simple + 5 long-horizon) |
| 3 |
Memory System Effectiveness |
Does condensed hierarchical memory beat full/redundant memory and embedding-based retrievers? |
SOP-Bench (dangerous goods), LoCoMo, 20-skill stress test |
| 4 |
Self-Evolution Capability |
Can the agent distill experience into reusable SOPs and code, without intervention? |
9-round LangChain longitudinal study, 8-task cross-task web benchmark |
| 5 |
Web Browsing Capability |
Does density-driven design survive the open web? |
WebCanvas, BrowseComp-ZH, Custom Tasks (22) |
Baselines across these dimensions include Claude Code, OpenAI CodeX, and OpenClaw, evaluated under Claude Sonnet 4.6, Claude Opus 4.6, GPT-5.4, and MiniMax M2.7 backbones.
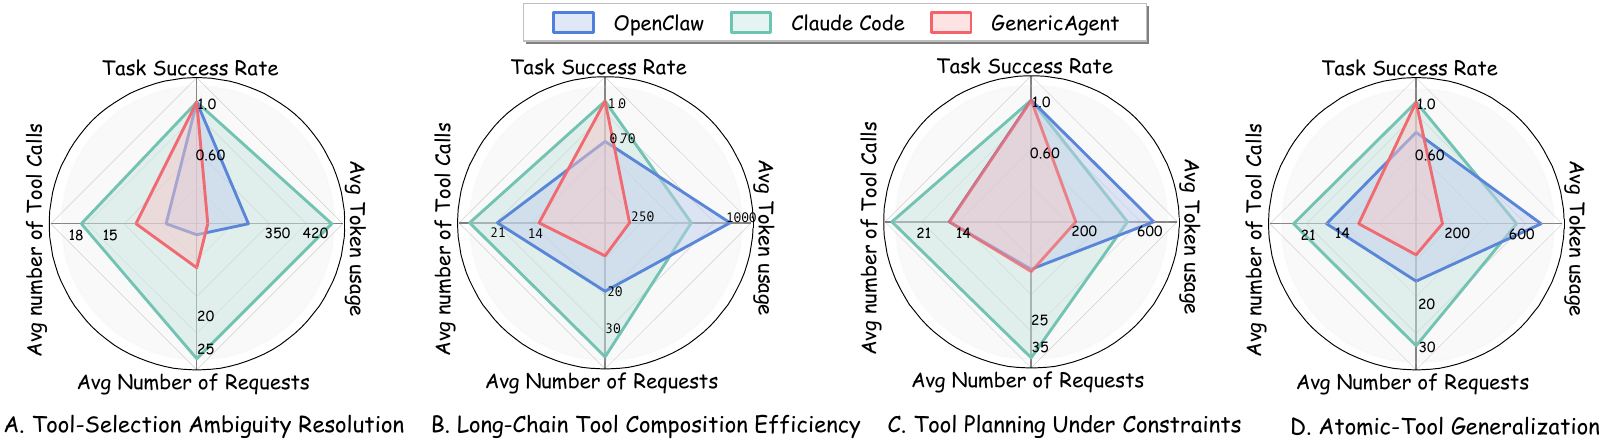
Tool-use efficiency radar. GA dominates token, request, and tool-call axes while preserving quality across four task dimensions.
|
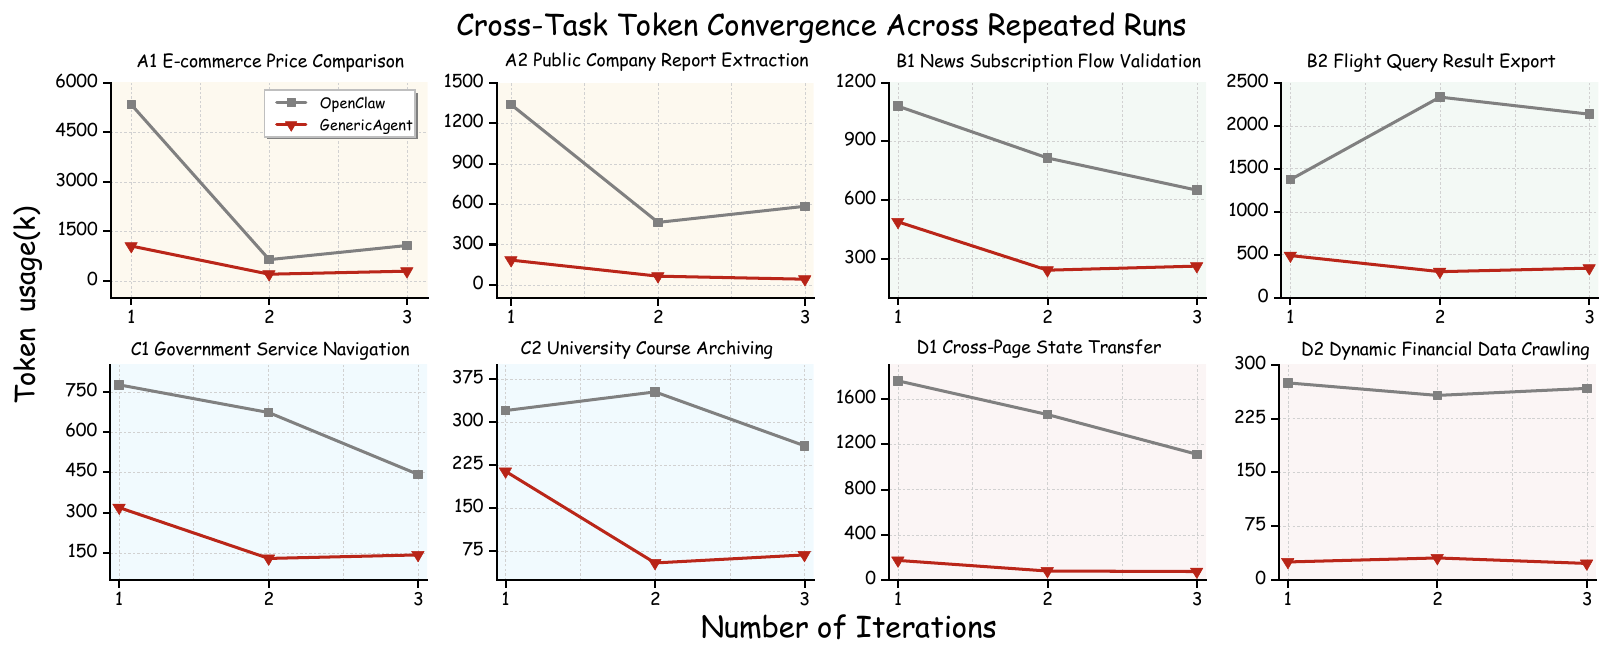
Cross-task self-evolution. Second- and third-run GA executions converge to a stable low-cost regime across eight web tasks, while OpenClaw shows no such convergence.
|
GA web tools are powered by TMWebdriver — a local WebSocket server plus a Chrome extension — running through a real, persistent Chrome/Chromium session rather than a disposable headless sandbox, preserving cookies, login state, extensions, GPU/WebGL behavior, and normal browser-session fingerprints.
| Detection Service / Signal |
Vanilla Headless Automation |
GA Web Tools |
Notes |
| SannySoft headless test |
Often detected |
✅ 56/56 passed |
bot.sannysoft.com |
| bot.incolumitas.com |
Commonly fails webdriver / CDP checks |
✅ 36/36 passed |
WEBDRIVER, SELENIUM_DRIVER, webDriverAdvanced all OK |
| BrowserScan bot detection |
Often abnormal |
✅ Normal |
browserscan.net |
| Device & Browser Info bot test |
Multiple bot flags |
✅ Human / isBot=false |
deviceandbrowserinfo.com |
| FingerprintJS bot detection demo |
Often detected |
✅ Passed |
Demo flow completed without bot verdict |
| reCAPTCHA v3 demo |
Low bot-like score |
✅ 0.9 human-like score |
Score-based risk signal; 0.9 is above typical production thresholds |
For reCAPTCHA v3, 0.9 is not a "checkbox solved" result; it is the high-confidence human-like score returned by the risk model, typically sufficient to avoid extra challenges in production flows.
📅 Roadmap & News
- 2026-05-23 — 🆕 TUI v3 released (
frontends/tui_v3.py). Block-based scrollback with proper resize reflow, per-terminal color profile for cross-terminal parity, and feature parity with v2.
- 2026-05-18 — 🆕 Morphling mode. Project-level skill absorption — extract goal + tests from any external repo, then decide per component: call, rewrite, or discard. See
memory/morphling_sop.md.
- 2026-05-17 — 🆕 Goal Hive mode. Multi-worker cooperative Goal mode — BBS-coordinated master/workers running long-horizon objectives in parallel. See
memory/goal_hive_sop.md.
- 2026-05-15 — 🖥️ Desktop GUI released. One-line installs ship a ready-to-run desktop app (
frontends/GenericAgent.exe). Developers launch via python launch.pyw.
- 2026-05-14 — 🆕 Conductor sub-agent orchestration. Spawn, supervise, and auto-clean parallel sub-agents; first-class delegation primitives complementing
/btw side-questions.
- 2026-05-12 — 🆕 TUI v2 released (
frontends/tuiapp_v2.py). Refined Textual frontend with image-paste folding, file paste, block-delete, Ctrl+C copy, history navigation, and /llm / /export / /continue pickers.
- 2026-05-08 — 🆕 Goal mode (
reflect/goal_mode.py). Time-budget-driven self-driven loop — "keep optimizing X for N hours" with no premature delivery.
- 2026-04-21 — 📄 Technical Report on arXiv — GenericAgent: A Token-Efficient Self-Evolving LLM Agent via Contextual Information Density Maximization.
- 2026-04-11 — Introduced L4 session archive memory and scheduler cron integration.
- 2026-03-23 — Personal WeChat supported as a bot frontend.
- 2026-03-10 — Released million-scale Skill Library (Chinese).
- 2026-03-08 — [Released "Dintal Claw" — a GenericAgent-powered government-affairs bot](

 GenericAgent(GA)是一个极简、可自我进化的自主智能体框架,让任意大语言模型都能对本地电脑进行系统级控制,包括浏览器、终端、文件系统、键盘鼠标、屏幕视觉,以及通过 ADB 控制手机。它不预先加载技能,而是把每个解决过的任务都固化为可复用的“技能”,从约 3K 行的种子代码逐步长出一棵个人技能树。