English · 简体中文
geo-score
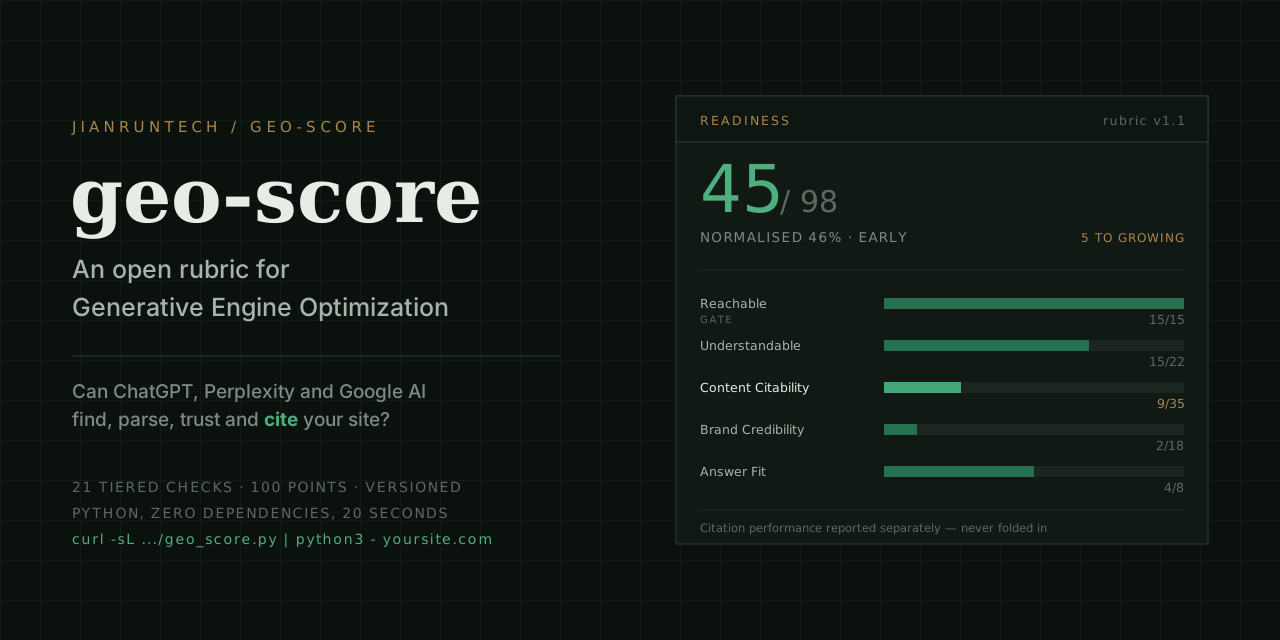
Will ChatGPT cite your site? Score it in 20 seconds.




curl -sL https://raw.githubusercontent.com/jianruntech/geo-score/main/cli/geo_score.py \
  | python3 - stripe.com --brief
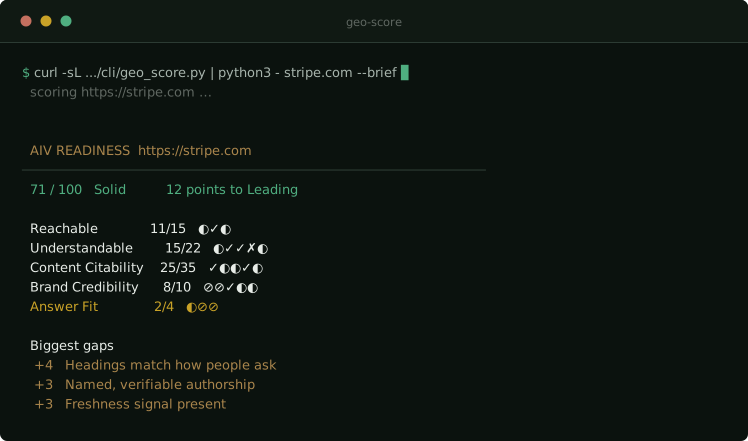
One command. About twenty seconds. Every check, and what the next tier needs.
Full output — every check, its evidence, and what the next tier asks for
  AIV READINESS  https://stripe.com
──────────────────────────────────────────────────────────────────────────
  71 / 100   Solid
  12 points to Leading

  Reachable 11/15
   ◐ Crawlers allowed in robots.txt   ███████████░░░░░░░  3/5
   ✓ Reachable to retrieval agents    ██████████████████  5/5
   ◐ Main content server-rendered     ███████████░░░░░░░  3/5
  Understandable 15/22
   ◐ Sitemap discoverable and fresh   █████████░░░░░░░░░  2/4
   ✓ llms.txt present and structured  ██████████████████  5/5
   ✓ Organization + WebSite schema    ██████████████████  6/6
   ✗ BreadcrumbList on nested pages   ░░░░░░░░░░░░░░░░░░  0/3
   ◐ Page-type schema (Product, FAQ…) █████████░░░░░░░░░  2/4
  Content Citability 25/35
   ✓ Self-contained answer passages   ██████████████████  9/9
   ◐ Headings match how people ask    ████████░░░░░░░░░░  3/7
   ◐ Freshness signal present         █████████░░░░░░░░░  3/6
   ✓ Statistics carry a source        ██████████████████  7/7
   ◐ Named, verifiable authorship     █████████░░░░░░░░░  3/6
  Brand Credibility 8/10
   ⊘ Third-party listings             ··················   —
   ⊘ Independent mentions             ··················   —
   ✓ Knowledge-graph entity           ██████████████████  4/4
   ◐ sameAs links resolve             ████████████░░░░░░  2/3
   ◐ Video and multimodal presence    ████████████░░░░░░  2/3
  Answer Fit 2/4
   ◐ Content shaped for extraction    █████████░░░░░░░░░  2/4
   ⊘ Covers the questions people ask  ··················   —
   ⊘ Chinese engine readiness         ··················   —
  Biggest gaps
   +4   Headings match how people ask    about half do
   +3   Named, verifiable authorship     and the name links to a verifiable identity page
   +3   Freshness signal present         most pages do, and dateModified agrees with the visible date

  Scored 61 / 86 observable · 4 checks left the denominator · rubric v1.1
  Needs judgement: p3.listings, p3.mentions, p4.question-coverage, p4.cn-engines

  Full rubric and what each tier means:
  https://github.com/jianruntech/geo-score
Python 3.8+, standard library only, nothing to install. It reads public URLs and prints
a score against a published, versioned rubric — not a black box.
See how 314 well-known sites score → · a quarter of them cannot be cited at all.
GEO means Generative Engine Optimization — getting cited by ChatGPT, Perplexity,
Google AI Overviews, Gemini and Copilot. Nothing to do with geography or maps.
Why this is a different question from SEO
Classic SEO asks where do I rank. Answer engines don't rank — they retrieve passages,
decide whether a source is worth quoting, and cite it. Different question, different
failure modes: a site can sit at position 3 on Google and never be quoted, while a page
nobody links to gets cited daily because its passages are clean.
Most of what determines this is mechanical and cheap to fix — a robots.txt line, a
JSON-LD block, a date in a template, a paragraph rewritten so it stands on its own. The
hard part is knowing which of them you are missing, and what each one is worth.
What it checks
21 tiered checks totalling 100 points, plus 4 bonus checks worth up to +6 outside the
denominator. Full specification: rubric/v1.1.md · 简体中文
| Pillar |
Pts |
Asks |
| Reachable — gates |
15 |
Can a retrieval crawler get the page at all? robots.txt, live reachability across 10 AI user-agents, server-rendered content |
| Understandable |
22 |
Can it tell what the page and the company are? Organization + WebSite, llms.txt, sitemap, breadcrumbs, page-type schema |
| Content Citability |
35 |
Is there anything here worth quoting? Self-contained answer passages, headings that match how people ask, sourced figures, real bylines, freshness |
| Brand Credibility |
18 |
Why should an engine trust it? Knowledge-graph entity, third-party listings, sameAs that resolves, video presence |
| Answer Fit |
10 |
Is the content shaped to be lifted into an answer? |
Content Citability carries the most weight on purpose: answer engines retrieve
passages, not domains. Passage shape beats domain authority more often than classic
SEO intuition expects.
Every scored check is tiered — 2 to 4 tiers, each naming a count out of the 8 sampled
pages, so two people scoring the same site agree on the arithmetic. Three checks are
gates: score zero on crawler access, live reachability or server-rendered content and
the result caps at 40, because until a crawler can reach the content nothing else you
change has any effect.
Bands
| 0–30 |
31–50 |
51–65 |
66–82 |
83–100 |
| Not started |
Early |
Growing |
Solid |
Leading |
Band names describe a stage, not a verdict. External benchmarks put most business
sites in the 30–55 range, so a score in the forties is ordinary, not alarming.
314 sites, scored in public
A quarter of them cannot be cited at all. 80 sites have a gate check at zero — a
retrieval crawler simply cannot get the content. 19 block AI crawlers by name in
robots.txt, which is an editorial choice and reported as such — amazon.com lands at 12
for exactly this reason. 45 serve a page whose body only exists after JavaScript runs.
Their content is there, a browser sees it, and a crawler gets an empty shell. That group
almost certainly did not choose it. A further 16 hand a crawler an outright error.
Median 56. Range 12 to 98.
| Site |
Score |
Band |
| pulumi.com |
98 |
Leading |
| minimaxi.com |
95 |
Leading |
| lumalabs.ai |
93 |
Leading |
| resend.com |
93 |
Leading |
| ironcladapp.com |
91 |
Leading |
| … |
|
|
| amazon.com |
12 |
Not started |
| keepa.com |
12 |
Not started |
| mercadolibre.com |
12 |
Not started |
The full table, by sector → · markdown · raw data · re-run it
Two more findings worth the click: sites built for the Chinese market score 19 points
lower than everyone else (median 40 against 59 — a gap that has held between 16 and 23
points across five separate samples, from 38 sites up to 314), and the same three cheap
things — a date in the page template, an opening paragraph that stands on its own, one
JSON-LD block — are missing from more than half the field.
Every number here is reproducible with the command at the top of this page — and we
measured how reproducible. Running the whole benchmark twice and comparing every site:
96% land within ±5, 45% land identically. Read one site's score as ±5 rather than as
exact; medians are stable. The unstable part is the gate checks, where five sites flipped
between runs because their bot protection answered a crawler differently.
The band, the control experiment and the per-site pairs are in
benchmark/REPRODUCIBILITY.md.
For five reference sites we also publish hand-scored audits covering all 21 checks,
with the evidence behind each one: examples/audits/v1.1/.
Three ways to run it
CLI — no install, no dependencies, 20 seconds.
python3 cli/geo_score.py example.com            # human-readable
python3 cli/geo_score.py example.com --explain  # with the evidence behind every check
python3 cli/geo_score.py example.com --json     # conforms to schema/report.v2.json
python3 cli/geo_score.py example.com --compare competitor.com   # side by side
python3 cli/geo_score.py example.com --badge aiv-badge.svg      # embeddable SVG
python3 cli/geo_score.py example.com --share                    # one line to paste somewhere
GitHub Action — score on every push, fail the build when it regresses.
- uses: jianruntech/geo-score@v1
  with:
    url: https://example.com
    fail-under: 40
Claude Code skill — the CLI measures what a static fetch can see. Four checks need
off-site search or human judgement, and the skill does those too.
git clone https://github.com/jianruntech/geo-score ~/.claude/skills/geo-score
# then: /geo-score audit https://example.com
The CLI leaves those four checks out of the denominator rather than guessing, so it
reads a little lower than a full audit — typically by 5 to 15 points on an established
brand, which has listings and mentions the CLI cannot see.
A score you cannot audit is a number someone made up. So the specification is the
product, and the tools are implementations of it:
- Versioned. Every score reports the rubric version.
71 (v1.1) is a claim; 71 is not.
- Tiered, with counts. Each tier names a page count out of 8, not "most".
- Evidence-bound. Every check requires an observation someone else can reproduce.
- Calibrated against public benchmarks, with the record published — including the four external sources the thresholds were checked against, and the eight specification ambiguities that real audits surfaced and v1.1 settled.
- Machine-readable.
rubric/v1.1.json with stable check ids, and schema/report.v2.json so results from different implementations are comparable.
Implement it in your own stack, disagree with a weight, open a rubric proposal. That is the main thing we want contributions on.
Scope — what this does not do
This is the part most tools leave out, so it's stated plainly.
AIV Score measures. It does not fix.
| Not included |
Why |
Fix templates — robots.txt, JSON-LD blocks, llms.txt boilerplate |
Remediation is where the actual work and judgement live. It is a separate, non-open project |
| Content rewriting — how to shape a passage so it gets quoted |
Same |
| Per-engine tactics — what to do differently for Perplexity vs Gemini |
Same |
| A remediation roadmap |
Same |
Other honest limits:
- It measures input-side readiness, not outcomes. A high readiness score means
engines can cite you. Whether they do depends on competition, query intent and
factors no external audit can observe. Citation performance is reported as a separate,
unscored block and never folded into the 100 — see
Two scores.
- Brand Credibility and the named-author check need human judgement. "Is this a real
identifiable person" and "is this mention independent" are not fully automatable.
Treat those ~24 points as assisted, not automatic.
- Tiers reduce disagreement, they do not remove it. Every tier names a count out of
the 8 sampled pages, so two auditors agree on the arithmetic. They can still disagree
on whether a given paragraph is a self-contained answer. The
settled ambiguities are the ones we found; there will be more.
- Heavily client-rendered sites score low, sometimes unfairly. If your content only
appears after hydration, most checks will read the pre-hydration HTML — which is also
roughly what a crawler sees, so the low score is usually right, but verify by hand.
- Engine behaviour moves. The rubric is versioned for exactly this reason. A score
from an older rubric version is not comparable to a current one.
Research behind the weights
The weights are opinionated but not invented. The two findings that most shaped them:
- Aggarwal et al., GEO: Generative Engine Optimization, KDD 2024 —
citing sources, adding statistics and quoting experts raise visibility by
up to 40% (measured as Position-Adjusted Word Count, not citation count).
Notably, the paper found an authoritative tone produced no significant improvement —
which is why this rubric scores structure and attribution, not voice.
- llms.txt proposal, Answer.AI — the convention this rubric
checks for in the Understandable pillar (
p1.llms-txt).
Where a check rests on our own field observation rather than published research, the
rubric says so. If you have evidence that a weight is wrong,
open a rubric proposal — that is the
main thing we want contributions on.
Deliberately naming what this is not, so you can pick correctly:
| Project |
What it does |
Relationship |
| llms-txt |
The llms.txt specification itself |
AIV checks for compliance with it |
| yao-geo-skills |
21 categorized GEO skills, execution-oriented |
Complementary — they do production, this does measurement |
| GEOFlow |
Full GEO operations system for company sites |
Much larger scope; AGPL |
If you need remediation and not just a score, those projects overlap with the part
this repo deliberately excludes.
Who maintains this
Built and maintained by Jianrun Tech (见润科技), Shenzhen —
we run GEO and AI-adoption programs for cross-border commerce companies. The rubric came
out of client work and out of optimizing our own products; publishing it is how we'd like
AI visibility to be measured consistently, including by people who never become our clients.
Commercial use of this repository is unrestricted under MIT — including inside paid
consulting work. You do not need our permission, and there is no separate commercial licence.
Contributing
The most valuable contribution is evidence about the weights.
See CONTRIBUTING.md.
Citation
If you reference the rubric in research or a report, see CITATION.cff.
License
MIT

 A free command-line scorecard for AI visibility: it reads your site the way answer-engine crawlers do and prints a 0-100 readiness score against a published, versioned rubric — not a black box.