


Auto-Empirical-Research-Skills README

The project's README from github.com/brycewang-stanford/Auto-Empirical-Research-Skills. As one markdown file: README.md.

Awesome GitHub stars License: CC BY-SA 4.0 PRs Welcome Validate catalog OpenSSF Scorecard Security audit: baseline 52/52 CLEAN Rigor coverage Powered by StatsPAI

Auto-Empirical Research Skills (AERS)

📌 文档结构(2026-07-22 起): 本文件是中文默认入口 —— banner + badges + 信任面 + 9 阶段流水线速览 + 76 行合集总表。 每个合集的完整描述、按用途分组、精确数字、验证方法在 docs/CONTENT_ZH.md(扩展正文,总表行内的 → 直接跳转到对应锚点)。

English version: README-en.md · 中文扩展正文:docs/CONTENT_ZH.md · README-zh-CN.md 已弃用(重定向占位)

🌐 语言: English | 简体中文(默认) | 繁體中文 | 日本語 | 한국어


CoPaper.AI Stanford REAP - Center on China's Economy & Institutions

Stanford REAP × CoPaper.AI · 实证研究 AI 工具的学术工业级产品
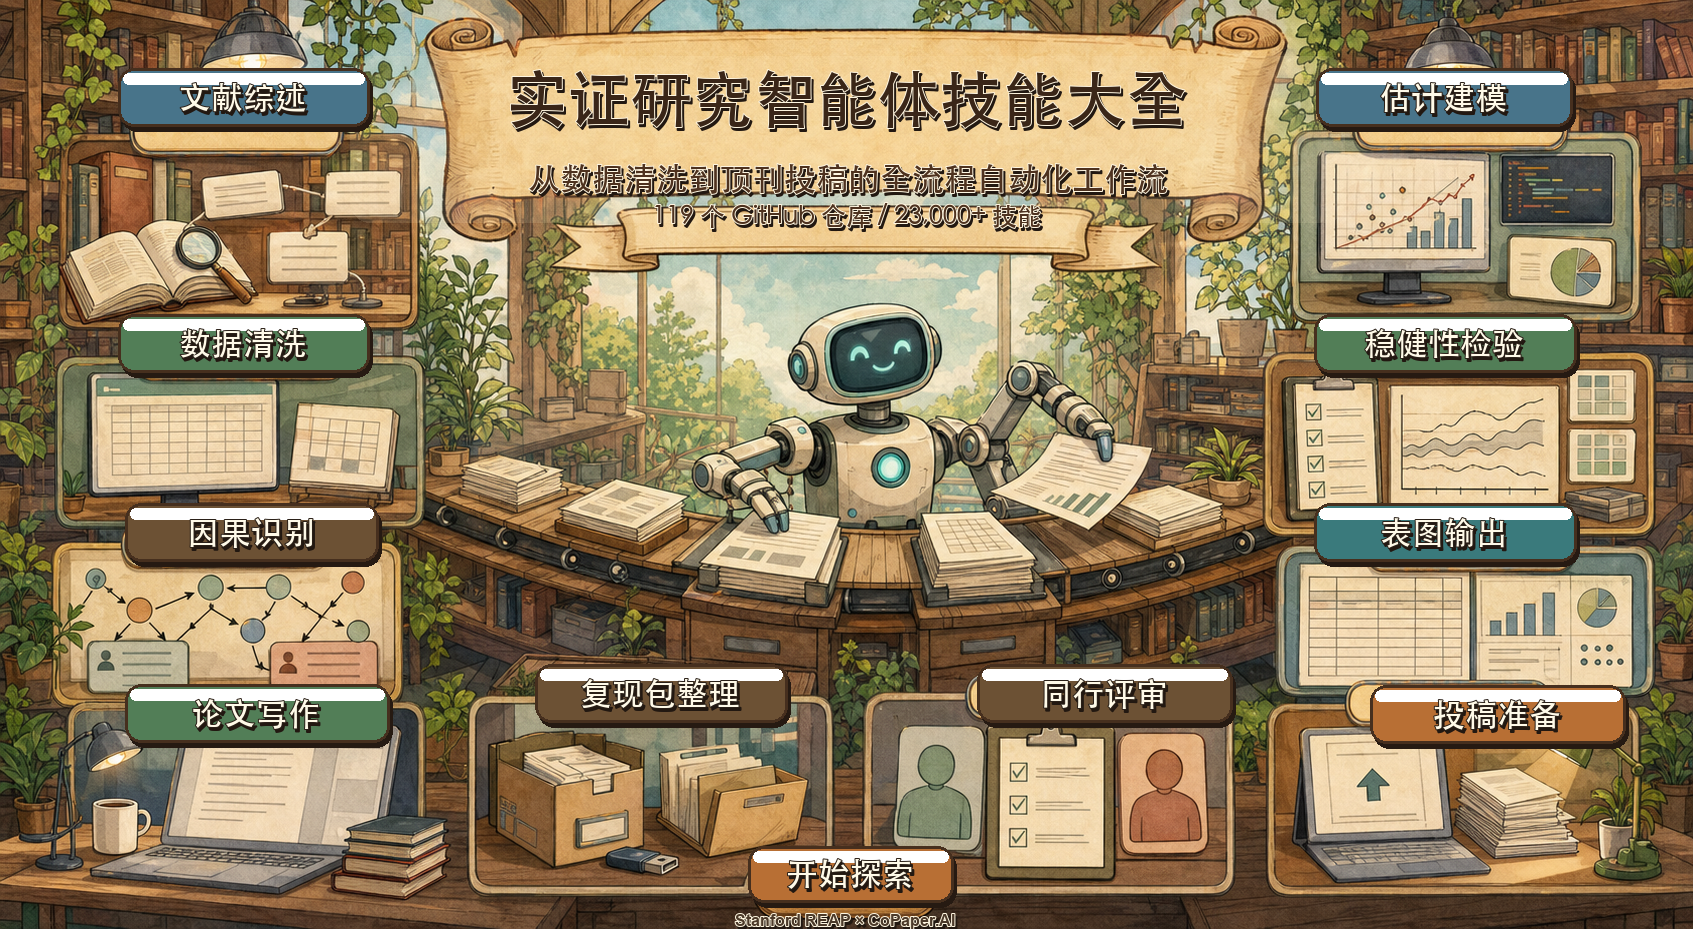
由斯坦福实证研究方法论团队打造,覆盖从数据清洗到顶刊投稿的完整工作流


实证研究智能体技能大全封面图

🚀 New here? Open the Skill Search → to filter all 1,096 skills by method, stage, language, and license. The 5-minute tour (make quickstart) prints the same picture in your terminal.

🇨🇳 中文用户从本文件开始(流水线速览 + 76 行总表),每个合集的完整描述见 docs/CONTENT_ZH.md。📖 English readers: see README-en.md.


信任面 · Trust surface (rigor stats)

Rigor lane Count Where
Numeric benchmark tasks — gold values recomputed from real data each run 19 benchmark/
Behavioral eval scenarios / rubric items 42 / 217 eval-harness/
其中已证明能区分对错的场景(pass/fail 双 fixture 自检) 9(全部 6 个 critical 场景在内) eval-harness/fixtures/

Full trust overview: docs/TRUST.md · docs/RIGOR_COVERAGE.md

🏁 带上你自己的 agent 来考同一份卷子:pip install -e . 后用 aers-score 给自己打分,成绩发布在 docs/EXTERNAL_SCOREBOARD.md(规则见 docs/SCOREBOARD_RULES.md)。榜上的数字是我们用同一套评分器重算出来的,不是提交者自报的。


⚡ 安装与使用(30 秒上手)

最省事的一招:把 URL 丢给 Agent

把项目 URL 地址 https://github.com/brycewang-stanford/Auto-Empirical-Research-Skills 丢给 Claude Code / Codex,并指定是目录 / 项目 / 全局安装 —— 剩下的让它自己做。例如:

帮我安装 https://github.com/brycewang-stanford/Auto-Empirical-Research-Skills
装到「全局」(~/.claude/skills/),我想在所有项目里都能用

把最后一行换成你要的作用域即可:

作用域 说给 Agent 的话 落到哪里
目录(当前会话临时用) "只在当前目录用,不要全局安装" 当前工作目录下的 .claude/skills/
项目(团队共享,可提交进 git) "装到本项目" 项目根目录 .claude/skills/
全局(所有项目可用) "装到全局" ~/.claude/skills/(Codex 为 ~/.codex/skills/)

手动安装(两种,任选其一)

A. 插件市场(Claude Code v2.1+,推荐,可升级)

claude plugin marketplace add brycewang-stanford/Auto-Empirical-Research-Skills
claude plugin install aer-skills@auto-empirical-research-skills                 # 顶刊投稿全流程(9 skills)
claude plugin install empirical-analysis-python@auto-empirical-research-skills  # Python 计量流水线
claude plugin install empirical-analysis-stata@auto-empirical-research-skills   # Stata 计量流水线
claude plugin install empirical-analysis-r@auto-empirical-research-skills       # R + Quarto 流水线

B. 只要某一个 skill —— 直接拷文件夹

git clone --recurse-submodules https://github.com/brycewang-stanford/Auto-Empirical-Research-Skills.git
cd Auto-Empirical-Research-Skills

cp -R skills/00.1-Full-empirical-analysis-skill_Python  .claude/skills/   # 项目级
cp -R skills/00.1-Full-empirical-analysis-skill_Python  ~/.claude/skills/ # 全局

拷进去的文件夹必须自带 SKILL.md(部分合集的 SKILL.md 在下一层,拷那一层)。

怎么用

新开一个会话,直接用自然语言说要做什么,Agent 会按 description 自动挑 skill;说不动就点名方法或 skill:

用面板数据跑一个 Callaway–Sant'Anna 事件研究,并出 HonestDiD 稳健性和期刊级表格

完整安装说明(Codex / CodeBuddy 整库导入、--plugin-dir 单次加载、常见故障排查)见 INSTALL.md。


中文文档结构

中文内容分两级维护,各司其职:

[!NOTE] 维护规则: 改合集总表 → 本文件与 CONTENT_ZH.md 的锚点表两处同步;改合集详情 / 分组 / 数字 → 只改 docs/CONTENT_ZH.md。统计数字(合集数 / skill 数)以 catalog/skills.json 为准,由 make validate 的 readme-stats 检查器守护。

贡献者(Contributors): 提交前请在本地跑通完整门禁 make check(catalog 校验 + 链接 + 单元测试 + eval-harness + benchmark)。详见 CONTRIBUTING.md。

旧版归档: README-zh-CN.md 已弃用,仅作向后兼容的重定向占位。


🚀 从一个 idea 到一篇论文:社科实证研究 · 端到端流水线(全自动、可介入)

AERS 不只是 76 个散装 skill —— 它能陪你走完一篇论文。 从模糊 idea → 选题精炼 → 文献综述 → 数据获取 → 识别策略 → 估计建模 → 稳健性审计 → 出版级表格 / 图形 → 写作与同行评审 → 降 AIGC → 投稿。端到端、全自动、每一步都可被人介入(中间任何一步你都可以接过去手工改方法、补变量、加稳健性,再让流水线自动接上跑)。

9 阶段流水线 · 每一步都覆盖到具体 skill

# 阶段 关键 skills(点合集名进目录,→ 进完整说明)
1️⃣ 选题精炼 — Agent 把模糊想法收紧成"可证伪 + 可执行"的研究问题 · 25 Diverga · 33 claude-scholar · 05 research-superpower · 11 compound-science
2️⃣ 文献综述 — 检索 · 筛选 · PRISMA 流程 · 批判性阅读 · 主题分析 · 36 literature-review-skill · 24 academic-research-skills · 59 openalex-skill · 68 research-productivity-skills · 53 thematic-analysis
3️⃣ 数据获取 — 公开数据库 · API · 网页抓取 · 数据清洗 · 33 claude-scholar · 68 research-productivity-skills · 32 stata-skill · 57 edgartools
4️⃣ 识别策略 — DiD / RD / IV / SCM / DML / matching 全覆盖 · ⭐ 00 StatsPAI 🔥 · 10 causal-inference-mixtape · 13 MixtapeTools · 51 CausalPy · 63 scientific-agent-skills
5️⃣ 估计建模 — Python / Stata / R 三栈,900+ 估计器 · ⭐ 00.1 Full Empirical · Python · ⭐ 00.2 Full Empirical · Stata · ⭐ 00.3 Full Empirical · R · 40 pyfixest · 39 marginaleffects · 09 awesome-econ-ai
6️⃣ 稳健性审计 — 复现包检查 · Honest-DiD · R&R 模拟 · 41 sewage-econometrics-check · ⭐ 50 AER-skills · 21 AI-research-feedback
7️⃣ 表格 & 图形 — 期刊出版级排版 · LaTeX 嵌入 · ⭐ 00 StatsPAI · 07 AI-Research-SKILLs · 33 claude-scholar · 08 latex-document-skill
8️⃣ 写作 & 同行评审 — LaTeX / Quarto · 仿审稿人 · 校对 · 06 stats-paper-writing · 04 scientific-writer · 22 christopherkenny-skills · 38 academic-proofreader · 56 econ-writing-skill · 16 clo-author
9️⃣ 降 AIGC & 去水印 & 投稿 — 知网 / 万方 / Turnitin / 23 类 AI 痕迹模式 / 隐藏字符 · C2PA · docx 元数据清理 · ⭐ 48 de-AIGC-skills 🇨🇳🇬🇧 · 44 humanizer_academic · 45 deslop · 46 stop-slop · 47 avoid-ai-writing · 49 humanize-chinese

🎼 元编排:⭐ 69 Paper-WorkFlow —— 一键串起来

Paper-WorkFlow 是 AERS 的"指挥棒",它把上面 9 个阶段的 skill 串成 一条按键即运行的端到端流水线。 你在 IDE 入口给它一句自然语言:

"开一个新论文项目:空气污染与中国劳动力市场,CS 设计 + 省级面板"

它会自动按顺序调:

  1. ⭐ 00 StatsPAI → sp.csdid(...) 给出 CS-DID 估计草案 + 写出估计方程与识别假设
  2. 33 claude-scholar → 抓变量定义 / 数据源候选 / 相关文献
  3. ⭐ 00 StatsPAI → 真跑 sp.feols(...) + sp.honest_did(...)
  4. 41 sewage-econometrics-check → 10 项复现包审计 + 稳健性体检
  5. ⭐ 00 StatsPAI + 07 AI-Research-SKILLs → 出 Table 1–5 + 期刊级图
  6. 38 academic-proofreader → 通读 + §comment 标"审稿人会挑刺的位置"
  7. 56 econ-writing-skill 起草初稿 + ⭐ 48 de-AIGC-skills 🇨🇳🇬🇧 + 45 deslop 过知网 / Turnitin

任何阶段你都可以手动介入 —— 上一阶段的产物全部落盘(产物-幂等 pipeline),你接过去改方法、补控制、加稳健性,再让流水线自动接下去跑。这就是"全自动 + 可介入"。

🏆 7 个 Stanford REAP × CoPaper.AI 自研 skill —— 是整个流水线的主干

⭐ Skill 在流水线里的角色
00 StatsPAI 🔥 因果引擎:900+ 函数,sp.causal(...) 一行跑闭环(DID / RD / IV / SCM / DML / matching)
00.1 Full Empirical · Python 📘 显式 Python 栈(pandas / statsmodels / linearmodels / pyfixest)
00.2 Full Empirical · Stata 📊 显式 Stata 栈(reghdfe / ivreg2 / csdid / sdid / rdrobust)
00.3 Full Empirical · R 📗 显式 R 栈(tidyverse / fixest / did / HonestDiD)+ Quarto 渲染
48 de-AIGC-skills 🇨🇳🇬🇧 中英双语学术降 AIGC + 去水印层(Turnitin AI / GPTZero / 知网 / 万方 · 隐藏字符 / C2PA / docx 元数据)
50 AER-skills 📕 Top-5 经济学投稿套件:识别 → 稳健性 → R&R
69 Paper-WorkFlow 🧭 元编排器,把上面 9 个阶段串成一键流水线

为什么挑这 7 个?因为它们的行为都被基准钉死了 —— 不是营销口径,是对着已知答案反复跑过验证过的(17 项数值 benchmark + 37 项行为评测 ↗)。

看到这里 —— 完整 76 行合集目录

↴ 直跳到下方 76 行总表(每个合集带 #skill-NN 锚点)。如果你更关心"这些 skill 怎么用"而不是"有哪些 skill",看 📘 中文唯一权威正文 里的「按用途分组」与「旗舰流水线」两节。


🧰 76 个核心 Skills 合集一览(00 → 72,编号连续无空缺)

打开仓库 → 看见整座库。 全部 76 个合集 · 1,096 个 skill,每一个都已 vendor 进本仓库,由 catalog/skills.json 跟踪。⭐ = Stanford REAP × CoPaper.AI 团队自研的 skill;其余为精选、经安全审计的社区作品。

主题图例 — 🚀 全流程与编排器 · 🎯 因果推断与计量经济学 · 📚 文献与研究设计 · ✍️ 写作 / 编辑 / 去 AIGC · 📑 引用 / 复现 / 同行评审 · 🛠️ 数据 / 工具 / 基础设施

点击【→】 跳转到 docs/CONTENT_ZH.md 中该合集的完整描述;点击合集名 直接打开其目录。

🙏 尊重原作者 — 「来源」列直接链回上游原始仓库(owner/repo)。本仓库里的社区合集都是上游快照:请去原仓库点 star、提 issue、看 LICENSE。完整的许可证与来源置信度审计见 docs/LICENSE_AUDIT.md,机器可读版本在 catalog/provenance.json。

# 合集 一句话 详情 来源
⭐ 00 StatsPAI 🔥 因果引擎 · Agent-native Python DSL:sp.causal(...) 一行跑闭环(DID/RD/IV/SCM/DML,900+ 函数) → brycewang-stanford/StatsPAI
⭐ 00.1 Full Empirical · Python 📘 显式栈:pandas · statsmodels · linearmodels · pyfixest → ⭐ 本仓库
⭐ 00.2 Full Empirical · Stata 📊 reghdfe · ivreg2 · csdid · sdid · rdrobust 复现包 → ⭐ 本仓库
⭐ 00.3 Full Empirical · R 📗 tidyverse · fixest · did · HonestDiD + Quarto 渲染 → ⭐ 本仓库
01 academic-paper-skills 大纲 → 手稿写作 + 7 维审稿人模拟 → lishix520/academic-paper-skills
02 research-skills 医学影像综述、提案、论文转幻灯片 → luwill/research-skills
03 scientific-skills 假设生成 + 28 个科学数据库 → K-Dense-AI/claude-scientific-skills
04 scientific-writer 引用管理 + 科学写作 → K-Dense-AI/claude-scientific-writer
05 research-superpower 系统化检索、筛选与引文溯源 → [kthorn/research-superpower](https://github.com/kthorn/res

Auto-Empirical-Research-Skills (brycewang-stanford/Auto-Empirical-Research-Skills)

Searching Database…

What is this?Auto-Empirical Research Skills (AERS) is a curated library of 1,096 AI agent skills across 76 collections for doing empirical social-science research (economics, political science, sociology, psychology, etc.), maintained by Stanford REAP and CoPaper.AI.
Is this a coding framework or a set of ready-made skill files?It is a skills library: each collection is a folder containing a SKILL.md that you drop straight into an AI coding agent's skills directory, not code you write against.
How do I install these skills into my agent?Easiest way: paste the repo URL to Claude Code or Codex and tell it whether to install at the directory, project, or global scope and it handles the rest; alternatively use the Claude Code v2.1+ plugin marketplace or manually copy a skill folder (with its SKILL.md) into .claude/skills/.
Which coding agents can use these skills?Claude Code (plugin marketplace needs v2.1+) and Codex are directly supported, with extra install paths documented for whole-repo import into CodeBuddy.
Are all 1,096 skills equally trustworthy?No — only the 7 flagship skills are built and benchmark-locked by the Stanford REAP/CoPaper.AI team (17 numeric benchmarks plus behavioral evals); the rest are community skills vendored from upstream repos with license/provenance audits but not the same rigor guarantee.
Who is this aimed at?Researchers and students doing quantitative empirical work in economics, political science, sociology, psychology, public administration, and international relations who use an AI coding agent as a research assistant.
What is StatsPAI?StatsPAI is the project's causal-inference engine: an agent-native Python DSL with 900+ functions where a call like sp.causal(...) runs a full DID/RD/IV/SCM/DML workflow in one go.
What does the 9-stage research pipeline cover?It chains idea refinement, literature review, data acquisition, identification strategy, estimation, robustness auditing, publication-grade tables/figures, writing/peer review, and de-AIGC/submission, orchestrated end-to-end by the Paper-WorkFlow skill.
Can I benchmark my own agent against the project's scoring suite?Yes - install with pip install -e . then run the aers-score command to get a score, which can be published on the public external scoreboard.
Does it help pass Chinese plagiarism/AI-detection checks?Yes, the de-AIGC-skills collection offers bilingual Chinese/English AI-trace removal targeting Turnitin AI, GPTZero, and Chinese platforms like Zhiwang and Wanfang, including hidden-character and docx metadata cleanup.
Size
42.3 MB
Stars
4.7K
Age
6mo
Commits · 90 Days