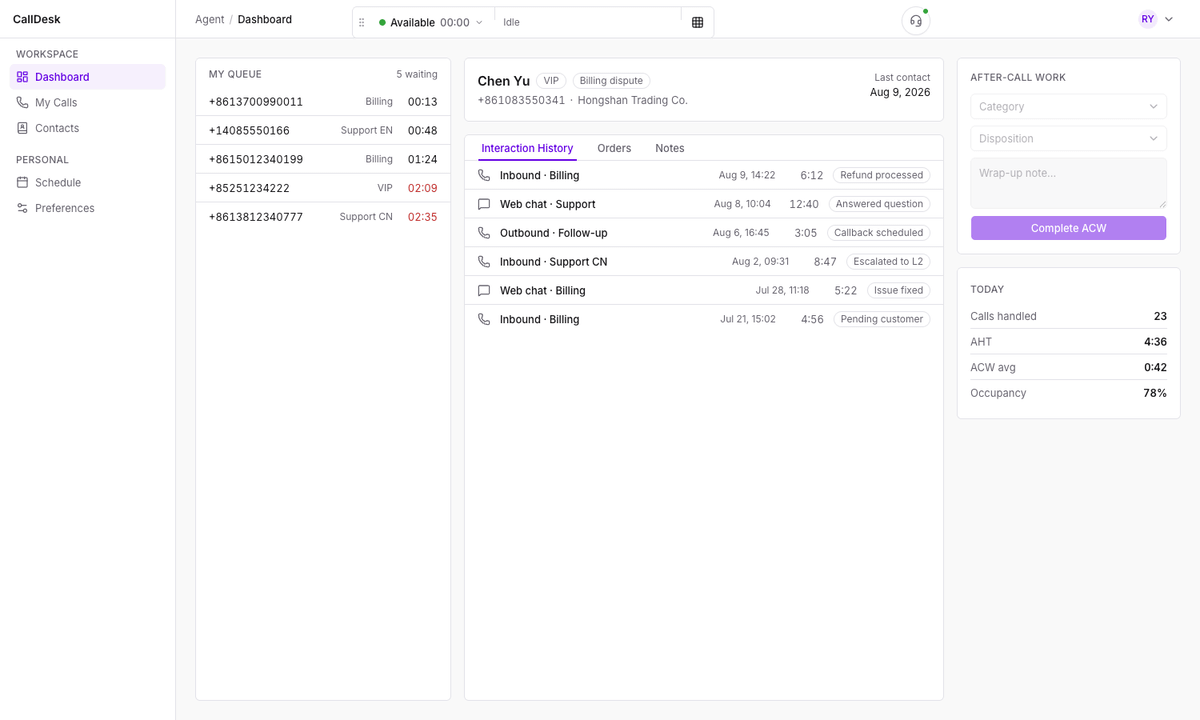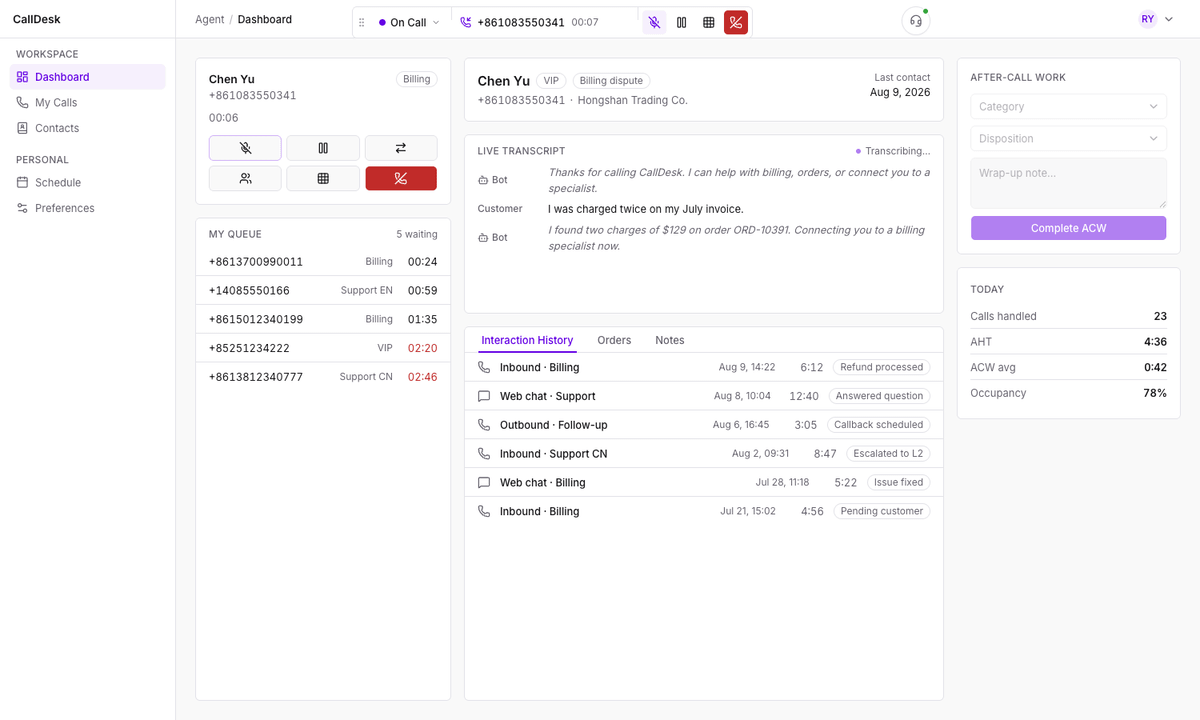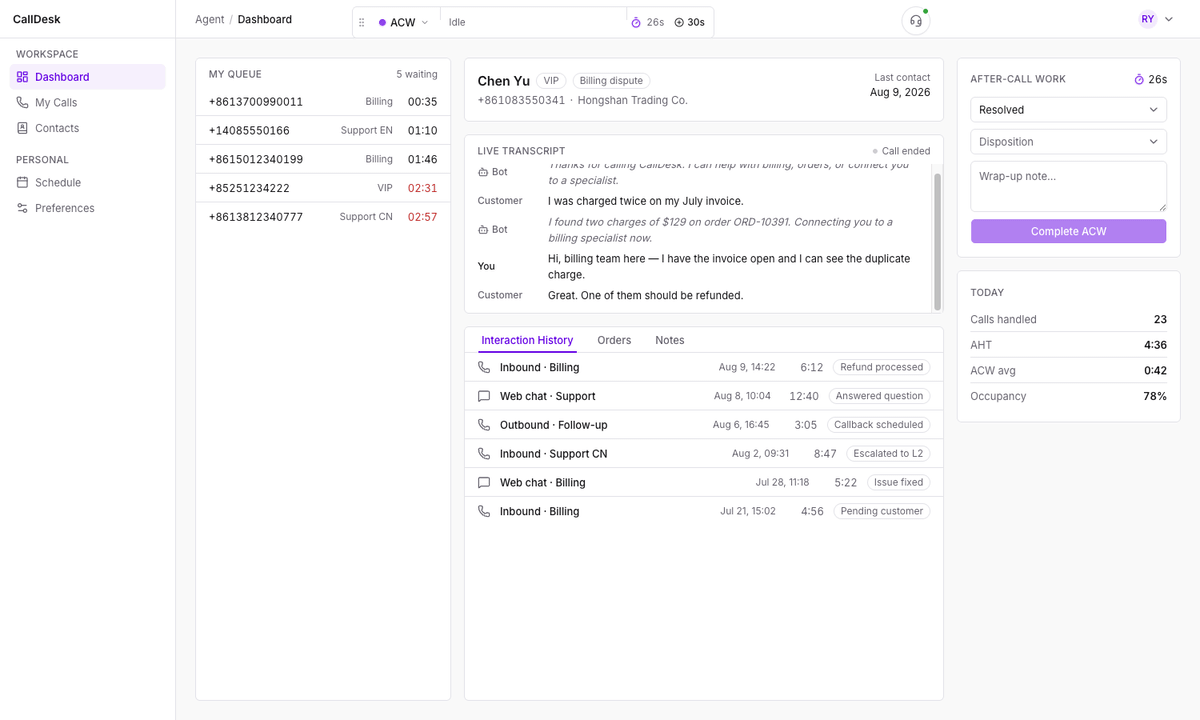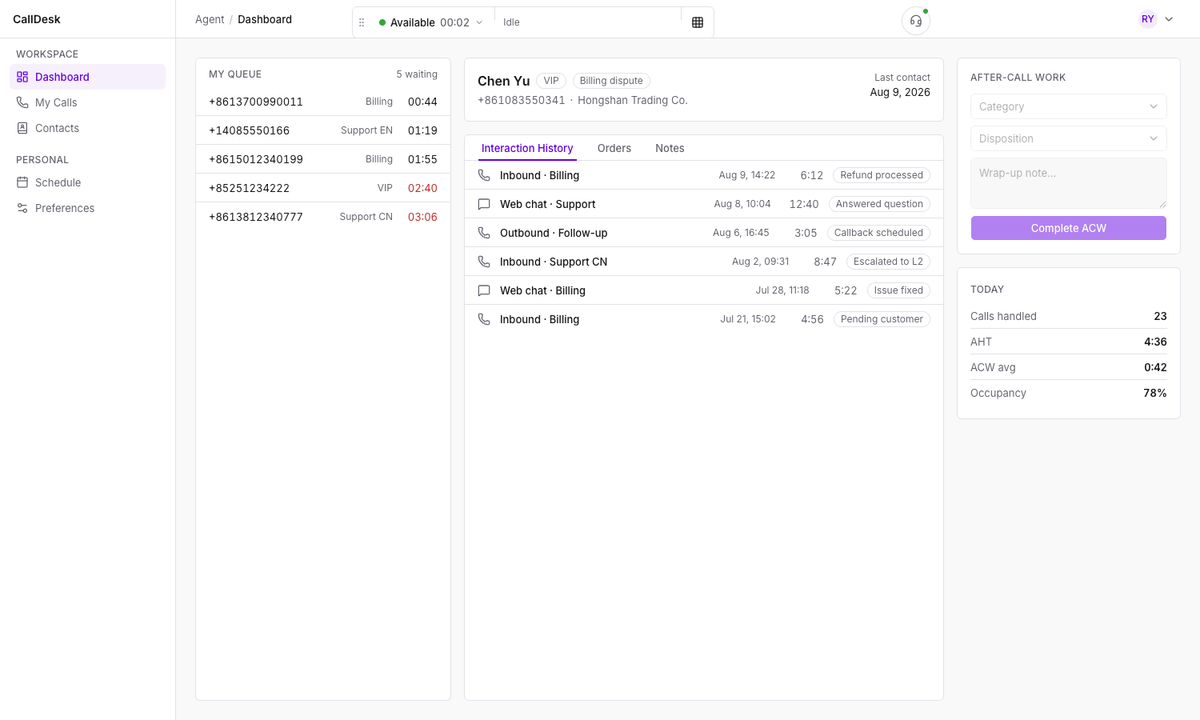
What is this?
 An open-source, self-hosted AI call center: calls land on FreeSWITCH and are answered by a speech-to-speech voice model by default, with a flow deciding when to hand the caller to a real human agent in a queue. It ships as one Go binary with a REST+SSE API, OpenAPI spec, PostgreSQL and FreeSWITCH underneath.
Is this a library I embed, or a standalone server I deploy?It's a standalone self-hosted service: one Go binary that bundles the REST API, the SSE event stream and the whole web UI, running alongside PostgreSQL and FreeSWITCH.
It's a standalone self-hosted service: one Go binary that bundles the REST API, the SSE event stream and the whole web UI, running alongside PostgreSQL and FreeSWITCH.How do I get it running?There's a one-line installer for Linux and macOS, documented in deploy/one-line-installer.md.
There's a one-line installer for Linux and macOS, documented in deploy/one-line-installer.md.What do I need besides the installer itself?FreeSWITCH and PostgreSQL are part of the stack, plus one voice provider picked at deployment startup: Qwen or Doubao (for mainland China), OpenAI Realtime or Gemini elsewhere, or your own Realtime-compatible gateway.
FreeSWITCH and PostgreSQL are part of the stack, plus one voice provider picked at deployment startup: Qwen or Doubao (for mainland China), OpenAI Realtime or Gemini elsewhere, or your own Realtime-compatible gateway.Has it actually been load-tested for production call volumes?The human path, AI path and packaging are verified against live FreeSWITCH and live providers, but no benchmark campaign has run yet, so the stated capacity/latency budget is an intention, not a measured guarantee.
The human path, AI path and packaging are verified against live FreeSWITCH and live providers, but no benchmark campaign has run yet, so the stated capacity/latency budget is an intention, not a measured guarantee.Does the installer work on Windows too?Only Linux and macOS one-line installers are provided; there's no mention of a Windows install path.
Only Linux and macOS one-line installers are provided; there's no mention of a Windows install path.How do human agents actually handle the call audio?Agents work in the browser for presence, call control and callbacks, but the audio itself is carried by a companion Chrome extension called web-sip-phone, which holds the agent's SIP registration and is controlled via REST calls.
Agents work in the browser for presence, call control and callbacks, but the audio itself is carried by a companion Chrome extension called web-sip-phone, which holds the agent's SIP registration and is controlled via REST calls.What languages can the bot speak?English and Chinese throughout both the interface and the bot, with the AI provider for a given deployment chosen independently of the caller's language.
English and Chinese throughout both the interface and the bot, with the AI provider for a given deployment chosen independently of the caller's language.Can I bolt a classic ASR+LLM+TTS pipeline onto this?No, that's deliberately excluded from the core process; any cascaded ASR/LLM/TTS composition is expected to live in a separate service speaking the same protocol.
No, that's deliberately excluded from the core process; any cascaded ASR/LLM/TTS composition is expected to live in a separate service speaking the same protocol.If a bot starts the call and a human finishes it, do I get one record or several?Just one: a call answered by the bot, transferred to a queue and finished by an agent produces a single CDR with one transcript and one recording, not fragmented pieces.
Just one: a call answered by the bot, transferred to a queue and finished by an agent produces a single CDR with one transcript and one recording, not fragmented pieces.What are similar projects?telnyx-code-examples, livekit, gin-vue-admin, electric, agents, webrtc, jargo, chat
telnyx-code-examples, livekit, gin-vue-admin, electric, agents, webrtc, jargo, chat